discovery engine
2 TopicsReinventing Organic Redox Flow Batteries with Microsoft Discovery
Discovery Bookshelf preserves negative scientific results to guide better hypotheses. Discovery Engine navigates imprecise computational tools, adapting to real-world scientific workflows. Discovery proposed a novel organic negolyte validated through in-lab measurements. At Microsoft Build 2026, we highlighted how Microsoft Discovery designed a novel organic replacement candidate intended to reduce reliance on vanadium, a critical mineral, in grid energy storage. This demonstration integrated AI, computational machine learning models, and laboratory feedback within a closed-loop discovery system. In this blog post, we explore how Discovery Engine with CLIO mode uniquely enabled this effort. This was our first end-to-end validated scientific result with in-lab measurements, therefore worth a deeper dive into the surprising methods that Discovery used to get the complete scientific outcome. This work highlights an important shift occurring across scientific AI. Generating ideas is no longer the primary bottleneck. Generative models can propose large numbers of chemically plausible compounds, leverage computational predictors to rapidly estimate properties such as redox potential, solubility, or synthesizability, and interpret experimental results. The new bottleneck arises in alignment of these models with scientific objectives: efficiently scheduling in silico and wet-lab experiments, effectively leveraging failures to shape future exploration, and enabling accumulation of knowledge across a multitude of design decisions over time. Scientific objectives are often hard to express as clean optimization problems. The imprecision of predictive models and divergence of computational estimates from experimental reality are just two examples of why defining a complete fitness function is not possible. Results which maximize fitness are often found lacking when examined by domain experts due to design requirements and preferences that are difficult to express numerically. For this campaign, we used Discovery Engine with CLIO mode enabled, and Discovery Bookshelf, built on GraphRAG to evolve and improve a benzo[c]cinnoline scaffold. The integration of language models into the design process allows these less rigid requirements to be expressed and considered as first-class priorities alongside numerical objectives. Microsoft Discovery Engine leverages Bookshelf’s knowledge graph representations to guide the design process, enabling multiple agents to coordinate a shared understanding of what is known with what level of confidence. This shared understanding is crucial to 1) escaping local minima by considering a global view of the task and 2) learning from negative results. Empowered by the combination, we designed a novel organic negolyte in partnership with Yale Engineering, Canam Bioresearch, and Pacific Northwest National Laboratory (PNNL). Closed-loop discovery workflow using Discovery Engine to guide molecular design using computational property predictors, wet-lab feedback, and Discovery Bookshelf to preserve both positive and negative results that inform each new design cycle. Turning Scientific Exploration into Durable Knowledge Scientific publication is shaped by positive-results bias: studies reporting statistically significant or otherwise favorable findings are more likely to be published than studies reporting null or negative results. In practice, however, exploration is dominated by unsuccessful attempts, both in silico and in the laboratory, and these negative results contain valuable information about the studied system. In computational design campaigns, such negative results often arise from in silico predictions deviating from experimental reality; properly capturing experimental feedback to inform subsequent designs under a constrained search space is crucial. Knowing where not to look is as important as knowing where to look next. Hence, capturing and preserving this evidence in a temporal, thematic structure is essential to scientific progress. Negative results become more valuable when they are retained as scientific state. Instead of fragmenting across notebooks, reports, conversations, institutional memory, and compressed context, structured records allow successes and dead ends to accumulate across themes and campaign rounds. Agents for science are highly capable of collecting information by orchestrating scientific tools, iterating through many designs, and identifying candidate solutions. The challenge is preserving this knowledge in a durable form that can readily re-align given far sparser experimental results to influence future decisions. In the absence of a dedicated structure for knowledge retention, valuable information is lost to context window compression, a critical but lossy technique for maintaining agent performance on long duration tasks. The scale of explorations and hypotheses increases rapidly over the course of a design campaign. This growth compounds further when scaled beyond a single campaign and rejected hypotheses. Negative results and abandoned pathways become fragmented across notebooks, reports, conversations, and institutional memory. As agentic science expands the scale and speed at which research can be accomplished, organizations have an unprecedented opportunity to capture and transform negative results from a fragmented form into durable institutional memory. Bookshelf as a Scientific State Mechanism Bookshelf was developed to represent the arc of science as a first-class object. Rather than representing only candidate molecules that were generated, we sought to maintain relationships between hypotheses, evidence, predictions, measured outcomes, unresolved contradictions, supporting rationale, and confidence over time. As such, through the evolution of Discovery Engine’s exploration in modifying the original seed scaffold, learnings were adapted and brought forward. The prime example of such interaction is in the figure below, where Engine self-organized the molecular design task into three rounds. The first and second design rounds emphasized exploration. Discovery Engine proposed a diverse collection of molecular modifications intended to probe the behavior of the benzo[c]cinnoline scaffold. This was both to identify the best candidate and to establish an empirical map of how structural changes influenced target properties. Discovery Engine organizes an ORFB molecular campaign from broad exploration to targeted follow-up. Across three rounds, measured solubility and redox-potential outcomes—including predominantly negative results—are retained in the Discovery Bookshelf and used to guide the next set of benzo[c]cinnoline derivatives. Learning from Failure Many structures designed across the first two rounds were found to be non-viable, yielding valuable negative results. Importantly, Discovery Bookshelf captured the learnings from these design rounds, preserving the arc of reasoning constructed while exploring the candidate’s modification space. The second round provides a particularly revealing example. None of Discovery Engine’s parallel explorations using CLIO mode produced a candidate suitable for advancement. Yet the round was scientifically productive. Its negative results revealed limitations in the tooling and preserved evidence that could inform the next round. Discovery Bookshelf retained those lessons, enabling four of the six explorations in the third round to succeed. This contrast demonstrates a central principle of good science: negative evidence creates value when it changes the next decision. The seed candidate, tools, compute, and problem boundary conditions were unchanged between the two rounds; what changed was how Discovery Engine interpreted the accumulated evidence and adapted its workflow for analyzing candidate options. Had only successful explorations been retained, the third round would likely have repeated the second round’s failures. Capturing, storing, and cataloging these changes in scientific judgment transforms campaign-specific lessons into reusable organizational assets. Calibrating Imperfect Predictors The preserved results also revealed why the third-round workflow needed to change. By comparing the property predictor with the limited experimental evidence, Discovery Engine identified a systematic mismatch: the redox potential predictor was not numerically accurate, but it remained directionally useful for ranking candidates. Rather than discarding the model, Discovery Engine recalibrated its trust in the predictor, treating predicted values as relative signals instead of precise estimates. This shift from trusting the predictor’s absolute values to using it as a ranking instrument changed the design workflow and enabled Engine to extract value from an imperfect scientific tool. Thematic representation and accumulation of this knowledge through Discovery Bookshelf allowed Discovery Engine to move beyond optimizing individual candidates in isolation and instead evolve the design campaign itself. In the third round, it produced a targeted set of candidate structures informed by both the most promising identified structure and a broader understanding of the design space. In any scientific organization, the ability to preserve and reuse an entire history of positive and negative results becomes increasingly important as search spaces expand. From Scientific Memory to Organizational Memory While we demonstrate Discovery for molecular discovery, the underlying principle and combination of Bookshelf as a semantic map for Engine extends beyond chemistry. Research organizations, engineering teams, and businesses all face the same challenge. Every major initiative generates large numbers of unsuccessful paths that never become final products, published papers, or approved strategies. Yet these discarded paths frequently contain valuable information that informs future decision making. Most organizations are optimized to preserve outcomes, yet few are optimized to preserve the evolution of belief that produced them. As a result, teams revisit previously explored directions, rediscover old constraints, and relearn lessons that have already been paid for. The challenge facing organizations is remarkably similar to the challenge facing scientific discovery. Both require a way to transform trajectories of exploration into durable memory. In combination with Microsoft's broader AI stack, this becomes an immensely powerful representation for agents and humans operating and capitalizing on increasing organizational value in the reverse information paradox. Co-authors Jake Smith • Karin Strauss • William Chappell2.1KViews5likes0CommentsAdaptive by Design: How Microsoft Discovery Explores Science
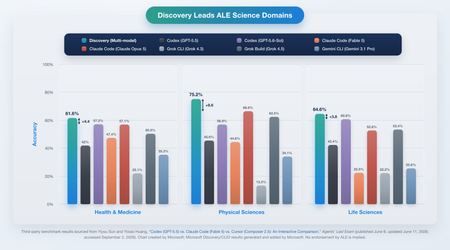
In Microsoft’s ALE evaluation, Discovery Engine with CLIO enabled leads publicly benchmarked agentic harnesses across three scientific domains. Microsoft Discovery is incorporating CLIO into Discovery Engine. Discovery Engine can effectively test competing hypotheses, learn from unsuccessful approaches, and revise reasoning toward the strongest path for success. Microsoft Discovery is incorporating CLIO (Cognitive Loop via In-Situ Optimization) into the latest releases of Discovery Engine, now available in the Discovery app and coming soon to the enterprise platform. Discovery Engine using CLIO mode achieved higher scores than all other publicly benchmarked agentic harnesses across the three scientific domains evaluated to date. With CLIO mode enabled, Discovery Engine can effectively explore competing hypotheses using tools and models, evaluate evidence, learn from unsuccessful approaches, and adjust its reasoning as new information emerges. To test the value of this update to the Discovery Engine, we ran the Agent’s Last Exam (ALE) benchmark with GPT-5.6 Sol as the default model while providing dynamic access to a broader mixture of models. Discovery Engine scored 61.6% in health and medicine versus 57.2% (+4.4%) for Codex with GPT-5.6 Sol, 75.2% in physical sciences versus 66.6% (+8.6%) Claude Code with Opus 5, and 64.6% in life sciences versus 60.8% (+3.8%) Codex with GPT-5.6 Sol. Built for the Scientific Mindset It is well established that agentic harnesses are important for accomplishing useful work. GitHub Copilot, Claude Code, Codex, and many others have made significant contributions on top of LLMs. However, these harnesses have largely been focused on workflows as they relate to software development, rather than scientific research. Discovery provides a harness for the rest of science and engineering, bringing both the scientific mindset of ideation and evidence collection, and the engineering rigor of problem decomposition and structured work to a collaborative environment. Importantly, CLIO reflects on regrets, treating unsuccessful paths as valuable information that informs its next course of action: it identifies why an approach failed, updates downstream reasoning, and redirects exploration without discarding what was learned. With Discovery Engine’s CLIO mode, we are rapidly increasing the ability to explore ideas that do not have a clear or well-researched solution. Figure 1 – Discovery Engine with CLIO enabled increased performance across all three scientific domains and provides consistency compared to individual models. Ultimately, this test of Discovery Engine's reasoning process and ability to use multiple models shows the benefit of how to increase the outcomes above any of the available models. The benefits increase further as you move from bounded direct workflow execution through exploration of new ideas and designs, but these results show that the increase even holds across a broad swath of scientific questions. Adaptive by Design Discovery Engine’s CLIO mode expands ideation and reflection to identify better options in addition to using multiple fallback models when the base model underperforms. Built using GitHub Copilot as the base harness, CLIO adds additional depth and exploration that is fit for purpose for the technical problems encountered in science and engineering. As the model ecosystem becomes increasingly diverse across performance and efficiency, having the flexibility to change is crucial to always adopting model strengths. One example of this benefit is in pursuit of Agent’s Last Exam questions where Discovery Engine switches models dynamically when facing false rejections or is otherwise unable to answer questions sufficiently using the base model. If we compare Discovery Engine to using a single specific model and harness combination, as you would experience when using a model-provider specific solution, the performance gaps expand dramatically (e.g., to +18.3% in physical sciences versus Codex with GPT-5.6 Sol, and +8.6% from Claude Code with Opus 5). The progress of ALE science tasks represented as performance average across life sciences, physical sciences, and health & medicine questions. Discovery Engine's harness and use of multi-models is crucial to improving performance and consistency. About Agent's Last Exam ALE is a large-scale, multi-disciplinary rolling benchmark released in June 2026, with 152 publicly available tasks spanning 13 professional domains and 55 subfields. Unlike benchmarks centered on question answering, ALE focuses on measuring agentic performance on tasks ranging from minutes to hours, completing deliverables using real data and tools. The questions in ALE are sufficiently difficult to stress the benefits of this update to Discovery Engine and importantly test the ability to react to scientific tools which are gathering new information in a long running agentic process. Consistent with Microsoft Discovery’s scientific focus, our evaluation focuses on three of ALE’s thirteen top-level domains: Physical Sciences, Health & Medicine, and Life Sciences. Example tasks include clinical variant annotation, molecular simulation, epidemiological forecasting, and medical-image analysis. For consistency with public benchmarking, we mirror ALE’s Strengths by Domain analysis, which reports domain level scores only for domains containing at least 10 tasks. We therefore exclude domains below that threshold as the published analysis does not provide corresponding comparison scores. Furthermore, as specified in the analysis, we benchmark comparably by following the five-hour time limit evaluation protocol rather than the two-hour limit. All attempts were immediately terminated after five hours and graded on the work produced, allowing partial credit for completed portions of the task. With CLIO mode, Discovery Engine can explore each ALE task through multiple independent approaches, within the same five-hour limit. By comparing these approaches, Discovery Engine identifies gaps, shares learnings across belief states, and successfully resolves the strongest path for each task into a single, evidence-backed answer. Accordingly, all reported domain scores are presented as Pass@1, demonstrating not only the performance gain but also the increase in reliability. Get Started Today While benchmarks like Agent’s Last Exam are useful in demonstrating Discovery’s utility for execution of scientific workflows, it has also generated real-world outcomes for high impact scenarios. Discovery Engine with CLIO mode was recently used to discover a novel organic redox flow battery negolyte. In the coming weeks, we will continue to demonstrate additional scientific use cases from chip design to radio frequency (RF) engineering to wastewater epidemiology, showing the depth and breadth of scientific applications which Discovery can enable. We are excited to see how Microsoft Discovery and CLIO can enable your hardest scientific or engineering problems. The Microsoft Discovery app is available in preview as a localized experience that gives researchers, students, academic labs, and scientific teams a simpler way to begin using Microsoft Discovery capabilities without starting with a full enterprise deployment. It is available for download on the Microsoft Discovery GitHub and users can get started with a GitHub Copilot account. Co-authored by Christine Caggiano, Joshua Bradley, Steven Truitt, and William Chappell1.5KViews3likes0Comments