blocking
8 TopicsLesson Learned #319: Lock request time out period exceeded using SSMS
Today, we got a service request that our customer got the following error message: Lock request time out period exceeded. (.Net SqlClient Data Provider) using SQL Server Management Studio. Following I would like to share with you some details about this issue and how to find and fix it.23KViews0likes0CommentsLesson Learned #330: Blocking issues Sch-M and Sch-S
Today, I worked in a very interested case. Our customer is trying to run an ALTER TABLE <TableName> to add two columns but this process is taking too much time, even, when the documentation reported "Starting with SQL Server 2012 (11.x) Enterprise Edition, adding a NOT NULL column with a default value is an online operation when the default value is a runtime constant. This means that the operation is completed almost instantaneously despite the number of rows in the table, because the existing rows in the table aren't updated during the operation" https://learn.microsoft.com/en-us/sql/t-sql/statements/alter-table-transact-sql?view=azuresqldb-current#adding-not-null-columns-as-an-online-operation7.5KViews0likes0CommentsLesson Learned #491: Monitoring Blocking Issues in Azure SQL Database
Time ago, we wrote an article Lesson Learned #22: How to identify blocking issues? today, I would like to enhance this topic by introducing a monitoring system that expands on that guide. This PowerShell script not only identifies blocking issues but also calculates the total, maximum, average, and minimum blocking times.2.2KViews0likes0Comments
Creating alerts for custom errors with auditing and Log Analytics
Errors are an inherent part of any application. As a database professional managing an Azure SQL Managed Instance, you may be interested in understanding when specific errors occur and how to leverage user-generated errors to respond swiftly when particular scenarios arise. On this post we will see how we can setup alerts for scenarios like query blocking and long open transactions. This will be an extend of what is described on How to setup alerts for deadlocks using Log Analytics | Microsoft Community Hub Step 1 - Setup Log Analytics and auditing Follow steps 1, 2, 3 and 4 described on How to setup alerts for deadlocks using Log Analytics | Microsoft Community Hub Step 2 - Create a table to save the details of the blocking chain / long open transaction Getting an alert itself is not useful if you don`t have a way of getting details for later analysis. Create the table on a database of your choice. If you are interested on blocking: CREATE TABLE [dbo].[blocking_report] ( [DateTime] [datetime] NULL ,[HeadBlocker] [varchar](1) NOT NULL ,[SessionID] [smallint] NOT NULL ,[Login] [nvarchar](128) NOT NULL ,[Database] [nvarchar](128) NULL ,[BlockedBy] [smallint] NULL ,[OpenTransactions] [int] NULL ,[Status] [nvarchar](30) NOT NULL ,[WaitType] [nvarchar](60) NULL ,[WaitTime_ms] [bigint] NULL ,[WaitResource] [nvarchar](256) NULL ,[WaitResourceDesc] [nvarchar](3072) NULL ,[Command] [nvarchar](32) NULL ,[Application] [nvarchar](128) NULL ,[TotalCPU_ms] [int] NOT NULL ,[TotalPhysicalIO_MB] [bigint] NULL ,[MemoryUse_KB] [int] NULL ,[LoginTime] [datetime] NOT NULL ,[LastRequestStartTime] [datetime] NOT NULL ,[HostName] [nvarchar](128) NULL ,[QueryHash] [binary](8) NULL ,[BlockerQuery_or_MostRecentQuery] [nvarchar](max) NULL ) If you are interested on open transactions: CREATE TABLE [dbo].[opentransactions]( [CapturedTime] [datetime] NOT NULL, [tran_elapsed_time_seconds] [int] NULL, [transaction_begin_time] [datetime] NOT NULL, [session_id] [int] NOT NULL, [database_name] [nvarchar](128) NULL, [open_transaction_count] [int] NOT NULL, [host_name] [nvarchar](128) NULL, [program_name] [nvarchar](128) NULL, [login_name] [nvarchar](128) NULL, [status] [nvarchar](30) NULL, [text] [nvarchar](max) NULL ) Step 3 - Create a SQL Agent job Schedule the two SQL Agent jobs using the queries below. You might be interested on schedule that runs every X amount of seconds/minutes. Describing very briefly what each query does: if a query is being blocked for more than 60 seconds, save the blocking chain on a table and raise an error if a transaction is open for more than 120 seconds, save the query details on a table and raise an error Make the necessary adjustments according to your goals. Query for blocking: IF ( SELECT count(*) FROM sys.dm_exec_requests WHERE wait_type LIKE 'LCK%' AND wait_time > 60000 ) > 0 -- checks for queries waiting to obtain a lock for more than 30 seconds BEGIN INSERT INTO database_name.dbo.Blocking_report -- make sure that you change the database_name value SELECT ( SELECT getdate() ) ,[HeadBlocker] = CASE WHEN r2.session_id IS NOT NULL AND ( r.blocking_session_id = 0 OR r.session_id IS NULL ) THEN '1' ELSE '' END ,[SessionID] = s.session_id ,[Login] = s.login_name ,[Database] = db_name(p.dbid) ,[BlockedBy] = w.blocking_session_id ,[OpenTransactions] = r.open_transaction_count ,[Status] = s.STATUS ,[WaitType] = w.wait_type ,[WaitTime_ms] = w.wait_duration_ms ,[WaitResource] = r.wait_resource ,[WaitResourceDesc] = w.resource_description ,[Command] = r.command ,[Application] = s.program_name ,[TotalCPU_ms] = s.cpu_time ,[TotalPhysicalIO_MB] = (s.reads + s.writes) * 8 / 1024 ,[MemoryUse_KB] = s.memory_usage * 8192 / 1024 ,[LoginTime] = s.login_time ,[LastRequestStartTime] = s.last_request_start_time ,[HostName] = s.host_name ,[QueryHash] = r.query_hash ,[BlockerQuery_or_MostRecentQuery] = txt.TEXT FROM sys.dm_exec_sessions s LEFT OUTER JOIN sys.dm_exec_connections c ON (s.session_id = c.session_id) LEFT OUTER JOIN sys.dm_exec_requests r ON (s.session_id = r.session_id) LEFT OUTER JOIN sys.dm_os_tasks t ON ( r.session_id = t.session_id AND r.request_id = t.request_id ) LEFT OUTER JOIN ( SELECT * ,ROW_NUMBER() OVER ( PARTITION BY waiting_task_address ORDER BY wait_duration_ms DESC ) AS row_num FROM sys.dm_os_waiting_tasks ) w ON (t.task_address = w.waiting_task_address) AND w.row_num = 1 LEFT OUTER JOIN sys.dm_exec_requests r2 ON (s.session_id = r2.blocking_session_id) LEFT OUTER JOIN sys.sysprocesses p ON (s.session_id = p.spid) OUTER APPLY sys.dm_exec_sql_text(ISNULL(r.[sql_handle], c.most_recent_sql_handle)) AS txt WHERE s.is_user_process = 1 AND ( r2.session_id IS NOT NULL AND ( r.blocking_session_id = 0 OR r.session_id IS NULL ) ) OR blocked > 0 ORDER BY [HeadBlocker] DESC ,s.session_id; THROW 50000 ,'There are queries being blocked for more than 60 seconds' ,1; END Query for open transactions: DECLARE @count INT = ( SELECT count(*) FROM sys.dm_tran_active_transactions at INNER JOIN sys.dm_tran_session_transactions st ON st.transaction_id = at.transaction_id LEFT OUTER JOIN sys.dm_exec_sessions sess ON st.session_id = sess.session_id LEFT OUTER JOIN sys.dm_exec_connections conn ON conn.session_id = sess.session_id OUTER APPLY sys.dm_exec_sql_text(conn.most_recent_sql_handle) AS txt WHERE DATEDIFF(SECOND, transaction_begin_time, GETDATE()) > 120 -- 120 seconds ) IF @count > 0 BEGIN INSERT INTO database_name.dbo.opentransactions -- change database_name to where the table was created SELECT GETDATE() AS CapturedTime ,DATEDIFF(SECOND, transaction_begin_time, GETDATE()) AS tran_elapsed_time_seconds ,at.transaction_begin_time ,st.session_id ,DB_NAME(sess.database_id) AS database_name ,st.open_transaction_count ,sess.host_name ,sess.program_name ,sess.login_name ,sess.STATUS ,txt.TEXT FROM sys.dm_tran_active_transactions at INNER JOIN sys.dm_tran_session_transactions st ON st.transaction_id = at.transaction_id LEFT OUTER JOIN sys.dm_exec_sessions sess ON st.session_id = sess.session_id LEFT OUTER JOIN sys.dm_exec_connections conn ON conn.session_id = sess.session_id OUTER APPLY sys.dm_exec_sql_text(conn.most_recent_sql_handle) AS txt WHERE DATEDIFF(SECOND, transaction_begin_time, GETDATE()) > 120 --120 seconds ORDER BY tran_elapsed_time_seconds DESC; THROW 50000 ,'There are open transactions for more than 120 seconds' ,1; END Step 4 - Create the alert based on a Log Analytics query Just as described on steps 6 and 7 of How to setup alerts for deadlocks using Log Analytics | Microsoft Community Hub, you can create the two separate alerts using the queries below. For blocking: AzureDiagnostics | where TimeGenerated > ago(15m) //last 15 minutes | where LogicalServerName_s == "server_name" //server name | where Category == "SQLSecurityAuditEvents" | where additional_information_s contains "There are queries being blocked for more" | project TimeGenerated, LogicalServerName_s, database_name_s, additional_information_s For open transactions: AzureDiagnostics | where TimeGenerated > ago(15m) //last 15 minutes | where LogicalServerName_s == "server_name" //server name | where Category == "SQLSecurityAuditEvents" | where additional_information_s contains "There are open transactions for more than" | project TimeGenerated, LogicalServerName_s, database_name_s, additional_information_s299Views0likes0CommentsLesson Learned #529: Troubleshooting Application Slowness Using SSMS Copilot
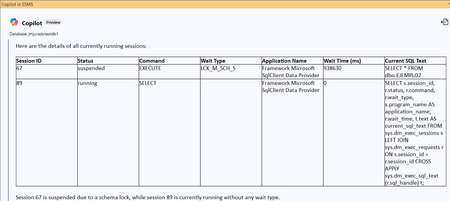
Some days ago, I worked on a support case where a customer reported application slowness affecting multiple users. Instead of jumping into traces or manually writing diagnostic queries, we used SSMS Copilot to investigate the issue. I would like to share with you how we diagnosed and understood the root cause. To illustrate the case, let’s walk through a simplified example: we create a new table, and right after that, we add a new column to it. CREATE TABLE Ejemplo2 (ID INT) BEGIN TRANSACTION ALTER TABLE dbo.eJEMPLO2 ADD NuevoCampo INT NULL Using SQL Server Management Studio and Copilot we executed the following prompt: Please, provide all currently running or suspended sessions. Include session ID, status, command, wait type (if any), application_name, wait time, and current SQL text. We got the following results: I executed multiple times the same prompt and always the session ID 67 is in suspended mode and Wait_type LCK_M_SCH_S, for this reason, I run a new prompt: Please, provide all sessions that are currently blocked by another session. Include session ID, the blocking session ID, wait type, and the blocked SQL text . At the end, I found that the session 51 is blocking the session ID 67 and for this reason, I run a new prompt: do we any have active transaction pending for commit for the session ID 51. So, I understand that the Session ID 51 has a transaction open, so, let's ask the details of the session 51, with a new prompt: Please, show the most recent SQL statement executed by session ID 51, even if the session is currently sleeping or not running any active request. Include the session status and login name as well. Use sys.dm_exec_connections and most_recent_sql_handle to retrieve the query text if necessary. Well, we identified the problem, the session ID 67 is running a SELECT * FROM sys.Ejemplo2 but it's beging blocked by the session 51. Session ID 51 hasn’t finished its transaction, and now we either need to commit, rollback, or kill that session, especially if we don’t have access to the application that owns it. Before resolving the issue, I asked Copilot an additional prompt: Please, explain why session ID 67 is currently waiting. Include the wait type, and explanation of that, the resource being waited on, how long it has been waiting (seconds), and the SQL text. Also identify if another session is blocking it. The name of the object and schema Please, provide recommendations to prevent or reduce this kind of blocking situation in the future, based on the current wait type and blocking scenario observed with session ID 67. Please, summarize all current blocking chains in the system. Include blocking session IDs, blocked session IDs, wait types, wait durations, login names, and SQL statements involved.210Views0likes0CommentsAzure SQL Performance Troubleshooting: When High Latency Is Not High CPU
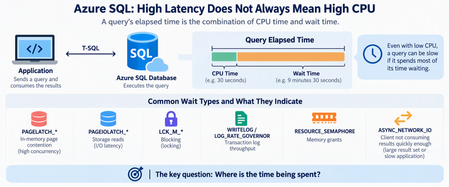
When an application connected to Azure SQL Database becomes slow or starts timing out, one of the first questions is usually: Is the database running out of CPU? It's a reasonable starting point, but CPU is only one part of the performance story. Some Azure SQL performance problems occur while CPU, Data IO, and worker utilization appear healthy. The database may have plenty of compute capacity while queries spend most of their time waiting rather than executing. The key troubleshooting question is therefore not simply: "How much CPU is Azure SQL using?" Instead, ask: "Where is the elapsed time being spent?" Start With Resources, But Don't Stop There Resource utilization should still be the first checkpoint. A simple query using sys.dm_db_resource_stats can help identify whether Azure SQL is approaching CPU, Data IO, Log IO, memory, or worker limits: SELECT DB_NAME() AS database_name, AVG(avg_cpu_percent) AS avg_cpu_percent, MAX(avg_cpu_percent) AS max_cpu_percent, MAX(avg_data_io_percent) AS max_data_io_percent, MAX(avg_log_write_percent) AS max_log_write_percent, MAX(avg_memory_usage_percent) AS max_memory_percent, MAX(max_worker_percent) AS max_worker_percent FROM sys.dm_db_resource_stats; If CPU is consistently near 100%, investigate CPU consumption. If Log IO reaches its limit, investigate transaction-log generation. If workers are exhausted, investigate concurrency. But if none of these resources is saturated, don't conclude that Azure SQL is healthy. Move to wait analysis. Follow the Waits A useful simplified model is: Query elapsed time = CPU execution If a query runs for 10 minutes but uses only 30 seconds of CPU, most of its elapsed time occurred somewhere else. Common wait patterns can point the investigation in different directions: Wait Area to investigate PAGELATCH_* In-memory page contention PAGEIOLATCH_* Storage reads LCK_M_* Blocking WRITELOG Transaction log LOG_RATE_GOVERNOR Log throughput RESOURCE_SEMAPHORE Memory grants ASYNC_NETWORK_IO Client/result consumption The wait type is not automatically the root cause. Think of it as a sign telling you: Look in this direction next. PAGELATCH Does Not Mean Slow Storage One important distinction is: PAGELATCH versus: PAGEIOLATCH Despite their similar names, they represent different problems. PAGEIOLATCH is associated with waiting for data pages involved in physical I/O. PAGELATCH, however, is synchronization around pages that are already in memory. Consider a highly concurrent workload: Hundreds of sessions ↓ Same memory page ↓ Latch contention ↓ Sessions wait ↓ Application CPU may still have available capacity. This is why increasing vCores doesn't necessarily eliminate latch contention. Additional compute provides more workload headroom, but it doesn't automatically remove a serialization point around a hot page. Microsoft's I/O troubleshooting guidance also distinguishes PAGEIOLATCH and other I/O-related waits when diagnosing storage-performance problems. Microsoft Learn: Troubleshoot SQL Server I/O performance Query Frequency Matters Too Another common mistake is focusing only on individually expensive queries. Imagine a query that takes only 20 milliseconds but executes hundreds of thousands of times, often concurrently. Its impact is better thought of as: Workload Impact = Cost per execution × Execution frequency × A small metadata lookup or initialization query can become significant when hundreds of application instances execute it simultaneously. This is where Query Store becomes particularly useful. Query Store preserves query, execution-plan, and runtime history, allowing you to compare executions, duration, CPU, plans, and other performance characteristics over time. Microsoft Learn: Monitor performance using Query Store Instead of asking only: "What's my most expensive query?" also ask: "What changed in the workload?" When Nine Hours of Duration Is Only One Minute of CPU Now consider the opposite problem. Suppose Query Store shows something like: Elapsed time 9 hours SQL CPU time 1 minute Returned rows 750,000+ Dominant wait ASYNC_NETWORK_IO Would adding CPU solve this? Probably not. CPU represents only a tiny fraction of the elapsed time. ASYNC_NETWORK_IO commonly occurs when SQL Server has results available but the client application is not consuming them quickly enough. Microsoft documents several possible causes, including: large result sets; slow application processing; applications fetching rows slowly; network-related delays. Microsoft Learn: Troubleshoot ASYNC_NETWORK_IO Importantly: ASYNC_NETWORK_IO does not automatically mean the network is slow. The bottleneck might actually be the application. Measure Time to First Row A useful troubleshooting technique is to separate database response time from result-consumption time. Instead of measuring only: Query start → Application finished measure: T0 = Query submitted T1 = First row received T2 = Last row received T3 = Application processing completed You can then separate: Database response = T1 - T0 Result consumption = T2 - T1 Application For example: First row received: 2 seconds Last row received: 2 hours Processing completed: 2.5 hours Calling this a "2.5-hour SQL query" would be misleading. SQL started returning results after two seconds. Most of the time was spent transferring or processing them. Don't Forget Blocking Low CPU can also be caused by blocking. If many sessions are waiting behind a transaction, increasing CPU isn't going to solve the problem. During an active incident, check requests and their waits: SELECT r.session_id, r.blocking_session_id, r.status, r.wait_type, r.wait_time, r.wait_resource, r.cpu_time, r.total_elapsed_time, st.text FROM sys.dm_exec_requests AS r CROSS APPLY sys.dm_exec_sql_text(r.sql_handle) AS st WHERE r.blocking_session_id <> 0 ORDER BY r.wait_time DESC; This helps determine whether the application is experiencing a resource problem or simply waiting behind another transaction. Why Scaling Can Be Misleading Imagine this sequence: Application slow ↓ Scale database ↓ Performance improves It's tempting to conclude: "We needed more CPU." But scaling can change more than CPU availability. Depending on the operation and environment, it can alter resource availability or execution conditions. Therefore: A successful mitigation does not automatically prove the root cause. Always distinguish between: What made the symptoms disappear? and: What originally caused the symptoms? A Practical Troubleshooting Workflow When investigating Azure SQL performance, I use the following approach: 1. Define the exact incident window Preferably using UTC timestamps. 2. Check core resources Look at: CPU Data IO Log IO memory workers 3. Compare CPU time with elapsed time If: Elapsed ≈ CPU investigate computational workload. If: Elapsed >>> CPU investigate waits. 4. Identify dominant waits Ask what prevented SQL from continuing execution. 5. Check blocking Determine whether requests are waiting behind other transactions. 6. Use Query Store Compare healthy and problematic periods for: execution count; CPU; duration; logical reads; plans; wait behavior. Microsoft provides Query Store examples specifically for workload and performance investigation. Microsoft Learn: Tune performance with Query Store 7. Inspect the execution plan Look for inefficient access patterns, cardinality problems, excessive reads, repeated lookups, spills, scans, or plan changes. 8. Investigate the application Especially when SQL CPU is low but result-transfer waits are high. Look at: rows returned; fetch size; batch size; application processing; concurrency; downstream dependencies. 9. Compare healthy vs unhealthy periods Don't analyze an incident in isolation. Ask: What changed? Common Misdiagnoses "CPU isn't 100%, so SQL is healthy." Not necessarily. Queries might simply be waiting. "ASYNC_NETWORK_IO means we have a network problem." Not necessarily. The client may be consuming results slowly. "PAGELATCH means storage is slow." No. Don't confuse PAGELATCH with PAGEIOLATCH. "Scaling fixed the problem, so CPU was the root cause." Not necessarily. Mitigation and root cause are different concepts. "The slowest query must be the problem." Not always. A small query executed extremely frequently can generate larger cumulative impact. Final Thought: Follow the Time When Azure SQL becomes slow, avoid jumping directly from: Slow database → Add more vCores Instead, work through: High latency ↓ Resource utilization ↓ CPU vs elapsed time ↓ Wait statistics ↓ Query Store ↓ Execution plan ↓ Application behavior ↓ Root cause ↓ Targeted optimization Performance troubleshooting becomes much easier once you stop asking only: "How busy is Azure SQL?" and start asking: "Where did the time go?" Because sometimes the database isn't busy at all. It's waiting. References Monitor Performance by Using the Query Store Tune performance with the Query Store Troubleshoot slow queries resulting from ASYNC_NETWORK_IO Troubleshoot slow SQL Server performance caused by I/O issues200Views0likes0CommentsThe Pipeline Is Slow, or Is SQL Waiting? Diagnosing Synapse-to-Azure SQL Regressions
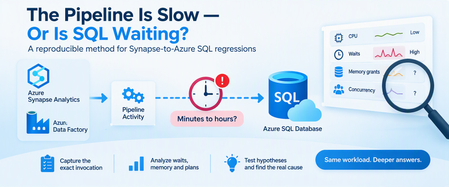
A query can consume very little CPU and still keep a pipeline waiting for hours. A pipeline activity that normally finishes in minutes suddenly starts taking hours. Nothing obvious has changed: The pipeline definition looks the same. The stored procedure looks the same. Azure SQL Database isn't showing sustained high CPU. Pipeline monitoring still points toward the SQL activity. At this point, saying "SQL is slow" isn't enough. The request may actually be: Executing expensive work. Waiting for memory. Blocked by another transaction. Reading more data than before. Running with a different execution plan. Competing with concurrent pipeline activities. Experiencing different cardinality because of different parameter values. The key is to connect the pipeline invocation to the database execution and determine where elapsed time is really going. 1. Define the Regression Precisely Before troubleshooting SQL, establish what actually changed. Capture: Expected pipeline duration. Observed pipeline duration. Pipeline activity involved. Stored procedure or statement invoked. Exact parameter values. Affected and unaffected executions. Pipeline concurrency. Retry behavior. Connection and command timeout. Deployment or configuration changes. For example: Evidence Baseline Regression Pipeline duration Minutes Much longer Stored procedure Same Same Parameter range A B Concurrent activities Low Higher Azure SQL CPU Normal Normal/moderate SQL wait behavior Unknown To investigate The most important rule is: Don't assume the SQL workload is identical simply because the stored procedure is identical. Different parameters can result in dramatically different: Row counts. Join choices. Memory grants. Sort requirements. Execution plans. Total duration. 2. Preserve the Exact Invocation One of the easiest ways to lose a performance regression is to reproduce it with different parameters. Capture the invocation before testing: Procedure name. Parameter values. Date range. Entity or partition identifier. Batch size. Pipeline run ID. Retry number. Number of parallel activities. Relevant timeout configuration. Then sanitize any business-sensitive values before sharing them outside your organization. The diagnostic principle is simple: Reproduce the same workload before trying to improve the workload. 3. Reproduce Safely Whenever possible, reproduce the issue using: A nonproduction database containing representative data. A controlled production troubleshooting window. The same stored procedure. The same parameter pattern. Comparable concurrency. For a controlled test, SQL execution statistics can help: SET STATISTICS IO ON; SET STATISTICS TIME ON; EXEC dbo.SampleProcedure @StartDate = '2026-01-01', @EndDate = '2026-01-31', @EntityID = 100; SET STATISTICS TIME OFF; SET STATISTICS IO OFF; Replace these synthetic names and values with the sanitized equivalent of the invocation you're investigating. Capture: Elapsed time. CPU time. Logical reads. Physical reads when relevant. Execution plan. Returned row count. The goal isn't simply to reproduce "slow." The goal is to understand why it is slow. 4. First Question: Is SQL Running or Waiting? This distinction changes the entire investigation. During the slow execution, examine the active request. SELECT r.session_id, r.request_id, r.status, r.command, r.start_time, r.cpu_time, r.total_elapsed_time, r.wait_type, r.wait_time, r.last_wait_type, r.wait_resource, r.blocking_session_id, r.reads, r.writes, r.logical_reads, r.row_count FROM sys.dm_exec_requests AS r WHERE r.database_id = DB_ID() ORDER BY r.total_elapsed_time DESC; sys.dm_exec_requests is supported for Azure SQL Database and exposes information about currently executing requests. Pay particular attention to the relationship between: cpu_time and: total_elapsed_time Suppose a request has: Very high elapsed time. Relatively little accumulated CPU time. A significant current wait. That's a strong reason to investigate waiting, rather than immediately treating the problem as insufficient CPU. Conversely: High elapsed time. High accumulated CPU. High logical reads. points more strongly toward expensive execution. 5. Identify Blocking Another request may be preventing the pipeline's SQL request from progressing. Start with: SELECT session_id, status, wait_type, wait_time, wait_resource, blocking_session_id, cpu_time, total_elapsed_time FROM sys.dm_exec_requests WHERE blocking_session_id <> 0 ORDER BY wait_time DESC; Blocking can explain a scenario where: Pipeline duration increases dramatically. Database CPU remains moderate. The SQL activity appears "active" for a long time. Microsoft documents sys.dm_exec_requests as one of the tools for identifying requests suspended on lock-related waits and tracing blocking behavior in Azure SQL Database. Don't confuse: "The SQL call took two hours." with: "SQL executed for two hours." Those statements aren't necessarily equivalent. 6. Look at the SQL That's Actually Running During an active incident, retrieve the request and its current SQL text: SELECT r.session_id, r.status, r.command, r.cpu_time, r.total_elapsed_time, r.wait_type, r.blocking_session_id, r.logical_reads, txt.text AS batch_text FROM sys.dm_exec_requests AS r CROSS APPLY sys.dm_exec_sql_text(r.sql_handle) AS txt WHERE r.database_id = DB_ID() ORDER BY r.total_elapsed_time DESC; sys.dm_exec_sql_text accepts the sql_handle exposed by sys.dm_exec_requests and returns the associated SQL batch text. This helps validate an important cross-service question: Is the database executing the statement we think the pipeline invoked? 7. Investigate Memory Grants Some operations need execution memory before they can proceed efficiently. Common examples include: Sorts. Hash joins. Hash aggregates. Some index operations. sys.dm_exec_query_memory_grants exposes queries that: Requested a memory grant and received one. Requested a memory grant and are still waiting. It is supported for Azure SQL Database. SELECT mg.session_id, mg.request_id, mg.dop, mg.request_time, mg.grant_time, mg.requested_memory_kb, mg.granted_memory_kb, mg.required_memory_kb, mg.used_memory_kb, mg.max_used_memory_kb, mg.query_cost, mg.timeout_sec, mg.resource_semaphore_id FROM sys.dm_exec_query_memory_grants AS mg ORDER BY mg.requested_memory_kb DESC; Interpret the important columns carefully: requested_memory_kb Memory requested by the query. granted_memory_kb Memory actually granted. required_memory_kb Minimum memory required for execution. used_memory_kb Memory currently being used. max_used_memory_kb Maximum used so far. grant_time NULL when the requested grant hasn't yet been granted. Microsoft specifically documents that queries waiting for memory grants appear in this DMV, and that grant_time remains NULL until the grant is provided. 8. Find Waiting Memory Grants During the active regression, focus specifically on requests that haven't received their grants: SELECT mg.session_id, mg.request_id, mg.request_time, mg.grant_time, mg.requested_memory_kb, mg.required_memory_kb, mg.granted_memory_kb, mg.timeout_sec, mg.dop, mg.query_cost FROM sys.dm_exec_query_memory_grants AS mg WHERE mg.grant_time IS NULL ORDER BY mg.request_time; If the affected session repeatedly appears here, you now have meaningful evidence supporting a memory-grant contention hypothesis. But that's still not enough to state: "Memory grants caused the pipeline regression." You should also establish: Whether the waiting session is actually the pipeline request. How long it remained waiting. Whether other statements were consuming large grants. Whether concurrency changed. Whether the execution plan requested unusually large memory. Why the query requested that amount of memory. That last question is particularly important. Memory-grant problems can be downstream symptoms of: Poor cardinality estimates. Large sorts. Large hash joins. Plan changes. Data growth. Parameter sensitivity. Microsoft's memory-grant troubleshooting guidance emphasizes that operations such as sorts and hash operations can require execution-memory reservations and that these grants exist for the lifetime of the query. Memory-grant contention is a diagnostic hypothesis until the evidence supports causality. 9. Pipeline Concurrency Is Database Concurrency This connection is easy to overlook. Suppose one stored-procedure invocation performs acceptably. Now imagine the orchestration layer starts: 2 copies concurrently. 5 copies concurrently. 10 copies concurrently. 20 copies concurrently. Each execution may individually be reasonable. Together, they can compete for: CPU. Workers. Memory grants. Buffer pool resources. I/O. Locks. This means: A pipeline concurrency change is also a database workload change. Even when: SQL code hasn't changed. Database configuration hasn't changed. Stored procedure code hasn't changed. As part of troubleshooting, compare: Single-execution performance. Typical production concurrency. Regression-period concurrency. Temporarily reducing pipeline concurrency can also be a valuable diagnostic experiment, provided the change is safe for the workload. 10. Capture the Live Execution Plan For a request that's still executing, Azure SQL Database supports sys.dm_exec_query_statistics_xml(), which returns Showplan XML containing transient execution statistics for an in-flight request. First identify the target session: SELECT session_id, request_id, status, command, cpu_time, total_elapsed_time, wait_type, logical_reads FROM sys.dm_exec_requests WHERE database_id = DB_ID() ORDER BY total_elapsed_time DESC; Then, for a known session: DECLARE @SessionID smallint = 123; SELECT qsx.session_id, qsx.request_id, qsx.query_plan FROM sys.dm_exec_query_statistics_xml(@SessionID) AS qsx; Replace 123 with the session being investigated. The live plan can help answer: Which operator is consuming time? How many rows are flowing through operators? Are estimates diverging significantly from runtime behavior? Are large joins or sorts involved? Where does execution appear to be spending time? Microsoft describes access to execution-plan runtime information as particularly useful when investigating long-running queries, because the information can be inspected without waiting for the query to finish. Use live-plan collection purposefully, especially on heavily loaded production systems. 11. Compare Historical Behavior in Query Store A live snapshot explains what's happening now. Query Store helps answer: What was happening when the query used to be fast? For example, find queries with multiple retained Query Store plans: SELECT TOP (50) q.query_id, COUNT(DISTINCT p.plan_id) AS plan_count, COUNT(DISTINCT p.query_plan_hash) AS distinct_plan_shapes, MIN(p.first_execution_time) AS first_plan_execution, MAX(p.last_execution_time) AS last_plan_execution FROM sys.query_store_query AS q JOIN sys.query_store_plan AS p ON q.query_id = p.query_id GROUP BY q.query_id HAVING COUNT(DISTINCT p.plan_id) > 1 ORDER BY plan_count DESC; Multiple plans aren't automatically evidence of a problem. Instead, investigate whether plan changes correlate with: Pipeline regressions. Duration changes. CPU changes. Logical-read changes. Memory behavior. Different parameter populations. 12. Compare Runtime Distributions, Not Just Averages Averages can hide regression patterns. Consider: Most executions take 10 seconds. A few take 45 minutes. The average won't fully describe the operational impact. For a known Query Store query_id, compare plans and runtime intervals: DECLARE @QueryID bigint = 123; SELECT p.plan_id, rsi.start_time, rsi.end_time, SUM(rs.count_executions) AS execution_count, CAST(AVG(rs.avg_duration) / 1000.0 AS decimal(18,2)) AS avg_duration_ms, CAST(MAX(rs.max_duration) / 1000.0 AS decimal(18,2)) AS max_duration_ms, CAST(AVG(rs.avg_cpu_time) / 1000.0 AS decimal(18,2)) AS avg_cpu_ms, CAST(AVG(rs.avg_logical_io_reads) AS decimal(18,2)) AS avg_logical_reads FROM sys.query_store_query AS q JOIN sys.query_store_plan AS p ON q.query_id = p.query_id JOIN sys.query_store_runtime_stats AS rs ON p.plan_id = rs.plan_id JOIN sys.query_store_runtime_stats_interval AS rsi ON rs.runtime_stats_interval_id = rsi.runtime_stats_interval_id WHERE q.query_id = @QueryID GROUP BY p.plan_id, rsi.start_time, rsi.end_time ORDER BY rsi.start_time DESC, p.plan_id; Replace 123 with the Query Store ID being investigated. Compare: Fast periods. Slow periods. Plans. Execution counts. CPU. Duration. Logical reads. This often produces a better picture than looking at lifetime averages. 13. Don't Force the Fastest Historical Plan Yet Suppose Query Store shows: Plan A took 30 seconds. Plan B takes 20 minutes. It might be tempting to immediately force Plan A. But first ask: How many times did Plan A execute? Which parameters used Plan A? Was the data distribution comparable? Was workload concurrency comparable? Did Plan A perform well repeatedly? Is the query parameter sensitive? A plan that was excellent for one parameter combination might be disastrous for another. The goal isn't to find the lowest historical duration. The goal is to find the plan behavior that's safe for the intended workload. If plan forcing is tested, define rollback criteria before deployment. 14. Test One Hypothesis at a Time Avoid simultaneously changing: Statistics. Indexes. Query code. Pipeline concurrency. Plan forcing. Compute tier. Doing everything together may improve performance, but you'll learn very little about why. Instead: Hypothesis: stale or inaccurate statistics Test: Appropriate statistics maintenance. Same parameters. Same concurrency. Then measure again. Hypothesis: memory-grant contention Test safely with: Reduced concurrency. Same parameter set. Same procedure. Same database configuration. Then compare: Grant wait behavior. Elapsed time. CPU time. Query plan. Hypothesis: plan regression Compare: Historical plans. Representative parameters. Runtime distributions. Only then evaluate targeted plan intervention. Hypothesis: poor cardinality Look for: Estimate-to-actual row differences. Parameter sensitivity. Implicit conversions. Sort/hash behavior. Excessive memory requests. This approach turns troubleshooting from guesswork into experimentation. 15. Correlation Is Not Root Cause This is perhaps the most important principle in cross-service troubleshooting. Suppose you see: A slow pipeline. A SQL memory-grant wait. Several concurrent activities. Those facts are correlated. They don't yet prove: "Memory contention caused the pipeline regression." A stronger conclusion requires a causal chain such as: The pipeline invokes the identified SQL request. That request repeatedly waits for execution memory during the regression. Competing queries hold substantial memory grants during the same period. Reducing the competing concurrency removes or materially reduces the grant wait. The same SQL invocation then returns toward its normal runtime. Repeating the workload reproduces the relationship. Now the evidence for causality is much stronger. This distinction matters because Azure SQL memory pressure can arise from several sources, including the chosen service objective, aggregate workload demand, and individual query memory demand. 16. Build a Cross-Service Evidence Package For difficult Synapse or Data Factory to Azure SQL regressions, both teams should be able to work from the same timeline. Capture: Pipeline evidence Pipeline run ID. Activity name. Activity start and end times. Sanitized parameters. Retry count. Timeout. Concurrent activities. Azure SQL evidence Session/request identification when captured live. Query Store query_id. Query Store plan_id. Runtime intervals. CPU time. Elapsed time. Logical reads. Wait type. Blocking session. Memory grant information. Execution plan. Investigation evidence Separate everything into: Facts Pipeline execution took longer than baseline. SQL request was identified. Request waited for memory. Multiple pipeline activities overlapped. A different plan appeared during the regression. Hypotheses Pipeline concurrency created memory-grant contention. Cardinality changes increased the requested memory grant. Parameter sensitivity caused a plan regression. Blocking contributed to runtime. Resource contention amplified an otherwise acceptable query. Experiments Document: What changed. Why it changed. Test duration. Result. Whether the hypothesis was strengthened or weakened. This prevents the pipeline and database teams from investigating two different incidents that simply happened at the same time. A Practical Decision Tree When a Synapse or Data Factory pipeline's Azure SQL activity suddenly becomes slow: 1. Can you identify the exact invocation? No Capture it before continuing. Yes Reproduce with equivalent parameters and concurrency. 2. Is SQL consuming significant CPU? Yes Investigate: Execution plan. Logical reads. Cardinality. Indexing. Parameter sensitivity. No Look at waits. 3. Is the request blocked? Yes Investigate: Blocking session. Transaction duration. Locking pattern. No Continue. 4. Is the request waiting for a memory grant? Yes Investigate: Requested versus granted memory. Other active grants. Sorts and hash operations. Cardinality estimates. Pipeline concurrency. No Investigate the actual current wait. 5. Did the execution plan change? Yes Compare: Runtime distributions. Parameter sets. CPU. Reads. Memory requirements. No Continue correlating waits, workload volume, and concurrency. 6. Does reducing concurrency improve the same invocation? Yes Resource competition becomes a stronger hypothesis. No Continue investigating query-specific behavior. Final Takeaway When a pipeline goes from minutes to hours, the fact that the Azure SQL activity is taking a long time doesn't automatically mean Azure SQL is spending all that time executing. The request might be spending much of its lifetime: Waiting for memory. Waiting behind another transaction. Waiting for another resource. Executing with a different plan. Processing a different parameter population. Competing with concurrent pipeline activities. A reliable investigation connects two perspectives: Pipeline context What exactly was invoked? With which parameters? At what time? At what concurrency? Database context Was the SQL request executing or waiting? How much CPU did it actually consume? What was it waiting for? Which plan did it use? How much memory did it request? What else was happening concurrently? sys.dm_exec_requests can identify active requests and their current execution state, while sys.dm_exec_query_memory_grants exposes statements that have requested or received execution memory. Azure SQL Database also supports obtaining transient plan information for in-flight requests through sys.dm_exec_query_statistics_xml(). Most importantly: Treat waits, memory grants, plan changes, and concurrency as evidence to test, not automatic root causes. That is how "the pipeline is slow" becomes a reproducible, evidence-backed performance diagnosis.