benchmarking
66 Topics
From Silicon to Service: Bringing AMD Helios™ to Azure
Article contributed by: Yash Bhamare and Anna Daly Azure’s ND MI455X v7 brings a rack-scale approach to AI inference, powered by AMD Helios. Each liquid-cooled compute rack combines 72 MI455X GPUs, 18 AMD EPYC “Venice” CPUs, and 31 TB of HBM4 memory, with a two-tier Ethernet backend connecting racks into larger clusters. Designed for reasoning, long-context inference, search, and multi-agent services, the platform brings compute, memory, and networking together to support demanding AI workloads. In the Azure context, “silicon to service” describes the engineering around that hardware foundation and deploying the hardware at scale. Start with the user’s needs Consider a user who asks a trained AI model a question and receives a response. For that user, the response is the result that matters. Microsoft provides the infrastructure behind that experience as a cluster product, including GPU capacity and a commitment to its availability and reliability. Users need confidence that their GPUs will be available when needed, that the next job will run reliably, that updates will leave the system usable, and that faults will leave enough evidence for diagnosis. Reliability lets model teams and engineers focus on their models rather than rediscovering machine state. It requires infrastructure that can be deployed, observed, updated, and recovered predictably. Datacenter requirements At Microsoft, we deliver AI supercomputing clusters as a product. With AMD, we design from the rack up to meet customer workload requirements. We account for power, cooling, and physical fit so each rack can be deployed, operated, and maintained in the datacenter throughout its lifetime. A Microsoft-owned, two-tier back-end network connects racks for high-bandwidth communication. Our job is to bring compute, networking, software, and physical infrastructure together into a system customers can use reliably. Hardware availability shapes how we get there, and a standalone rack lets us advance software enablement and rack-local testing, but validating the cluster requires connected racks and the back-end network operating together under load. That is why we include power delivery, cooling, cabling, and software versions in the test configuration rather than treating them as separate concerns. The same principle applies after maintenance. We confirm that a replacement component responds and works within the connected system. Establish a repeatable software foundation System firmware, the operating-system kernel and device drivers must work together to initialize and manage hardware. Testing each layer alone cannot establish how the stack behaves. A versioned baseline recipe of all firmware components, the operating-system image, GPU and network drivers, and diagnostic tools are tested together. This supports reproducible installation in cloud-scale datacenters and helps distinguish hardware faults from configuration or integration issues. Secure boot and driver signing also belong in that baseline and repeatability must preserve Microsoft’s trust requirements. When expected behavior changes, the baseline provides a traceable starting point for investigation. Bring cloud management into the lab early Our work starts when the first systems power on in the lab, and since early hardware is limited and still evolving, we focus on iterating quickly by testing whatever we can, fixing what we find, and testing again. The first milestone is a stable foundation, where each system reliably boots the target operating system, discovers and initializes its devices, and reports their health. Getting there often exposes subtle interactions between firmware, drivers, and the operating system that we need to resolve before more advanced testing can begin. Once the system is stable, we turn to performance, starting with microbenchmarks for GPU compute, memory bandwidth, and GPU-to-GPU and network transfers, and using tools such as TransferBench and RCCL tests to characterize how accelerators communicate. These simple tests are especially valuable during bring-up because an unexpected result can point to a firmware defect, a driver issue, or a configuration problem. From there, we step up to distributed training and inference workloads to see how compute, memory, and networking behave together under sustained load and where the software stack needs tuning. Alongside this work, we validate how device inventory and configuration integrate with Azure for health reporting, updates, and recovery, so the tests, tooling, and management workflows we refine in the lab are ready to scale in the datacenter. Burn-In – Make readiness an engineering outcome Burn-in is where we take the same kinds of tests we ran in the lab and automate them at scale in the datacenter. Before a cluster reaches customers, we lock in an approved hardware and software configuration and use SuperBench to orchestrate sustained workloads across the whole system. Running these workloads for extended periods across thousands of GPUs surfaces intermittent hardware failures, thermal problems, and performance anomalies that shorter lab runs can miss. The communication tests from the lab also expand to cover the full network, both within racks (scale-up) and across racks (scale-out), where RCCL collectives such as AllReduce and AllGather expose bandwidth bottlenecks, topology misconfigurations, and failures that only appear at scale. After any faulty components are repaired or replaced and retested, the cluster enters production with data showing it can sustain demanding distributed AI workloads at expected performance and run reliably as one system. Exercise recovery as normal operation Once GPU racks enter production and begin running customer workloads, hardware failures are inevitable over time. These failures may manifest as workload performance degradation, unexpected errors, or device failures that must be traced to specific hardware components across one or more systems. To maintain cluster capacity, healthy spare nodes replace affected systems, while faulty nodes are moved to dedicated quarantine racks for further investigation. There, we run extensive diagnostics to isolate the underlying issues and repair or replace faulty components. Repair alone, however, is not sufficient to return a system to production. While still in quarantine, the repaired node undergoes another round of validation, running representative workloads against established performance and reliability baselines. This ensures that the original issue has been resolved and that the system performs as expected under realistic operating conditions. Once the node passes these checks, it becomes a healthy spare, ready to replace the next system requiring maintenance. This creates a continuous cycle of detection, isolation, repair, validation, and reuse, allowing Azure to maintain reliable GPU capacity as hardware ages and individual components fail. We apply the same rigor to system updates, looking across the GPU, firmware, operating system, and network layers to verify that the system remains healthy and workloads can continue or recover predictably after a change. Come and See it at SC26 This is what we mean by Microsoft delivering AI Supercomputing Clusters. Yash Bhamare and Anna Daly will share more in their session at the Microsoft booth (#3411) at SC26, on Wednesday 18 November at 10:00am CT.
Azure Delivers Strong MLPerf Inference v6.1 Results with NVIDIA GB300 & GB200
By Mark Gitau and Azin Heidarshenas In the MLPerf Inference v6.1 round, Azure demonstrated strong Deepseek-R1 performance on GB300 NVL72 and GB200 NVL72 platforms. Azure submitted GB200 results at 18-node (1-rack) and 72-node (4-rack) scale, and GB300 results at 18 nodes (1 rack), marking our first rack-scale and cross-rack MLPerf Inference submissions. According to results published by MLCommons, Azure achieved the highest reported Interactive score on GB300 NVL72 and the highest reported Server and Offline scores on GB200 NVL72 at both 1- and 4-rack scale, demonstrating the ability to sustain high throughput across latency-constrained and throughput-optimized deployment scenarios. DeepSeek-R1 is a large Mixture-of-Experts (MoE) model, making it an ideal benchmark for modern AI infrastructure. It stresses compute, networking (both NVLink and scale-out network), memory, and serving infrastructure under realistic large-scale deployment conditions. As a result, performance is determined by the effectiveness of the entire system stack rather than GPU capability alone. MLPerf Inference evaluates system performance across several deployment scenarios. Offline measures maximum throughput for batch-oriented workloads with no latency constraints. Server simulates production online serving, where requests arrive continuously and systems must maximize throughput while meeting latency targets, evaluating how efficiently a system balances responsiveness and utilization. Interactive focuses on user-facing AI experiences by measuring token generation performance under stringent latency requirements on metrics such as time-to-first token and token-to-token latency. Together, these scenarios provide a comprehensive view of both throughput and real-time serving performance. Results Summary Scenario Throughput (Tokens/second) Platform Interactive Offline Server ND GB300 NVL72 (18 nodes) 260,098 661,143 589,391 ND GB200 NVL72 (18 nodes) - 542,075 426,796 ND GB200 NVL72 (72 nodes) - 2,091,190 1,598,510 Beyond the top results on GB200, Azure's GB300 submission achieved 97.7% of the best reported Server performance and 95.8% of the best reported Offline performance while maintaining the highest Interactive performance among all reported submissions. Together, these results demonstrate competitive performance across diverse deployment scenarios and highlight the strength of Azure's full-stack AI infrastructure. Acknowledgments This submission was led by Mark Gitau and Azin Heidarshenas, who drove the benchmarking, performance characterization, and submission efforts across GB200 and GB300 platforms. MLPerf from MLCommons® MLCommons® is an open engineering consortium of AI leaders from academia, research, and industry where the mission is to “build fair and useful benchmarks” that provide unbiased evaluations of training and inference performance for hardware, software, and services—all conducted under predetermined conditions.Adaptive by Design: How Microsoft Discovery Explores Science
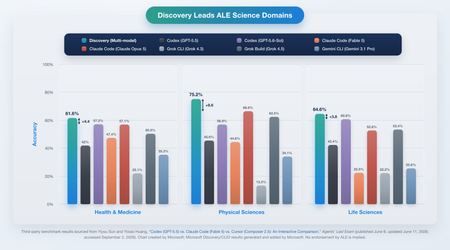
In Microsoft’s ALE evaluation, Discovery Engine with CLIO enabled leads publicly benchmarked agentic harnesses across three scientific domains. Microsoft Discovery is incorporating CLIO into Discovery Engine. Discovery Engine can effectively test competing hypotheses, learn from unsuccessful approaches, and revise reasoning toward the strongest path for success. Microsoft Discovery is incorporating CLIO (Cognitive Loop via In-Situ Optimization) into the latest releases of Discovery Engine, now available in the Discovery app and coming soon to the enterprise platform. Discovery Engine using CLIO mode achieved higher scores than all other publicly benchmarked agentic harnesses across the three scientific domains evaluated to date. With CLIO mode enabled, Discovery Engine can effectively explore competing hypotheses using tools and models, evaluate evidence, learn from unsuccessful approaches, and adjust its reasoning as new information emerges. To test the value of this update to the Discovery Engine, we ran the Agent’s Last Exam (ALE) benchmark with GPT-5.6 Sol as the default model while providing dynamic access to a broader mixture of models. Discovery Engine scored 61.6% in health and medicine versus 57.2% (+4.4%) for Codex with GPT-5.6 Sol, 75.2% in physical sciences versus 66.6% (+8.6%) Claude Code with Opus 5, and 64.6% in life sciences versus 60.8% (+3.8%) Codex with GPT-5.6 Sol. Built for the Scientific Mindset It is well established that agentic harnesses are important for accomplishing useful work. GitHub Copilot, Claude Code, Codex, and many others have made significant contributions on top of LLMs. However, these harnesses have largely been focused on workflows as they relate to software development, rather than scientific research. Discovery provides a harness for the rest of science and engineering, bringing both the scientific mindset of ideation and evidence collection, and the engineering rigor of problem decomposition and structured work to a collaborative environment. Importantly, CLIO reflects on regrets, treating unsuccessful paths as valuable information that informs its next course of action: it identifies why an approach failed, updates downstream reasoning, and redirects exploration without discarding what was learned. With Discovery Engine’s CLIO mode, we are rapidly increasing the ability to explore ideas that do not have a clear or well-researched solution. Figure 1 – Discovery Engine with CLIO enabled increased performance across all three scientific domains and provides consistency compared to individual models. Ultimately, this test of Discovery Engine's reasoning process and ability to use multiple models shows the benefit of how to increase the outcomes above any of the available models. The benefits increase further as you move from bounded direct workflow execution through exploration of new ideas and designs, but these results show that the increase even holds across a broad swath of scientific questions. Adaptive by Design Discovery Engine’s CLIO mode expands ideation and reflection to identify better options in addition to using multiple fallback models when the base model underperforms. Built using GitHub Copilot as the base harness, CLIO adds additional depth and exploration that is fit for purpose for the technical problems encountered in science and engineering. As the model ecosystem becomes increasingly diverse across performance and efficiency, having the flexibility to change is crucial to always adopting model strengths. One example of this benefit is in pursuit of Agent’s Last Exam questions where Discovery Engine switches models dynamically when facing false rejections or is otherwise unable to answer questions sufficiently using the base model. If we compare Discovery Engine to using a single specific model and harness combination, as you would experience when using a model-provider specific solution, the performance gaps expand dramatically (e.g., to +18.3% in physical sciences versus Codex with GPT-5.6 Sol, and +8.6% from Claude Code with Opus 5). The progress of ALE science tasks represented as performance average across life sciences, physical sciences, and health & medicine questions. Discovery Engine's harness and use of multi-models is crucial to improving performance and consistency. About Agent's Last Exam ALE is a large-scale, multi-disciplinary rolling benchmark released in June 2026, with 152 publicly available tasks spanning 13 professional domains and 55 subfields. Unlike benchmarks centered on question answering, ALE focuses on measuring agentic performance on tasks ranging from minutes to hours, completing deliverables using real data and tools. The questions in ALE are sufficiently difficult to stress the benefits of this update to Discovery Engine and importantly test the ability to react to scientific tools which are gathering new information in a long running agentic process. Consistent with Microsoft Discovery’s scientific focus, our evaluation focuses on three of ALE’s thirteen top-level domains: Physical Sciences, Health & Medicine, and Life Sciences. Example tasks include clinical variant annotation, molecular simulation, epidemiological forecasting, and medical-image analysis. For consistency with public benchmarking, we mirror ALE’s Strengths by Domain analysis, which reports domain level scores only for domains containing at least 10 tasks. We therefore exclude domains below that threshold as the published analysis does not provide corresponding comparison scores. Furthermore, as specified in the analysis, we benchmark comparably by following the five-hour time limit evaluation protocol rather than the two-hour limit. All attempts were immediately terminated after five hours and graded on the work produced, allowing partial credit for completed portions of the task. With CLIO mode, Discovery Engine can explore each ALE task through multiple independent approaches, within the same five-hour limit. By comparing these approaches, Discovery Engine identifies gaps, shares learnings across belief states, and successfully resolves the strongest path for each task into a single, evidence-backed answer. Accordingly, all reported domain scores are presented as Pass@1, demonstrating not only the performance gain but also the increase in reliability. Get Started Today While benchmarks like Agent’s Last Exam are useful in demonstrating Discovery’s utility for execution of scientific workflows, it has also generated real-world outcomes for high impact scenarios. Discovery Engine with CLIO mode was recently used to discover a novel organic redox flow battery negolyte. In the coming weeks, we will continue to demonstrate additional scientific use cases from chip design to radio frequency (RF) engineering to wastewater epidemiology, showing the depth and breadth of scientific applications which Discovery can enable. We are excited to see how Microsoft Discovery and CLIO can enable your hardest scientific or engineering problems. The Microsoft Discovery app is available in preview as a localized experience that gives researchers, students, academic labs, and scientific teams a simpler way to begin using Microsoft Discovery capabilities without starting with a full enterprise deployment. It is available for download on the Microsoft Discovery GitHub and users can get started with a GitHub Copilot account. Co-authored by Christine Caggiano, Joshua Bradley, Steven Truitt, and William Chappell1.7KViews3likes0CommentsScaling AI Storage: Azure Managed Lustre excels in MLPerf Storage v3.0
In large scale AI clusters storage is responsible for delivering training data fast enough to keep accelerators busy and completing checkpoint saves and recoveries quickly enough to avoid costly stalls. MLPerf Storage is an industry-standard benchmark developed by MLCommons that reproduces the I/O patterns of different stages of AI pipelines covering training, checkpointing, context cache and vector database scenarios, reporting how efficiently a storage system can sustain the I/O rates required by the workload maximizing accelerators throughput without introducing bottlenecks. Azure submitted results in the MLPerf Storage v3.0 round, and its training and checkpointing results rank as the top submissions among major hyperscalers, in both demonstrated scale and sustained performance. In checkpointing, Azure Managed Lustre reached 642.2 GiB/s of write throughput and 489.6 GiB/s during recovery, showing the highest peak write performance for both the 405B and 1T model configurations among hyperscalers and public cloud submissions. In training, Azure Managed Lustre demonstrated the ability to sustain the required accelerator utilization with hundreds of GiB/s across five different tiers and file systems ranging from 40 TiB to the largest system presented in the submission, a 25 PiB file system in a single POSIX namespace. These peer-reviewed results demonstrate that Azure Managed Lustre is a service built for the scale AI now demands and that can sustain the storage performance required to keep AI accelerators highly utilized across different stages of AI workloads. What the Benchmark Measures MLPerf Storage answers one question: how effectively can a storage system keep AI accelerators highly utilized and operating efficiently? In a modern AI cluster, accelerators are among the most constrained and expensive resources. Every second they wait for training samples or checkpoint I/O reduces the productive value of provisioned compute. MLPerf Storage isolates the storage path and measures whether it can sustain the I/O rate required by a representative AI workload. The benchmark has an OPEN and a CLOSED division. In the CLOSED division, workload code and benchmark parameters are standardized, while submitters may tune the storage system within the benchmark rules. This constraint reduces variation outside the storage path and makes results more directly comparable across submitters. Azure submitted every reported result in CLOSED division. Training category The training category evaluates whether a storage system can sustain the data-delivery rate required to keep simulated accelerators utilized throughout an extended time window, rather than only demonstrating a short burst of peak throughput. Why it matters: accelerators represent the widest portion of an AI cluster’s cost, and storage stalls reduce the productive value of provisioned compute. Because the benchmark evaluates simulated accelerator utilization rather than raw bandwidth alone, a passing score indicates that the storage path sustained the required workload’s data-delivery requirements without becoming a bottleneck. Checkpointing category The checkpointing category measures how quickly a storage system can write model state at a synchronization barrier and read that state during recovery, including recovery on different client hosts. These operations model the storage demands involved when a distributed training job resumes after a failure. Why it matters: checkpoint writes pause progress across a distributed training job, making checkpoint duration a shared overhead for the cluster with accelerator stalling. Faster writes let teams checkpoint more often and reduce the work at risk without significantly affecting accelerator utilization, while faster recovery reads shorten the time required to resume a disrupted job. What Was Tested Every result used Azure Managed Lustre, a managed parallel file system that presents clients with a single POSIX namespace. Testing covered five service tiers and file-system capacities from 40 TiB to approximately 25 PiB. MLPerf Storage generates workload I/O from standard client nodes rather than GPU nodes, and the submission used publicly available Azure virtual machine SKUs, network configurations, deployment patterns, and service interfaces. Results were produced across multiple Azure regions using configurations available to customers today. Together with the published system descriptions and configuration details, these results provide a practical reference for evaluating Azure Managed Lustre performance. In the training category, Azure Managed Lustre sustained throughput and maintained simulated accelerator utilization above 90% for five consecutive hours on the UNET3D workload with 13 distinct system configurations. The submitted configurations ranged from tens of TiB to tens of PiB and delivered sustained throughput in the hundreds of GiB/s. The five-hour result demonstrates predictable storage performance over an extended benchmark run rather than a short-lived burst. AMLFS delivers target performance across all service tiers, enabling customers to optimize capacity and performance for each workload without compromising accelerator utilization, as shown in Figure 1. Figure 1, AMLFS UNET3D Training performance (B200) across different bandwidth density configurations Most relevant to highlight is how Azure Managed Lustre delivers at more than 96% the nominal bandwidth density across all tiers tested in training category, and how the results, taking AMLFS 125 as a tier, scale almost linearly increasing the number of accelerators (Figure 2). Figure 2, AMLFS UNET3D Training performance (B200) delivered bandwidth density and scalability. In checkpointing category, the benchmark covered four Llama3 scales, from an 8B model with a 105 GB checkpoint to a 1T-class model with an 18 TB checkpoint, and Azure submitted results for all four. Within those benchmark rules, Azure Managed Lustre reached up to 642 GiB/s of checkpoint write throughput and up to 490 GiB/s during recovery, enabling the tested checkpoints to be written and restored in tens of seconds or less. For checkpointing, AMLFS 125 has been picked as example tier, but similar results are expected, as demonstrated in the training scenario, with different AMLFS tiers. Figure 3, AMLFS checkpointing performance across different model size. The published results give the AI community a peer-reviewed view of Azure Managed Lustre under modern AI workloads, including sustained throughput, predictable performance, and deployment choices across service tiers. Full system descriptions and performance numbers are available in the MLCommons MLPerf Storage v3.0 results tables. Five Tiers, 20 to 500 MB/s per TiB, One Right Size for Every AI Workload Results span five Azure Managed Lustre service tiers, from 20 MB/s per TiB to 500 MB/s per TiB, showing how the tested performance extends across the range of configurations available for demanding AI workloads. That breadth is deliberate because AI infrastructure requirements vary by model size, accelerator count, data volume, and I/O pattern; there is no single correct storage configuration. Results across five tiers show how customers can balance throughput, capacity, and cost as models, datasets, and clusters grow. Correct sizing can reduce storage bottlenecks and shorten time to results while retaining the durability and resiliency of a managed cloud file system. Getting Started with Azure Managed Lustre To evaluate Azure Managed Lustre for an AI or HPC workload, review the Azure Managed Lustre documentation for service capabilities, planning guidance, and deployment options. Then use the Azure portal deployment guide to configure and create a file system. For deployment examples, explore the AI Infrastructure on Azure GitHub repository. It provides reference architectures, best practices, and templates for AI and HPC environments, including examples built with Azure CycleCloud and Azure Kubernetes Service. Together with the resources below, these examples show how Azure Managed Lustre can serve as a high-performance shared storage layer for AI workloads. Learn More Azure Resources Azure Managed Lustre Azure Managed Lustre MLPerf Storage v3.0 results Azure AI Infrastructure AI Infrastructure on Azure GitHub repository Azure CycleCloud Azure Kubernetes Service MLPerf Resources MLCommons MLPerf Storage MLPerf Storage GitHub repository Benchmark MLPerf Storage | MLCommons V3.0 Results GitHub Repository of MLPerf Storage v3.0 resultsInside Llama 3.1 405B MLPerf Training on Azure: System-Level Insights at 8K+ GPU Scale
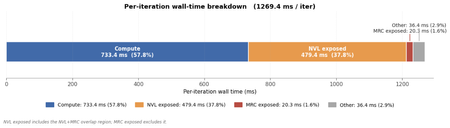
By Shantanu Patankar, and Azin Heidarshenas As part of Azure's MLPerf Training v6.0 submission, we scaled Llama 3.1 405B (NVFP4) pretraining to 8,192 GB200 GPUs across 128 racks on Azure's Fairwater infrastructure, converging in 7.07 minutes (MLPerf Training Blog). Llama 3.1, with 405 billion active parameters, has the highest active parameter count among all models in the MLPerf suite. Getting a model of this scale to train efficiently requires a cascade of tightly coupled choices around parallelism, batch sizing, and network placement. This post shares what we learned from bringing up and scaling Llama 3.1 405b on Fairwater at frontier scale. Three insights emerged: Even at 8K+ GPU scale, Llama 3.1 405B training remains compute-bound, with Feed forward Network (FFN) kernels dominating execution Topology-aware mapping is the key enabler of 8000+ GPU scale Scaling efficiency is governed by convergence dynamics, not system or network limits The rest of this post explains how these effects appear in practice. Where Does the Time Go Inside One Iteration, and What Are the Bottlenecks? Llama 3.1 405B is a dense transformer with 126 layers, each consisting of a self-attention block (QKV projections and attention) followed by a feed-forward network (FFN). To understand what limits performance at scale, we profiled steady-state iterations and broke down where time is spent, as shown in Figure 1. A single training step (Global Batch Size=1024) takes approximately 1.27s. 1: Compute vs Communication Breakdown of Llama 3.1 405B (Global Batch Size=1024) Compute: Roughly 57% of the training iteration wall time (~733 ms) is spent in compute. GEMM kernels dominate, accounting for 74% of that compute time. What is striking is how concentrated the compute is. The FFN up-projection and down-projection GEMMs alone consume ~54% of total compute (~397 ms). Everything else, including QKV projections, attention, softmax, normalization, etc., shares the remaining 46%. the FFN clearly dominates and is the primary driver of compute time. Communication: The system operates across two communication domains: high-bandwidth NVIDIA NVLink (NVL) within a rack (scale-up, 72 GPUs) and Azure’s Multipath Reliable Connection (MRC) network across racks (scale-out). The total communication work is 853 GPU-ms. Nearly 42% of this overlaps with compute or other communication (with MRC overlapping NVL), leaving only ~500 ms on the critical path. This is the portion that directly impacts step time, as shown in Figure 1. Of this ~500 ms critical-path communication, NVLink accounts for nearly all of it, while MRC contributes just 1.6%. Intra-rack NVLink communication on the critical path accounts for 37.8% (~479 ms). This includes Tensor Parallelism (TP), Pipeline Parallelism (PP), and Context Parallelism (CP) exchanges on the 1.8 TB/s intra-rack NVLink fabric, as well as pipeline bubbles, where stages idle between micro-batches. Although substantial, in a weak scaling regime, where each rack handles a fixed shard of the workload, NVLink communication per rack remains constant as we scale. MRC communication covers gradient synchronization across all DP ranks. Although it represents a substantial amount of communication work, it overlaps heavily with both NVLink communication and compute. As a result, only 1.6% (~20 ms) remains on the critical path. The cross-rack MRC network is nearly invisible in the step profile. The workload is compute-bound even at 8192 GPU scale, with FFN as the center of gravity. Any improvement to FFN kernel efficiency (precision, tiling, scheduling) translates almost directly into faster training steps. Why Is Topology-Aware Mapping the Key Enabler of Scale? In the first section, we showed that cross-rack MRC communication accounts for just 1.6% of step time. This result comes from how parallelism is mapped to the cluster’s two-tier network. Training Llama 3.1 405B distributes work across four dimensions. Tensor Parallelism (TP), Pipeline Parallelism (PP), and Context Parallelism (CP) split the model and sequence across GPUs, communicating frequently throughout each step. Data Parallelism (DP) replicates the model and synchronizes gradients once per step. The key difference: TP, PP, and CP are latency-sensitive. DP communication can be overlapped with compute, along with other NVLink-based communication. The design principle follows directly: keep latency-sensitive dimensions on the fastest links, and push traffic that can be overlapped with compute to the scale-out fabric On Azure's Fairwater cluster, each rack provides a 72-GPU NVLink domain at 1.8 TB/s. We use 64 GPUs per rack and constrain TP × PP × CP = 64, so one complete model-parallel shard fits within a single rack. Scaling to more racks adds DP replicas, with gradient synchronization flowing across the 100 GB/s Multipath Reliable Connection (MRC) network, the traffic that hides almost entirely behind compute. We swept TP, PP, and CP at fixed DP = 8 and GBS = 1152 to isolate the effect of communication efficiency on throughput. TP4–PP8–CP2 achieves the highest TFLOPS/GPU among the feasible configurations, reaching an Model FLOPs Utilization (MFU) of 26.45% as shown in Figure 2. What Limits Scaling Efficiency at 8K+ GPU Scale? We scaled Llama 3.1 405B training from 40 to 128 racks, adjusting MiniBS (per-DP-shard batch size, i.e., Global Batch Size ÷ DP) and Global Batch Size (GBS) at each scale point to balance GPU utilization against convergence efficiency. Training time drops from 18.79 minutes to 7.07 minutes, representing 83% scaling efficiency relative to the 40-rack baseline as shown in the table below. Racks GPUs MiniBS (GBS/Racks) Global Batch Size (GBS) Time-to-Train 40 2,560 24 960 18.79 min 64 4,096 16 1024 12.86 min 112 7,168 8 896 7.75 min 128 8,192 8 1,024 7.07 min Notice that MiniBS shrinks as we scale. MiniBS determines how much work each GPU processes per step and is the primary driver of step time. As we scale by increasing DP (one replica per rack), the global batch size grows proportionally unless MiniBS is reduced. Higher MiniBS improves per-step GPU utilization, but at scale it inflates GBS, and beyond a critical batch size the model requires quadratically more samples to converge. So we trade per-step throughput for faster end-to-end convergence, reducing MiniBS from 144 at 8 racks to 8 at 128 racks. MiniBS cannot be reduced below 8 in our setup because PP = 8 requires at least one microbatch per pipeline stage to keep the pipeline fully utilized. Since MiniBS cannot drop further, adding more racks only increases GBS, pushing deeper into the convergence penalty. At large scale, the optimal configuration minimizes time-to-train, not per-step throughput. The 83% scaling efficiency gap is not a network or system bottleneck. It is inherent to the benchmark's convergence dynamics. Conclusion MLPerf Training v6.0 provides a practical lens into how frontier-scale LLM systems behave under real constraints. Azure’s Llama 3.1 405B submission, which achieved a leading result at 8K+ GPU scale, highlights how performance at this level is shaped not just by infrastructure, but by the interaction of compute, topology, and convergence. Scaling efficiently at this level requires aligning these factors with the workload, not just adding more compute. View Azure's MLPerf Training v6.0 results. Read Azure's MLPerf v6.0 announcement blog. Acknowledgement This work was made possible through strong collaboration across multiple teams. We thank Prabhat Ram for his guidance throughout this effort, along with Mark Gitau, Amirreza Rastegari, Ojasvi Bhalerao, Sai Kovouri, Adam Hough, Bhupender Thakur, Nandini Ramanathan, Manasa Govindu, Sanian Gaffar, Ekrem Aksoy, Matthew Kappel, John Rankin, Girish Bhatia, Sreevatsa Anantharamu, Scott Moe, Yang Wang, and Jithin Jose — as well as many others across Azure and NVIDIA who supported this effort.
Azure Sets a New Performance Record for LLM Training Benchmark at Extreme Scale
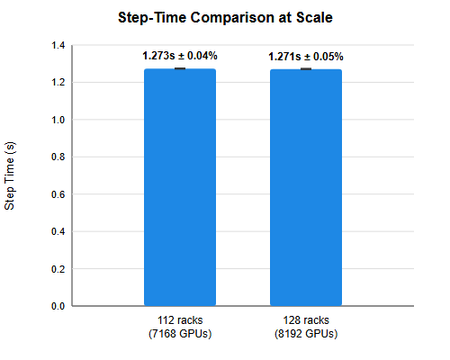
Azure achieved the most performant MLPerf Training v6.0 result to date for Llama 3.1 405B, with a time-to-train of just over seven minutes according to MLCommons. This loadbearing benchmark measures how communication overhead and system stability dominate training performance, where Azure’s full stack, end-to-end advantages shine. Azure scaled to 2,048 NVIDIA GB200 NVL72 compute tray nodes spanning 128 racks (8,192 GPUs), assembling the largest reported GB200 NVL72 cluster to date in MLPerf Training. As model sizes continue to grow into hundreds of billions of parameters, achieving this level of performance consistently requires not only massive compute capacity, but also a highly efficient communication infrastructure. To meet the demands of the massive training workloads, Azure’s Fairwater AI supercomputing infrastructure offers high-performance GPU scale-up domains with resilient, scale-out networking. Fairwater is optimized for frontier-scale distributed AI training, where communication overhead and synchronization latency can become major scaling bottlenecks at multi-thousand GPU scale. This remarkable result was possible by leveraging fifth-generation NVIDIA NVLink at 1,800 GB/s per GPU for intra-rack communication and Azure’s 100 GB/s MRC (Multipath Reliable Connection) fabric accelerated by NVIDIA DOCA and connected with NVIDIA ConnectX-8 and NVIDIA Spectrum-X Ethernet switches for inter-rack communication. What Enabled Scaling Llama 405B to 8,192 GPUs on Azure Achieving efficient training at this scale requires more than raw compute. Three architectural ingredients came together to make this result possible: High operational efficiency of NVLink scale-up domains, providing fast intra-rack GPU-to-GPU communication. Resiliency and stability of Azure’s MRC scale-out networking fabric, built on NVIDIA ConnectX-8 SuperNICs and Spectrum-X Ethernet switches, delivering 100 GB/s per GPU across racks. Topology-aware workload mapping, aligning parallelism strategies with the underlying network structure. Large-scale LLM training is fundamentally synchronous. At every training step, GPUs perform forward and backward passes followed by gradient synchronization across ranks. Because all GPUs must stay in sync, training progress is ultimately limited by the slowest rank — any time spent waiting on the network directly increases overall step time. For the Llama 405B benchmark, the workload is distributed across four dimensions of parallelism: Tensor, Context, Pipeline, and Data parallelism. Each generates different communication patterns, with some communication sitting directly on the critical training path. If left unmanaged, communication overhead can quickly become a major bottleneck at scale. The key insight is that not all communication is equally latency-sensitive. Some communication must be completed before computation can continue, while other communication can overlap with compute. Tensor-Parallel and Context-Parallel communication sit directly on the critical compute path, meaning each layer must wait for its collective operation to complete before execution can proceed. Pipeline-Parallel communication is also on the critical path, but across stages rather than within a layer (i.e., the next stage cannot begin processing its data until the previous stage has transferred its gradients). To minimize latency, all three are placed on the high-bandwidth NVLink domain, which provides up to 1,800 GB/s per GPU. Data-Parallel communication, on the other hand, can overlap with backward compute because gradient reduction runs alongside the backward pass and does not immediately block the next operation. This traffic is carried over the MRC scale-out network. The impact of such mapping is clear at scale. Our profiling shows that cross-rack MRC communication contributes just ~20 ms of exposed time on the critical path of a ~1.27 s training step (≈1.6% of step time). This communication — primarily gradient synchronization across all ranks — is well overlapped by compute and NVLink traffic, making the scale-out network nearly invisible to training performance. Stable Step Time as the Cluster Grows To evaluate execution stability as the cluster scales, we compared our GB200 NVL72 128-rack submission against a 112-rack configuration used for this experiment. In the Llama 405B workload, the critical path of each training step is dominated by compute (forward and backward GEMMs) together with latency-sensitive Tensor-Parallel and Context-Parallel communication over NVLink. Importantly, neither of these changes as the cluster scales out. Cross-node communication, such as Data-Parallel collectives and Pipeline-Parallel transfers over the MRC network, runs concurrently with backward compute and remains largely hidden behind computation. This overlap is sustained only if cross-node communication remains fast and predictable. Any network instability, congestion, or synchronization jitter would reduce this overlap and expose communication on the critical path, directly increasing overall step time. Figure 1. Step-time vs cluster size at scale This is exactly what we observe in practice under a weak scaling model, where we maintain a constant workload per GPU while scaling total cluster capacity. As shown in Figure 1, step time remains nearly identical at scale, measuring 1.2734 seconds at 112 GB200 NVL72 racks (7,168 GPUs) and 1.2712 seconds at 128 racks (8,192 GPUs) — a difference of just 2 ms. This corresponds to a near-perfect 99.8% weak scaling efficiency as we expanded the cluster by an additional 1,024 GPUs. Step-time variance also remains extremely low (±0.04–0.05%), confirming stable and predictable execution at extreme scale. This directly translates to maximized hardware utilization and an accelerated overall time-to-train, demonstrating the resiliency of Azure’s MRC scale-out network. Acknowledgement This work was made possible through strong collaboration across multiple teams. We would like to especially recognize Shantanu Patankar for his contributions to execution and performance analysis and Mark Gitau for his contributions to data preparation and experiment support as core contributors, and extend our thanks to Amirreza Rastegari, Ojasvi Bhalerao, Sai Kovouri, Adam Hough, Nandini Ramanathan, Manasa Govindu, Sanian Gaffar, Ekrem Aksoy, Bhupender Thakur, Matthew Kappel, John Rankin, Girish Bhatia, Sreevatsa Anantharamu, Scott Moe, Yang Wang, and Jithin Jose, as well as many others across Azure and NVIDIA who supported this effort.Azure Recognized as an NVIDIA Cloud Exemplar, Setting the Bar for AI Performance in the Cloud
As AI models continue to scale in size and complexity, cloud infrastructure must deliver more than theoretical peak performance. What matters in practice is reliable, end-to-end, workload-level AI performance—where compute, networking, system software, and optimization work together to deliver predictable, repeatable results at scale. This directly translates to business value: efficient full-stack infrastructure accelerates time-to-market, maximizes ROI on GPU and cloud investments, and enables organizations to scale AI from proof-of-concept to revenue-generating products with predictable economics. Today, Microsoft is proud to share an important milestone in partnership with NVIDIA: Azure has been validated as an NVIDIA Exemplar Cloud, becoming the first cloud provider recognized for Exemplar-class AI performance aligned with GB300-class (Blackwell generation) systems. This recognition builds on Azure’s previously validated Exemplar status for H100 training workloads and reflects NVIDIA’s confidence in Azure’s ability to extend that rigor and performance discipline into the next generation of AI platforms. What Is NVIDIA Exemplar Cloud? The NVIDIA Exemplar Cloud initiative celebrates cloud platforms that demonstrate robust end-to-end AI workload performance using NVIDIA’s Performance Benchmarking suite. Rather than relying on synthetic microbenchmarks, Performance Benchmarking evaluates real AI training workloads using: Large-scale LLM training scenarios Production-grade software stacks Optimized system and network configurations Workload-centric metrics such as throughput and time-to-train Achieving Exemplar validation signals that a provider can consistently deliver world-class AI performance in the cloud, showcasing that end users are getting optimal performance value by default. Proven Exemplar Validation on H100 Azure’s Exemplar Cloud journey began with publicly shared benchmarking results for H100-based training workloads, where Azure ND GPU clusters demonstrated exemplar performance using NVIDIA Performance Benchmarking recipes. Those results—published previously and validated through NVIDIA’s benchmarking framework—established a proven foundation of end-to-end AI performance for large-scale, production workloads running on Azure today. Extending Exemplar-Class AI Performance to GB300-Class Platforms Building on the rigor and learnings from H100 validation, Microsoft has now been recognized by NVIDIA as the first cloud provider to achieve Exemplar-class performance and readiness aligned with GB300-class systems. This designation reflects NVIDIA’s assessment that the same principles applied to H100—including end-to-end system tuning, networking optimization, and software alignment—are being successfully carried forward into the Blackwell generation. Rather than treating GB300 as a point solution, Azure approaches it as a continuation of a proven performance model: delivering consistent world-class AI performance in the cloud while preserving the flexibility, elasticity, and global scale customers expect. What Enables Exemplar-Class AI Performance on Azure Delivering Exemplar-class AI performance requires optimization across the full AI stack: Infrastructure and Networking High-performance Azure ND GPU clusters with NVIDIA InfiniBand NUMA-aware CPU, GPU, and NIC alignment to minimize latency Tuned NCCL communication paths for efficient multi-GPU scaling Software and System Optimization Tight integration with NVIDIA software, including Performance Benchmarking recipes and NVIDIA AI Enterprise Parallelism strategies aligned with large-scale LLM training Continuous tuning as models, workloads, and system architectures evolve End-to-End Workload Focus Measuring real training performance, not isolated component metrics Driving repeatable improvements in application-level throughput and efficiency Closing the performance gap between cloud and on-premises systems—without sacrificing manageability Together, these capabilities enabled Azure to deliver consistent Exemplar-class AI performance across generations of NVIDIA platforms. What This Means for Customers For customers training and deploying advanced AI models, this milestone delivers clear benefits: World-class AI performance in a fully managed cloud environment Predictable scaling from small clusters to thousands of GPUs Faster time to train and improved performance per dollar Confidence that Azure is ready for Blackwell-class and GB300-class AI workloads As AI workloads become more complex and reasoning-heavy, infrastructure performance increasingly determines outcomes. Azure’s NVIDIA Cloud Exemplar recognition provides a clear signal: customers can build and scale next-generation AI systems on Azure without compromising on performance. Learn More DGX Cloud Benchmarking on Azure DGX Cloud Benchmarking on Azure | Microsoft Community HubCentralized cluster performance metrics with ReFrame HPC and Azure Log Analytics
Imagine having several clusters across different environments (dev, test and prod) or planning a migration between PBS and Slurm or porting codes to a different system. They can all seem like daunting tasks. This is where the combination of ReFrame HPC, a powerful and feature rich testing framework, and Azure Log Analytics can help improve confidence and assurance in the performance and accuracy of a system. Here we will look at how to configure ReFrame HPC specifically for Azure: Deploying the required Azure resources, running a test and capturing the results in Log Analytics for analysis. Deploying the required Azure Resources Firstly, deploy the required resources in Azure by using this bicep from GitHub. The deployment includes the creation and configuration of everything required for ReFrame HPC. These resources include a data collection endpoint, a data collection rule and a log analytics workspace. Running ior via ReFrame HPC For the purpose of demonstrating a running test and capturing the results in Azure from start to finish, here is a simple ior test which will run both a read and a write operation against the shared storage. import reframe as rfm import reframe.utility.sanity as sn @rfm.simple_test class SimplePerfTest(rfm.RunOnlyRegressionTest): valid_systems = ["*"] valid_prog_environs = ["+ior"] executable = 'ior' executable_opts = [ '-a POSIX -w -r -C -e -g -F -b 2M -t 2M -s 25600 -o /data/demo/test.bin -D 300' ] reference = { 'tst:hbv4': { 'write_bandwidth_mib': (500, -0.05, 0.1, 'MiB/s'), 'read_bandwidth_mib': (350, -0.05, 0.5, 'MiB/s'), } } @sanity_function def validate_run(self): return sn.assert_found(r'Summary of all tests:', self.stdout) @performance_function('MiB/s') def write_bandwidth_mib(self): return sn.extractsingle(r'^write\s+([0-9]+\.?[0-9]*)', self.stdout, 1, float) @performance_function('MiB/s') def read_bandwidth_mib(self): return sn.extractsingle(r'^read\s+([0-9]+\.?[0-9]*)', self.stdout, 1, float) Test explanation Set the binary to be executed to ior, along with its arguments. executable = 'ior' executable_opts = [ '-a POSIX -w -r -C -e -g -F -b 2M -t 2M -s 25600 -o /data/demo/test.bin -D 300' ] Specify which systems the test should run on. In this case, any system/cluster which is known to have ior available will be selected. Look at the ReFrame HPC documentation to get a better understanding of the options available for use. valid_systems = ["*"] valid_prog_environs = ["+ior"] Verify the stdout of the job by searching for a specific value to assert that it ran successfully. @sanity_function def validate_run(self): return sn.assert_found(r'Summary of all tests:', self.stdout) If the sanity function passed it will then extract the performance metrics from the stdout of the job. The naming of the methods is important, as they will be stored in the results later. @performance_function('MiB/s') def write_bandwidth_mib(self): return sn.extractsingle(r'^write\s+([0-9]+\.?[0-9]*)', self.stdout, 1, float) @performance_function('MiB/s') def read_bandwidth_mib(self): return sn.extractsingle(r'^read\s+([0-9]+\.?[0-9]*)', self.stdout, 1, float) Performance references are used to determine if the current cluster has met the requirement or not. It also allows margins to be specified in either direction. reference = { 'tst:hbv4': { 'write_bandwidth_mib': (500, -0.05, 0.1, 'MiB/s'), 'read_bandwidth_mib': (350, -0.05, 0.5, 'MiB/s'), } } ReFrame HPC Configuration The ReFrame HPC configuration is key to determine how and where the test will run. It is also where the logic allowing Reframe HPC to use Azure for centralized logging will be defined. The full configuration file is vast and is covered in detail within the ReFrame HPC documentation. For the purpose of this test an example can be found on GitHub. Below is a breakdown of the key parts that allow Reframe HPC to push its results into Azure Log Analytics. Logging Handler The most important part of this configuration is the logging section, without it ReFrame HPC will not attempt to log the results. A handler_perflog of type httpjson is added to enable the logs to be sent to a HTTP endpoint with specific values which our covered below. 'logging': [ { 'perflog_multiline': True, 'handlers_perflog': [ { 'type': 'httpjson', 'url': 'REDACTED', 'level': 'info', 'debug': False, 'extra_headers': {'Authorization': f'Bearer {_get_token()}'}, 'extras': { 'TimeGenerated': f'{datetime.now(timezone.utc).isoformat()}', 'facility': 'reframe', 'reframe_azure_data_version': '1.0', }, 'ignore_keys': ['check_perfvalues'], 'json_formatter': _format_record } ] } Multiline Perflog To ensure this works with Azure, enable perflog_multiline. This will ensure a single record per metric is sent to Log Analytics. This is the cleanest way to output the results. Having this set to False will move the metric names into column names, which means that the schema will be different for each test and will become hard to maintain. Extra Headers A bearer token is required to authenticate the request. ReFrame HPC allows the adding of headers via the extra_headers property and a simple Python function, which obtains a scoped token that can be appended to the additional header. def _get_token(scope='https://monitor.azure.com/.default') -> str: credential = DefaultAzureCredential() token = credential.get_token(scope) return token.token Url Structure The url can be found in the output of the bicep which was run previously. It can also be obtained via the portal. Here is the structure of the url for reference. '${dce.properties.logsIngestion.endpoint}/dataCollectionRules/${dcr.properties.immutableId}/streams/Custom-${table.name}?api-version=2023-01-01' json Formatter A small work around is needed as the Data Collection Rule expects an array of items and ReFrame HPC outputs a single record. To resolve this another Python function can be used which simply wraps the record up in an array. In this example it also tidys up and removes some items that are not required and would cause issues with the json serialization. def _format_record(record, extras, ignore_keys): data = {} for attr, val in record.__dict__.items(): if attr in ignore_keys or attr.startswith('_'): continue data[attr] = val data.update(extras) return json.dumps([data]) Running the Test Now that the infrastructure has been deployed, the test has been defined and is correctly configured, we can run the test. Start by logging in. Here I am using the managed identity of the node, but User auth and User Assigned Managed Identities are also supported. $ az login --identity ReFrame HPC can be installed via Spack or Python and, while I am using Spack for packages on the cluster, I find the simplest approach is to activate a Python environment and install ReFrame HPC along with test specfic Python dependencies. $ python3 -m venv .venv $ . .venv/bin/activate $ python -m pip install -U pip $ pip install -r requirements.txt Now using the ReFrame HPC cli, the test can be run using the configuration file and the test file. $ reframe -C config.py -c simple_perf.py --performance-report -r ReFrame HPC will now run the test against the system/cluster defined in the configuration. For this example it is a Slurm cluster on a partition of HBv4 nodes and running squeue clarifys that. $ squeue JOBID PARTITION NAME USER ST TIME NODES NODELIST(REASON) 955 hbv4 rfm_Simp jim.pain R 0:28 1 tst4-hbv4-97 Results And there we have it, results are now appearing in Azure! From here we can use kql to query and filter the results. This is just a subset of the values available but the dataset is vast and includes a huge range of values that are extremely helpful. Summary By standardizing on the combination of ReFrame HPC and Azure Log Analytics for testing and reporting of performance data across our clusters, whether Slurm based, Azure CycleCloud or existing on-prem clusters, you can gain unprecendented visibility and confidence in the systems you manage and the codes you deploy that were previously hard to obtain. Enabling the potential for: 🔎Fast cross-cluster comparisions 📈Trend analysis over long running periods 📊Standardized metrics regardless of scheduler or system ☁️Unified monitoring and reporting across clusters ReFrame HPC is suitable for a wide range of testing, so if testing is something you have been looking to implement, take a look at ReFrame HPC