azure sql database cdc
2 TopicsAzure SQL Scaling Stuck? Investigating CDC and Transaction Log Pressure
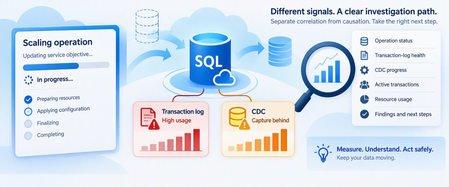
Azure SQL Database makes scaling compute straightforward. But troubleshooting becomes more complicated when several things happen simultaneously: A scale operation remains IN_PROGRESS. A cancellation remains CANCEL_IN_PROGRESS. Transaction-log usage is growing. Change Data Capture (CDC) is enabled. Log truncation reports REPLICATION. Long-running transactions are present. The temptation is to connect all these observations immediately: "CDC is preventing Azure SQL from scaling." That's a hypothesis, not yet a diagnosis. CDC reads changes from the transaction log, and CDC capture latency can delay log truncation under certain conditions. Microsoft specifically documents scenarios where CDC combined with long-running transactions can contribute to continued transaction-log growth. However, that doesn't establish a universal rule that: CDC causes scale operations to become stuck. REPLICATION as a log reuse wait means scaling is blocked. Disabling CDC will resolve a scale operation. A CDC problem and a long-running scale operation necessarily share the same root cause. The safest investigation separates the evidence into layers. 1. Start With the Scale Operation A scale operation changes the resources available to Azure SQL Database. Depending on the type of scaling operation, Azure SQL might need to: Create a compute instance with the requested configuration. Move or copy data when necessary. Redirect connections to the new environment. Terminate existing connections during the final switch. Microsoft documents that Azure SQL Database normally remains online during much of this process, although the final connection switch can cause a short interruption. Long-running transactions can increase the time required for recovery when connections are terminated. So, begin with the operation itself. 2. Check the Operation State Azure SQL Database exposes database-operation status using: sys.dm_operation_status This DMV reports operations such as ALTER and their state. Run the query from the logical server's master database: SELECT session_activity_id, major_resource_id AS database_name, operation, state_desc, percent_complete, start_time, last_modify_time, error_code, error_desc FROM sys.dm_operation_status ORDER BY start_time DESC; Possible states include: PENDING IN_PROGRESS COMPLETED FAILED CANCEL_IN_PROGRESS CANCELLED An important detail is that percent_complete shouldn't automatically be interpreted like a traditional progress bar. For many active operations: 50 = operation in progress and: 100 = operation complete Restore operations have more granular progress values. So: An ALTER operation remaining at 50% doesn't necessarily mean exactly half of the work is complete. 3. Build an Operation Timeline Capture: Scale request time. Requested service objective. Operation start time. Current state. last_modify_time. Cancellation request time, when applicable. Subsequent scale requests. Application impact. Database availability. Workload running during the operation. For example: Time Observation T0 Scale requested T1 Operation enters IN_PROGRESS T2 Transaction-log utilization rises T3 log_reuse_wait_desc reports REPLICATION T4 Cancellation requested T5 Operation still CANCEL_IN_PROGRESS This timeline establishes correlation. It doesn't yet establish causation. 4. Don't Keep Submitting Scale Requests When a scale or cancellation appears slow, avoid repeatedly submitting new modifications without understanding the state of the existing operation. Instead: Preserve the current operation ID. Record the operation state. Record timestamps. Capture current database workload. Investigate the transaction log. Investigate CDC independently. Escalate if the operation remains persistently unable to reach a terminal state. The goal is to reduce variables rather than introduce new ones. 5. Measure Transaction-Log Utilization Now move to the database being investigated. sys.dm_db_log_space_usage is supported in Azure SQL Database and reports how much transaction-log space is currently occupied. SELECT total_log_size_in_bytes / 1024.0 / 1024.0 AS total_log_size_mb, used_log_space_in_bytes / 1024.0 / 1024.0 AS used_log_space_mb, used_log_space_in_percent FROM sys.dm_db_log_space_usage; Capture this repeatedly. You're looking for a trend such as: T1 25% T2 41% T3 58% T4 73% T5 88% versus: T1 60% T2 63% T3 56% T4 61% T5 58% The first pattern suggests sustained net log growth. The second shows that log space is being reused. One snapshot can't tell you which behavior is occurring. 6. Ask Why the Log Can't Be Reused One of the most useful checks is: SELECT name, log_reuse_wait_desc FROM sys.databases WHERE database_id = DB_ID(); The value describes the current condition preventing transaction-log reuse. Microsoft also exposes the same concept through sys.dm_db_log_stats() as log_truncation_holdup_reason. A more complete diagnostic query is: SELECT database_id, total_log_size_mb, active_log_size_mb, total_vlf_count, active_vlf_count, log_truncation_holdup_reason, log_since_last_checkpoint_mb FROM sys.dm_db_log_stats(DB_ID()); sys.dm_db_log_stats() is documented as applicable to Azure SQL Database and returns summary-level information for diagnosing transaction-log health. 7. What Does REPLICATION Mean When CDC Is Enabled? This point requires careful interpretation. CDC uses the transaction log as the source for captured changes. Inserts, updates, and deletes are recorded in the transaction log before CDC processes those changes. Microsoft documents an important interaction: CDC is enabled. Transactions produce log records. CDC must capture relevant log information. Capture latency can hold back log truncation. log_reuse_wait_desc can consequently report REPLICATION. Therefore, if you see: REPLICATION in a CDC-enabled Azure SQL Database, CDC-related log processing is a legitimate investigation path. But don't jump from: "log_reuse_wait_desc = REPLICATION" to: "CDC caused the scaling operation to become stuck." That's a different claim requiring separate evidence. 8. Confirm Whether CDC Is Enabled Azure SQL Database exposes CDC status through sys.databases. SELECT name, is_cdc_enabled FROM sys.databases WHERE database_id = DB_ID(); If: is_cdc_enabled = 1 CDC is enabled for the database. Microsoft documents CDC support in Azure SQL Database and notes that the database must first be CDC-enabled before individual source tables can be tracked. 9. Inventory CDC Capture Instances Rather than using SQL Server Agent job queries, inspect Azure SQL Database CDC metadata. SELECT ct.capture_instance, OBJECT_SCHEMA_NAME(ct.source_object_id) AS source_schema, OBJECT_NAME(ct.source_object_id) AS source_table, ct.start_lsn, ct.create_date FROM cdc.change_tables AS ct ORDER BY source_schema, source_table; This helps answer: Which tables are tracked? How many capture instances exist? When were they created? Has the CDC scope changed recently? An important Azure SQL-specific detail is: Azure SQL Database doesn't depend on SQL Server Agent CDC capture and cleanup jobs. Instead, Azure SQL Database uses a built-in CDC scheduler that automatically runs capture and cleanup within the database. That distinction is critical when adapting SQL Server CDC troubleshooting procedures to Azure SQL Database. 10. Check Whether CDC Is Advancing A simple high-level check is: SELECT sys.fn_cdc_get_min_lsn( ct.capture_instance ) AS minimum_lsn, sys.fn_cdc_get_max_lsn() AS maximum_lsn, ct.capture_instance, OBJECT_SCHEMA_NAME(ct.source_object_id) AS source_schema, OBJECT_NAME(ct.source_object_id) AS source_table FROM cdc.change_tables AS ct; Take repeated samples. The objective isn't to derive a universal threshold. The objective is to determine whether the observable CDC boundary is: Advancing. Intermittently advancing. Apparently static over a meaningful period. Again: Trend matters more than a single snapshot. 11. Investigate Long-Running Transactions This is particularly important when CDC and log growth appear together. Microsoft specifically documents transaction-log growth scenarios involving CDC and long-running transactions. Start by examining database transactions: SELECT dt.transaction_id, dt.database_transaction_begin_time, dt.database_transaction_type, dt.database_transaction_state, dt.database_transaction_log_record_count, CAST ( dt.database_transaction_log_bytes_used / 1024.0 / 1024.0 AS decimal(18,2) ) AS log_mb_used, CAST ( dt.database_transaction_log_bytes_reserved / 1024.0 / 1024.0 AS decimal(18,2) ) AS log_mb_reserved FROM sys.dm_tran_database_transactions AS dt WHERE dt.database_id = DB_ID() ORDER BY dt.database_transaction_log_bytes_used DESC; sys.dm_tran_database_transactions is supported in Azure SQL Database and provides transaction-level database information, including transaction start time and log bytes consumed. 12. Connect Transactions Back to Sessions A transaction ID is useful, but identifying the application session makes it actionable. SELECT st.session_id, at.transaction_id, at.transaction_begin_time, at.transaction_type, at.transaction_state, dt.database_transaction_begin_time, CAST ( dt.database_transaction_log_bytes_used / 1024.0 / 1024.0 AS decimal(18,2) ) AS log_mb_used, s.login_name, s.host_name, s.program_name, r.status, r.command, r.wait_type, r.blocking_session_id FROM sys.dm_tran_session_transactions AS st JOIN sys.dm_tran_active_transactions AS at ON st.transaction_id = at.transaction_id JOIN sys.dm_tran_database_transactions AS dt ON st.transaction_id = dt.transaction_id LEFT JOIN sys.dm_exec_sessions AS s ON st.session_id = s.session_id LEFT JOIN sys.dm_exec_requests AS r ON st.session_id = r.session_id WHERE dt.database_id = DB_ID() ORDER BY at.transaction_begin_time; sys.dm_tran_active_transactions and sys.dm_tran_database_transactions are documented for Azure SQL Database. Look for: Very old transactions. Transactions consuming large amounts of log. Sleeping sessions with open transactions. Blocking. Large write activity. Don't terminate transactions merely because they're old. First determine: Which application owns them. Whether rollback would cause more impact. Whether they're expected. Whether they're actually contributing to the observed log condition. 13. Correlate With Log-Write Pressure Azure SQL Database also exposes recent transaction-log write utilization through: sys.dm_db_resource_stats It provides roughly one hour of resource history with approximately 15-second samples. SELECT TOP (240) end_time, avg_cpu_percent, avg_data_io_percent, avg_log_write_percent, avg_memory_usage_percent FROM sys.dm_db_resource_stats ORDER BY end_time DESC; Now correlate: Scale-operation start time. Log-space growth. log_reuse_wait_desc. CDC progression. Long-running transactions. avg_log_write_percent. This can reveal two very different scenarios. Scenario A Log is large. Log-write rate is currently modest. CDC continues advancing. No unusually long transaction is present. This weakens the hypothesis that current transaction-log pressure is the primary explanation for the ongoing scale behavior. Scenario B Log usage continually rises. REPLICATION remains the reuse wait. CDC progression appears delayed. Large transactions remain active. Log-write pressure is high. This strengthens the case for investigating the log/CDC workload further. It still doesn't prove CDC is blocking scaling. 14. Test Correlation Without Inventing Causation Build a timeline like this: Time Scale state Log used Reuse wait CDC progress Long transaction T1 IN_PROGRESS 45% NOTHING Advancing No T2 IN_PROGRESS 62% REPLICATION Slower Yes T3 IN_PROGRESS 78% REPLICATION Limited Yes T4 IN_PROGRESS 66% NOTHING Advancing No Then ask: Evidence supporting a relationship Problem begins at the same time. Log pressure remains sustained. CDC progression is materially delayed. Long transactions contribute substantial log activity. Reducing unnecessary write pressure produces measurable improvement. Evidence weakening the relationship CDC progresses normally. Log space is actively reused. Scale remains IN_PROGRESS despite normal log behavior. Scale problems occur independently of CDC pressure. Log pressure clears but operation state doesn't change. This distinction protects the investigation from a common mistake: Correlation is an investigation path, not proof of root cause. 15. Don't Disable CDC as a First Step Disabling CDC is a substantial configuration change. It can affect: ETL pipelines. Integration platforms. Analytics workloads. Incremental processing. Downstream synchronization. CDC history. Azure SQL Database provides documented procedures for enabling and disabling CDC, but those procedures should be used because changing CDC is an intentional design decision, not simply because a scale operation is taking longer than expected. Even if disabling CDC changes the symptom, that fact alone doesn't prove: CDC was the root cause. Other conditions may have changed simultaneously. 16. Use a Safe Mitigation Order When a scale operation, CDC, and transaction-log pressure overlap, consider this sequence. Step 1: Stop introducing new variables Avoid repeatedly submitting duplicate or conflicting scale operations. Step 2: Preserve operation evidence Capture: Operation ID. Start time. State. Last modification time. Errors. Step 3: Measure log health Capture: Log size. Used log percentage. Truncation holdup reason. Trend over time. Step 4: Validate CDC Confirm: CDC enabled. Tracked tables. CDC progression. Recent CDC configuration changes. Step 5: Investigate long-running transactions Determine: Age. Session. Application owner. Log consumption. Business impact of intervention. Step 6: Reduce avoidable write pressure When operationally safe, reduce nonessential: Bulk updates. Large batches. ETL writes. Maintenance jobs. Excessive write concurrency. Step 7: Treat CDC changes as controlled interventions Only disable CDC when: Downstream impact is understood. The change is justified. The recovery/reinitialization path is understood. Evidence supports testing it. 17. Validate Recovery Don't stop when the scale operation finally completes. Confirm all layers. Scale operation Verify that the operation reached: COMPLETED FAILED CANCELLED rather than remaining indefinitely in an intermediate state. Transaction log Verify: Log usage stabilizes. Log reuse resumes. log_truncation_holdup_reason changes appropriately. CDC Verify: Change capture continues. Expected tracked tables remain enabled. Downstream consumers remain healthy. Application Verify: Connections recover. Workload resumes normally. No unexpected backlog remains. 18. Know When to Escalate Escalation becomes appropriate when you've established that: The scale or cancellation operation remains persistently nonterminal. No meaningful state changes are occurring. Database workload evidence has been captured. Log health is understood. CDC status is documented. Long transactions have been investigated. Business impact continues. Microsoft provides sys.dm_operation_status specifically for monitoring operations performed on Azure SQL databases, including pending, in-progress, failed, cancellation-in-progress, and canceled states. A useful escalation package includes: Sanitized operation history. Service objective before and after the requested scale. sys.dm_operation_status evidence. Log-space trend. log_truncation_holdup_reason. CDC state. CDC progress observations. Long-running transaction evidence. Resource metrics. Mitigations attempted and their results. Remaining application/business impact. 19. Practical Decision Tree When an Azure SQL scale operation appears stuck: Is the operation still nonterminal? No Validate workload, CDC, and log health. Continue monitoring. Yes Record its state and timeline. Is the transaction log under sustained pressure? No Don't make CDC the primary hypothesis solely because it's enabled. Yes Continue. What is preventing log reuse? ACTIVE_TRANSACTION Investigate long-running transactions. REPLICATION with CDC enabled Investigate CDC progress and transaction activity. Another value Investigate that truncation holdup independently. Is CDC demonstrating progress? Yes A completely stalled CDC process becomes a weaker hypothesis. Continue investigating log generation and the scale operation separately. No, or inconclusive Gather repeated samples. Check transactions and workload pressure. Did log pressure resolve while scaling remained stuck? Yes The evidence weakens the hypothesis that log/CDC pressure alone explains the operation. No Continue correlation and consider escalation. Final Takeaway When Azure SQL scaling, CDC, and transaction-log pressure happen together, don't begin with: "CDC blocked the scale operation." Begin with four independent questions: What is the actual state of the scale operation? Is the transaction log genuinely under sustained pressure? Why is log reuse being delayed? Is CDC demonstrating forward progress? Azure SQL Database provides documented tools for each layer: sys.dm_operation_status for operation state. sys.dm_db_log_space_usage for log-space utilization. sys.dm_db_log_stats() for transaction-log health and truncation holdup. sys.dm_tran_database_transactions for transaction/log consumption. sys.dm_db_resource_stats for recent CPU, I/O, and log-write pressure. Azure SQL Database's built-in CDC scheduler and CDC metadata for capture investigation. Most importantly: Don't disable CDC just because two symptoms occurred together. Preserve evidence, reduce unnecessary workload pressure, address demonstrated transaction problems, and escalate persistent nonterminal scaling operations with a clear timeline. Because: The safest diagnosis separates correlation from causation before changing the workload. Further reading Change Data Capture (CDC) with Azure SQL Database Scale single database resources in Azure SQL Database sys.dm_operation_status sys.dm_db_log_space_usage sys.dm_db_log_stats Transaction log growth with long-running transactions and CDC108Views0likes0CommentsTroubleshooting Change Tracking cleanup growth and orphaned rows in Azure SQL Database
Applies to: Azure SQL Database Scenario: Change Tracking (CT) side tables grow unexpectedly, and “orphaned” rows appear after switching between auto-cleanup and custom/scheduled manual cleanup. The problem (what we observed) In the case tracked, the discussion focused on Change Tracking cleanup behavior—including unexpected growth in CT side tables and orphaned records. The customer also referenced earlier guidance to move away from auto-cleanup due to locking concerns during upgrades, and the team needed to propose safe next steps quickly. A parallel concern was that CT auto-cleanup could block DDL during upgrades (schema lock behavior), which triggered work to deploy a fix and validate it in a lab before broader rollout. Why this is tricky The engagement highlighted that manual cleanup and auto-cleanup can behave differently in real-world, high-scale environments (large number of CT-enabled tables, heavy activity, and operational constraints like access and auditing). Investigation efforts included: validating where orphaned rows exist and how many CT side tables are affected, checking whether auto-cleanup is enabled/disabled, and using auditing / Extended Events to identify who/what is dropping related history objects. Additionally, Snapshot Isolation can prevent cleanup from progressing in some cases. it was noted that long-running snapshot transactions can prevent a safe cleanup point from advancing, which can block removal of expired entries from internal commit tracking tables until those transactions complete. Practical troubleshooting steps (what helped) 1) Confirm CT configuration (retention + auto-cleanup) Use the Change Tracking configuration options to validate retention and whether auto-cleanup is enabled. Microsoft Learn documents enabling CT at the database level (including CHANGE_RETENTION and AUTO_CLEANUP). Enable and Disable Change Tracking - SQL Server | Microsoft Learn 2) Quick backlog signal: commit table “oldest commit_time” During the investigation, the team used a lightweight query to sanity-check backlog in the commit table: SELECT TOP (1) * FROM sys.dm_tran_commit_table ORDER BY commit_time ASC; if the returned commit_time is close to the retention horizon, auto-cleanup is likely keeping up (this query doesn’t require DAC). 3) Detect orphaned rows in CT side tables (read-only script) A key artifact from this case is the following T-SQL script, which calculates a cleanup point based on configured retention and then iterates over CT side tables (sys.internal_tables where internal_type = 209) to identify rows whose sys_change_xdes_id no longer has a matching entry in sys.syscommittab at/below the cleanup point. -- use <[DBName]> -- switch to the right database SET NOCOUNT ON -- find the invalid clean version based on configured retention DECLARE time DATETIME, @csn BIGINT = 0, @minCleanupPoint BIGINT = 0 DECLARE @retention_period INT, @retention_period_units NVARCHAR(10) SELECT @retention_period = retention_period, @retention_period_units = retention_period_units FROM sys.change_tracking_databases where database_id = DB_ID() SELECT time = CASE WHEN @retention_period_units = 1 then DATEADD(minute, (-1 * @retention_period), GETUTCDATE()) WHEN @retention_period_units = 2 then DATEADD(hour, (-1 * @retention_period), GETUTCDATE()) ELSE DATEADD(day, (-1 * @retention_period), GETUTCDATE()) END EXEC sp_changetracking_time_to_csn time = time, @csn = @csn OUTPUT SELECT @minCleanupPoint = @csn SELECT @minCleanupPoint as minCsn -- 688118 -- iterate over all the change tracking side tables DECLARE @sideTable SYSNAME; DECLARE ct_cursor CURSOR FAST_FORWARD FOR SELECT name FROM sys.internal_tables WHERE internal_type = 209; -- internal_type = 209 is for change tracking side tables OPEN ct_cursor; FETCH NEXT FROM ct_cursor INTO @sideTable; WHILE @@FETCH_STATUS = 0 BEGIN -- find the minimum expired xdes id declare @minXdesId BIGINT SELECT @minXdesId = min(xdes_id) FROM sys.dm_tran_commit_table where commit_ts <= @minCleanupPoint -- SELECT @minXdesId as minXdes -- create temp table for storing orphaned xdes id DROP TABLE IF EXISTS #OrphanedXdes; CREATE TABLE #OrphanedXdes ( sys_change_xdes_id BIGINT NOT NULL ); DECLARE @sql NVARCHAR(MAX); SET @sql = N' INSERT INTO #OrphanedXdes(sys_change_xdes_id) SELECT ct.sys_change_xdes_id FROM sys.' + QUOTENAME(@sideTable) + N' AS ct WHERE ct.sys_change_xdes_id < @minXdesId AND NOT EXISTS ( SELECT 1 FROM sys.syscommittab AS s WHERE s.xdes_id = ct.sys_change_xdes_id AND s.commit_ts <= @minCleanupPoint );'; EXEC sys.sp_executesql @sql, N'@minXdesId BIGINT, @minCleanupPoint BIGINT', @minXdesId = @minXdesId, @minCleanupPoint = @minCleanupPoint; DECLARE @orphanedIdsCount BIGINT; SET @sql = N' SELECT @cnt = COUNT_BIG(sys_change_xdes_id) FROM #OrphanedXdes; '; EXEC sys.sp_executesql @sql, N'@cnt BIGINT OUTPUT', @cnt = @orphanedIdsCount OUTPUT; -- Raise error if any orphaned xdes exists IF (@orphanedIdsCount > 0) BEGIN DECLARE @msg NVARCHAR(4000) = @sideTable + N' : ' + CONVERT(NVARCHAR(30), @orphanedIdsCount); RAISERROR (@msg, 16, 1) WITH NOWAIT; DECLARE @newLine NVARCHAR(10) = CHAR(13) + CHAR(10) PRINT (@newLine) END DROP TABLE IF EXISTS #OrphanedXdes; FETCH NEXT FROM ct_cursor INTO @sideTable; END CLOSE ct_cursor; DEALLOCATE ct_cursor; SET NOCOUNT OFF Here’s the high-level logic (excerpted/annotated from the script): Read retention settings from sys.change_tracking_databases Convert “retention window” to a cleanup CSN using sp_changetracking_time_to_csn For each CT side table (sys.internal_tables internal_type = 209): compare side-table sys_change_xdes_id vs. sys.syscommittab and count “orphaned” xdes ids emit a message when orphaned counts are present Tip: This is read-only diagnostic logic. In your environment, validate permissions and impact before running in production. 4) If auto-cleanup is unexpectedly disabled, re-enable and monitor In the email thread, the team observed auto-cleanup was disabled in at least one environment and recommended re-enabling it, then monitoring the CT history table to confirm cleanup activity resumes. 5) Use auditing / Extended Events to identify unexpected object drops When investigating why a “history table” disappeared, the team reviewed extended event data and noted evidence of a specific application context associated with the drop (shared in the meeting discussion). This is a key lesson: without auditing, it can be difficult to determine who/what disabled auto-cleanup or dropped relevant objects; the email thread explicitly called this out. Mitigation options discussed (often safest): disable & re-enable Change Tracking on affected tables As an alternative to running manual deletion scripts, the troubleshooting recommended disabling and re-enabling Change Tracking on the set of tables containing orphaned rows—described as a well-established and safer cleanup method that avoids needing elevated access to run cleanup scripts directly. Trade-off: disabling CT on a table removes existing change data from the corresponding side tables for that table. About auto-cleanup performance improvements (why “stay on auto” may be preferred) The troubleshooting included discussion that auto-cleanup is the area that continues to receive improvements and that performance enhancements exist (for example, improved adaptive behavior in newer SQL Server versions). Microsoft Learn describes that SQL Server 2025 introduces an “adaptive shallow cleanup approach” for large side tables, enabled by default, and explains how cleanup behavior changes compared to prior versions. While Azure SQL Database implementation details differ from boxed SQL Server, the key operational takeaway from the discussion was: if possible, prefer auto-cleanup and avoid manual cleanup unless you have a strong reason, because manual cleanup may lack telemetry and can be harder to reason about at scale. Key takeaways Start with read-only validation: use a backlog signal query and an orphan-detection script to quantify scope before making changes. Auditability matters: without auditing/trace evidence, identifying who disabled auto-cleanup or dropped related objects is difficult. Snapshot Isolation can block cleanup progress: long-running snapshot transactions may prevent safe cleanup from advancing. Keep snapshot transactions short where possible. A safe mitigation exists disable/re-enable Change Tracking on affected tables (with awareness of change data loss) can be safer than running deletion scripts. References Microsoft Learn: Change Tracking management overview (permissions, internal tables, behavior considerations). Manage Change Tracking - SQL Server | Microsoft Learn Microsoft Learn: Enable and Disable Change Tracking (retention + auto-cleanup configuration). Enable and Disable Change Tracking - SQL Server | Microsoft Learn300Views0likes0Comments