azure app service
565 TopicsAnnouncing flex nodes for AKS (preview) in Azure portal
Explore how AKS flex nodes can address regional CPU and GPU capacity constraints, bring distributed compute under one control plane, and support on-premises workload placement for data residency, now with the Azure portal experience to simplify onboarding.467Views1like0CommentsAzure Catalyst: one connected, agent-led modernization experience across apps, data, and infra
Azure Catalyst brings together Azure and GitHub Copilot in one experience to modernize applications, data, and infrastructure. It connects discovery, planning, and execution to help customers modernize faster, reduce complexity, and accelerate AI transformation.2.5KViews0likes0CommentsIntroducing Geo-redundancy in Azure App Service: Simplify multi-region application resilience
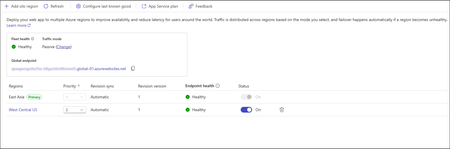
Building resilient applications across Azure regions has traditionally required teams to deploy and maintain separate applications, coordinate application updates and configuration, and manage traffic routing and failover. While these capabilities are essential for business-critical applications, implementing them can introduce significant operational complexity. Today, at Microsoft Ignite 2026, we're excited to announce the public preview of Geo-redundancy in Azure App Service, a new capability that simplifies how customers build and operate regionally resilient web applications. With Geo-redundancy, you can extend an eligible Azure App Service web app across multiple Azure regions, synchronize supported application content and configuration, and configure health-based traffic routing and regional failover, all through a unified App Service experience. The result: less time managing multi-region application infrastructure and more time delivering application value. Multi-region resilience, simplified Geo-redundancy introduces a more integrated approach to building multi-region applications on Azure App Service. Instead of independently provisioning, deploying, and maintaining web applications in multiple regions, you can start with an existing eligible web app and add managed regional replicas in supported Azure regions. Azure App Service provisions and manages the corresponding regional application and App Service plan resources, synchronizes supported application revisions, and maintains the underlying Azure Traffic Manager configuration. This gives you a simpler way to establish and operate a multi-region application topology while retaining control over where your application runs, how traffic is distributed, and how application revisions are synchronized. What's new in the public preview? Geo-redundancy brings together several capabilities designed to simplify regional application resilience: Managed regional replicas: Extend your application into additional Azure regions without independently provisioning and maintaining each regional deployment. Application content and configuration synchronization: Keep supported application revisions aligned across regions, reducing the effort required to coordinate multi-region deployments. Flexible traffic routing: Choose between Active and Passive traffic modes to align regional traffic distribution with your application's resilience strategy. Integrated health-based routing and failover: Use Azure Traffic Manager to direct new connections to eligible, healthy regional endpoints according to your configured routing policy. Application revision control: Inspect synchronization status, validate application revisions, and use supported last-known-good revision capabilities to maintain greater control over regional deployments. Together, these capabilities reduce the operational overhead of managing multi-region web applications while giving teams more control over how applications are deployed and served across regions. Choose how your application serves traffic across regions Different applications have different resilience requirements. Geo-redundancy supports two traffic modes, giving you flexibility in how regional application replicas participate in serving requests. Active mode: Serve traffic across multiple regions With Active mode, multiple healthy regional replicas can serve application traffic simultaneously. You can configure traffic weights to influence how new connections are distributed across eligible regional endpoints. This approach is useful for applications designed to operate across multiple regions, allowing you to distribute application traffic while maintaining regional deployment flexibility. Passive mode: Prioritize a primary region with regional failover With Passive mode, your application primarily serves traffic from a designated region, with additional regional replicas available as failover destinations. You configure regional routing priorities to determine which endpoints should receive traffic when the preferred region becomes unavailable. This approach is particularly useful for applications that normally operate from a primary region but need an alternative regional hosting destination when disruptions occur. Both modes use Azure Traffic Manager's DNS-based routing capabilities. Routing decisions depend on endpoint health and the configured policy, with failover timing influenced by DNS caching and client behavior. Whether your application needs multiple active regions or a primary region with standby capacity, Geo-redundancy provides an integrated way to configure and manage regional traffic routing. Simplify application deployments across regions Maintaining consistent application versions across regions is an important part of operating resilient applications. Geo-redundancy helps simplify this process by enabling supported application content and configuration to be synchronized from your primary web app to regional replicas. Rather than coordinating every regional application deployment independently, you can deploy supported updates to your primary application and manage their synchronization across regional replicas. The preview also introduces revision-management capabilities that help you: Inspect application revision and synchronization status across regions. Control when supported application revisions are synchronized. Validate application revisions in regional replicas. Retain a validated last-known-good revision for a replica where supported. These capabilities give application teams greater visibility and control over regional application versions, helping reduce the complexity of coordinating deployments across multiple Azure regions. Applications should still be validated in each region, including their dependencies and regional configuration. Changes made outside supported deployment workflows may require an explicit snapshot or synchronization action. Build resilience across your application architecture Geo-redundancy simplifies multi-region application hosting on Azure App Service, but resilient applications also depend on the availability of their underlying services. Databases, storage accounts, secrets, networking, external APIs, and other application dependencies must be designed and configured with appropriate regional resilience. For example, an application replica may be healthy and available in another region, but it still needs access to the data and downstream services required to process requests. Geo-redundancy does not automatically replicate databases, Azure Storage, Azure Key Vault, live runtime state, or external dependencies. Customers remain responsible for designing and testing the resilience of these services, including data consistency, regional connectivity, and recovery behavior. Geo-redundancy simplifies the application hosting layer of your resilience architecture, allowing your team to focus on the broader application and data resilience strategy. Get started with Geo-redundancy in public preview The public preview of Geo-redundancy is initially available for eligible Windows web apps running on Premium v3 and Premium v4 App Service plans in supported multitenant Azure regions. Getting started involves five steps: Choose your application and regions. Review preview eligibility, supported configurations, and regional availability. Add a regional replica. Configure Geo-redundancy for an eligible web app and select a supported Azure region. Configure traffic routing. Choose Active or Passive mode and configure the appropriate regional weights or priorities. Synchronize and validate your application. Verify supported application content, configuration, and revision status across regions. Test your resilience strategy. Validate endpoint health, regional failover, recovery behavior, and the availability of application dependencies. Before enabling the preview, review the published support matrix for supported regions, application configurations, custom-domain requirements, and known limitations. Pricing Geo-redundancy introduces a per-enabled-application monthly charge in addition to the App Service compute charges associated with the primary application and regional replicas. For current pricing and billing details, see Azure App Service pricing. Take the next step toward multi-region application resilience Building regionally resilient applications shouldn't mean building and operating your own multi-region application deployment and traffic-management solution. With Geo-redundancy in Azure App Service, we're making it simpler to extend applications across Azure regions, coordinate application revisions, and configure regional traffic routing and failover. The public preview is an opportunity to explore a simpler approach to multi-region application hosting, with more integrated management and greater control over regional application behavior. Ready to explore what's possible? Explore Geo-redundancy in Azure App Service and get started with the public preview.270Views0likes0CommentsModernize more Windows applications with Managed Instance on Azure App Service
For many organizations, the hardest part of modernizing a Windows web application isn't moving the code. It's understanding the dependencies that tie the application to its current server: installed components, registry settings, Windows services, network shares, and other operating system configuration. Since Managed Instance on Azure App Service became generally available in August 2026, we've continued investing in ways to make these migrations easier to discover, assess, and execute. At Microsoft Ignite 2026, we're highlighting three updates: Azure Catalyst support, Premium v3 availability, and Isolated v4 support. Together, they make Managed Instance easier to include in portfolio-scale modernization plans and give customers more flexibility in choosing where to host eligible applications. Start with discovery: Azure Catalyst support for Managed Instance Modernization begins with understanding which applications you have and which Azure destination fits their requirements. Applications with Windows-specific dependencies may have been ruled out for conventional App Service migrations, leaving teams to choose between extensive rewrites and continuing to manage virtual machines. Azure Catalyst support for Managed Instance helps bring this hosting option into migration discovery and assessment workflows. Teams can revisit Windows web applications that were previously considered unsuitable for standard App Service hosting, assess their dependencies, and evaluate whether Managed Instance is an appropriate destination. This supports a more repeatable modernization approach: Discover Windows application workloads across the estate. Assess application and infrastructure dependencies, using Azure Migrate and available assessment tooling. Identify candidates whose requirements align with Managed Instance capabilities. Validate one representative application in a non-production environment. Expand from a proven migration pattern to a wider application portfolio. Azure Catalyst assessment informs the decision; it does not guarantee compatibility or eliminate the need to test installation scripts, networking, configuration, and application behavior. Managed Instance also complements Azure Catalyst in GitHub Copilot modernization for .NET, which can help teams assess, remediate, validate, and deploy suitable applications. More hosting flexibility: Premium v3 availability Managed Instance initially emphasized Premium v4 hosting. We're expanding the options with support for Premium v3 and Premium v3 memory-optimized plans in enabled regions. This gives customers an additional path where Premium v4 regional capacity or availability would otherwise constrain a modernization project. It also allows teams to consider a broader set of App Service compute options when balancing workload needs, capacity, and cost. Premium v3 availability is being enabled across eligible App Service infrastructure over time. Dedicated hosting: Isolated v4 support We're also expanding Managed Instance to Isolated v4 App Service plans in App Service Environment v3. This brings Managed Instance capabilities to a single-tenant App Service hosting environment for organizations whose architecture calls for dedicated hosting and network isolation. It offers another modernization option for eligible Windows web applications with installed components, operating system customization, or other supported dependencies. Isolated v4 expands the choice of hosting environment; it does not mean arbitrary server administration or that every Windows workload is supported. Customers should validate Managed Instance feature boundaries, region support, networking, and application dependencies before migration. Why Managed Instance matters Managed Instance on Azure App Service is designed for Windows web applications that need more operating system customization than conventional App Service hosting offers, while retaining managed platform benefits such as patching, scaling, diagnostics, and identity integration. Capabilities include: - Configuration scripts for supported installers, components, Windows features, and services. - Registry adapters for supported application configuration. - Storage mounts for required file-share and drive-letter scenarios. - Secure RDP through Azure Bastion for diagnostics and familiar Windows tools. - Managed identity and Azure Key Vault integration for securely accessing supported resources and secrets. Managed Instance is intended for eligible Windows web applications. It is not a Linux or container hosting option, nor a replacement for a fully customizable Windows virtual machine. From one application to a modernization portfolio These updates connect the key stages of modernization: - Discover and assess: Use Azure Catalyst and application assessment tools to identify candidates. - Modernize where needed: Use GitHub Copilot modernization for .NET and targeted changes to address compatibility gaps. - Choose the hosting model: Evaluate Managed Instance on Premium v3, Premium v4, or Isolated v4, subject to region and plan support. - Migrate and operate: Validate dependencies and deploy to App Service with managed operational capabilities. A practical first step is to revisit one Windows web application previously excluded from App Service because of its dependencies. Assess it, validate its fit, and use the lessons learned to inform a repeatable approach for similar applications. Get started - Managed Instance quickstart - Managed Instance configuration documentation - Managed Instance samples and configuration scripts - Managed Instance overview on Microsoft Learn Revisit applications that previously seemed too complex for App Service. With Azure Catalyst support and more hosting choices, Managed Instance can help you move more of your Windows application portfolio to a managed platform with fewer changes.104Views0likes0CommentsWhat's new in Azure Functions durable task scheduler: Durable agents, disaster recovery, and more
There's been a lot happening with the Azure Functions durable task scheduler lately. Here's a quick look at what's new: Durable agents: The Durable Extension for Microsoft Agent Framework is generally available, durable execution with DTS for LangGraph is in preview, and Pydantic AI now includes Azure Durable Task as a built-in durability option. Native disaster recovery and task queues: Both are now in public preview. Private endpoints and customer-managed keys: Both are now generally available. Durable Task Go SDK: Now available in preview. Whether you're running business workflows, processing event-driven pipelines, or coordinating AI agents, here's what these updates mean for your apps and how to get started. What is the Durable Task Scheduler? If you're new to the Durable Task Scheduler, it's a fully managed durable execution backend for workflows and agents on Azure. It saves progress as work runs, so applications can recover from interruptions without starting over. Completed steps whose results have been saved can be reused, and workflows can wait for human input or external events without keeping a worker active just to wait. DTS handles task scheduling, state persistence, and recovery. Its built-in dashboard lets you inspect execution history and manage running orchestrations. The DTS dashboard shows the execution timeline of a travel-planning workflow, including agent calls and a wait for approval. DTS runs separately from your application. Use it with Durable Functions, the Durable Task SDKs, or supported agent framework integrations, including the Durable Extension for Microsoft Agent Framework. Your application code can run anywhere in Azure, including Azure Functions, Azure Container Apps, and Azure Kubernetes Service. Already using DTS? Here's what's new. Durable execution in agent SDKs Agents and workflows need more than conversation history to recover from interruptions. They might call several tools, start a long-running job, or wait for someone's approval. If a worker restarts halfway through, the application needs to know which steps completed and what should happen next. Durable execution saves that progress, so agents and workflows can run for minutes, days, or weeks and resume from recorded progress after worker or container restarts, scaling events, or infrastructure failures. Retry policies help handle transient errors such as rate limits and timeouts. Completed model calls, tool calls, and activities whose results have been saved can be reused during recovery, reducing repeated work and token costs. Conversation context remains available, and workflows can wait for approvals or external events for hours or days without keeping a worker active just to wait. You can bring these durable execution capabilities to agents and workflows built with Microsoft Agent Framework, LangGraph, or Pydantic AI. Here's how to get started with each: Microsoft Agent Framework: The Durable Extension is generally available for .NET and Python. Keep your core agent logic and coordinate durable agents and multi-agent workflows with Durable Task orchestrations or Agent Framework graphs. See the GA blog post and samples. LangGraph: In public preview. Add DTS to existing Python graphs, ReAct agents, and Deep Agents on Azure without rewriting your graph logic. Pydantic AI: Azure Durable Task is now available as a durability capability in Pydantic AI Harness. Use it with Durable Task orchestration and worker setup to persist model and tool results and recover agent execution without building your own checkpointing or recovery system. Native disaster recovery is now in public preview Native disaster recovery for Azure Functions durable task scheduler is now in public preview. For business-critical workflows and applications with cross-region recovery requirements, it provides a way to resume work in another region from replicated state rather than starting workflows over. Pair your primary scheduler with a secondary in another Azure region, and DTS replicates orchestration and entity state to the secondary. When you need to fail over, you can promote the secondary and resume work from that replicated state. Learn more: Disaster recovery documentation. Task queues are now in public preview Task queues for Azure Functions durable task scheduler are now in public preview. Group orchestration and activity work into named queues within a task hub and control how quickly DTS delivers that work to workers. This helps teams pace batch processing and give different workloads their own dispatch-rate budgets without creating separate task hubs. For workloads that call downstream services, it provides a way to manage how quickly work is dispatched. Create a queue, configure its work-item delivery rate, and select it using the DTS_TaskQueue tag when scheduling work. For a closer look at how task queues work and an example of how to use them, see Task queues in Durable Task Scheduler. Learn more: Task queues documentation and SDK examples. Private endpoints are now generally available Private endpoints for Azure Functions durable task scheduler are now generally available for both Consumption and Dedicated SKU schedulers. Connect your applications to DTS through a private IP address in your virtual network using Azure Private Link. Traffic stays on the Microsoft backbone instead of traversing the public internet. You can also disable public network access so your scheduler accepts connections only through private endpoints. Applications continue to use the same scheduler endpoint and Microsoft Entra authentication. Learn more: Configure private endpoints for DTS. Customer-managed keys are now generally available Customer-managed keys for Azure Functions durable task scheduler are now generally available for Dedicated SKU schedulers. Organizations that need to manage their own encryption keys can now use customer-managed keys to protect their workflow data, supporting separation of duties, centralized auditing of key access, and customer-defined key rotation policies. Use a key you own in Azure Key Vault or Azure Managed HSM to protect scheduler data at rest. Configuration is available through the ARM REST API, Azure CLI using az rest, or Bicep. Learn more: Configure customer-managed keys for DTS. The Durable Task Go SDK is now available in preview Writing your application in Go? You can now build durable workflows with the Durable Task Go SDK, available in preview. Write your orchestrations and activities in Go, and let DTS take care of durable state and dispatching work. You can chain activities, run work in parallel, wait for external events, and use durable timers. Retry policies help you handle failures, and orchestration management APIs let you manage execution. Start locally with the DTS emulator, then connect your application to a scheduler in Azure when you're ready. You'll need Go 1.25 or later, and DTS is currently the SDK's only supported runtime. Get started: Go SDK documentation, DTS quickstart sample, and Go sample catalog. Get started with the Durable Task Scheduler If you're new to DTS, start with the documentation and samples. You can develop locally with the emulator, then choose the Consumption or Dedicated SKU based on your workload's pricing and capacity requirements. We'd love to hear your feedback, especially as you try the new previews. Share questions and feedback through the Durable Task Scheduler GitHub repository.247Views0likes0CommentsIntroducing Azure App Service Builder (Public Preview)
This is a summarized version of the full post which can be found here: Introducing Azure App Service Builder: From code to a running app Builder brings application builds, hosting, and deployment management into one app-focused workflow. Connect an authorized GitHub repository for source-based builds or deploy a ZIP package, track deployment progress, and open your app at its service-provided URL. The initial preview focuses on static sites, web applications, and HTTP APIs. Whether you write code directly or work alongside an AI coding agent, Builder helps reduce the setup and handoffs between development and deployment so you can spend more time building and iterating on your application. A new option alongside the App Service you use today Builder does not replace existing Azure App Service experiences. Those experiences remain available and supported, and there is no requirement to move an existing application. Builder offers a new starting point for applications where a streamlined code-to-app workflow is a priority. The public preview is intended for development and test workloads, has no financially backed SLA, and is not recommended for production workloads. Supported regions, runtimes, workflows, and resource limits apply. Read the full announcement For a walkthrough, more on how Builder fits alongside existing App Service experiences, and what to expect during preview, read Introducing Azure App Service Builder: From code to a running app on the App Service Builder blog. Ready to explore? Visit the Builder portal and the App Service Builder documentation to get started.756Views0likes0CommentsRun on your schedule: App Service plan start/stop now in public preview
Start and stop your apps together Managing an environment with multiple apps shouldn't mean stopping and starting each app individually. App Service plan start/stop brings that control to the plan level, letting you manage the apps and deployment slots it hosts together. Today, we're announcing the public preview for this feature for Premium v4 (Pv4) and Premium memory-optimized v4 (Pmv4) plans. Stop the plan to take its workloads offline, then start it again when you're ready, without issuing separate commands for each app. NOTE: Start and stop operations are asynchronous: the apps on your plan don’t all stop or become ready to serve requests immediately. After you stop a plan, app shutdown and cleanup can continue over the next few minutes. When you start it again, allow time for your applications to become ready before sending traffic. This is particularly useful for development, test, and demo environments that share an operating schedule. Because the operation affects the entire plan, make sure every hosted workload can tolerate the interruption. To bring workloads on a stopped plan back online, start the plan rather than an individual app. Get started with Azure CLI You can call the start and stop REST operations using az rest . Sign in to Azure, select the subscription containing your plan, and set its resource group and name: resourceGroup="[RESOURCE-GROUP-NAME]" planName="[APP-SERVICE-PLAN-NAME]" planId=$(az appservice plan show \ --resource-group "$resourceGroup" \ --name "$planName" \ --query id --output tsv) || exit 1 # Stop the plan. All hosted apps and deployment slots will be unavailable. az rest --method post --url "https://management.azure.com${planId}/stopSites?api-version=2026-07-15" When you're ready to run the workloads again, start the plan: az rest --method post --url "https://management.azure.com${planId}/startSites?api-version=2026-07-15" Plan for application startup time before sending traffic back to the environment. A successful API response isn't a substitute for checking that your applications are ready to serve requests. Get started with the Azure portal You can also use the Azure portal to start and stop your plans. On the App Service plan Overview page, select start and stop as you may have done for your individual apps. If you try to start an app when its App Service plan is stopped, you will get an error letting you know to start the App Service plan instead. NOTE: This feature is rolling out in the portal over the next few weeks. If you don't see the option in the portal yet, check back in a couple days and use the Azure CLI in the meantime. Billing considerations Compute billing for an eligible plan pauses when the plan is stopped, even though app shutdown and cleanup can continue over the next few minutes. Compute billing resumes when the plan is started. Charges for other resources and services can continue. Preview limitations and considerations Supported tiers: Premium v4 and Premium memory-optimized v4 only. Other App Service plan tiers aren't supported. Availability: All public regions that support Premium v4 Plan-wide impact: All apps and deployment slots on the plan are affected. Don't stop a plan that also hosts workloads that must remain available. Restart at the plan level: Attempting to start an individual app will not restart the plan. You must restart the plan to restart the apps. Automatic scaling: Plans with App Service automatic scaling enabled aren't supported. This is distinct from Azure Monitor autoscale. Scaling in progress: Wait for an in-progress asynchronous scale operation to finish before starting or stopping the plan. Start/stop throttling: Plan start and stop operations are subject to a five-minute throttle. Account for this when scheduling operations or testing repeated start/stop cycles. Changes while stopped: Start the plan before scaling it or making other plan updates. Try the preview Try start/stop on a development or test plan whose apps share an operating schedule. Review the apps and deployment slots it hosts, then use the plan-level commands to stop and start those workloads together instead of managing each app individually. For the API details, see Stop Web Apps and Start Web Apps.292Views0likes0CommentsWhy Did Our Azure Bill Change? Investigating Cloud Spend with Azure SRE Agent
The question after the cost chart The monthly cost review usually starts with a straightforward observation: Azure spending changed. Then come the questions that take the time. Which subscription accounts for the increase? Is it an existing workload getting more expensive, or something that only started generating charges this month? Did a reduction somewhere else hide part of the increase? And which optimization recommendations are worth taking to a workload owner? Azure already has the underlying information. Cost Management provides spending data. Azure Advisor provides optimization recommendations. Resource inventory provides context about what those resources are. The work is connecting those sources into an explanation that someone can check and act on. Conversational Cost Analytics Agent: a solution built around Azure SRE Agent that lets operations and FinOps leads start with a question, investigate cost drivers, identify optimization opportunities, and generate reusable reports. The solution can also generate proactive alerts and scheduled reports. Scope of this post: The repository contains a prototype, an importable dashboard template, reusable skills, and example report screenshots. These demonstrate the reporting approach; they are not evidence of measured customer savings, verified production readiness, or a completed deployment in your environment. The prompts below are examples to try, not a transcript of a measured production investigation. What we built This is a custom cost-investigation workflow on Azure SRE Agent, not a separate billing system or a claim that every feature is available out of the box. The solution brings together three pieces: An analytical skill that describes how to compare spending, calculate resource contributions, identify newly billed resources, and handle incomplete periods. A query-reference skill that records the Cost Management query patterns, response shapes, aggregation rules, and SRE Agent tool mappings used by the dashboard workflow. An HTML Live Report template that presents subscription selection, summary metrics, six-month trends, and expandable resource-level comparisons. The distinction matters. A template determines how findings appear. A skill determines how the agent should investigate. Neither replaces access to the underlying data. The agent still needs scoped permissions, supported tools, and a successful data refresh before the report can represent your subscriptions.' How the investigation works The workflow starts by discovering the subscriptions the agent can access. It then queries Cost Management for historical totals and current- and previous-month resource-level details, aggregates the results, and populates the report template. Source or component Role in the investigation Azure Cost Management Billing-based cost data and historical comparisons Azure Resource Graph Resource inventory and metadata enrichment, not cost data Azure Advisor Optimization recommendations to review alongside spending Reusable agent skills Investigation rules, query patterns, and interpretation guardrails Live Report template Interactive presentation of the refreshed data snapshot How cost data is collected: The agent sends a request to Azure Cost Management to retrieve spending data. The request uses HTTP POST, so the kit runs it through RunAzCliWriteCommands, even though it only reads data. Reading costs does not change resources: This query does not resize, delete, or modify resources. Still, configure permissions and tools carefully to limit what the agent can do. The report shows the most recently refreshed data: Opening the report displays the data collected during its most recent refresh. It does not automatically request updated billing data. Fetching data directly from the report requires a connector: A supported connector gives the report access to a cost-query tool. The report cannot directly use the agent’s built-in CLI tools. You can start without a connector: Use the report with periodically refreshed data, and add a connector later if you need to fetch updates directly from the report. Four questions to explore in the report 1. Where is spending heading? Start with the broad view: The overview brings subscription selection, summary KPIs, previous-month actuals, and an adjustable cost trend into one view. Select the number of months you want to compare, up to 12, and expand any month to explore the services behind the spending changes. Figure 1. Historical prototype snapshot, not current pricing or a verified financial result. The current-month KPI is a projection; the screenshot does not establish that the partial-month trend bar uses the same basis. Reconcile those values and use consistent labels before relying on the comparison. This is also where an apparently simple comparison can become misleading. Ten days of current-month spend and a full previous month are not comparable periods. For an in-progress month, ask for matched month-to-date periods when investigating change. If the report displays a full-month run-rate projection, keep it labeled as a projection. Do not describe it as a Cost Management forecast unless that forecast was actually retrieved. The useful outcome is not just a larger or smaller bar. It is an explicit statement of the period, cost basis, currency, and freshness behind that bar. 2. Which resources explain the change? Once the subscription-level movement is clear, move to the contributors: "Rank the resources driving increases and decreases. Separate newly billed resources from existing resources whose costs changed." The resource view compares spending at the resource level, highlights resources appearing in the current period’s billing data, and supports expandable service breakdowns. Figure 2. Historical prototype comparison. The screenshot's "New Resources" label means newly observed in billing, not confirmed creation. In this example workflow, current-month "Full" values are projections, not completed-month actuals. The agent can help break down cost changes that might otherwise require multiple spreadsheets and time-consuming manual comparisons: New charges do not always mean new resources: An existing resource may start generating charges after a period of inactivity. Costs may also rise because of autoscaling, longer VM running hours, increased storage usage, more read/write operations, or billable data transfers. These changes can be difficult to spot in summary reports. Newly created resources can add to spending: The agent can highlight resources appearing in the current period’s billing data. Resource inventory or deployment history is needed to confirm whether they were newly created or simply started generating charges. One resource can have several cost entries: A resource may appear in multiple billing records for different services or meters. Adding the relevant entries together helps show its total cost and contribution to the change. The net change can hide larger movements: For example, if one resource’s cost increases by $800 while another decreases by $300 over comparable periods, the net increase is $500. Showing both changes reveals the increase and the offsetting reduction. These figures are illustrative. Finding the cost driver is not the same as finding the cause: Identifying which resource contributed to an increase is the first step. Explaining why it happened may require additional evidence about usage, configuration changes, pricing, or other factors. 3. Which optimization opportunities deserve attention? The next question is usually practical: "Show Azure Advisor cost optimization recommendations for the subscriptions in scope. Separate estimated savings from confirmed spending reductions." The repository includes an example Advisor optimization view for reviewing rightsizing and commitment-related opportunities alongside the cost investigation. Figure 3. Historical prototype optimization view. Displayed savings are estimates, not realized savings; low CPU alone does not establish that shutdown is appropriate. A displayed zero for reservations requires a successful, authorized query before it can be interpreted as no reservations. The useful next step is to review the findings with the workload owner, not to make an automatic purchase or resize a resource. Rightsizing can change the baseline for a reservation or savings plan decision. Recommendations can also overlap, so adding every displayed savings figure may overstate the opportunity. Billing and commitment visibility depend on the identity's actual access; subscription resource access does not automatically expose every reservation or savings plan dataset. An unavailable dataset should be reported as unavailable. It should never silently become "no recommendations" or "no commitments." 4. What might we be paying for without using? Finally, investigate cleanup candidates: "Identify potentially orphaned resources and show the evidence that makes each one a candidate for owner review." The example orphaned-resource view covers candidates such as unattached disks, stale snapshots, unassociated public IP addresses and network interfaces, and empty App Service plans. Figure 4. Example cleanup-candidate inventory. An apparent orphan is an investigation finding, not deletion approval. An unattached disk may be retained for recovery. A snapshot may be subject to a retention requirement. A network resource may be reserved for a planned deployment. The report should help the owner answer those questions by identifying the resource, its state, and any observed charges. It should not turn "not currently attached" into "safe to delete." The intended configuration is read-only reporting and investigation. Validate the identity's effective permissions and enabled tools before use; the template alone does not enforce that boundary. Any cleanup requires separate validation and explicit approval. Have a meaningful cost conversation with the agent A cost dashboard remains useful. It shows the shape of spending and gives people a shared view. However, a conversational approach takes this further by helping users investigate what is driving spending, identify key contributors, distinguish new charges from changes in existing resources, and explore cost optimization opportunities. Start with a simple cost question, then use follow-up prompts to explore what changed, which resources contributed, and what needs further investigation. Example prompts include: “Which subscriptions and resources explain the largest cost increases compared with last month?” “Why did costs increase this month?” “Which resources contributed most to the increase?” “Is this newly billed spending or higher costs from existing resources?” “Compare the last three months and show the biggest changes.” “Create a report focused on this subscription and its top cost drivers.” “Show Azure Advisor savings opportunities and orphaned resources that require owner review.” “Refresh this report every Monday morning.” With the required data access and tools configured, the agent can help rerun analyses, narrow the scope, and generate reports focused on specific cost questions. Scheduled reports and cost alerts require supported capabilities, appropriate permissions, and separate configuration. Check findings against source data before making decisions or changing resources. Try it in your environment Start with one subscription whose costs you already understand. That makes it easier to reconcile the first report before expanding the scope. Review the kit. Start with the repository overview Add the three skills from the skills folder, and upload the cost analysis playbook as a knowledge source. Configure scoped access. The kit calls for Cost Management Reader and Reader on each target subscription for cost queries and inventory enrichment. Validate any additional billing or commitment access separately. Bootstrap the report. Submit the first-run prompt from the bootstrap prompts and provide the HTML report template. Validate the result. Reconcile a completed month's totals against Cost Management using the same scope, currency, and cost basis. Check resource aggregation, labels, and missing-data states. Configure refresh only after validation. The kit includes a suggested Monday 07:00 UTC refresh prompt. Confirm scheduling support, permissions, and failure handling in your environment before relying on it. Using this workflow may incur Azure SRE Agent charges and other applicable service charges. Review Azure SRE Agent pricing and billing and the pricing for the services you configure before running a pilot. This post does not describe a free service offering. Further reading Azure SRE Agent overview Azure Cost Management overview Azure Cost Management Query API Azure Advisor cost recommendations Azure Resource Graph overview612Views1like0CommentsAnnouncing the Public Preview of the New App Service Quota Self-Service Experience
Update 10/30/2025: The App Service Quota Self-Service experience is back online after a short period where we were incorporating your feedback and making needed updates. As this is public preview, availability and features are subject to change as we receive and incorporate feedback. What’s New? The updated experience introduces a dedicated App Service Quota blade in the Azure portal, offering a streamlined and intuitive interface to: View current usage and limits across the various SKUs Set custom quotas tailored to your App Service plan needs This new experience empowers developers and IT admins to proactively manage resources, avoid service disruptions, and optimize performance. Quick Reference - Start here! Leverage the new self-service experience to increase your quota automatically. If your deployment requires quota for ten or more subscriptions, then file a support ticket with problem type Quota following the instructions at the bottom of this post. If any subscription included in your request requires zone redundancy (note that most Isolated v2 deployments require ZR), then file a support ticket with problem type Quota following the instructions at the bottom of this post. Self-service Quota Requests For non-zone-redundant needs, quota alone is sufficient to enable App Service deployment or scale-out. Follow the provided steps to place your request. 1. Navigate to the Quotas resource provider in the Azure portal 2. Select App Service (Public Preview) Navigating the primary interface: Each App Service VM size is represented as a separate SKU. If the intention is to be able to scale up or down within a specific offering (e.g., Premium v3), then equivalent number of VMs need to be requested for each applicable size of that offering (e.g., request 5 instances for both P1v3 and P3v3). As with other quotas, you can filter by region, subscription, provider, or usage. Note that your portal will now show "App Service (Public Preview)" for the Provider name. You can also group the results by usage, quota (App Service VM type), or location (region). Current usage is represented as App Service VMs. This allows you to quickly identify which SKUs are nearing their quota limits. Adjustments can be made inline: no need to visit another page. This is covered in detail in the next section. Total Regional VMs: There is a SKU in each region called Total Regional VMs. This SKU summarizes your usage and available quota across all individual SKUs in that region. There are three key points about using Total Regional VMs. You should never request Total Regional VMs quota directly - it will automatically increase in response to your request for individual SKU quota. If you are unable to deploy a given SKU, then you must request more quota for that SKU to unblock deployment. For your deployment to succeed, you must have sufficient quota in the individual SKU as well as Total Regional VMs. If either usage is at its respective limit, then you will be unable to deploy and must request more of that individual SKU's quota to proceed. In some regions, Total Regional VMs appears as "0 of 0" usage and limit and no individual SKU quotas are shown. This is an indication that you should not interact with the portal to resolve any quota-related issues in this region. Instead, you should try the deployment and observe any error messages that arise. If any error messages indicate more quota is needed, then this must be requested by filing a support ticket with problem type Quota following the instructions at the bottom of this post so that App Service can identify and fix any potential quota issues. In most cases, this will not be necessary, and your deployment will work without requesting quota wherever "0 of 0" is shown for Total Regional VMs and no individual SKU quotas are visible. See the example below: 3. Request quota adjustments Clicking the pen icon opens a flyout window to capture the quota request: The quota type (App Service SKU) is already populated, along with current usage. Note that your request is not incremental: you must specify the new limit that you wish to see reflected in the portal. For example, to request two additional instances of P1v2 VMs, you would file the request like this: Click submit to send the request for automatic processing. How quota approvals work: Immediately upon submitting a quota request, you will see a processing dialog like the one shown: If the quota request can be automatically fulfilled, then no support request is needed. You should receive this confirmation within a few minutes of submission: If the request cannot be automatically fulfilled, then you will be given the option to file a support request with the same information. In the example below, the requested new limit exceeds what can be automatically granted for the region: 4. If applicable, create support ticket If automatic quota fulfillment fails, and it recommend you Create a support request, then follow the steps given in the at the end of this post. Known issues The self-service quota request experience for App Service is in public preview. Here are some caveats worth mentioning while the team finalizes the release for general availability: Closing the quota request flyout window will stop meaningful notifications for that request. You can still view the outcome of your quota requests by checking actual quota, but if you want to rely on notifications for alerts, then we recommend leaving the quota request window open for the few minutes that it is processing. Some SKUs are not yet represented in the quota dashboard. These will be added later in the public preview. The Activity Log does not currently provide a meaningful summary of previous quota requests and their outcomes. This will also be addressed during the public preview. As noted in the walkthrough, the new experience does not enable zone-redundant deployments. Quota is an inherently regional construct, and zone-redundant enablement requires a separate step that can only be taken in response to a support ticket being filed. Quota API documentation is being drafted to enable bulk non-zone redundant quota requests without requiring you to file a support ticket. Create a support request Important: Most App Service quota requests can be completed through the self-service experience without creating a support request. If you're prompted to create one, select Severity B or Severity C. Requests submitted at these severity levels will enter the automated quota-processing workflow. Severity A requests are not currently eligible for this automation, and selecting a higher severity does not typically expedite a quota increase request. While we are continuously improving the system to automatically process quota requests, there are certain scenarios you might need to create a support request: Automatic fulfillment request failed on quota blade. Deployment requires zone-redundancy You want to make bulk request for ten or more subscriptions When creating a support request, select your Issue type as “Service and subscription limits (quotas)” and Quota type as “Function or Web App (Windows and Linux)”. Select Next. You can then fill in your quota requirements by clicking on “Enter details”. There are 4 mandatory fields you must provide in your request: Region – Quota limits are based on region. If you are facing quota limits in one region, you can always try deployment in a geographically paired region. For example, West US 2 and West Central US are paired regions. East Asia (Hong Kong) and Southeast Asia (Singapore) are also paired regions. See Azure cross-region replication pairings for all geographies for more information. Deployment type – This is another important criterion when submitting quota request. If you are not sure which deployment type your App Service Plan is using, you can check it here on the portal: App >> App Service Plan >> Zone redundant >> Enabled\Disabled. App Service plan – Each SKU in your subscription and the region selected above, will have its own limit. Choose the SKU based on your deployment requirement. You will be able to see the current usage and the limit on that SKU. New limit – You must submit the new limit that you want for the SKU selected above. Do not add the increment value. The new limit must be higher than the existing limit. If you choose to create a support ticket, then you will interact with the capacity management team for that region. This is a 24x7 service, so requests may be created at any time. Once you have filed the support request, you can track its status via the Help + support dashboard. Note for Logic Apps You can now self-serve your Logic App quota requirements using the same App Services quotas blade. You must choose one of the Logic App SKUs (WS1, WS2, WS3) when making the request, and it will be processed in the same way App Services requests are processed. We want your feedback! If you notice any aspect of the experience that does not work as expected, or you have feedback on how to make it better, please use the comments below to share your thoughts!26KViews5likes37Comments