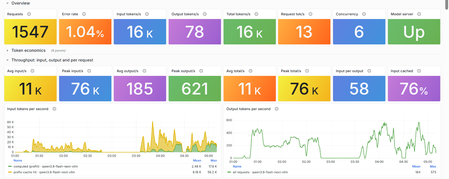
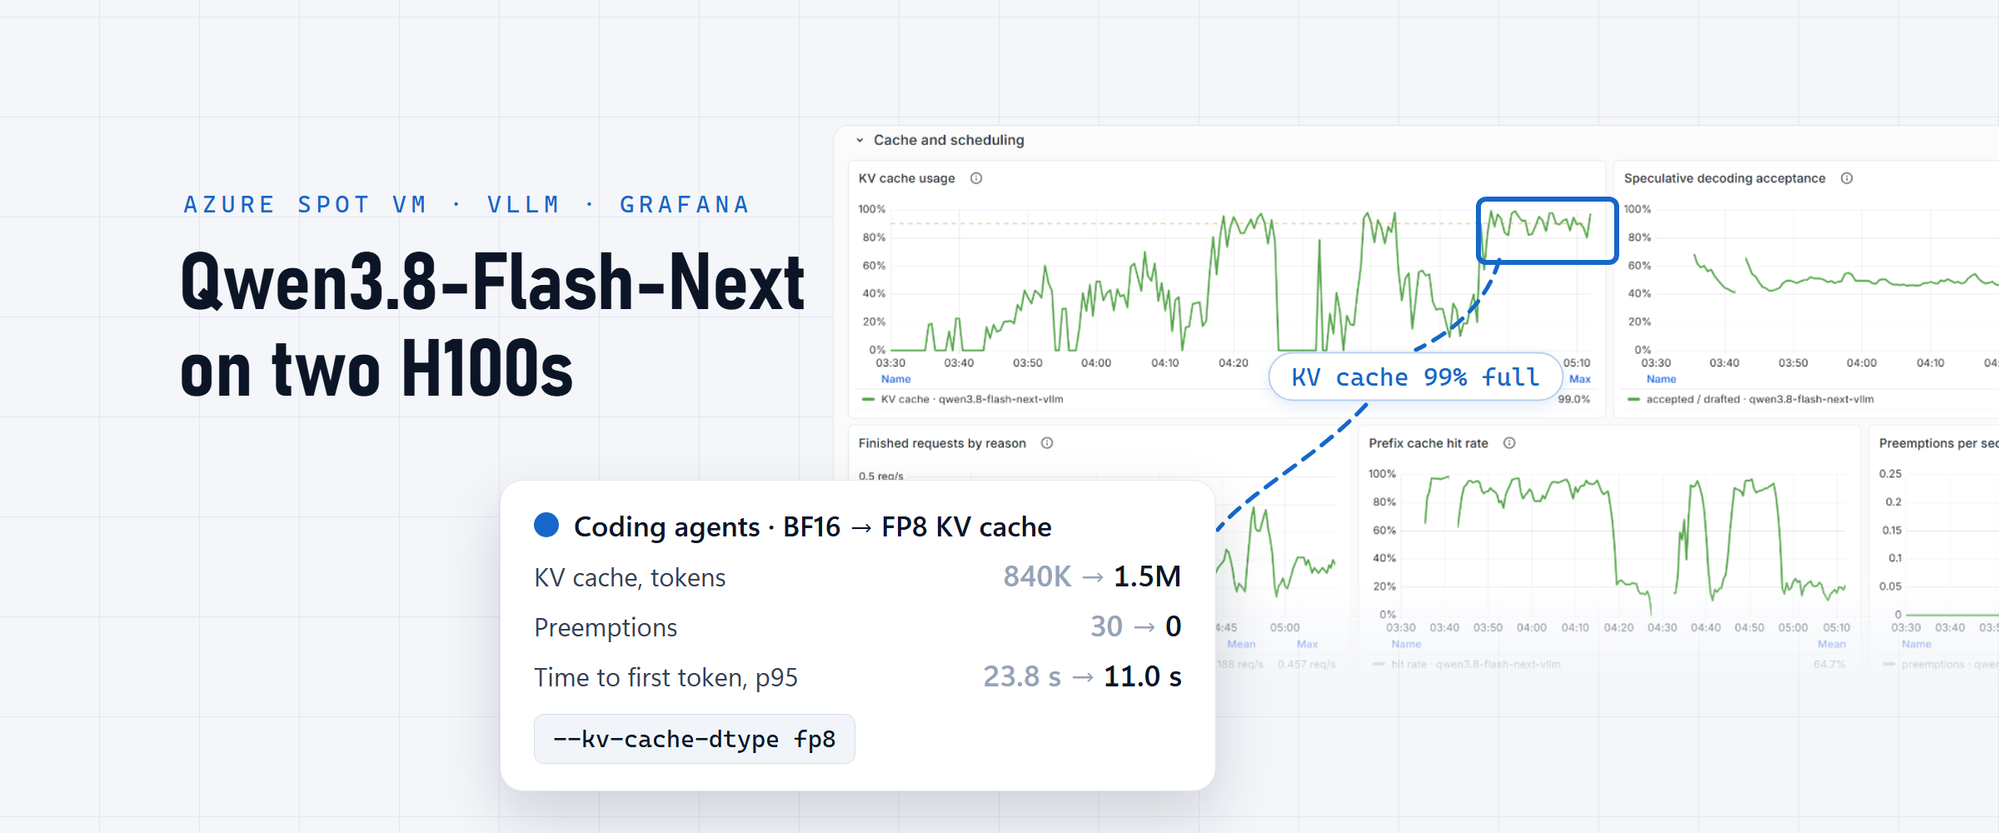
How to serve a 125B mixture-of-experts model on a two-GPU Azure Spot VM with vLLM, and what its metrics, traces and GPU counters show when coding agents use it.
Updated Oct 30, 2026
Version 2.0
Wuyi_Weng Microsoft
 MicrosoftMicrosoft

Interesting performance results, especially the impact of prompt caching on token throughput and time to first token. It would be great to see how these results compare across different VM configurations and what trade-offs emerge between Spot VM cost savings, GPU availability, and production reliability.