storage
22 TopicsIntroducing New Performance Tiers for Azure Managed Lustre: Enhancing HPC Workloads
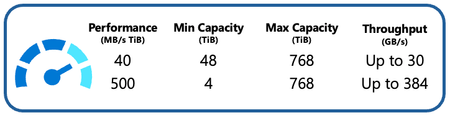
Building upon the success of its General Availability (GA) launch last month, we’re excited to unveil two new performance tiers for Azure Managed Lustre (AMLFS): 40MB/s per TiB and 500MB/s per TiB. This blog post explores the specifics of these new tiers and how they embody a customer-centric approach to innovation.Announcing the Public Preview of AMLFS 20: Azure Managed Lustre New SKU for Massive AI&HPC Workloads
Sachin Sheth - Principal PDM Manager Brian Barbisch - Principal Group Software Engineering Manager Matt White - Principal Group Software Engineering Manager Brian Lepore - Principal Product Manager Wolfgang De Salvador - Senior Product Manager Ron Hogue - Senior Product Manager Introduction We are excited to announce the Public Preview of AMLFS Durable Premium 20 (AMLFS 20), a new SKU in Azure Managed Lustre designed to deliver unprecedented performance and scale for demanding AI and HPC workloads. Key Features Massive Scale: Store up to 25 PiB of data in a single namespace, with up to 512 GB/s of total bandwidth. Advanced Metadata Performance: Multi-MDS (Metadata Server) architecture dramatically improves metadata IOPS. In mdtest benchmarks, AMLFS 20 demonstrated more than 5x improvement in metadata operations. An additional MDS is provided for every 5 PiB of provisioned filesystem. High File Capacity: Supports up to 20 billion inodes for maximum namespace size. Why AMLFS 20 Matters Simplified Architecture: Previously, datasets larger than 12.5 PiB required multiple filesystems and complex management. AMLFS 20 enables a single, high-performance file system for massive AI and HPC workloads up to 25 PiB, streamlining deployment and administration. Accelerated Data Preparation: The multi-MDT architecture significantly increases metadata IOPS, which is crucial during the data preparation stage of AI training, where rapid access to millions of files is required. Faster Time-to-Value: Researchers and engineers benefit from easier management, reduced bottlenecks, and faster access to large datasets, accelerating innovation. Availability AMLFS 20 is available in Public Preview alongside the already existing AMLFS SKUs. For more details on other SKUs, visit the Azure Managed Lustre documentation. How to Join the Preview If you are working with large-scale AI or HPC workloads and would like early access to AMLFS 20, we invite you to fill out this form to tell us about your use case. Our team will follow up with onboarding details.Using Azure CycleCloud with Weka
What is Azure CycleCloud? Azure CycleCloud is an enterprise-friendly tool for orchestrating and managing HPC environments on Azure. With Azure CycleCloud, users can provision infrastructure for HPC systems, deploy familiar HPC schedulers, and automatically scale the infrastructure to run jobs efficiently at any scale. CycleCloud is used for running workloads like scientific simulations, rendering tasks, Genomics and Bionomics, Financial Modeling, Artificial Intelligence, Machine Learning and other data-intensive operations that require large amounts of compute power. CycleCloud supports GPU computing which is useful for the workloads described above. One of the strengths of Azure CycleCloud is its ability to automatically scale resources up or down based on demand. If your workload requires more GPU power (such as for deep learning training), CycleCloud can provision additional GPU-enabled instances as needed. The question remains – If the GPU’s provisioned by CycleCloud are waiting for storage I/O operations, not only is the performance of the application severely impacted, the GPU is also underutilized meaning you are not fully exploiting the resources you are paying for! This brings us to Weka.io. But before we talk about the problems Weka & CycleCloud solve, let's talk about what Weka is. What is WEKA? The WEKA® Data Platform was purpose-built to seamlessly and sustainably deliver speed, simplicity, and scale that meets the needs of modern enterprises and research organizations without compromise. Its advanced, software-defined architecture supports next-generation workloads in virtually any location with cloud simplicity and on-premises performance. At the heart of the WEKA® Data Platform is a modern fully distributed parallel filesystem, WekaFS™ which can span across 1,000’s of NVMe SSD spread across multiple hosts and seamlessly extend itself over S3 compatible object storage. You can deploy WEKA software on a cluster of Microsoft Azure LSv3 VMs with local SSD to create a high-performance storage layer. WEKA can also take advantage of Azure Blob Storage to scale your namespace at the lowest cost. You can automate your WEKA deployment through HashiCorp Terraform templates for fast easy installation. Data stored with your WEKA environment is accessible to applications in your environment through multiple protocols, including NFS, SMB, POSIX, and S3-compliant applications. Key components to WEKA Data Platform in Azure include: The Architecture is deployed directly in the customer Tenant within a subscription ID of the customers choosing. WEKA software is deployed across 6 or more Azure LSv3 VMs. The LSv3 VMs are clustered to act as one single device. The WekaFS™ namespace is extended transparently onto Azure Hot Blob Scale Up and Scale down functions are driven by Logic App’s and Function Apps All client secrets are kept in Azure Vault Deployment is fully automated using Terraform WEKA Templates What is the integration? Using the Weka-CycleCloud template available here, any compute nodes deployed via CycleCloud will automatically install the WEKA agent as well as automatically mount to the WEKA filesystem. Users can deploy 10, 100, even 1000’s of compute nodes and they will all mount to the fastest storage in Azure (WEKA). Full integration steps are available here: WEKA/CycleCloud for SLUM Integration Benefits The combined solution of Weka combines the best of both worlds. With the CycleCloud / Weka template, customers will get: Simplified HPC management. With CycleCloud, you can provision clusters with a few clicks using preconfigured templates – and the clusters will all be mounted directly to WEKA. A High-Performance End to End Architecture. CycleCloud & WEKA allows users to combine the benefits of CPUs/GPUs with ultra fast storage. This is essential to ensure high throughput and low latency for computational workloads. The goal is to ensure that the storage subsystem can keep up with the high-speed demands of the CPU/GPU, especially in scenarios where you're running compute-heavy workloads like deep learning, scientific simulations, or large-scale data processing. Cost Optimization #1. Both CycleCloud and WEKA allow for autoscaling (up and down). Adjust the number of compute resources (CycleCloud) as well as the number of Storage backend nodes (WEKA) based on workload needs. Cost Optimization #2. WEKA.IO offers intelligent data tiering to help optimize performance and storage costs. The tiering system is designed to automatically move data between different storage classes based on access patterns, which maximizes efficiency while minimizing expenses. Conclusion The CycleCloud & WEKA integration delivers a simplified HPC (AI/ML) cloud management platform, exceptional performance for data-intensive workloads, cost optimization via elastic scaling, flash optimization, & data tiering, all in one user Interface. This enables organizations to achieve high throughput, low latency, and optimal CPU/GPU resource utilization for their most demanding applications and use cases. Try it today! Special thanks to Raj Sharma and the WEKA team for their work on this integration!
Azure Managed Lustre with Automatic Synchronisation to Azure BLOB Storage
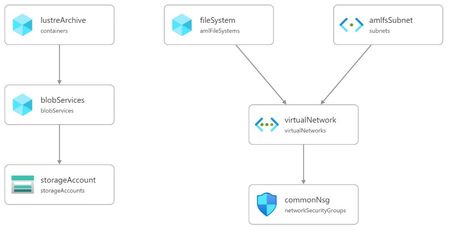
This blog post walks through how to setup an Azure Managed Lustre Filesystem (AMLFS) that will automatically synchronise to an Azure BLOB Storage container. The synchronisation is achieved using the Lustre HSM (Hierarchical Storage Management) interface combined with the Robinhood policy engine and a tool that reads the Lustre changelog and synchronises metadata with the archived storage. The lfsazsync repository on GitHub contains a Bicep template to deploy and setup a virtual machine for this purpose.Azure Managed Lustre: not your grandparents' parallel file system
Although our new Azure Managed Lustre File System is built on tried-and-true Lustre, thinking about it as the same monolithic parallel file system you'd see on-prem leaves most of its real value on the table. Let's talk about how we've made Lustre easier to use and manage in Azure, and what new ways of approaching HPC storage open up as a result.Announcing the AI Infrastructure on Azure repository
Today we’re excited to release the AI Infrastructure on Azure repository—a one-stop reference for teams building large-scale AI clusters on Azure. Authors Davide Vanzo - Senior Technical Program Manager - Azure Specialized Jer-Ming Chia - Principal Technical Program Manager - Azure Specialized Jesse Lopez - Senior Technical Program Manager - Azure Specialized Jingchao Zhang - Senior Technical Program Manager - Azure Specialized Paul Edwards - Principal Technical Program Manager - Azure Specialized Wolfgang De Salvador - Senior Product Manager - Azure Storage Introduction When building a supercomputer on Azure for AI workloads, teams must stitch together orchestration, storage, and compute components. They often spend weeks fine-tuning those configurations for peak performance. This repo delivers well-tested (Infrastructure as Code) blueprints for fully integrated clusters that prioritize reliability and performance, and that can be used to reproduce our published benchmarks. Design Considerations Building an AI supercomputer on Azure spans many moving parts: VM family selection (e.g. ND GB200 v6 vs ND H200 v5), deployment model (fully containerized AKS clusters to traditional HPC), and storage strategy—you can even run training without POSIX file systems by tuning your data lifecycle, as detailed in several blog posts and sessions. Other impactful design drivers include: Storage & I/O Capacity needs (dataset, checkpoints, logs) Throughput & IOPS (sequential vs random access patterns) Filesystem interface (POSIX-compliant vs API-native cloud storage) Tiering strategy Software & Orchestration AI framework & version (e.g MegatronLM, LLM-foundry, DeepSpeed) Container runtime (e.g enroot+pyxis, Singularity, Docker) Scheduler/Orchestration integration (e.g Slurm, Kueue, Volcano) OS image & driver stack (e.g Ubuntu/HPC image, NVIDIA drivers, IB drivers) Node Health Checks (checks for Infiniband fabric performance/health, GPU errors etc) Workflow & Automation Checkpoint frequency & size (impacts storage performance) Data staging/ingest (pre-processing on CPU nodes vs GPU nodes) Monitoring & logging (telemetry pipelines, DCGM, Prometheus) Systems optimizations CPU configs (NUMA topology files & affinity overrides) NCCL tuning (topology mapping, P2P chunk size, channel count) IB fabric tuning (queue-per-connection, zero-copy transfers) Storage tuning (mount options, I/O scheduler, parallel-FS striping) Given the breadth of these design considerations, landing on an optimal configuration can be challenging. This repo’s purpose is to centralize our battle-tested configurations and optimization guidance—so you can push the health, reliability, and performance of your Azure AI supercomputers to the limit. We’ve also published end-to-end benchmarks here, giving you clear baselines to compare your own deployments against. It also includes recommended node- and cluster-level health checks, baseline performance benchmarks, and a sample LLM training run using this configuration. Configuration guidance In this initial release, the repo provides a ready-to-run template for a "canonical" SLURM-managed HPC cluster, leveraging Azure NetApp Files for networked storage, and Azure Managed Lustre Service for parallel filesystem performance. This section of the repository is aimed to contain well-tested infrastructure as code configurations for AI supercomputers on Azure that have been widely tested and adopted. Storage Guidance The repository also provides guidance for choosing storage backends. For instance, evaluating Azure Managed Lustre tiers to match the size and performance required for the specific training jobs. One of the key elements to optimize in distributed training is the checkpoint time. This is critical for GPU utilization and it is strongly connected to the filesystem throughput. An example of this scenario for a GPT-3–style model (175 B parameters) has been presented in the repository for the case of Azure Managed Lustre. In a similar way, we present guidance on how to use BlobFuse2 with Azure Blob Storage for training jobs. Azure Blob Storage has demonstrated the ability to reach 25 Tbps of egress bandwidth on a single account in a recent Microsoft Build session. Moreover, the repository is meant to host guidance on specific filesystem tunings to maximize the delivered performance. Node and Cluster-level Healthchecks Validating cluster readiness before large-scale training runs helps catch system issues early, so you don’t waste compute cycles and can hit the performance baselines. We recommend running a series of healthchecks at both the node- and cluster-level to catch hardware or software issues early. It is recommended that AzureHPC Node Health Checks (AzNHC) is used to validate node-level functionality. Built on the LBNL NHC framework, AzNHC adds Azure-specific hardware tests for HPC and GPU VM SKUs. It includes SKU-specific tests, such as GPU availability, NVLink health, ECC memory error checks, device-to-host and host-to-device bandwidth tests, InfiniBand throughput (GDR and non-GDR), topology validation, and intra-node NCCL all-reduce benchmarks. It runs inside a Docker container that can be invoked easily. In parallel, at the cluster level, testing inter-node GPU communication with NCCL all-reduce benchmarks is an effective way to measure collective bandwidth across your fleet. The Azure HPC Image includes the prebuilt nccl-tests suite in /opt/nccl-tests/build/, which can be used to run across all nodes via MPI. The recommended NCCL settings -- CollNet/NVLS, GDR, and relaxed PCI ordering -- provide optimal collective performance and serve as the baseline. The repo includes best practices for running these validation tests. Benchmarks A recent published set of benchmarks demonstrates near-linear scaling from 8 up to 1,024 NDv5 H100 GPUs (Standard_ND96isr_H100_v5), delivering training performance on par with NVIDIA’s reference DGX systems and underscoring Azure’s infrastructure scalability and efficiency for large-scale AI workloads. These benchmarks ran on the repo’s reference architecture. The recipes, deployment instructions, and full benchmark results are all available inside the example section of the repository. Workload Examples Equally important, the repo contains some real world examples of E2E AI training -- including best practices for training jobs data preparation and execution. Currently, in the examples section, we introduced the Megatron-LM GPT175B and the LLM Foundry MPT-30B and MPT-70B case. The current examples are focused on the Azure CycleCloud Workspace for Slurm architecture, but there is the plan to extend them to additional orchestration solutions in the future. These guides allow interested users to configure sample distributed training jobs, relying on important configuration guidance for their environment and infrastructure. What’s next The repository presented in this blog post will be expanded with additional scenarios, best practices and configuration recipes. We will share periodically updates on new contents and evolution of what available in the catalog. We welcome contributions and we encourage to actively open requests for new content that you may find of interest. Thank you to all our readers!Deploying ZFS Scratch Storage for NVMe on Azure Kubernetes Service (AKS)
This guide demonstrates how to use ZFS LocalPV to efficiently manage the NVMe storage available on Azure NDv5 H100 VMs. Equipped with eight 3.5TB NVMe disks, these VMs are tailored for high-performance workloads like AI/ML and large-scale data processing. By combining the flexibility of AKS with the advanced storage capabilities of ZFS, you can dynamically provision stateful node-local volumes while aggregating NVMe disks for optimal performance.