reliability and resiliency in azure
29 Topics
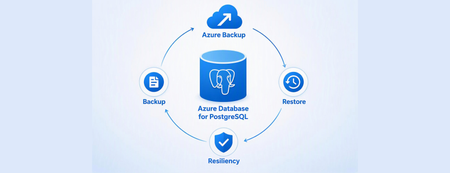
Azure Backup for PostgreSQL flexible server and elastic cluster (v2) is now in public preview
Azure Backup for PostgreSQL flexible servers and elastic clusters (v2) is now in public preview. Built on physical, snapshot-based backups, v2 brings scalable protection, flexible retention and streamlined recovery to PostgreSQL estates of all sizes. It helps customers improve data resiliency through vaulted backups and support compliance requirements with long-term retention of backups. Organizations can protect larger databases, back them up more frequently and restore them directly to a server when recovery is needed. What v2 can do V2 protects both Azure Database for PostgreSQL flexible servers and elastic clusters. It supports databases of up to 32 TB on Premium SSD v1 and up to 64 TB on Premium SSD v2, including production configurations with high availability, virtual network or private endpoint connectivity through Trusted Access, and Customer Managed Key encryption. You can schedule backups daily or weekly, with a recovery point objective goal of one day, and create on-demand backups whenever an additional recovery point is required. The first backup is full and subsequent backups are incremental, enabling a practical daily protection cadence even for multi-terabyte databases. Retention can range from 7 days to 10 years. Separate daily, weekly, monthly and yearly retention rules make it possible to align one policy with both operational recovery and long-term compliance requirements. Recovery points are stored in an Azure Backup vault and can use the platform protections organizations already rely on: Soft delete and WORM immutability to protect backups from premature deletion or alteration. Multi-user authorisation and MFA for sensitive operations. Customer Managed Key encryption and cross-subscription vaulting within the same tenant. Central monitoring and management through Backup center. Restore as Server Restore as Server turns a recovery point into a ready-to-use PostgreSQL environment by restoring it directly to a pre-created flexible server or elastic cluster. Unlike Restore as Files, which writes the backup to a storage container and requires a separate manual import into PostgreSQL, Restore as Server removes that intermediate phase. This reduces operational effort, shortens the path to application recovery and provides a more consistent restore experience at scale. How v2 improves on v1 V2 moves from logical exports to physical backups created from managed disk snapshots. This architectural change expands the service from the 1 TB limit in v1 to as much as 64 TB on supported storage, while incremental backups make daily schedules possible instead of limiting vaulted backups to a weekly full copy. The new solution also extends protection to elastic clusters and introduces direct restoration to a server. Together, these improvements provide broader workload coverage, more frequent recovery points and a simpler path from backup to a usable PostgreSQL environment. How to get started with v2 You can configure v2 in the Azure portal from a Backup vault, the Resiliency experience, or the LTR (Vaulted Backups) pane of the flexible server. Each entry point leads to the same policy and protection workflow. Before enabling protection, confirm that the server meets the preview requirements and check details on supported scenarios and limitations. Once eligibility is confirmed, create or select a Backup vault, define the schedule and retention rules that fit your recovery objectives, and enable protection for the server or elastic cluster. For PostgreSQL flexible server and elastic cluster vaulted backup v2 (preview), you incur charges from 15 October 2026. Refer to Azure Backup pricing page and pricing calculator for more details. How to migrate from v1 to v2 Existing protected items can be moved to v2 while retaining the same policy and Backup vault. The protected item and its existing recovery points are preserved, allowing organisations to adopt the new capabilities without losing backups already retained for operational or compliance needs. The migration is one way, so review readiness before starting. Servers running PostgreSQL 14 or earlier must first be upgraded to PostgreSQL 15 or later, and servers on the Burstable tier must be scaled to General Purpose or Memory Optimized. With those prerequisites complete, the move to v2 opens the way to larger-scale protection, daily incremental backups, elastic cluster coverage and direct server recovery—all while preserving the continuity of your existing backup estate.Azure Incident Retrospective - Please register! Session 2 - Tracking ID: SPCX-S1Z
Join our upcoming live webcast for a transparent discussion about this recent Azure service incident led by our engineering teams. Power issue in Southeast Asia Tracking ID: SPCX-S1Z | Impacted: 25-26 August 2026 Same content presented in both sessions: pick the one that works best for your timezone! What to expect 📚 Understand What happened, how we responded, and what we learned 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn The fixes we've put in place and guidance for workload resiliency Choose your session Same content presented at both times: pick the one that works best for your timezone: Session 1 15:30 UTC Thursday, 24 Sept 2026 Register now → Session 2 03:30 UTC Friday, 25 Sept 2026 Register now → 8:30 AM US Pacific (PDT) 11:30 AM US Eastern (EDT) 4:30 PM London (BST) 11:30 PM Beijing (CST) 1:30 AM +1 Sydney (AEDT) 3:30 AM +1 Auckland (NZDT) 8:30 PM -1 US Pacific (PDT) 11:30 PM -1 US Eastern (EDT) 4:30 AM London (BST) 11:30 AM Beijing (CST) 1:30 PM Sydney (AEDT) 3:30 PM Auckland (NZDT) Our engineering leaders Terry Lo Datacenter Operations Manager Southeast Asia Cloud+AI Engineering LinkedIn ↗ ⚠️ Prepare before the livestream Read the Post Incident Review (PIR) ahead of time so you can ask any follow up questions during the live Q&A Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program192Views0likes0CommentsAzure Incident Retrospective - Please register! Session 1 - Tracking ID: SPCX-S1Z
Join our upcoming live webcast for a transparent discussion about this recent Azure service incident led by our engineering teams. Power issue in Southeast Asia Tracking ID: SPCX-S1Z | Impacted: 25-26 August 2026 Same content presented in both sessions: pick the one that works best for your timezone! What to expect 📚 Understand What happened, how we responded, and what we learned 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn The fixes we've put in place and guidance for workload resiliency Choose your session Same content presented at both times: pick the one that works best for your timezone: Session 1 15:30 UTC Thursday, 24 Sept 2026 Register now → Session 2 03:30 UTC Friday, 25 Sept 2026 Register now → 8:30 AM US Pacific (PDT) 11:30 AM US Eastern (EDT) 4:30 PM London (BST) 11:30 PM Beijing (CST) 1:30 AM +1 Sydney (AEDT) 3:30 AM +1 Auckland (NZDT) 8:30 PM -1 US Pacific (PDT) 11:30 PM -1 US Eastern (EDT) 4:30 AM London (BST) 11:30 AM Beijing (CST) 1:30 PM Sydney (AEDT) 3:30 PM Auckland (NZDT) Our engineering leaders Terry Lo Datacenter Operations Manager Southeast Asia Cloud+AI Engineering LinkedIn ↗ ⚠️ Prepare before the livestream Read the Post Incident Review (PIR) ahead of time so you can ask any follow up questions during the live Q&A Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program161Views0likes0CommentsAzure Retirements Livestream - Please register! Session 2 - Tracking ID: 0P59-60Z
Join our upcoming live webcast for a transparent discussion about this upcoming Azure retirement — led by our engineering teams. Network Security Group (NSG) flow logs in Azure Network Watcher Tracking ID: 0P59-60Z | Retirement Date: 30 September 2027 Same content presented in both sessions — pick the one that works best for your timezone! What to expect 📚 Understand What will happen, the timelines for the change, and how you can manage it 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn How to manage the change smoothly Choose your session Same content presented at both times — pick the one that works best for your timezone: Session 1 16:30 UTC Thursday, 24 Sept 2026 Register now → Session 2 04:30 UTC Friday, 25 Sept 2026 Register now → 9:30 AM US Pacific (PDT) 12:30 PM US Eastern (EDT) 5:30 PM London (BST) 12:30 AM +1 Beijing (CST) 2:30 AM +1 Sydney (AEDT) 4:30 AM +1 Auckland (NZDT) 9:30 PM -1 US Pacific (PDT) 12:30 AM US Eastern (EDT) 5:30 AM London (BST) 12:30 PM Beijing (CST) 2:30 PM Sydney (AEDT) 4:30 PM Auckland (NZDT) Our engineering leaders Chaithanya Rai Senior Product Manager Azure Network Security & Observability LinkedIn ↗ Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program150Views0likes0CommentsAzure Retirements Livestream - Please register! Session 1 - Tracking ID: 0P59-60Z
Join our upcoming live webcast for a transparent discussion about this upcoming Azure retirement — led by our engineering teams. Network Security Group (NSG) flow logs in Azure Network Watcher Tracking ID: 0P59-60Z | Retirement Date: 30 September 2027 Same content presented in both sessions — pick the one that works best for your timezone! What to expect 📚 Understand What will happen, the timelines for the change, and how you can manage it 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn How to manage the change smoothly Choose your session Same content presented at both times — pick the one that works best for your timezone: Session 1 16:30 UTC Thursday, 24 Sept 2026 Register now → Session 2 04:30 UTC Friday, 25 Sept 2026 Register now → 9:30 AM US Pacific (PDT) 12:30 PM US Eastern (EDT) 5:30 PM London (BST) 12:30 AM +1 Beijing (CST) 2:30 AM +1 Sydney (AEDT) 4:30 AM +1 Auckland (NZDT) 9:30 PM -1 US Pacific (PDT) 12:30 AM US Eastern (EDT) 5:30 AM London (BST) 12:30 PM Beijing (CST) 2:30 PM Sydney (AEDT) 4:30 PM Auckland (NZDT) Our engineering leaders Chaithanya Rai Senior Product Manager Azure Network Security & Observability LinkedIn ↗ Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program146Views0likes0CommentsChoosing two-zone and three-zone patterns for zone-resilient Azure workloads
This article complements our Advancing Reliability series post, Two zones or three? A design framework for zone-resilient Azure workloads. Together, they provide guidance on both the considerations and deployment patterns for zone-resilient Azure workloads. Purpose This article helps customers evaluate Azure workload components and choose zone-resilient patterns that meet their requirements during a single-zone failure. The goal is to identify where two zones can meet workload requirements, where three zones are required, and where service-managed zone redundancy is the right approach. Important: This guidance is a decision framework, not a service support matrix. Availability zone behavior varies by Azure service, SKU, tier, region, and configuration. Always validate the selected design against the relevant Azure reliability guidance and test the workload's actual failure behavior before finalizing the architecture. Zone resiliency helps protect against the loss of a single availability zone. It does not protect against a full-region outage. For mission-critical workloads or workloads with strict disaster recovery requirements, evaluate whether the workload also requires a multi-region design. Availability zones are separate groups of datacenters within an Azure region. Each availability zone has independent power, cooling, and networking infrastructure. Azure services that support availability zones generally expose support through zone-redundant or zonal deployment models. Key takeaways Evaluate zone patterns at the workload component level, not only at the whole-workload level. Many workloads can meet single-zone failure objectives by using two zones for some components and three zones only where component requirements demand them. For the single-zone failure mode, two-zone and three-zone patterns can both meet resource availability objectives when remaining capacity and failover behavior are validated. Use service-managed zone redundancy when it meets workload requirements. Use two zones when the component can meet its availability, durability, capacity, performance, and operational requirements across two zones. Use three zones when a component requires the additional zone for post-failure capacity, data durability, replication topology, quorum, leader election, or operational margin. Balance cost and operational complexity after defining the workload's resiliency objective. Do not assume that two zones are always cheaper or that three zones are always required. Zone-redundant and zonal deployment models Zone-resilient designs depend on the deployment model used by each Azure service. Zone-redundant resources are distributed or replicated across multiple availability zones. Azure manages replication, request distribution, and failover behavior for the service. Where available and aligned to workload requirements, zone-redundant resources should be preferred, especially for production deployments. Zonal resources are pinned to a specific availability zone. A zonal resource is isolated from failures in other zones, but it is not automatically resilient to a failure in its own zone. To make a zonal service resilient, customers need to deploy separate instances across multiple zones and design the workload to route traffic, replicate data, detect failures, and recover. Some Azure services offer both zonal and zone-redundant deployment options, while others may be zone-resilient by default. In some cases, availability zone support requires additional configuration, service modification, or redeployment. Support can also vary by region, SKU, tier, or service configuration. Before choosing a deployment model, review the service-specific reliability guidance and availability zone support matrix to understand the options and requirements for your scenario. Primary decision dimensions Current Azure Well-Architected guidance emphasizes deploying production workloads across two or more failure domains to improve resiliency to failures within a single failure domain. In Azure regions that support availability zones, those failure domains are exposed as availability zone boundaries. When deciding whether a component should use two zones, three zones, or service-managed zone redundancy, evaluate three dimensions: Resource availability: For the single-zone failure mode, two-zone and three-zone patterns can both meet resource availability objectives when the remaining zone or zones can support the required operating state and failover behavior. The additional zone in a three-zone design does not by itself make the component resilient to more than one zone failure within the same region. Data consistency and durability: Stateful components might require three zones when data durability, replication topology, quorum, consensus, leader election, or split-brain prevention depends on a third failure domain or third replica placement. Cost and capacity: For the same post-failure performance target, a two-zone design can require more recovery capacity than a three-zone design. Cost optimization should be evaluated after the resiliency objective is defined. If more than one availability zone is unavailable in the same region, the concern can become regional rather than only workload-specific because foundational regional services require at least two surviving availability zones for continued regional availability. Workloads with requirements beyond a single-zone failure should evaluate disaster recovery or multi-region design separately. Common workload components can be grouped as follows: Component category Typical zone decision Stateless resources that support networking or application code and do not store persistent data Two-zone or three-zone flexibility, based on remaining capacity, routing, latency, and operational requirements. Stateful resources that use node-based quorum, consensus, or leader election Three zones, a third failure domain, or a product-specific witness pattern is commonly required to avoid split-brain or quorum-loss scenarios. Critical data stores that require three replicas for the highest durability targets Three-zone replication might be required to support the intended durability level, such as eleven-nines-style durability targets. Validate service-specific claims. Other stateful resources Two-zone, three-zone, or service-managed patterns can be valid depending on service behavior, recovery time objective (RTO), recovery point objective (RPO), durability, failover, and recovery requirements. Component-level decision framework Walk through the workload by critical flow and component. For each component, determine whether service-managed zone redundancy applies, whether a two-zone pattern can meet the component's single-zone failure objective, or whether three zones are required. Component question What to evaluate Decision guidance Is zone resiliency managed by the Azure service? Confirm whether the service provides zone-redundant or zone-resilient behavior through a supported configuration, SKU, tier, or replication mode. Use service-managed zone redundancy when it meets workload requirements. Do not force a two-zone or three-zone customer-managed design onto services where Azure manages placement and failover internally. Is the component stateless or easily replaceable? Evaluate routing, health probes, scale-out behavior, post-failure capacity, deployment automation, monitoring, and recovery steps. Two zones can often meet requirements for stateless or easily replaceable components when the remaining zone can support the required degraded or full operating state. Use three zones when capacity distribution or operational requirements justify the added design and testing scope. Does the component store durable state? Evaluate replication mode, data durability, consistency, RTO, RPO, failover behavior, recovery behavior, and service-specific support. Use the pattern that satisfies the data protection and recovery requirements. Three zones might be required when the storage or data service requires an additional zone for durability, triple-replica placement, replication topology, or recovery behavior. Does the component use quorum, consensus, or leader election? Validate replica placement, majority behavior, witness or tie-breaker design, leader election, split-brain prevention, recovery, and failback. Do not assume that three replicas across two zones are sufficient. Three zones, a third failure domain, or a product-specific witness pattern might be required to tolerate a zone loss safely. Is the component latency-sensitive? Define latency and throughput thresholds, test candidate zone pairs with realistic protocols and configuration, and identify which paths are actually latency-sensitive. Two zones can be appropriate for latency-sensitive synchronous paths that use tested placement. Logical zone numbers can map to different physical zones across subscriptions, so validate zone mapping when selected zone pairs matter. What capacity must remain after one zone fails? Define the required post-failure operating state for the component: degraded but acceptable, full baseline, or standby recovery. Choose the zone pattern that can satisfy the required post-failure operating state. Two zones can meet requirements when each remaining zone has enough capacity for the target state. Three zones can reduce the capacity each zone must carry for the same post-failure target. How will the design be operated and reviewed? Assign owners for monitoring, testing, incident response, failover, failback, and periodic reassessment. Confirm that identity, network security, encryption, secrets management, policy, monitoring, and data protection requirements are preserved. Document why each component uses service-managed zone redundancy, two zones, or three zones. If three zones are required for a component, state the requirement that drives that decision. Where two zones can meet requirements A two-zone pattern can be a practical way to meet single-zone failure objectives when the component's requirements are satisfied across two zones. Common examples include: Stateless compute, application, or network components where traffic can be routed to the remaining zone. Pairwise active-passive or active-active designs that are simpler to deploy, test, and operate across two zones. Latency-sensitive synchronous paths where a tested zone pair meets performance requirements. Customer-managed zonal resources where the remaining capacity, failover process, monitoring, recovery, and failback behavior are validated. Components whose acceptable degraded operating state can be supported after one zone is unavailable. The design should define what happens after one zone is unavailable, including remaining capacity, acceptable degradation, data consistency, failover behavior, recovery steps, observability, and operational ownership. Where three zones are required Three zones are required when two zones cannot meet the component's requirements during or after a single-zone failure. Examples include: A required post-failure operating state that cannot be supported by the remaining zone in a two-zone design. Data durability or replication requirements that depend on placement across three zones, such as triple-replica placement for the highest durability targets. Quorum, consensus, or leader-election designs that require a third failure domain or witness placement to avoid losing quorum or creating split-brain risk. Three zones still primarily help a workload tolerate a single availability-zone failure within a region. When this guidance refers to an additional failure domain, it means an additional Azure availability-zone placement option or an application-level failure domain needed by a specific component design, such as quorum, witness, or leader-election behavior. Where three zones may add value Some components do not strictly require three zones but can benefit from the additional placement option. In these cases, the value is usually related to capacity distribution, maintenance flexibility, or operational margin, not a different single-zone availability failure mode. Use three zones when the additional zone helps the component meet the required post-failure operating state, reduces how much capacity each zone must carry, or improves the ability to maintain and recover the component without violating workload requirements. Data consistency and durability considerations Stateful components should be evaluated based on consistency, replication, quorum, durability, RTO, and RPO requirements. Some distributed systems use quorum, leader election, or consensus-based coordination to maintain consistent state. Three zones are not universally required for every quorum-based architecture, but quorum-based systems require careful validation. Replica count alone is not enough. Replica placement, majority behavior, witness or tie-breaker placement, leader election, write consistency, split-brain prevention, recovery behavior, and failure-domain assumptions all affect whether a two-zone or three-zone deployment is appropriate. Some systems can place three or more replicas across two zones, and some managed services provide zone-resilient behavior without exposing direct customer control over zone placement. These patterns should not be generalized. In customer-managed majority-quorum systems, placing replicas across only two failure domains can still lose quorum if the majority-holding zone is unavailable. A third failure domain, witness, or tie-breaker might be required to tolerate a zone loss safely, depending on the product architecture. For customer-managed stateful systems, validate replica count and placement, quorum behavior, leader election behavior, synchronous and asynchronous replication, split-brain prevention, failure recovery behavior, data durability requirements, and RTO and RPO objectives. For managed data services, understand how the service implements zone resiliency, which configuration choices are available, and how the service behaves during zone-down scenarios. Capacity planning for a single-zone failure Capacity planning should start with the component's required operating state after the loss of one availability zone. Determine the capacity required to support the component in an approved degraded resiliency state, then use that post-failure target to compare zone patterns. For active-active deployments, use: Total Capacity = Target Remaining Capacity x Z / (Z - 1) In this formula: Target Remaining Capacity is the capacity the component must have after one zone is unavailable. Z is the number of zones used by the component. For example, if a component requires 100 units of baseline capacity and can operate at an approved degraded level of at least 80 units after losing one zone, the model estimates: Deployment model Formula Total provisioned capacity Capacity per zone Remaining after one zone loss Two availability zones 80 x 2 / (2 - 1) 160 units 80 units 80 units Three availability zones 80 x 3 / (3 - 1) 120 units 40 units 80 units This example compares designs against the same post-failure operating objective. The acceptable degraded state should be explicitly defined, tested, and approved. It should include the minimum remaining capacity, expected throttling or prioritization behavior, scale-out assumptions, and how long the component can remain in the degraded state. If the component must maintain full baseline capacity after one zone is unavailable, use the full baseline capacity as the target remaining capacity. Capacity requirements depend on workload architecture, scaling behavior, service limits, failover behavior, and acceptable degradation. Cost and operational considerations Cost and operational complexity should be evaluated after the resiliency objective is defined. They should not be used to dismiss two-zone designs that can meet component requirements, and they should not be used to justify two-zone designs that do not meet requirements. For the same post-failure capacity target, a three-zone design can require less total provisioned capacity than a two-zone design because the recovery capacity is distributed across more zones. Use the capacity model to understand that tradeoff before optimizing costs. For workloads with predictable usage, evaluate commitment-based discounts such as Azure savings plans or Azure reservations where they apply to the selected services. Operationally, consider whether the selected pattern can be deployed, monitored, tested, failed over, recovered, and reviewed consistently. A two-zone pattern can be simpler for pairwise designs. A three-zone pattern can provide more operational margin for components that benefit from additional placement options. Component classification workflow Before finalizing the zone pattern, confirm that: Each critical flow is decomposed into the components that support it. Each component is evaluated across resource availability, data consistency and durability, and cost or capacity impact. Each component is classified as service-managed zone-redundant, two-zone customer-managed, or three-zone required. The reason for requiring three zones is documented when two zones do not meet the component objective. Each Azure service's zone support, SKU, tier, region, and configuration requirements are validated. Customer-managed zonal resources have validated routing, load balancing, replication, failover, monitoring, recovery, and failback. Remaining capacity and acceptable degradation after one zone loss are documented. Stateful or quorum-based components have validated replica placement, witness or tie-breaker behavior, leader election, and split-brain prevention. Latency-sensitive paths have been tested across the selected zone placement. Security, identity, monitoring, and data protection requirements are preserved. Ownership for testing, incident response, failover, failback, and periodic reassessment is assigned. Related public guidance Azure services that support availability zones Enable zone resiliency for Azure workloads Zonal resources and zone resiliency What are Azure availability zones Architecture strategies for availability zones and regionsAnnouncing the resiliency agent in Azure Copilot, now in public preview
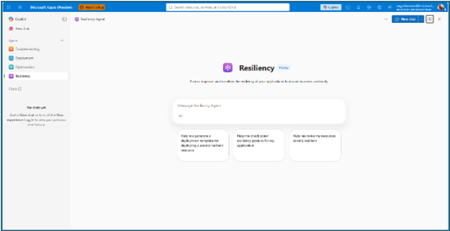
The distance between knowing and doing Most teams already know that zonal resiliency matters. What slows them down is everything in between: assessing posture across subscriptions and regions, deciding which gaps should be prioritized, writing the templates, and confirming the change actually rolled out. That is four separate workstreams, in four separate places, usually picked up long after the application is shipped. The resiliency agent closes that distance. We’re excited to announce that it is now available in public preview as part of the agents in Azure Copilot. The agent brings resiliency assessment, prioritized recommendations, and deployment-ready code into a single conversation, so resiliency becomes something your team does continuously rather than something you audit once a year. Learn more about Azure Copilot agents here. What the resiliency agent does The Resiliency agent is the conversational, action-oriented layer of Azure Infrastructure Resiliency Manager. The platform gives you a goal-driven view of your resiliency posture, and the agent lets you act on that posture in plain language. It brings together the signals you would otherwise chase manually across availability zones, Azure Backup, Azure Site Recovery, service level indicators, and Azure health models, then turns them into workload-aware guidance you can execute. Starting with zonal resiliency, it is designed to complement the resiliency capabilities you already rely on rather than replace them. The agent is built on the same foundational belief as Azure Infrastructure Resiliency Manager: application resiliency is a continuous journey, not a one-time task. That journey runs in three phases: Start Resilient Get Resilient Stay Resilient. This public preview addresses the activities associated with first two phases, frontloading the capabilities customers asked for most: direct remediation, Infrastructure as Code integration, and cost visibility. Stay Resilient comes next. What you can do in public preview Generate deployment-ready Bicep and Terraform with zone-redundant settings already enabled, before your first deployment Find the service groups and resources that are not zone resilient across your subscriptions and regions Prioritize remediation with cost-aware indicators that flag whether a fix needs extra spend, downtime, or redeployment Generate ready-to-deploy scripts to configure zone resiliency for supported resource types Create and update service groups so your applications are modeled correctly from the start Start resilient: build it in from the first line of code The most durable resiliency is the kind you never have to retrofit. Starting resilient means treating zone resiliency as an architectural requirement on day one, and the Resiliency Agent makes that the path of least resistance. Describe the application you are building, and the agent helps you generate deployment-ready Infrastructure as Code with the recommended resiliency configurations already enabled at creation time. Ask for a Bicep or Terraform template for a new workload and the agent returns one with zone-redundant settings pre-built for your databases, VMs, and load balancers, aligned to the goals you set. For example, try prompts like: “Generate a Bicep template for a zonally resilient VM setup.” “Create Terraform templates for a resilient architecture with VMs, AKS, and Storage.” The payoff: new services reach production already meeting your high availability standards, and the expensive redesign never has to happen. Get resilient: close the gaps in what you already run Applications change. The configuration that was right at first deployment is often not the one a business-critical workload needs two years later. This is where the resiliency agent turns posture insight into prioritized, executable action. Ask the agent to assess your environment, and it surfaces the resources and service groups that are not zone resilient, that are exposed to a datacenter outage, or that have key alerts waiting on attention. Every recommendation carries cost-aware decision support, qualitative indicators that flag whether a fix requires additional spend, downtime, or redeployment, so your team can sequence remediation against business value instead of guesswork. When you are ready to act, the agent generates ready-to-deploy scripts to configure zone resiliency for supported resource types, or targeted IaC snippets to close one specific gap. Try prompts like: “Assign resiliency goals for my application.” “Give me the posture of my service group: Contoso Payments.” “Enable zonal resiliency for my PostgreSQL server.” “Generate scripts to create a zonally resilient storage account.” This is a human-in-the-loop model by design. The agent brings the analysis, the recommendations, and the code. You keep full control over execution. Remediation gets faster without giving up governance. Stay resilient: what comes next Resiliency is not only about withstanding a zone outage. It is about protecting your data and knowing you can recover when something does go wrong. Recovery orchestration plans and zone drills are available today in Azure Infrastructure Resiliency Manager, and we are bringing both into the agent experience next. That closes the loop: assess, remediate, and validate recovery readiness in the same conversation. Get started with the public preview Open Azure Copilot and select the Resiliency Agent from the dropdown or the side panel. Three actions will get you value in the first session. Model your application. The agent works from your application, not a flat list of resources, so make sure it is represented as a service group that reflects your latest resource discovery. You can create service groups natively through the agent. Try: “Create a service group for my application.” Find your gaps. Ask which of your service groups and resources are not zone resilient. Most teams uncover exposure that was previously invisible. See Set resiliency goals and track compliance. Design it in. Ask for a Bicep template with zone-redundant defaults for a workload you plan to deploy and see how much retrofit effort disappears. See Generate resilient Bicep templates. What to expect in the preview Ready-to-deploy zone resiliency scripts are supported for Azure services that have zonal resiliency support in Infrastructure Resiliency Manager. See the support matrix for current coverage. Some advanced configurations, including multi-user authorization and Azure Site Recovery, may require manual steps, and the agent provides guidance to help you complete them. Where we are going This public preview is a starting line, not a finish. We are building toward end-to-end, agent-led journeys across Start, Get, and Stay Resilient, with cross-agent orchestration that reaches into migration, deployment, and observability, and multi-surface delivery so resiliency validation shows up in your IDEs, APIs, and CI/CD pipelines, not only in Azure Copilot. Service coverage will keep expanding, and the guidance will keep getting richer. The goal is simple and ambitious: make resilient-by-design the path of least resistance for every application on Azure. Preview is where that gets shaped, so tell us what is working and what you need next at azureresiliency@microsoft.com. Start here: open Azure Copilot, select the resiliency agent, and ask which of your applications are not zone resilient yet. Resources Announcing Azure Infrastructure Resiliency Manager public preview Agents in Azure Copilot public preview Resiliency capabilities in Agents (preview) in Azure Copilot, Azure Infrastructure Resiliency Manager overview Get started with service groups Microsoft Learn Questions or feedback: azureresiliency@microsoft.comSimpler, private connectivity between Azure and AWS with Azure Multicloud Interconnect
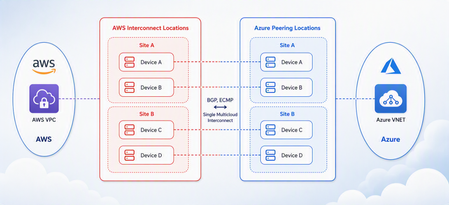
Multicloud is no longer the exception — it is how most enterprises operate. Teams run analytics in one cloud and applications in another, place workloads to meet data-residency requirements, and increasingly move large volumes of data between clouds to train and serve AI models. Yet the network that connects these environments has remained one of the hardest parts of a multicloud strategy to get right. Connecting Azure and AWS privately has traditionally meant stitching together Azure ExpressRoute, AWS Direct Connect, a connectivity provider or colocation footprint, customer-managed routers, BGP sessions, and link-layer encryption — then owning the resiliency design and day-to-day operations across all of it. The result is often slow to deliver, difficult to troubleshoot, and inconsistent in performance. Today, Microsoft and AWS are together introducing Azure Multicloud Interconnect, a jointly engineered, fully managed service that delivers private, high-throughput connectivity between Azure and AWS through a single logical resource. Both clouds coordinate provisioning, resiliency, encryption, and lifecycle operations, so the connection between your environments simply works — end to end. The challenge with connecting clouds today For most organizations, cross-cloud connectivity has been a build-it-yourself exercise. Establishing a private link between Azure and AWS typically requires provisioning an ExpressRoute circuit on one side and a Direct Connect circuit on the other, engaging a connectivity provider or securing space in a colocation facility to bridge them, and then configuring and maintaining the routers, BGP peering, and encryption that tie the two clouds together. Each of those pieces is owned by a different team or vendor, which makes the end-to-end path only as reliable as its least-managed component. When something breaks, isolating the root cause means coordinating across Microsoft, AWS, a network provider, and your own operations team — and mean time to resolution suffers as a result. Capacity planning is equally difficult: bandwidth is often provisioned for peak demand and left underused, while scaling up to meet a new AI or data initiative can take weeks. The outcome is a connectivity layer that is slow to stand up, expensive to operate, and hard to reason about — exactly the opposite of what a multicloud strategy is meant to deliver. Azure Multicloud Interconnect removes that complexity by turning cross-cloud connectivity into a managed service. What is Azure Multicloud Interconnect? Azure Multicloud Interconnect is a provider-managed, private intercloud connectivity service built on the proven foundations of Azure ExpressRoute and AWS Direct Connect. Instead of assembling and operating the underlying components yourself, you establish one interconnect resource and consume a private, dedicated path between your Azure and AWS environments. Under the covers, Microsoft and AWS coordinate the circuits, routing, and encryption on your behalf. You get the outcome you want — a reliable private connection between clouds — without becoming the systems integrator for it. Because the service builds on ExpressRoute and Direct Connect, it fits naturally into the connectivity models, tooling, and operational practices your teams already use in each cloud. One managed resource replaces a stack of circuits, routers, BGP sessions, and encryption you would otherwise build and operate yourself. Figure 1. Azure Multicloud Interconnect provides a single, managed private path between Azure and AWS, built on ExpressRoute and Direct Connect with a quad-redundant, 400G-class design and MACsec encryption. How it works Azure Multicloud Interconnect is engineered for the performance and availability that production and AI-scale workloads demand: A single logical connection. You provision and manage one interconnect resource. There are no customer-owned routers to rack, configure, or patch between the clouds. Quad-redundant, multi-site design. The data path is built across redundant devices and diverse sites — four Azure Microsoft Enterprise Edge (MSEE) routers and four AWS routers — so there is no single point of failure. High bandwidth backbone. A high-capacity LAG-based design provides the headroom needed for large-scale data movement and distributed AI traffic. Elastic bandwidth. Scale capacity up or down as demand changes, rather than provisioning for peak and paying for it year-round. Encryption by default. MACsec link-layer encryption is enabled automatically, so traffic between clouds is protected without extra configuration. Enterprise-ready networking. The service is IPv6-ready, supports APIPA addressing, and targets a 99.99% availability SLA. Routing and provisioning are coordinated by the platform, which removes the most common sources of cross-cloud connectivity errors — mismatched BGP configuration, inconsistent encryption settings, and asymmetric or fragile failover paths. A foundation you can trust Azure Multicloud Interconnect is not a new, unproven path — it extends two connectivity services that enterprises already rely on: Azure ExpressRoute and AWS Direct Connect. Both are private connectivity backbones trusted for mission-critical hybrid and cloud workloads, and the interconnect inherits their carrier-grade capacity, global edge presence, and operational maturity from day one. It also means your teams do not have to learn a separate model. The interconnect appears as a first-class resource governed by the identity, access, and monitoring controls each cloud already provides, and it can be automated with the tooling you use today. Extending trusted services, rather than introducing a parallel one, is what allows Microsoft and AWS to offer intercloud connectivity as a managed experience with confidence. Why this matters for your team Azure Multicloud Interconnect is designed to change the economics and the experience of running across clouds. Taken together, these benefits shift cross-cloud networking from a specialized, high-effort project to a repeatable, on-demand capability. Instead of dedicating senior engineers to build and babysit intercloud links, your team can direct that expertise toward the applications and data platforms that differentiate your business — while trusting that the connective tissue between clouds is reliable, secure, and ready to scale. Faster time to value. Turn up private Azure–AWS connectivity through a guided, managed workflow instead of a multi-week integration project spanning several vendors. Lower operational burden. Microsoft manages the infrastructure, resiliency, and lifecycle, so your networking team is freed from patching routers and diagnosing cross-cloud faults. Predictable, high performance. A dedicated, private path with high capacity that delivers the consistent throughput and low latency that public-internet or VPN paths cannot guarantee. Security you don’t have to assemble. Private connectivity plus default MACsec encryption keeps intercloud traffic off the public internet and protected in transit. A consistent experience in both clouds. Provision, monitor, and manage the interconnect using the native constructs and tooling your teams already rely on in Azure and AWS alike. Built for the way enterprises use multicloud “I've heard a very consistent message across many years of customer engagements - we are multi-cloud enterprise by design. With this announcement we are taking a burden on connecting clouds away from the customers." Igor Sakhnov, CVP Azure Networking Customers have told us where dedicated, managed intercloud connectivity makes the biggest difference. Azure Multicloud Interconnect is designed for scenarios such as: Distributed AI workloads. Move training data and model outputs between clouds at high throughput to feed pipelines wherever the compute lives. Large-scale data movement. Replicate datasets, back up across clouds, and support analytics that span Azure and AWS. Cross-cloud disaster recovery. Use a second cloud as a resilient recovery target over a private, reliable link. Hybrid and best-of-breed architectures. Run each application on the cloud that suits it best while keeping the connection between them private and performant. Regulated and sovereign workloads. Keep intercloud traffic on a private path to help meet data-residency and compliance requirements. Workload migration. Rehost or rebalance workloads between clouds without re-engineering connectivity for each move. Availability and what’s next Azure Multicloud Interconnect is launching first for Azure and AWS connectivity, the pairing customers ask about most often. Microsoft and AWS are starting with a preview so that you can validate the experience against your own architectures, with general availability to follow. This is the beginning of a broader journey. Building on existing multicloud connectivity capabilities, we plan to extend the managed interconnect model to additional clouds — including Google Cloud (coming soon)— so that a consistent, provider-managed experience can span your entire multicloud estate. As always, the roadmap will be guided by customer demand and real-world use. Our shared goal is simple: make the network the easiest part of your multicloud strategy, not the hardest. By delivering intercloud connectivity as a managed service, Microsoft and AWS want every organization — from a team moving its first dataset between clouds to an enterprise operating at AI scale — to connect Azure and AWS privately, securely, and with confidence, and to do it in minutes rather than months. Get started Learn more about Azure Multicloud Interconnect, Azure ExpressRoute, and AWS Direct Connect from Microsoft and AWS documentation, talk with your Microsoft or AWS account team about joining the preview, and tell us which cloud pairings and scenarios matter most for your organization. We are building this with your feedback. Azure Multicloud Interconnect is jointly delivered by Microsoft and AWS, built on Azure ExpressRoute and AWS Direct Connect. Feature availability, performance targets, and timelines may evolve as the service moves from preview to general availability.6.1KViews3likes0CommentsAzure Incident Retrospective - Please register! Session 2 - Tracking ID: ZJV6-SGG-BW8
Join our upcoming live webcast for a transparent discussion about this recent Azure service incident led by our engineering teams. Network connectivity issues in West US Tracking ID: ZJV6-SGG | Impacted: 23 July 2026 Same content presented in both sessions: pick the one that works best for your timezone! What to expect 📚 Understand What happened, how we responded, and what we learned 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn The fixes we've put in place and guidance for workload resiliency Choose your session Same content presented at both times: pick the one that works best for your timezone: Session 1 17:30 UTC Thursday, 27 Aug 2026 Register now → Session 2 05:30 UTC Friday, 28 Aug 2026 Register now → 10:30 AM US Pacific (PDT) 1:30 PM US Eastern (EDT) 6:30 PM London (BST) 1:30 AM +1 Beijing (CST) 3:30 AM +1 Sydney (AEDT) 5:30 AM +1 Auckland (NZDT) 10:30 PM -1 US Pacific (PDT) 1:30 AM US Eastern (EDT) 6:30 AM London (BST) 1:30 PM Beijing (CST) 3:30 PM Sydney (AEDT) 5:30 PM Auckland (NZDT) Our engineering leaders Jamie Gaudette Vice President Azure Networking Cloud+AI Engineering LinkedIn ↗ ⚠️ Prepare before the livestream Read the Post Incident Review (PIR) ahead of time so you can ask any follow up questions during the live Q&A Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program242Views0likes0CommentsAzure Incident Retrospective - Please register! Session 1 - Tracking ID: ZJV6-SGG-BW8
Join our upcoming live webcast for a transparent discussion about this recent Azure service incident led by our engineering teams. Network connectivity issues in West US Tracking ID: ZJV6-SGG | Impacted: 23 July 2026 Same content presented in both sessions: pick the one that works best for your timezone! What to expect 📚 Understand What happened, how we responded, and what we learned 💬 Ask Live Q&A with our engineering experts throughout the session 🛠 Learn The fixes we've put in place and guidance for workload resiliency Choose your session Same content presented at both times: pick the one that works best for your timezone: Session 1 17:30 UTC Thursday, 27 Aug 2026 Register now → Session 2 05:30 UTC Friday, 28 Aug 2026 Register now → 10:30 AM US Pacific (PDT) 1:30 PM US Eastern (EDT) 6:30 PM London (BST) 1:30 AM +1 Beijing (CST) 3:30 AM +1 Sydney (AEDT) 5:30 AM +1 Auckland (NZDT) 10:30 PM -1 US Pacific (PDT) 1:30 AM US Eastern (EDT) 6:30 AM London (BST) 1:30 PM Beijing (CST) 3:30 PM Sydney (AEDT) 5:30 PM Auckland (NZDT) Our engineering leaders Jamie Gaudette Vice President Azure Networking Cloud+AI Engineering LinkedIn ↗ ⚠️ Prepare before the livestream Read the Post Incident Review (PIR) ahead of time so you can ask any follow up questions during the live Q&A Helpful resources 🔔 Azure Service Health Alerts Get alerts for relevant incidents by setting up notifications via email, SMS, or webhook 🎥 Past Retrospective Recordings Watch recordings of previous retrospective livestreams 📄 Azure Post Incident Reviews Learn more about PIRs and the retrospective program237Views1like0Comments