rag
59 TopicsMicrosoft Build 2024: Essential Guide for AI Developers at Startups and Cloud-First Companies
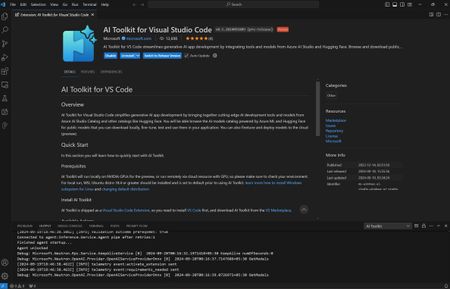
Generative AI is advancing fast, with OpenAI’s GPT-4o leading the way. GPT-4o boasts improved multilingual understanding, faster responses, lower costs, and real-time processing of text, audio, and images. This boosts new Generative AI (GenAI) use cases. Explore cutting-edge solutions like models, frameworks, vector databases, and LLM observability platforms. Born-in-the-cloud companies are at the forefront of this AI revolution. Be part of the future at Microsoft Build 2024!Building Retrieval Augmented Generation on VSCode & AI Toolkit
LLMs usually have limited knowledge about specific domains. Retrieval Augmented Generation (RAG) helps LLMs be more accurate and give relevant output to specific domains and datasets. We will see how we can do this for local models using AI Toolkit,
The Future of Agentic AI: Inside Microsoft Agent Framework 1.0
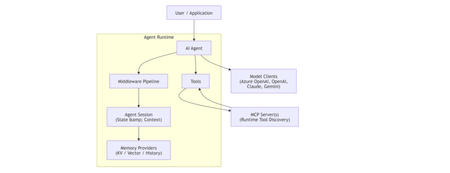
Agentic AI is rapidly moving beyond demos and chatbots toward long‑running, autonomous systems that reason, call tools, collaborate with other agents, and operate reliably in production. On April 3, 2026, Microsoft marked a major milestone with the General Availability (GA) release of Microsoft Agent Framework 1.0, a production‑ready, open‑source framework for building agents and multi‑agent workflows in.NET and Python. [techcommun...rosoft.com] In this post, we’ll deep‑dive into: What Microsoft Agent Framework actually is Its core architecture and design principles What’s new in version 1.0 How it differs from other agent frameworks When and how to use it—with real code examples What Is Microsoft Agent Framework? According to the official announcement, Microsoft Agent Framework is an open‑source SDK and runtime for building AI agents and multi‑agent workflows with strong enterprise foundations. Agent Framework provides two primary capability categories: 1. Agents Agents are long‑lived runtime components that: Use LLMs to interpret inputs Call tools and MCP servers Maintain session state Generate responses They are not just prompt wrappers, but stateful execution units. 2. Workflows Workflows are graph‑based orchestration engines that: Connect agents and functions Enforce execution order Support checkpointing and human‑in‑the‑loop scenarios This leads to a clean separation of responsibilities: Concern Handled By Reasoning & interpretation Agent Execution policy & control flow Workflow This separation is a foundational design decision. High‑Level Architecture From the official overview, Agent Framework is composed of several core building blocks: Model clients (chat completions & responses) Agent sessions (state & conversation management) Context providers (memory and retrieval) Middleware pipeline (interception, filtering, telemetry) MCP clients (tool discovery and invocation) Workflow engine (graph‑based orchestration) Conceptual Flow 🌟 What’s New in Version 1.0 Version 1.0 marks the transition from "Release Candidate" to "General Availability" (GA). Production-Ready Stability: Unlike the earlier experimental packages, 1.0 offers stable APIs, versioned releases, and a commitment to long-term support (LTS). A2A Protocol (Agent-to-Agent): A new structured messaging protocol that allows agents to communicate across different runtimes. For example, an agent built in Python can seamlessly coordinate with an agent running in a .NET environment. MCP (Model Context Protocol) Support: Full integration with the Model Context Protocol, enabling agents to dynamically discover and invoke external tools and data sources without manual integration code. Multi-Agent Orchestration Patterns: Stable implementations of complex patterns, including: Sequential: Linear handoffs between specialized agents. Group Chat: Collaborative reasoning where agents discuss and solve problems. Magentic-One: A sophisticated pattern for task-oriented reasoning and planning. Middleware Pipeline: The new middleware architecture lets you inject logic into the agent's execution loop without modifying the core prompts. This is essential for Responsible AI (RAI), allowing you to add content safety filters, logging, and compliance checks globally. DevUI Debugger: A browser-based local debugger that provides a real-time visual representation of agent message flows, tool calls, and state changes. Code Examples Creating a Simple Agent (C#) From Microsoft Learn : using Azure.AI.Projects; using Azure.Identity; using Microsoft.Agents.AI; AIAgent agent = new AIProjectClient( new Uri("https://your-foundry-service.services.ai.azure.com/api/projects/your-project"), new AzureCliCredential()) .AsAIAgent( model: "gpt-5.4-mini", instructions: "You are a friendly assistant. Keep your answers brief."); Console.WriteLine(await agent.RunAsync("What is the largest city in France?")); This shows: Provider‑agnostic model access Session‑aware agent execution Minimal setup for production agents Creating a Simple Agent (Python) from agent_framework.foundry import FoundryChatClient from azure.identity import AzureCliCredential client = FoundryChatClient( project_endpoint="https://your-foundry-service.services.ai.azure.com/api/projects/your-project", model="gpt-5.4-mini", credential=AzureCliCredential(), ) agent = client.as_agent( name="HelloAgent", instructions="You are a friendly assistant. Keep your answers brief.", ) result = await agent.run("What is the largest city in France?") print(result) The same agent abstraction applies across languages. When to Use Agents vs Workflows Microsoft provides clear guidance: Use an Agent when… Use a Workflow when… Task is open‑ended Steps are well‑defined Autonomous tool use is needed Execution order matters Single decision point Multiple agents/functions collaborate Key principle: If you can solve the task with deterministic code, do that instead of using an AI agent. 🔄 How It Differs from Other Frameworks Microsoft Agent Framework 1.0 distinguishes itself by focusing on "Enterprise Readiness" and "Interoperability." Feature Microsoft Agent Framework 1.0 Semantic Kernel / AutoGen LangChain / CrewAI Philosophy Unified, production-ready SDK. Research-focused or tool-specific. High-level, developer-friendly abstractions. Integration Deeply integrated with Microsoft Foundry and Azure. Varied; often requires more glue code. Generally cloud-agnostic. Interoperability Native A2A and MCP for cross-framework tasks. Limited to internal ecosystem. Uses proprietary connectors. Runtime Identical API parity for .NET and Python. Primarily Python-first (SK has C#). Primarily Python. Control Graph-based deterministic workflows. More non-deterministic/experimental. Mixture of role-based and agentic. 🛠️ Key Technical Components Agent Harness: The execution layer that provides agents with controlled access to the shell, file system, and messaging loops. Agent Skills: A portable, file-based or code-defined format for packaging domain expertise. Implementation Tip: If you are coming from Semantic Kernel, Microsoft provides migration assistants that analyze your existing code and generate step-by-step plans to upgrade to the new Agent Framework 1.0 standards. Microsoft Agent Framework Version 1.0 | Microsoft Agent Framework Agent Framework documentation 🎯 Summary Microsoft Agent Framework 1.0 is the "grown-up" version of AI orchestration. By standardizing the way agents talk to each other (A2A), discover tools (MCP), and process information (Middleware), Microsoft has provided a clear path for taking AI experiments into production. For more detailed guides, check out the official Microsoft Agent Framework DocumentationMicrosoft Agent Framework - .NET AI Community StandupVectorless Reasoning-Based RAG: A New Approach to Retrieval-Augmented Generation
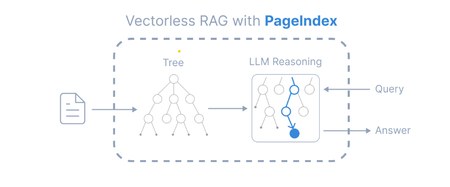
Introduction Retrieval-Augmented Generation (RAG) has become a widely adopted architecture for building AI applications that combine Large Language Models (LLMs) with external knowledge sources. Traditional RAG pipelines rely heavily on vector embeddings and similarity search to retrieve relevant documents. While this works well for many scenarios, it introduces challenges such as: Requires chunking documents into small segments Important context can be split across chunks Embedding generation and vector databases add infrastructure complexity A new paradigm called Vectorless Reasoning-Based RAG is emerging to address these challenges. One framework enabling this approach is PageIndex, an open-source document indexing system that organizes documents into a hierarchical tree structure and allows Large Language Models (LLMs) to perform reasoning-based retrieval over that structure. Vectorless Reasoning-Based RAG Instead of vectors, this approach uses structured document navigation. User Query ->Document Tree Structure ->LLM Reasoning ->Relevant Nodes Retrieved ->LLM Generates Answer This mimics how humans read documents: Look at the table of contents Identify relevant sections Read the relevant content Answer the question Core features No Vector Database: It relies on document structure and LLM reasoning for retrieval. It does not depend on vector similarity search. No Chunking: Documents are not split into artificial chunks. Instead, they are organized using their natural structure, such as pages and sections. Human-like Retrieval: The system mimics how human experts read documents. It navigates through sections and extracts information from relevant parts. Better Explainability and Traceability: Retrieval is based on reasoning. The results can be traced back to specific pages and sections. This makes the process easier to interpret. It avoids opaque and approximate vector search, often called “vibe retrieval.” When to Use Vectorless RAG Vectorless RAG works best when: Data is structured or semi-structured Documents have clear metadata Knowledge sources are well organized Queries require reasoning rather than semantic similarity Examples: enterprise knowledge bases internal documentation systems compliance and policy search healthcare documentation financial reporting Implementing Vectorless RAG with Azure AI Foundry Step 1 : Install Pageindex using pip command, from pageindex import PageIndexClient import pageindex.utils as utils # Get your PageIndex API key from https://dash.pageindex.ai/api-keys PAGEINDEX_API_KEY = "YOUR_PAGEINDEX_API_KEY" pi_client = PageIndexClient(api_key=PAGEINDEX_API_KEY) Step 2 : Set up your LLM Example using Azure OpenAI: from openai import AsyncAzureOpenAI client = AsyncAzureOpenAI( api_key=AZURE_OPENAI_API_KEY, azure_endpoint=AZURE_OPENAI_ENDPOINT, api_version=AZURE_OPENAI_API_VERSION ) async def call_llm(prompt, temperature=0): response = await client.chat.completions.create( model=AZURE_DEPLOYMENT_NAME, messages=[{"role": "user", "content": prompt}], temperature=temperature ) return response.choices[0].message.content.strip() Step 3: Page Tree Generation import os, requests pdf_url = "https://arxiv.org/pdf/2501.12948.pdf" //give the pdf url for tree generation, here given one for example pdf_path = os.path.join("../data", pdf_url.split('/')[-1]) os.makedirs(os.path.dirname(pdf_path), exist_ok=True) response = requests.get(pdf_url) with open(pdf_path, "wb") as f: f.write(response.content) print(f"Downloaded {pdf_url}") doc_id = pi_client.submit_document(pdf_path)["doc_id"] print('Document Submitted:', doc_id) Step 4 : Print the generated pageindex tree structure if pi_client.is_retrieval_ready(doc_id): tree = pi_client.get_tree(doc_id, node_summary=True)['result'] print('Simplified Tree Structure of the Document:') utils.print_tree(tree) else: print("Processing document, please try again later...") Step 5 : Use LLM for tree search and identify nodes that might contain relevant context import json query = "What are the conclusions in this document?" tree_without_text = utils.remove_fields(tree.copy(), fields=['text']) search_prompt = f""" You are given a question and a tree structure of a document. Each node contains a node id, node title, and a corresponding summary. Your task is to find all nodes that are likely to contain the answer to the question. Question: {query} Document tree structure: {json.dumps(tree_without_text, indent=2)} Please reply in the following JSON format: {{ "thinking": "<Your thinking process on which nodes are relevant to the question>", "node_list": ["node_id_1", "node_id_2", ..., "node_id_n"] }} Directly return the final JSON structure. Do not output anything else. """ tree_search_result = await call_llm(search_prompt) Step 6 : Print retrieved nodes and reasoning process node_map = utils.create_node_mapping(tree) tree_search_result_json = json.loads(tree_search_result) print('Reasoning Process:') utils.print_wrapped(tree_search_result_json['thinking']) print('\nRetrieved Nodes:') for node_id in tree_search_result_json["node_list"]: node = node_map[node_id] print(f"Node ID: {node['node_id']}\t Page: {node['page_index']}\t Title: {node['title']}") Step 7: Answer generation node_list = json.loads(tree_search_result)["node_list"] relevant_content = "\n\n".join(node_map[node_id]["text"] for node_id in node_list) print('Retrieved Context:\n') utils.print_wrapped(relevant_content[:1000] + '...') answer_prompt = f""" Answer the question based on the context: Question: {query} Context: {relevant_content} Provide a clear, concise answer based only on the context provided. """ print('Generated Answer:\n') answer = await call_llm(answer_prompt) utils.print_wrapped(answer) When to Use Each Approach Both vector-based RAG and vectorless RAG have their strengths. Choosing the right approach depends on the nature of the documents and the type of retrieval required. When to Use Vector Database–Based RAG Vector-based retrieval works best when dealing with large collections of unrelated or loosely structured documents. In such cases, semantic similarity is often sufficient to identify relevant information quickly. Use vector RAG when: Searching across many independent documents Semantic similarity is sufficient to locate relevant content Real-time retrieval is required over very large datasets Common use cases include: Customer support knowledge bases Conversational chatbots Product and content search systems When to Use Vectorless RAG Vectorless approaches such as PageIndex are better suited for long, structured documents where understanding the logical organization of the content is important. Use vectorless RAG when: Documents contain clear hierarchical structure Logical reasoning across sections is required High retrieval accuracy is critical Typical examples include: Financial filings and regulatory reports Legal documents and contracts Technical manuals and documentation Academic and research papers In these scenarios, navigating the document structure allows the system to identify the exact section that logically contains the answer, rather than relying only on semantic similarity. Conclusion Vector databases significantly advanced RAG architectures by enabling scalable semantic search across large datasets. However, they are not the optimal solution for every type of document. Vectorless approaches such as PageIndex introduce a different philosophy: instead of retrieving text that is merely semantically similar, they retrieve text that is logically relevant by reasoning over the structure of the document. As RAG architectures continue to evolve, the future will likely combine the strengths of both approaches. Hybrid systems that integrate vector search for broad retrieval and reasoning-based navigation for precision may offer the best balance of scalability and accuracy for enterprise AI applications.Generative AI for Beginners - Full Videos Series Released!
With so many new technologies, tools and terms in the world of Generative AI, it can be hard to know where to start or what to learn next. "Generative AI for Beginners" is designed to help you on your learning journey no matter where you are now. We are happy announce that the "Generative AI for Beginners" course has received a major refresh - 18 new videos for each lesson.Building Your First Local RAG Application with Foundry Local
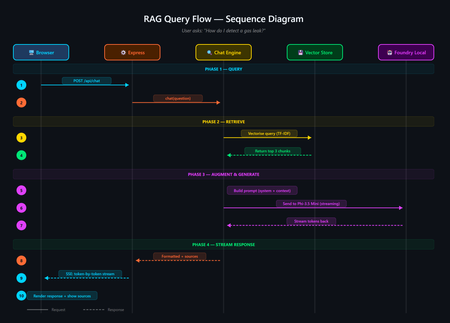
A developer's guide to building an offline, mobile-responsive AI support agent using Retrieval-Augmented Generation, the Foundry Local SDK, and JavaScript. Imagine you are a gas field engineer standing beside a pipeline in a remote location. There is no Wi-Fi, no mobile signal, and you need a safety procedure right now. What do you do? This is the exact problem that inspired this project: a fully offline RAG-powered support agent that runs entirely on your machine. No cloud. No API keys. No outbound network calls. Just a local language model, a local vector store, and your own documents, all accessible from a browser on any device. In this post, you will learn how it works, how to build your own, and the key architectural decisions behind it. If you have ever wanted to build an AI application that runs locally and answers questions grounded in your own data, this is the place to start. The finished application: a browser-based AI support agent that runs entirely on your machine. What Is Retrieval-Augmented Generation? Retrieval-Augmented Generation (RAG) is a pattern that makes AI models genuinely useful for domain-specific tasks. Rather than hoping the model "knows" the answer from its training data, you: Retrieve relevant chunks from your own documents using a vector store Augment the model's prompt with those chunks as context Generate a response grounded in your actual data The result is fewer hallucinations, traceable answers with source attribution, and an AI that works with your content rather than relying on general knowledge. If you are building internal tools, customer support bots, field manuals, or knowledge bases, RAG is the pattern you want. RAG vs CAG: Understanding the Trade-offs If you have explored AI application patterns before, you have likely encountered Context-Augmented Generation (CAG). Both RAG and CAG solve the same core problem: grounding an AI model's answers in your own content. They take different approaches, and each has genuine strengths and limitations. RAG (Retrieval-Augmented Generation) How it works: Documents are split into chunks, vectorised, and stored in a database. At query time, the most relevant chunks are retrieved and injected into the prompt. Strengths: Scales to thousands or millions of documents Fine-grained retrieval at chunk level with source attribution Documents can be added or updated dynamically without restarting Token-efficient: only relevant chunks are sent to the model Supports runtime document upload via the web UI Limitations: More complex architecture: requires a vector store and chunking strategy Retrieval quality depends on chunking parameters and scoring method May miss relevant content if the retrieval step does not surface it CAG (Context-Augmented Generation) How it works: All documents are loaded at startup. The most relevant ones are selected per query using keyword scoring and injected into the prompt. Strengths: Drastically simpler architecture with no vector database or embeddings All information is always available to the model Minimal dependencies and easy to set up Near-instant document selection Limitations: Constrained by the model's context window size Best suited to small, curated document sets (tens of documents) Adding documents requires an application restart Want to compare these patterns hands-on? There is a CAG-based implementation of the same gas field scenario using whole-document context injection. Clone both repositories, run them side by side, and see how the architectures differ in practice. When Should You Choose Which? Consideration Choose RAG Choose CAG Document count Hundreds or thousands Tens of documents Document updates Frequent or dynamic (runtime upload) Infrequent (restart to reload) Source attribution Per-chunk with relevance scores Per-document Setup complexity Moderate (ingestion step required) Minimal Query precision Better for large or diverse collections Good for keyword-matchable content Infrastructure SQLite vector store (single file) None beyond the runtime For the sample application in this post (20 gas engineering procedure documents with runtime upload), RAG is the clear winner. If your document set is small and static, CAG may be simpler. Both patterns run fully offline using Foundry Local. Foundry Local: Your On-Device AI Runtime Foundry Local is a lightweight runtime from Microsoft that downloads, manages, and serves language models entirely on your device. No cloud account, no API keys, no outbound network calls (after the initial model download). What makes it particularly useful for developers: No GPU required: runs on CPU or NPU, making it accessible on standard laptops and desktops Native SDK bindings: in-process inference via the foundry-local-sdk npm package, with no HTTP round-trips to a local server Automatic model management: downloads, caches, and loads models automatically Hardware-optimised variant selection: the SDK picks the best variant for your hardware (GPU, NPU, or CPU) Real-time progress callbacks: ideal for building loading UIs that show download and initialisation progress The integration code is refreshingly minimal: import { FoundryLocalManager } from "foundry-local-sdk"; // Create a manager and discover models via the catalogue const manager = FoundryLocalManager.create({ appName: "gas-field-local-rag" }); const model = await manager.catalog.getModel("phi-3.5-mini"); // Download if not cached, then load into memory if (!model.isCached) { await model.download((progress) => { console.log(`Download: ${Math.round(progress * 100)}%`); }); } await model.load(); // Create a chat client for direct in-process inference const chatClient = model.createChatClient(); const response = await chatClient.completeChat([ { role: "system", content: "You are a helpful assistant." }, { role: "user", content: "How do I detect a gas leak?" } ]); That is it. No server configuration, no authentication tokens, no cloud provisioning. The model runs in the same process as your application. The Technology Stack The sample application is deliberately simple. No frameworks, no build steps, no Docker: Layer Technology Purpose AI Model Foundry Local + Phi-3.5 Mini Runs locally via native SDK bindings, no GPU required Back end Node.js + Express Lightweight HTTP server, everyone knows it Vector Store SQLite (via better-sqlite3 ) Zero infrastructure, single file on disc Retrieval TF-IDF + cosine similarity No embedding model required, fully offline Front end Single HTML file with inline CSS No build step, mobile-responsive, field-ready The total dependency footprint is three npm packages: express , foundry-local-sdk , and better-sqlite3 . Architecture Overview The five-layer architecture, all running on a single machine. The system has five layers, all running on a single machine: Client layer: a single HTML file served by Express, with quick-action buttons and a responsive chat interface Server layer: Express.js starts immediately and serves the UI plus SSE status and chat endpoints RAG pipeline: the chat engine orchestrates retrieval and generation; the chunker handles TF-IDF vectorisation; the prompts module provides safety-first system instructions Data layer: SQLite stores document chunks and their TF-IDF vectors; documents live as .md files in the docs/ folder AI layer: Foundry Local runs Phi-3.5 Mini on CPU or NPU via native SDK bindings Building the Solution Step by Step Prerequisites You need two things installed on your machine: Node.js 20 or later: download from nodejs.org Foundry Local: Microsoft's on-device AI runtime: winget install Microsoft.FoundryLocal The SDK will automatically download the Phi-3.5 Mini model (approximately 2 GB) the first time you run the application. Getting the Code Running # Clone the repository git clone https://github.com/leestott/local-rag.git cd local-rag # Install dependencies npm install # Ingest the 20 gas engineering documents into the vector store npm run ingest # Start the server npm start Open http://127.0.0.1:3000 in your browser. You will see the status indicator whilst the model loads. Once the model is ready, the status changes to "Offline Ready" and you can start chatting. Desktop view Mobile view How the RAG Pipeline Works Let us trace what happens when a user asks: "How do I detect a gas leak?" The query flow from browser to model and back. 1 Documents are ingested and indexed When you run npm run ingest , every .md file in the docs/ folder is read, parsed (with optional YAML front-matter for title, category, and ID), split into overlapping chunks of approximately 200 tokens, and stored in SQLite with TF-IDF vectors. 2 Model is loaded via the SDK The Foundry Local SDK discovers the model in the local catalogue and loads it into memory. If the model is not already cached, it downloads it first (with progress streamed to the browser via SSE). 3 User sends a question The question arrives at the Express server. The chat engine converts it into a TF-IDF vector, uses an inverted index to find candidate chunks, and scores them using cosine similarity. The top 3 chunks are returned in under 1 ms. 4 Prompt is constructed The engine builds a messages array containing: the system prompt (with safety-first instructions), the retrieved chunks as context, the conversation history, and the user's question. 5 Model generates a grounded response The prompt is sent to the locally loaded model via the Foundry Local SDK's native chat client. The response streams back token by token through Server-Sent Events to the browser. Source references with relevance scores are included. A response with safety warnings and step-by-step guidance The sources panel shows which chunks were used and their relevance Key Code Walkthrough The Vector Store (TF-IDF + SQLite) The vector store uses SQLite to persist document chunks alongside their TF-IDF vectors. At query time, an inverted index finds candidate chunks that share terms with the query, then cosine similarity ranks them: // src/vectorStore.js search(query, topK = 5) { const queryTf = termFrequency(query); this._ensureCache(); // Build in-memory cache on first access // Use inverted index to find candidates sharing at least one term const candidateIndices = new Set(); for (const term of queryTf.keys()) { const indices = this._invertedIndex.get(term); if (indices) { for (const idx of indices) candidateIndices.add(idx); } } // Score only candidates, not all rows const scored = []; for (const idx of candidateIndices) { const row = this._rowCache[idx]; const score = cosineSimilarity(queryTf, row.tf); if (score > 0) scored.push({ ...row, score }); } scored.sort((a, b) => b.score - a.score); return scored.slice(0, topK); } The inverted index, in-memory row cache, and prepared SQL statements bring retrieval time to sub-millisecond for typical query loads. Why TF-IDF Instead of Embeddings? Most RAG tutorials use embedding models for retrieval. This project uses TF-IDF because: Fully offline: no embedding model to download or run Zero latency: vectorisation is instantaneous (it is just maths on word frequencies) Good enough: for 20 domain-specific documents, TF-IDF retrieves the right chunks reliably Transparent: you can inspect the vocabulary and weights, unlike neural embeddings For larger collections or when semantic similarity matters more than keyword overlap, you would swap in an embedding model. For this use case, TF-IDF keeps the stack simple and dependency-free. The System Prompt For safety-critical domains, the system prompt is engineered to prioritise safety, prevent hallucination, and enforce structured responses: // src/prompts.js export const SYSTEM_PROMPT = `You are a local, offline support agent for gas field inspection and maintenance engineers. Behaviour Rules: - Always prioritise safety. If a procedure involves risk, explicitly call it out. - Do not hallucinate procedures, measurements, or tolerances. - If the answer is not in the provided context, say: "This information is not available in the local knowledge base." Response Format: - Summary (1-2 lines) - Safety Warnings (if applicable) - Step-by-step Guidance - Reference (document name + section)`; This pattern is transferable to any safety-critical domain: medical devices, electrical work, aviation maintenance, or chemical handling. Runtime Document Upload Unlike the CAG approach, RAG supports adding documents without restarting the server. Click the upload button to add new .md or .txt files. They are chunked, vectorised, and indexed immediately. The upload modal with the complete list of indexed documents. Adapting This for Your Own Domain The sample project is designed to be forked and adapted. Here is how to make it yours in four steps: 1. Replace the documents Delete the gas engineering documents in docs/ and add your own markdown files. The ingestion pipeline handles any markdown content with optional YAML front-matter: --- title: Troubleshooting Widget Errors category: Support id: KB-001 --- # Troubleshooting Widget Errors ...your content here... 2. Edit the system prompt Open src/prompts.js and rewrite the system prompt for your domain. Keep the structure (summary, safety, steps, reference) and update the language to match your users' expectations. 3. Tune the retrieval In src/config.js : chunkSize: 200 : smaller chunks give more precise retrieval, less context per chunk chunkOverlap: 25 : prevents information falling between chunks topK: 3 : how many chunks to retrieve per query (more gives more context but slower generation) 4. Swap the model Change config.model in src/config.js to any model available in the Foundry Local catalogue. Smaller models give faster responses on constrained devices; larger models give better quality. Building a Field-Ready UI The front end is a single HTML file with inline CSS. No React, no build tooling, no bundler. This keeps the project accessible to beginners and easy to deploy. Design decisions that matter for field use: Dark, high-contrast theme with 18px base font size for readability in bright sunlight Large touch targets (minimum 44px) for operation with gloves or PPE Quick-action buttons that wrap on mobile so all options are visible without scrolling Responsive layout that works from 320px to 1920px+ screen widths Streaming responses via SSE, so the user sees tokens arriving in real time The mobile chat experience, optimised for field use. Testing The project includes unit tests using the built-in Node.js test runner, with no extra test framework needed: # Run all tests npm test Tests cover the chunker, vector store, configuration, and server endpoints. Use them as a starting point when you adapt the project for your own domain. Ideas for Extending the Project Once you have the basics running, there are plenty of directions to explore: Embedding-based retrieval: use a local embedding model for better semantic matching on diverse queries Conversation memory: persist chat history across sessions using local storage or a lightweight database Multi-modal support: add image-based queries (photographing a fault code, for example) PWA packaging: make it installable as a standalone offline application on mobile devices Hybrid retrieval: combine TF-IDF keyword search with semantic embeddings for best results Try the CAG approach: compare with the local-cag sample to see which pattern suits your use case Ready to Build Your Own? Clone the RAG sample, swap in your own documents, and have an offline AI agent running in minutes. Or compare it with the CAG approach to see which pattern suits your use case best. Get the RAG Sample Get the CAG Sample Summary Building a local RAG application does not require a PhD in machine learning or a cloud budget. With Foundry Local, Node.js, and SQLite, you can create a fully offline, mobile-responsive AI agent that answers questions grounded in your own documents. The key takeaways: RAG is ideal for scalable, dynamic document sets where you need fine-grained retrieval with source attribution. Documents can be added at runtime without restarting. CAG is simpler when you have a small, stable set of documents that fit in the context window. See the local-cag sample to compare. Foundry Local makes on-device AI accessible: native SDK bindings, in-process inference, automatic model selection, and no GPU required. TF-IDF + SQLite is a viable vector store for small-to-medium collections, with sub-millisecond retrieval thanks to inverted indexing and in-memory caching. Start simple, iterate outwards. Begin with RAG and a handful of documents. If your needs are simpler, try CAG. Both patterns run entirely offline. Clone the repository, swap in your own documents, and start building. The best way to learn is to get your hands on the code. This project is open source under the MIT licence. It is a scenario sample for learning and experimentation, not production medical or safety advice. local-rag on GitHub · local-cag on GitHub · Foundry Local6.8KViews2likes0Comments