foundry
11 Topics
Microsoft Foundry External MCP Server Traffic Routing via Corporate Firewall
The customer would like to confirm whether traffic from an Azure AI Foundry agent to an external MCP server can be routed through a corporate firewall and whether this scenario is officially supported. To validate this scenario, I configured the following in my lab: Deployed an Azure AI Foundry resource using the Standard Agent Service with network injection. Created a dedicated subnet for the Foundry Agent Service and delegated it to Microsoft.App/environments. Associated a route table with the Foundry Agent subnet to route outbound traffic through Azure Firewall. Configured the required application and network rules on Azure Firewall. The Foundry agent is able to successfully retrieve data from the external MCP server. However, no corresponding traffic is visible in the Azure Firewall logs. Could you please confirm whether outbound traffic from the Foundry agent to an external MCP server can be routed through Azure Firewall or a corporate firewall? Also, is this routing scenario officially supported? Appreciate your support!
Is there a way to connect 2 Ai foundry to the same cosmos containers?
I defined Azure AI Foundry Connection for Azure Cosmos DB and BYO Thread Storage in Azure AI Agent Service by using these instructions: Integration with Azure AI Agent Service - Azure Cosmos DB for NoSQL | Microsoft Learn I see that it created 3 containers under the cosmos I provided: <guid>-agent-entity-store v-system-thread-message-store <guid>-thread-message-store Now I created another AI foundry and added a connection for the same AI foundry, and it created 3 different containers under the same DB. Is there a way that they'll use the same exact containers? I want to use multiple AI foundries, and they will use the same Cosmos containers to manage the data.307Views0likes1Comment
Missing equivalent for Python MemorySearchTool and AgentMemorySettings in C# SDK
Hi Team, I am currently working with the Azure AI Foundry Agent Service (preview). I’ve been reviewing the documentation for managed long-term memory, specifically the "Automatic User Memory" features demonstrated in the Python SDK here: https://learn.microsoft.com/en-us/azure/ai-foundry/agents/how-to/memory-usage?view=foundry&tabs=python. In Python, it is very straightforward to attach a MemorySearchTool to an agent and use AgentMemorySettings(scope="user_123") during a run. This allows the service to automatically extract, consolidate, and retrieve memories without manual intervention. However, in the https://github.com/Azure/azure-sdk-for-net/tree/main/sdk/ai/Azure.AI.Projects#memory-store-operations, I only see the low-level MemoryStoreClient which appears to require manual CRUD operations on memory items. My Questions: Is there an equivalent high-level AgentMemorySearchTool or similar abstraction in the current C# NuGet package (Azure.AI.Projects) that handles automatic extraction and retrieval? If not currently available, is this feature on the immediate roadmap for the .NET SDK? Are there any samples showing how to achieve "automatic" memory (where the Agent extracts facts itself) using the C# SDK without having to build a custom orchestration layer or call REST APIs directly? Any guidance on the timeline for feature parity between the Python and .NET SDKs regarding Agent Memory would be greatly appreciated. SDK Version: Azure.AI.Projects 1.2.0-beta.5213Views0likes2CommentsUnable to delete Foundry Agent identity Entra app in Azure
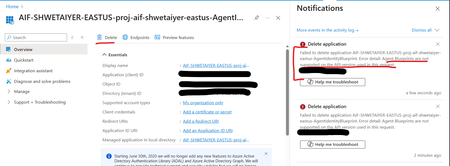
I'm trying to delete an Entra app in Azure created by Foundry Agent identity blueprint as its currently unused and is causing EntraID hygiene alerts. However getting an error mentioning that delete is not supported. Is there any other way to delete an unused Entra app for an agent identity blueprint? Error detail: Agent Blueprints are not supported on the API version used in this request.459Views0likes3Comments8 Architectural Pillars to Boost GenAI LLM Accuracy and Performance in Low Cost
Smarter AI architecture, not bigger LLM models - how engineering teams push LLM accuracy and high performance in low cost. Enterprises using LLM (Large Language Models) hits the same ceiling and paying big price! A raw API call to a frontier model- GPT-4, Claude, Gemini delivers only 35-40% accuracy on structured output tasks like code generation, NL to DAX query generation, domain-specific reasoning. Prompt engineering pushes that to ~60%. But the final 35+ percentage points? Those come from system architecture, not model upgrades. This guide presents 8 architectural pillars, distilled from production Gen AI systems, that compound to close the accuracy gap. These patterns are model-agnostic and domain-agnostic, they apply equally to chatbots, coding assistants, content/query generators, automation agents, and any application where an LLM produces structured or semi-structured output. It’s based on my recent Gen AI projects. The key takeaway: use the LLM as one component in a larger system, not as the system itself. Surround it with deterministic guardrails, verified knowledge, and feedback loops. Pillar 1: Enhance Prompts with Verified Knowledge Context Impact: +35–40% accuracy (based on production use cases; may vary by domain) Top source of LLM errors in production is hallucinated identifiers knowledgebase, the model invents names, references, or structures that don't exist in the target system. This happens because LLMs are trained on general knowledge but deployed against specific, private enterprise systems they've never seen local database and knowledgebase. The fix is straightforward: inject verified, system-specific context (type definitions, API specs, ontologies, configuration schemas, entity catalogues) directly into the prompt so the model composes from known-good elements rather than recalling from training data. Use Knowledge Graph for better sematic knowledge. How to Implement Provide explicit context, never implicit- Whatever the LLM needs to reference identifiers, valid values, semantic knowledge, structures must appear verbatim in the prompt or retrieved context window. Filter aggressively. A full knowledge base with thousands of entities overwhelms the context window and confuses the model. Use intelligent filtering to surface only needed 5-10 most relevant elements per request. Store structured semantic knowledge in a graph or searchable index. This enables relationship-aware retrieval: "given entity X, what related entities, attributes, and constraints are also needed?" Include rich Semantic metadata. Names alone are insufficient. Include types, constraints, valid value ranges, relationships, and usage notes to minimize ambiguity. Keep context fresh. Stale context causes a different class of hallucination the model generates valid-looking output that references outdated structures. Sync your knowledge store with your source of truth. Why This Works LLMs excel at composition and reasoning combining elements, applying logic, following patterns. They are unreliable at recall of specific identifiers exact names, valid values, structural constraints. By offloading recall to a deterministic retrieval system and giving the LLM only composition tasks, you play to each system's strengths. Pillar 2: Tiered LLM Approach: Route Deterministically First, Use LLMs Last Impact: 80% cost reduction, 85% latency reduction, eliminates non-deterministic errors for most traffic. The most impactful architectural insight: most production requests don't need an LLM at all. A well-designed system handles 60-70% of traffic with deterministic logic templates, composition rules, cached results and reserves expensive, non-deterministic LLM calls only for genuinely novel inputs. The Three-Tier Model These metrics are from a real use case to convert NLP to Power BI DAX query. Tier Strategy Uses LLM ? Latency Accuracy Tier 0 Template slot-filling - handles requests that match known patterns exactly the system fills slots in a pre-built template with extracted parameters. No LLM, no non-determinism, near-perfect accuracy, sub-100ms response. No ~50ms 95-98% Tier 1 Compose from pre-validated fragments- handles requests that combine known patterns in new ways. The system retrieves pre-validated building blocks via search, composes them using deterministic rules, and validates the result. Still no LLM call. No ~200ms 90-95% Tier 2 Full LLM generation with enriched context- is reserved for genuinely novel requests that can't be served deterministically. Even here, the LLM receives maximum support: filtered context, relevant examples, explicit rules, and structured planning. Yes (1 call) 2-5s 88-93% Complexity-Based Routing A lightweight scoring function (evaluated in <1ms) routes each incoming request: Factors: reasoning depth, number of components, cross-references, constraints, nesting depth, novelty (distance from known patterns) Score 0-39: Tier 0 (deterministic template) Score 40-59: Tier 1 if confidence ≥ 85%, else Tier 2 Score 60+: Tier 2 (LLM generation) This routing achieves 96%+ accuracy in tier assignment and ensures the expensive path is only taken when necessary. Why This Matters Cost: 70-80% of requests cost zero LLM tokens Latency: Majority of responses in <200ms instead of 2-5s Reliability: Deterministic tiers produce identical output for identical input. Scalability: Deterministic tiers scale horizontally with trivial compute Pillar 3: Encode Prompt Anti-Patterns as Explicit Rules Impact: +8-10% accuracy, ~80% reduction in common structural errors LLM mistakes are patterned, not random. In any domain, 80% of errors cluster around a small set of 6-13 recurring structural mistakes. Instead of hoping the model avoids them through general instruction-following, compile these mistakes into explicit WRONG => CORRECT rules embedded directly in the system prompt. How to Implement Collect error data. Run 100+ requests through your system and categorize the failures. You'll find the same 6-13 patterns appearing repeatedly. Write concrete rules. For each pattern, show the exact wrong output and the exact correct alternative, with a one-line explanation of why. Embed in system prompt. Place rules prominently after the task description, before examples. Use formatting that's hard to ignore (headers, bold, explicit "NEVER" language). Keep the list short. 6-13 rules maximum. Beyond that, attention dilutes and the model starts ignoring rules. Prioritize by frequency. Refresh continuously. As the system improves (via other pillars), some errors disappear. New error types emerge. Update the rule set quarterly. Why This Works LLMs respond strongly to explicit negative examples. A generic instruction like "be careful with X" has minimal impact. But showing the exact wrong output the model tends to produce, paired with the correction, creates a strong avoidance signal. It's analogous to unit tests. Pillar 4: Retrieve Few-Shot Examples Dynamically Impact: +5-15% accuracy depending on domain complexity Static examples hardcoded in a prompt become stale, irrelevant of context tokens. Dynamic few-shot retrieval selects the 3-5 most relevant examples for each specific request, maximizing the signal-to-noise ratio in the prompt. Hybrid Retrieval Architecture The most effective approach combines two search strategies for intent search to understand natural language (NL) context: Keyword search (BM25) Finds examples with exact matching terms, identifiers, and domain vocabulary Vector search (semantic similarity) Finds examples with similar intent and structure, even if wording differs Rank fusion Merges results from both strategies, re-ranking by combined relevance This hybrid approach outperforms either strategy alone because keyword search catches exact identifier matches that vector search dilutes, while vector search captures semantic similarity that keyword search misses entirely. Best Gen AI Architectural Practices Match complexity to complexity. Simple requests should see simple examples. Complex requests should see complex examples. Mismatched examples confuse the model. Include negative examples. For the detected request type, include 1-2 "wrong => correct" pairs alongside positive examples. This reinforces Pillar 3's anti-pattern rules with concrete, contextually relevant demonstrations. Pre-compute embeddings. Generate vector embeddings at indexing time, not at query time. Cache retrieval results for repeated patterns. Curate quality over quantity. 3 excellent, diverse examples beat 10 mediocre ones. Each example should demonstrate a distinct pattern or edge case. Keep examples current. As your system evolves, old examples may demonstrate outdated patterns. Review and refresh the example store periodically. Pillar 5: Feedback Loop- Validate and Auto-Fix Every Output Deterministically Impact: +3-5% accuracy as a safety net, plus continuous improvement via feedback No matter how well-prompted, LLMs will occasionally produce outputs with minor structural errors - wrong casing, missing delimiters, references to slightly-incorrect identifiers, or subtle format violations. A deterministic post-processing pipeline catches and fixes these without any additional LLM calls. The Validation Pipeline LLM Output => Parse (grammar/AST) => Rule-Based Fixes => Compliance Check/validation => Final Output Each stage is fully deterministic: Parsing: Use a formal grammar or AST parser (ANTLR, tree-sitter, language-native parsers) to structurally analyse the output. Never regex-parse structured output - it's fragile and misses edge cases. Rule-based fixes: 10-20 deterministic transformation rules that correct known error patterns - name normalization, casing fixes, missing delimiters, structural repairs. Compliance check: Verify every identifier referenced in the output actually exists in the provided context. Flag unknown references. Design Principles Zero LLM calls in the fix pipeline. Every fix is a regex, an AST transformation, or a lookup table operation. Instant, free, deterministic, 100% reliable. Fail safe. If a fix is ambiguous (multiple valid corrections possible), pass through rather than corrupt. A minor error is better than a confident wrong "fix." Log everything. Track every fix applied, categorized by type. This data drives the feedback loop. The Critical Feedback Loop- The validation pipeline's most important function isn't fixing outputs, it's generating improvement signals: This creates a feedback loop: the auto-fix catches errors → the errors get promoted to upstream prevention → fewer errors reach the auto-fix → the system continuously tightens. Pillar 6: Multi-Agent Orchestration with Fewer Agents and Clear Contracts Impact: Reduced latency, clearer debugging, fewer failure modes The multi-agent pattern is powerful but commonly over-applied. The counter-intuitive lesson from production systems: fewer agents with well-defined responsibilities outperform many fine-grained agents. Why Fewer Is Better Each agent handoff introduces: Latency - serialization, network calls, context assembly Context loss - information dropped between boundaries Failure modes - each handoff is a potential error point Debugging complexity - tracing issues across many agents is exponentially harder Multi-Agent Orchestration Principles Merge agents that always run sequentially. If Agent A always feeds into Agent B with no branching or conditional logic, they should be one agent with two internal steps. Parallelize independent operations. Context retrieval and example lookup are independent, run them concurrently to halve retrieval latency. Route sub-tasks to cheaper models. Decomposed sub-problems are simpler by design. Use a smaller, faster, cheaper model (3x cost savings, 2x speed improvement). Define strict contracts. Each agent boundary should have an explicit schema defining inputs and outputs. No implicit assumptions about what crosses the boundary. Only 2 of 4 agents should call an LLM. The rest are purely deterministic. This minimizes non-deterministic behavior and cost. Pillar 7: Multi-Agent Cache at Multiple Hierarchical Levels Impact: 40-50% faster responses, 85%+ combined hit rate, significant cost reduction A single cache layer captures only one type of repetition. Production systems need hierarchical caching where multiple levels catch different repetition patterns , from exact duplicates to semantic near-misses. with -> A single cache layer captures only one type of repetition. Production systems need multi-level caching to handle exact matches, similar requests, and reusable fragments. or -> with Production systems need hierarchical caching where multiple levels handle exact matches, similar requests, and reusable fragments. Pillar 8: Measure Everything, Learn Continuously Impact: Enables data-driven iteration and prevents accuracy regressions. Architecture without observability is guesswork. The final pillar ensures every other pillar stays effective over time through comprehensive metrics and automated feedback loops. This isn't a one-time setup; it's a perpetual feedback loop. Every week, the top error patterns shift slightly. The auto-fix metrics tell you exactly where to focus next. Over months, this flywheel compounds into dramatic accuracy gains that no single prompt rewrite could achieve. Auto-Learning for New Domains When extending your system to new domains or knowledge areas: Auto-classify elements using naming conventions, type analysis, and structural patterns Auto-generate templates from universal patterns (transformations, comparisons, compositions, sequences) Bootstrap few-shot examples from successful template outputs Monitor for the first 100 requests, then curate only the edge cases manually This reduces domain onboarding from days of manual work to minutes of automated bootstrapping plus focused human review of outliers. Key Takeaways Architecture beats model size. A well-architected system with a smaller model outperforms a raw frontier model call on structured tasks at a fraction of the cost. Deterministic systems should do the heavy lifting. Reserve LLMs for genuinely novel, creative tasks. 70-80% of production requests should never touch an LLM. Verified knowledge is your top accuracy lever. Ground every prompt in context the model can trust. Errors are patterned, not random- Track them, compile them, and explicitly forbid them. Build feedback loops, not static systems- Every auto-fix, every cache miss, every routing decision is a signal for improvement. Fewer agents, done well- Fewer agents with strict contracts outperform 9 agents with fuzzy boundaries in accuracy, latency, and debuggability. Measure what matters and iterates- The system that wins isn't the one with the best day-one prompt, it's the one that improves fastest over time. Production-grade GenAI isn't about finding the perfect prompt or waiting for the next LLM model release. It's about building architectural guardrails that make failure nearly impossible and when failure does occur, the system learns from it automatically. These 8 pillars, applied together, transform any LLM from an unreliable black box into a precise, efficient, and continuously improving production system. -> Production Gen AI success is not about perfect prompts or waiting for the next LLM release. It comes from designing strong system guardrails that reduce failures and ensure consistent output. Even when failures happen, the system learns and improves automatically. When applied together, these 8 pillars turn an LLM into a reliable, efficient, and continuously improving production system.Nasdaq builds thoughtfully designed AI for board governance with PostgreSQL on Azure
Authored by: Charles Federssen, Partner Director of Product Management for PostgreSQL at Microsoft and Mohsin Shafqat, Senior Manager, Software Engineering at Nasdaq When people think of Nasdaq, they usually think of markets, trading floors, and financial data moving at extraordinary speed. But behind the scenes, Nasdaq also plays an equally critical role in how boards of directors govern, deliberate, and make decisions. Nasdaq Boardvantage® is the company’s governance platform, used by more than 4,400 organizations worldwide—including nearly half of the Fortune 100. It’s where directors review board books, collaborate in an environment designed with robust security, and prepare for meetings that often involve some of the most sensitive information a company has. In recent years, Nasdaq set out to modernize Nasdaq Boardvantage with AI, without compromising security and reliability. That journey was featured in a Microsoft Ignite session, “Nasdaq Boardvantage: AI-Driven Governance on PostgreSQL and Foundry.” It offers a practical look at how Azure Database for PostgreSQL can support AI-driven applications where precision, isolation, and data control are non-negotiable. Introducing AI where trust is everything Board governance isn’t a typical productivity workload. Board packets can run 400 to 600 pages, meeting minutes are legal records, and any AI-generated insight must be confined to a customer’s own data. “Our customers trust us with some of their most strategic, sensitive data,” said Mohsin Shafqat, Senior Manager of Software Development at Nasdaq. That trust meant tackling several core challenges upfront, including: How do you minimize AI hallucinations in a governance context? How do you guarantee tenant isolation at scale? How do you keep data regional across a global customer base? A cloud foundation built for governance Before adding intelligence, Nasdaq decided to re-architect Nasdaq Boardvantage on Microsoft Azure, using Azure Kubernetes Service (AKS) to run containerized, multi-tenant workloads with strong isolation boundaries. Microsoft Foundry provides the managed foundation for deploying, governing, and operating AI models across this architecture, adding consistency, security, and control as intelligence is introduced. At the data layer, Azure Database for PostgreSQL and Azure Database for MySQL became the backbone for governance data. PostgreSQL, in particular, plays a central role in managing structured governance information alongside vector embeddings that support AI-driven features. Together, these services give Nasdaq the performance, security, and operational control required for a highly regulated, multi-tenant environment, while still moving quickly. Key architectural choices included: Tenant isolation by design, with separate databases and storage Regional deployments to align with data residency requirements High availability and managed operations, so teams could focus on product innovation instead of infrastructure maintenance PostgreSQL and pgvector: Powering context-aware AI With that foundation in place, Nasdaq was ready to carefully introduce AI. One of the first AI capabilities was intelligent document summarization. Board materials that once took hours to review could now be condensed into concise, contextually accurate summaries. Under the hood, this required more than just calling an LLM. Nasdaq uses pgvector, natively supported in Azure Database for PostgreSQL, to store and query embeddings generated from board documents. This allows the platform to perform hybrid searches that combine traditional SQL queries with vector similarity to retrieve the most relevant context before sending anything to a language model. Instead of treating AI as a black box, the team built a pipeline where: Documents are processed with Azure Document Intelligence to preserve structure and meaning Content is chunked and embedded Embeddings are stored in PostgreSQL with pgvector Vector similarity searches retrieve precise context for each AI task Because this runs inside PostgreSQL, the same database benefits from Azure’s built-in high availability, security controls, and operational tooling – delivering tangible results, including a 25% reduction in overall board preparation time and internal testing shows 91–97% accuracy for AI-generated summaries and meeting minutes. From summaries to an AI Board Assistant With summarization working in production, Nasdaq expanded further. The team is now building an AI-powered Board Assistant that will help directors prepare for upcoming meetings by surfacing trends, risks, and insights from prior discussions. This introduces a new level of scale. Years of board data across thousands of customers translate into millions of embeddings. PostgreSQL continues to anchor this architecture, storing vectors for semantic retrieval while MySQL supports complementary non-vector workloads. Across Nasdaq Boardvantage, users are advised to always review AI outputs, and no customer data is shared or used to train external models. “We designed AI for governance, not the other way around,” Shafqat said. More importantly, customers trust the system because security, isolation, and data control were engineered in from day one. Looking ahead Nasdaq’s work shows how Azure Database for PostgreSQL can support AI workloads that demand both intelligence and integrity. With PostgreSQL at the core, Nasdaq has built a governance platform that scales globally, respects regulatory boundaries, and introduces AI in a way that feels dependable and not experimental. What started as a modernization of Nasdaq Boardvantage is now influencing how Nasdaq approaches AI across the enterprise. To dive deeper into the architecture and hear directly from the engineers behind it, watch the Ignite session and check out these resources: Watch the Ignite breakout session for a technical walkthrough of how Nasdaq Boardvantage is built, including PostgreSQL on Azure, pgvector, and Microsoft Foundry in production. Read the case study to see how Nasdaq introduced AI into board governance and what changed for directors, administrators, and decision-making. Watch the Ignite broadcast for a candid discussion on Azure Database for PostgreSQL, Azure HorizonDB, and what it takes to scale AI-driven governance.
cosmos_vnet_blocked error with BYO standard agent setup
Hi! We've tried deploying the standard agent setup using terraform as described in the https://learn.microsoft.com/en-us/azure/ai-foundry/agents/how-to/virtual-networks?view=foundry-classic and using the terraform sample available https://github.com/azure-ai-foundry/foundry-samples/tree/main/infrastructure/infrastructure-setup-terraform/15a-private-network-standard-agent-setup/code as a basis to give the necessary support in our codebase. However we keep getting the following error: cosmos_vnet_blocked: Access to Cosmos DB is blocked due to VNET configuration. Please check your network settings and make sure CosmosDB is public network enabled, if this is a public standard agent setup. Has anyone experienced this error?861Views8likes7CommentsUnable to publish Foundry agent to M365 copilot or Teams
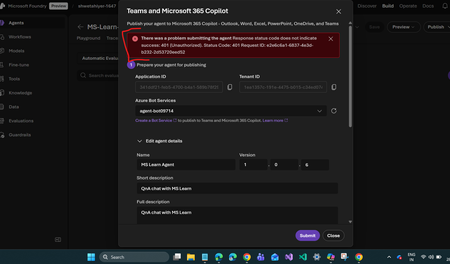
I’m encountering an issue while publishing an agent in Microsoft Foundry to M365 Copilot or Teams. After creating the agent and Foundry resource, the process automatically created a Bot Service resource. However, I noticed that this resource has the same ID as the Application ID shown in the configuration. Is this expected behavior? If not, how should I resolve it? I followed the steps in the official documentation: https://learn.microsoft.com/en-us/azure/ai-foundry/agents/how-to/publish-copilot?view=foundry Despite this, I keep getting the following error: There was a problem submitting the agent. Response status code does not indicate success: 401 (Unauthorized). Status Code: 401 Any guidance on what might be causing this and how to fix it would be greatly appreciated.Solved1.2KViews0likes3CommentsGet to know the core Foundry solutions
Foundry includes specialized services for vision, language, documents, and search, plus Microsoft Foundry for orchestration and governance. Here’s what each does and why it matters: Azure Vision With Azure Vision, you can detect common objects in images, generate captions, descriptions, and tags based on image contents, and read text in images. Example: Automate visual inspections or extract text from scanned documents. Azure Language Azure Language helps organizations understand and work with text at scale. It can identify key information, gauge sentiment, and create summaries from large volumes of content. It also supports building conversational experiences and question-answering tools, making it easier to deliver fast, accurate responses to customers and employees. Example: Understand customer feedback or translate text into multiple languages. Azure Document IntelligenceWith Azure Document Intelligence, you can use pre-built or custom models to extract fields from complex documents such as invoices, receipts, and forms. Example: Automate invoice processing or contract review. Azure SearchAzure Search helps you find the right information quickly by turning your content into a searchable index. It uses AI to understand and organize data, making it easier to retrieve relevant insights. This capability is often used to connect enterprise data with generative AI, ensuring responses are accurate and grounded in trusted information. Example: Help employees retrieve policies or product details without digging through files. Microsoft FoundryActs as the orchestration and governance layer for generative AI and AI agents. It provides tools for model selection, safety, observability, and lifecycle management. Example: Coordinate workflows that combine multiple AI capabilities with compliance and monitoring. Business leaders often ask: Which Foundry tool should I use? The answer depends on your workflow. For example: Are you trying to automate document-heavy processes like invoice handling or contract review? Do you need to improve customer engagement with multilingual support or sentiment analysis? Or are you looking to orchestrate generative AI across multiple processes for marketing or operations? Connecting these needs to the right Foundry solution ensures you invest in technology that delivers measurable results.164Views0likes0CommentsBuild Smarter with Azure HorizonDB
By: Maxim Lukiyanov, PhD, Principal PM Manager; Abe Omorogbe, Senior Product Manager; Shreya R. Aithal, Product Manager II; Swarathmika Kakivaya, Product Manager II Today, at Microsoft Ignite, we are announcing a new PostgreSQL database service - Azure HorizonDB. You can read the announcement here, and in this blog you can learn more about HorizonDB’s AI features and development tools. Azure HorizonDB is designed for the full spectrum of modern database needs - from quickly building new AI applications, to scaling enterprise workloads to unprecedented levels of performance and availability, to managing your databases efficiently and securely. To help with building new AI applications we are introducing 3 features: DiskANN Advanced Filtering, built-in AI model management, and integration with Microsoft Foundry. To help with database management we are introducing a set of new capabilities in PostgreSQL extension for Visual Studio Code, as well as announcing General Availability of the extension. Let’s dive into AI features first. DiskANN Advanced Filtering We are excited to announce a new enhancement in the Microsoft’s state of the art vector indexing algorithm DiskANN – DiskANN Advanced Filtering. Advanced Filtering addresses a common problem in vector search – combining vector search with filtering. In real-world applications where queries often include constraints like price ranges, ratings, or categories, traditional vector search approaches, such as pgvector’s HNSW, rely on multiple step retrieval and post-filtering, which can make search extremely slow. DiskANN Advanced Filtering solves this by combining filter and search into one operation - while the graph of vectors is traversed during the vector search, each vector is also checked for filter predicate match, ensuring that only the correct vectors are retrieved. Under the hood, it works in a 3-step process: first creating a bitmap of relevant rows using indexes on attributes such as price or rating, then performing a filter-aware graph traversal against the bitmap, and finally, validating and ordering the results for accuracy. This integrated approach delivers dramatically faster and more efficient filtered vector searches. Initial benchmarks show that enabling Advanced Filtering on DiskANN reduces query latency by up to 3x, depending on filter selectivity. AI Model Management Another exciting feature of HorizonDB is AI Model Management. This feature automates Microsoft Foundry model provisioning during database deployment and instantly activates database semantic operators. This eliminates tens of setup and configuration steps and simplifies the development of new AI apps and agents. AI Model Management elevates the experience of using semantic operators within PostgreSQL. When activated, it provisions key models for embedding, semantic ranking and generation via Foundry, installs and configures the azure_ai extension to enable the operators, establishes secure connections, integrates model management, monitoring and cost management within HorizonDB. What would otherwise require significant manual effort and context-switching between Foundry and PostgreSQL for configuration, management, and monitoring is now possible with just a few clicks, all without leaving the PostgreSQL environment. You can also continue to bring your own Foundry models, with a simplified and enhanced process for registering your custom model endpoints in the azure_ai extension. Microsoft Foundry Integration Microsoft Foundry offers a comprehensive technology stack for building AI apps and agents. But building modern agents capable of reasoning, acting, and collaborating is impossible without connection to data. To facilitate that connection, we are excited to announce a new PostgreSQL connector in Microsoft Foundry. The connector is designed using a new standard in data connectivity – Model Context Protocol (MCP). It enables Foundry agents to interact with HorizonDB securely and intelligently, using natural language instead of SQL, and leveraging Microsoft Entra ID to ensure secure connection. In addition to HorizonDB this connector also supports Azure Database for PostgreSQL (ADP). This integration allows Foundry agents to perform tasks like: Exploring database schemas Retrieving records and insights Performing analytical queries Executing vector similarity searches for semantic search use cases All through natural language, without compromising enterprise security or compliance. To get started with Foundry Integration, follow these setup steps to deploy your own HorizonDB (requires participation in Private Preview) or ADP and connect it to Foundry in just a few steps. PostgreSQL extension for VS Code is Generally Available We’re excited to announce that the PostgreSQL extension for Visual Studio Code is now Generally Available. This extension garnered significant popularity within the PostgreSQL community since it’s preview in May’25 reaching more than 200K installs. It is the easiest way to connect to a PostgreSQL database from your favorite editor, manage your databases, and take advantage of built-in AI capabilities without ever leaving VS Code. The extension works with any PostgreSQL whether it's on-premises or in the cloud, and also supports unique features of Azure HorizonDB and Azure Database for PostgreSQL (ADP). One of the key new capabilities is Metrics Intelligence, which uses Copilot and real-time telemetry of HorizonDB or ADP to help you diagnose and fix performance issues in seconds. Instead of digging through logs and query plans, you can open the Performance Dashboard, see a CPU spike, and ask Copilot to investigate. The extension sends a rich prompt that tells Copilot to analyze live metrics, identify the root cause, and propose an actionable fix. For example, Copilot might find a full table scan on a large table, recommend a composite index on the filter columns, create that index, and confirm the query plan now uses it. The result is dramatic: you can investigate and resolve the CPU spike in seconds, with no manual scripting or guesswork, and with no prior PostgreSQL expertise required. The extension also makes it easier to work with graph data. HorizonDB and ADP support open-source graph extension Apache AGE. This turns these services into fully managed graph databases. You can run graph queries against HorizonDB and immediately visualize the results as an interactive graph inside VS Code. This helps you understand relationships in your data faster, whether you’re exploring customer journeys, network topologies, or knowledge graphs - all without switching tools. In Conclusion Azure HorizonDB brings together everything teams need to build, run, and manage modern, AI-powered applications on PostgreSQL. With DiskANN Advanced Filtering, you can deliver low-latency, filtered vector search at scale. With built-in AI Model Management and Microsoft Foundry integration, you can provision models, wire up semantic operators, and connect agents to your data with far fewer steps and far less complexity. And with the PostgreSQL extension for Visual Studio Code, you get an intuitive, AI-assisted experience for performance tuning and graph visualization, right inside the tools you already use. HorizonDB is now available in private preview. If you’re interested in building AI apps and agents on a fully managed, PostgreSQL-compatible service with built-in AI and rich developer tooling, sign-up for Private Preview: https://aka.ms/PreviewHorizonDB.1.8KViews4likes0Comments