evaluation
45 TopicsInformation Extraction with Low-Inference-Cost Models: 85% F1 Gain via Foundry Interactive Training
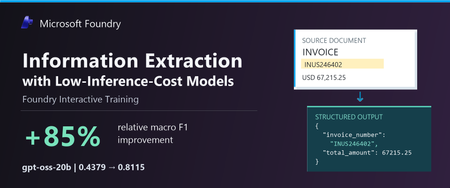
The task: turn documents into structured data Many business workflows need to turn documents into structured data. The model must find the right values, capture the requested records, and return output the next system can use. Long documents and repeated tables make this harder. We tested gpt-oss-20b and gpt-oss-120b to explore lower-cost alternatives to frontier models. In our baseline tests, both fell short on field coverage. gpt-oss-20b also declined the task or returned unparseable output. We wanted to see whether task-specific fine-tuning could improve these results. In Figure 1, we show an invoice that we held out from training. We can quickly spot the invoice number, customer, due date, and balance, but our application must map those values to the correct schema fields, preserve all 37 line items, and return complete, valid JSON. A wrong or missing value can trigger downstream errors or manual review, while invalid JSON can break the workflow altogether. We used schema-guided extraction. We gave the model document text and a JSON Schema defining the required fields, then asked it to return one JSON object. Our grader compared normalized field-path/value pairs with the expected answer, counting repeated occurrences. We measure precision as the share of extracted pairs that match the expected answer, and recall as the share of expected pairs we recover correctly. We use F1 to combine the two into one score, using their harmonic mean. F1 ranges from 0 to 1, with higher scores indicating better extraction. A wrong value hurts precision and can also hurt recall if the expected value remains unmatched. A missing value hurts recall. What changed after fine-tuning We evaluated the base and fine-tuned versions of gpt-oss-20b and gpt-oss-120b on the same 20 documents. Both improved their extraction F1. gpt-oss-20b rose from 0.4379 to 0.8115, and gpt-oss-120b rose from 0.6816 to 0.8573. gpt-oss-20b made the larger gain, with an 85.3% relative improvement after 100 GRPO steps. Fine-tuned gpt-oss-120b finished with the higher F1. Fine-tuning helped both models, but the size of the improvement differed. We also evaluated GPT-5.5, GPT-5.6-sol, and GPT-6-sol as reference models. They scored 0.9760, 0.9766, and 0.9764, respectively—still higher than our fine-tuned models. gpt-oss-20b reached 83.1% of GPT-5.6-sol’s reference F1. This is a substantial improvement for gpt-oss-20b and a promising starting point for further task-specific tuning. Our base and tuned scores are averaged across repeated evaluations, while the reference models used a different single-pass protocol. These reference scores provide useful context for the progress we made, with the evaluation differences noted above. These improvements make lower inference-cost base models worth a closer look. Table 1 compares published Azure inference prices. The pricing comparison is intended to provide inference-cost context only and should not be interpreted as a complete total-cost-of-ownership analysis, which would also include training, hosting, retries, and operational costs. Table 1. Extraction macro F1 and published Azure inference prices (USD per 1M tokens); GPT-5.5, GPT-5.6-sol, and GPT-6-sol are included as frontier-model references Model Macro F1 Azure input / 1M Azure output / 1M gpt-oss-20b 0.8115 $0.07 $0.30 gpt-oss-120b 0.8573 $0.15 $0.60 GPT-5.6-sol 0.9766 $4.00 $20.00 GPT-5.5 0.9760 $5.00 $30.00 GPT-6-sol 0.9764 $2.00 $10.00 Notes: Prices checked October 9, 2026, in USD; input rates are uncached. gpt-oss-20b prices are published fine-tuned inference rates for Regional deployments. gpt-oss-120b prices are base-model rates; its fine-tuned rates remain unconfirmed. Frontier prices use Global Standard pricing, with the short-context tier for GPT-5.6-sol and GPT-6-sol. These rates do not represent measured deployment costs for our experimental checkpoints. Token rates exclude training and hosting costs. F1 scores come from fine-tuned checkpoints for the two gpt-oss models and reference runs for the frontier models. All use the same 20 documents, but tuned scores average repeated evaluations while frontier references use a different single-pass protocol. We observed more parseable output and higher coverage We looked through gpt-oss-20b’s responses and found examples where it declined the task or said it could not finish. We tracked this with a “refusal-wording rate”: the share of responses where our grader detected an apology or cannot-complete language. This measures wording, not whether the model made a safety refusal. We tracked JSON parseability and field coverage separately, although these problems can overlap. After fine-tuning, the refusal-wording rate (Refusals) fell from 25% to zero; JSON parseability (Valid JSON) rose from 63.8% to 98.8%, and coverage rose from 47.1% to 94.9%. Valid JSON means our grader could read the response as an object or array. Coverage compares the number of predicted field/value pairs with the expected count, capped at 100%. Wrong or extra pairs can raise coverage, so we read it alongside F1 rather than treat it as a measure of correctness. Extraction quality and output behavior before and after fine-tuning on the same 20 documents. Bars show means across repeated evaluations. “Valid JSON” measures JSON parseability, not schema compliance or value correctness. “Refusal rate” measures detected refusal wording, not safety refusals. Higher is better except for refusal rate. Figure 4 shows how these measures changed during training. We repeated the full training run with a second seed. It reached 0.8101 F1, close to the headline run’s 0.8115. We ran four temperature-0 evaluations for each seed. Across all eight post-training evaluations, our grader detected no refusal wording. What we learned from the model comparison We saw different starting points and different gains between the two models. gpt-oss-20b had clearer output problems before training: it sometimes declined the task, returned unparseable JSON, or missed required information. After fine-tuning, we saw improvements in extraction F1, JSON parseability, and field coverage, along with less refusal wording. gpt-oss-120b started with fewer format problems. We detected no refusal wording, and 96.3% of its baseline responses were parseable JSON. But parseable output did not mean complete or correct extraction. After fine-tuning, its field coverage rose from 74.1% to 94.1%, and its F1 rose from 0.6816 to 0.8573. gpt-oss-20b made the larger F1 gain, while fine-tuned gpt-oss-120b finished with the higher F1. For us, the lesson is to measure the problem first. Try simpler, lower-cost changes, such as prompting, before committing to training. Then consider fine-tuning when your grader can reward the improvements your application needs. How we trained with Foundry Interactive Training We used the Foundry Interactive Training API [1] with 17 training documents, expected structured answers, and a Python grader. We followed the cookbook to connect our grader to Foundry’s managed generation and training operations. We ran 100 group relative policy optimization, or GRPO, steps and saved checkpoints for evaluation. For each document, we had gpt-oss-20b generates eight candidate answers. Our grader awarded partial credit for correct values and penalized invalid JSON. GRPO used the candidates’ relative scores to reinforce better answers. We used the expected answers only for grading. We did not include them in the inputs we gave the model during reinforcement training. The model had to produce its own answers, and the grader supplied the feedback. 5. Customers define the application outcome and quality bar; Foundry Interactive Training runs the post-training loop in Microsoft Foundry. How customers can use Foundry Interactive Training To try this approach, bring four ingredients: a supported base model, examples from your workload, expected outcomes, or another way to check the answers, and a Python grader. Your grader should measure what matters to the application—not just whether an answer looks convincing. Get connected. Request access to the Microsoft Foundry Interactive Training public preview [2] and connect the onboarding cookbook [3][4] to an assigned Foundry project. Separate your data. Build training, validation, and final test sets. Use validation data to choose checkpoints. Keep the final test set for an independent check, with new sources and document structures where possible. Build your grader. Implement a grader that rewards the desired outcome. For our extraction task, we checked normalized field-path/value pairs and penalized unparseable JSON. Run a bounded experiment. Set a training budget, inspect the training signal, and compare saved checkpoints on the validation set. Once you choose a checkpoint, evaluate it on the untouched final test set. Evaluate and prepare for deployment. Use session sampling to test your LoRA adapter on held-out prompts and compare it with the baseline. Save checkpoints so you can continue experimenting. Before using the model in an application, confirm the supported deployment path, model compatibility, and serving costs. Takeaway With Foundry Interactive Training, we improved extraction F1 for both gpt-oss-20b and gpt-oss-120b. We brought our task examples and a Python grader, and Foundry managed the generation and training loop. gpt-oss-20b made the larger gain, while fine-tuned gpt-oss-120b reached the higher F1. We did not match the frontier references, but our results show why task-specific fine-tuning is worth exploring before switching to a higher-priced model. The final choice should depend on independently tested quality and the full cost of deployment. Reference [1] https://github.com/microsoft-foundry/fine-tuning [2] What is interactive training (preview) in Microsoft Foundry? - Microsoft Foundry | Microsoft Learn [3] Interactive Training - Public Preview Intake Form [4] https://github.com/microsoft-foundry/fine-tuning/tree/main/interactive_training137Views0likes0CommentsClosing the AI Agent Governance Gap with Microsoft Foundry
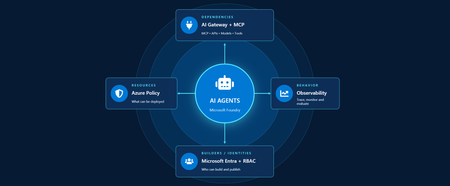
Developers are shipping agents faster than security teams can catalog them. As organizations move beyond pilots and begin operating dozens or hundreds of agents, one question keeps coming up: how do we actually get visibility into our AI agents across our environment? In this article, we'll walk through how Azure services can help establish visibility, guardrails, and cost accountability across your AI estate. Governance for AI happens across four layers: Resources – who can create new AI resources Builders – who can develop and publish agents in a certain scope Behavior – how agent outputs are evaluated, monitored, and governed Dependencies – what models, tools, APIs, and MCP servers agents can interact with Most organizations already have governance controls for identities, networking, and compliance. The challenge isn't creating new controls. It's connecting existing controls into an operating model that works for AI agents. Below we walk through each area and go a bit deeper on how to close the gap. Setting up boundaries with Azure Policy First, let's start in the Azure portal with Azure Policy. Azure Policy lets you set guardrails on what can be deployed in your environment and flags or blocks anything that doesn't comply. For AI workloads, the built-in definitions range from limiting models that people in your organization can deploy to locking down the network through enabling private endpoints. Some policies you get started with: Foundry model deployments should only use approved models: Restricts deployments to models or publishers your organization has explicitly approved Foundry model deployments should meet eligibility requirements (preview): Applies rules based on model attributes like preview vs. GA status and distribution source Azure AI Services resources should have key access disabled: Makes Microsoft Entra ID the only entry point The full list of policies related to Azure AI Services are available here: List of built-in policy definitions - Azure Policy | Microsoft Learn Why this comes first: Policy checks resources before they are created, so it proactively keeps your environment aligned with your standards. Implementing role-based access control (RBAC) Once these boundaries are in place, the next step is RBAC. Setting RBAC up early ensures that people and identities building agents have the right scope for what they actually need to do. Foundry roles only apply when you authenticate using Microsoft Entra ID. If you're using key-based authentication instead, the key grants full access with without role restrictions. API keys are convenient for quick development usage but when moving towards production, Microsoft Entra ID is the preferred method. Roles can be assigned at three scopes: the Foundry resource, a Foundry project, or an individual agent itself. Below is an example of how different personas within organization can map to a certain scope for creating and building agents with Foundry. Here's how each role in the diagram compares, from least to most privileged: Role Privilege Level What it does in Microsoft Foundry Foundry Agent Consumer Least Interact with agent endpoints in a project. This is your least-privilege role for people who only need to use agents. Foundry User Low Grants reader access to the Foundry project, the Foundry resource, and data actions for your Foundry project. Least-privilege access role for developers building and testing agents. Foundry Project Manager Medium This role lets you perform management actions on Foundry projects, build and develop with projects, and conditionally assign the Foundry User role to other user principals. Foundry Account Owner Higher Grants full access to manage Foundry projects and resources, and lets you assign the Foundry User role to other user principals. Foundry Owner Highest Grants full access to manage Foundry projects and resources to build and develop with projects. This role can also assign the Foundry User, ACR, and monitoring roles to users in the environment. Source: Role-based access control for Microsoft Foundry - Microsoft Foundry | Microsoft Learn For the agent resources themselves, assign managed identities rather than API keys since it lowers the risk of having compromised credentials. Note if you're scripting RBAC permissions: these roles were recently renamed from Azure AI User, Azure AI Owner, Azure AI Account Owner, and Azure AI Project Manager. The role IDs and permissions didn't change, so use the role definition GUID in your code to avoid issues while the rename rolls out. Observability in Microsoft Foundry Governance requires more than access control. Organizations also need evidence of how agents are being used. Observability provides the audit trail needed to investigate incidents, understand usage patterns, and track costs. The Foundry Control Plane brings these observability and governance tools together in one place, alongside services like Azure Monitor, Microsoft Entra, Microsoft Purview, and Azure Policy. In the Foundry portal, tracing is a good starting point. Once you connect an Application Insights resource to your project, Foundry turns on tracing automatically so every run, including the ones you test in the playground, is logged. After it is completed, you can search by Response ID or Trace ID to see the conversation history, token usage, run steps, tool calls, and inputs and outputs between the user and the agent. For more granular queries, you can write KQL to dive into individual agent runs or use the prebuilt Grafana dashboards in Azure Monitor. With client-side tracing, you can also export traces to observability tools you may already use, such as Datadog or Jaeger. Note: Permissions required for viewing this telemetry requires the Log Analytics Reader role on the connected Application Insights resource, and Privileged Monitoring Data Reader on top of that if the underlying Log Analytics tables are protected. Alongside all of these monitoring features, every agent comes with content safety guardrails and evaluations let you test and optimize performance before and after you publish your agents. When agents get published to Microsoft Teams and Microsoft 365 Copilot, Microsoft 365 admins can approve usage requests. These requests can be further scoped to a limited group for pilot testing/department usage or the full organization. Adding an AI gateway Observability tells you what your agents are doing, but how do you actually control them? This is where Azure API Management comes in. Once you have more than one agent, model deployment, or multiple teams consuming them, you need a single enforcement point between the agents and the resources they call. Adding Azure API Management in front of Microsoft Foundry gives you: Rate limiting and load balancing across regions and model deployments Consistent authentication and quota policies for model and tool traffic Usage tracking per team or cost center so you can accurately charge back to different departments Governed access to your custom and remote MCP servers Note: When choosing MCP servers, start with trusted, enterprise supported sources (GitHub, Microsoft, internally developed servers, etc.) that have documented security controls, enterprise authentication, clear ownership, and least-privilege permissions. Treat community MCP servers as untrusted until they have undergone a formal security review and are verified by organizations. Adding an AI gateway completes the governance picture. Azure Policy governs what can be deployed. RBAC governs who can build and manage agents. Observability provides evidence of how agents behave in production. The AI gateway extends governance into runtime, controlling how agents interact with models, tools, and external systems. Combined, these layers help organizations move beyond simply building agents to operating them responsibly at scale. Extend governance across the wider estate A few directions to take this further: MCP registry in Azure API Center – As MCP usage grows, you can create an approved inventory of MCP servers and APIs that can be used across an organization. Microsoft Agent 365 – Microsoft's enterprise control plane for AI agents. It gives every agent its own Microsoft Entra Agent ID and published Foundry agents sync to its registry automatically. This gives your IT team one place to run access reviews, lifecycle policies, and owner attestation across every agent in the tenant, including shadow agents discovered outside Foundry. Copilot Studio – when you add an MCP tool, you can point it at the API Management URL instead of the direct remote endpoint to gain additional observability through the gateway. GitHub Copilot – you can apply the same AI gateway-fronted MCP registry, applied to the developer side. Microsoft Purview – data classification, DLP, audit, and AI interaction governance across the wider estate. Where to go next Looking for a quick start? Turn on the three Azure Policy definitions above in audit mode against a non-production subscription and see what gets flagged that is out of compliance. Ready to design the end-to-end pattern? Take a look at this Cloud Adoption Framework guidance on AI governance and governing Azure platform services for AI. Want to go deeper on agent observability? Start with these articles around Application Insights integrations with Foundry: Use Insights in Microsoft Foundry and Monitor AI Agents with Application Insights Governing AI agents doesn't require starting from scratch. The identity, policy, monitoring, and cost controls you already use for the rest of your Azure estate can extend to AI workloads. Start with one layer, connect the next, and build a governance foundation that grows with your AI adoption.588Views3likes0Comments
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.742Views2likes0CommentsBeyond the Trace: The Science of Insight Quality
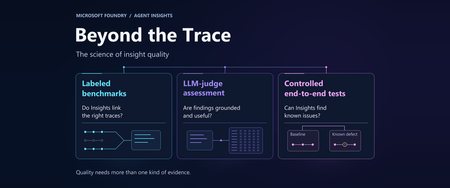
Co-authors and reviewers: Morteza Ziyadi, Hanchi Wang, Han Che, Billy Hu, Sean Gayler, Nishal Dsilva, Avinav Jami, Ankit Singhal, Augustus Arthur TL;DR. Insights in Foundry turns recurring agent behavior into evidence-linked findings developers can review and act on. We evaluate trace linkage, finding quality, and detection of known issues using labeled benchmarks, LLM-judge assessment, and controlled end-to-end tests. What is an Insight? An Insight is a reviewable finding about recurring agent behavior. It brings together an explanation, supporting trace evidence, and a possible next step, helping developers investigate a pattern rather than inspect each execution in isolation. Depending on the available evidence and supported configuration, an Insight can include: Part of an Insight What it gives the reviewer Title and description The recurring behavior and an evidence-based explanation of a possible cause. Linked traces The broader group of traces associated with the finding. Highlighted traces Representative examples to open and check against the explanation. Category, severity, and status Context for triaging the finding, not a substitute for a risk assessment. Agent version and recency Which version is represented and when the finding was created. Proposed action or fix An investigation or improvement path; concrete proposals depend on the configuration. Figure 1. An Insight detail view in Microsoft Foundry, cropped from public Microsoft Learn documentation. The description, evidence, and proposed fix support human review. This UI illustration is not a benchmark result; the source link provides a full-size view. UI source and field definitions: Insights in Foundry documentation. From trace search to an actionable review queue Production agents can generate thousands of traces containing model calls, tool calls, latency, token usage, errors, and final responses. Observability shows what happened, while evaluations test criteria a team already knows to measure. The harder problem is discovering repeated behavior that the team did not know to predefine. Insights in Foundry analyzes traces from the Application Insights resource connected to a Foundry project and organizes recurring behavior into reviewable Insights. Depending on the evidence and supported configuration, an Insight can include representative traces, affected agent versions, severity, an explanation of a possible cause, and a recommended next action. Concrete prompt or code proposals are available only for supported agent types and configurations; other Insights provide general investigation or remediation guidance. Insights in Foundry is now available in public preview. It analyzes production traces to surface recurring behaviors and regressions with supporting evidence and suggested areas for investigation or improvement. Developers remain in control: review the cited traces and validate proposed changes through normal evaluation and deployment practices. During public preview, we will continue expanding the experience based on customer feedback. To make this concrete, Figure 2 maps 220 inputs from TraceElephant, a public agent-trace benchmark, to seven generated Insights. Figure 3 examines one linked trace. Figure 2. Recorded links from 220 public TraceElephant inputs to seven generated Insights in the September 17 benchmark. The 80-input finding includes the looping trace examined in Figure 3. Titles are editorial paraphrases; the layout is editorial, not a product screenshot or a validation of each diagnosis. Figure 3. A public TraceElephant trace contains 54 model calls; steps 26, 30, 34, 38, 42, 46, and 50 repeat an identical extraction plan. The September 17 benchmark run of the production pipeline links this trace to a finding about missing progress-aware termination. Wording is paraphrased; this is an illustration, not product UI. The proposed intervention still needs evaluation. Three complementary ways to evaluate Insight quality Insight quality involves which inputs a finding links, how well it explains the evidence, and whether it identifies known issues in controlled tests. We combine labeled trace evaluation, unlabeled finding assessment, and controlled end-to-end testing. These are complementary sources of evidence, not mutually exclusive dataset categories. Evidence Question Assessment / results Labeled trace evaluation Do Insights link inputs that reference annotations mark as failing? Reference labels; trace precision and trace recall (%). Unlabeled finding assessment Are generated findings grounded and useful? Eight-dimension LLM judge; mean score (1-5). Controlled end-to-end tests Do Insights identify known injected issues? Known issues and healthy baselines; detections, misses, unsupported findings, duplicates, and unscored cases. Here, 'unlabeled' means reference failure labels are not used for the evaluation; the sources can still contain annotations or reference answers. Public versus internal describes where data comes from, not how it is evaluated. LLM judges can also assess findings from labeled or controlled scenarios. Labeled evaluation: Do Insights link the right traces? Trace precision: among unique benchmark inputs linked by at least one generated Insight, the fraction marked as failing. This measures discrimination only when a dataset includes healthy inputs, and it does not validate the diagnosis. Trace recall: the percentage of failure-labeled benchmark inputs linked by at least one generated Insight. It does not measure how many distinct failure modes were discovered. We evaluated the production pipeline on the same 746 benchmark inputs (653 failure-labeled) on September 15, 16, and 17, 2026. Repeating these inputs does not create 2,238 distinct examples. The six benchmark corpus slices come from public agent-trace research datasets with human reference annotations: AgentRx (Tau-bench retail), AgentRx Magentic-One, TRAIL, AgentErrorBench, TraceElephant, and the MAST-Data human subset. AgentErrorBench is the annotated failure-trajectory dataset released with AgentDebug, a framework for detecting and recovering from agent failures. The two AgentRx slices come from the same public release. The benchmark uses selected and normalized inputs from these releases, not a representative sample of customer production traffic. For each dataset, the chart shows daily generated-Insight counts and trace recall. The table reports equal-weight means of daily trace precision and recall. These datasets support ongoing development; results depend on the dataset and model used. Labeled results Figure 4. Generated Insight count versus trace recall for all six public corpus slices. Each point is one daily run; labels retain values where markers overlap. Recall measures linkage to failure-labeled inputs, not diagnosis correctness. Three-day mean precision and recall follow in the table. Dataset Inputs/day Failure-labeled/day Linked/day range Mean trace precision Mean trace recall AgentRx (Tau-bench retail) 102 29 43-45 37.8% 57.5% AgentRx Magentic-One 58 44 54-57 75.3% 94.7% TRAIL 148 143 139-140 96.9% 94.6% AgentErrorBench 200 200 194-196 100.0%** 97.3% TraceElephant 220 220 218-220 100.0%** 99.7% MAST-Data (human subset) 18 17 14-16 93.3% 82.4% ** When every input is failure-labeled, 100% trace precision cannot measure false-positive control. What the labeled results show High precision can reflect the corpus base rate. AgentErrorBench and TraceElephant contain only failure-labeled inputs, so their measured precision is 100% by construction. TRAIL, AgentRx Magentic-One, and the MAST subset also contain mostly failures; their precision values are close to their underlying failure-label prevalence. Read precision beside trace recall and each dataset's label prevalence rather than as a standalone quality score. AgentRx (Tau-bench retail) is the clearest mixed-traffic stress test. Only 29 of 102 inputs were failure-labeled. Across the three days, trace precision was 43.2%, 37.8%, and 32.6%, averaging 37.8%; trace recall was 65.5%, 58.6%, and 48.3%, averaging 57.5%. Daily linked counts were 44, 45, and 43, including 19, 17, and 14 labeled failures respectively. These daily rates are averaged before rounding. Some linked inputs without failure labels could contain issues outside the reference labels, such as cost or latency, but this benchmark cannot confirm that. Trace precision and trace recall measure whether Insights link inputs that reference annotations mark as failing. They do not establish whether an explanation is correct or a proposed action is useful. Our unlabeled evaluation examines those qualities using an eight-dimension LLM judge. Unlabeled evaluation: Are the findings grounded and useful? For this evaluation, a separate LLM judge scores generated Insights against the supplied input evidence, without using reference failure labels to compute precision or recall. These scores are automated assessments produced by an LLM judge. They are not human ratings and do not establish that a proposed action will improve the agent. This evaluation covers PUPA, FailSafeQA, tau2-bench, synthetic scenarios, and an internal production dataset for the monitoring dashboard agent compiled from Microsoft employee usage. These sources are normalized into benchmark inputs; not every input is a complete execution trace. The eight-dimension judge rubric Each generated Insight receives a score from 1 to 5 on eight dimensions. The rubric separates the quality of the explanation, the importance of the issue, and the usefulness of the suggested action: Dimension Question the judge considers Actionability Does the Insight tell a developer what to investigate, evaluate, or change next? Specificity Does it name concrete behavior, tools, or prompt elements rather than offer generic advice? Novelty Does it surface a pattern beyond an obvious dashboard signal? This is an estimate, not a measurement of what a team already knows. Correctness Is the claim supported by the supplied evidence? Severity calibration Does the assigned severity match the evidenced impact? Impact How consequential does the underlying issue appear, rather than just how well it is described? Fix specificity Does the proposed fix identify an exact asset or behavior to change? Fix applicability Is that proposed change plausibly on target for the issue? For example, a concrete next step earns a stronger actionability rating than generic advice. Severity calibration and impact are deliberately separate: a minor issue can have a well-calibrated severity label without being high-impact. Fix applicability is judged from the proposal and evidence; the fix is not executed as part of this scoring. Unlabeled results Results compiled from two recent benchmark runs cover 4,496 inputs and 40 generated Insights. Every emitted Insight in these selected snapshots was scored with the same judge rubric. Each Insight's overall score is the mean of its eight dimension scores; the table then averages those overall scores within each dataset. We do not combine datasets into one quality score. Dataset Inputs Insights scored Mean judge score (1-5) PUPA 901 5 3.53 FailSafeQA 1,101 11 3.57 Monitoring dashboard agent (internal) 1,342 4 3.88 tau2-bench 1,112 16 2.84 Synthetic scenarios 40 4 3.81 These are per-dataset snapshots, not a controlled comparison of dataset difficulty or pipeline versions. Small Insight counts and grading choices, such as grouped versus individual judging, make these protocol-specific diagnostics rather than stable absolute ratings. Automated judge scores are not precision or recall, human ratings, or measured improvements after applying a fix. The dimension-level scores make the weak spots more concrete. Fix specificity was the lowest-scoring dimension in four of the five snapshots, with means from 2.00 to 2.64. For tau2-bench, correctness was lowest at 2.25: a signal to review whether claims are supported by the supplied evidence. Making a next step more concrete and grounding a diagnosis more carefully are different improvement targets. What the public findings look like The examples below connect generated findings to concrete input evidence: an arithmetic inconsistency, a question/answer mismatch, and a payment allocation that exceeds the available balance. They are selected illustrations, not a representative sample of the 40 scored Insights. Figure 5. Three illustrative findings, with one checked input per finding. Titles and evidence summaries are editorial paraphrases. PUPA is a normalized QA record; FailSafeQA normalization pairs a perturbed question with the original answer, creating the displayed mismatch. Neither is a new agent execution. Tau2-bench shows a recorded tool interaction. These examples are not a representative quality sample. Public input sources: PUPA; FailSafeQA; tau2-bench. Controlled end-to-end tests: Can Insights find known issues? Dataset benchmarks are complemented by tests with healthy baseline agents and versions containing predefined defects. The framework generates traffic, runs Insights on the resulting traces, and compares the findings with the known issues and supporting evidence. It separately tracks detections, misses, unsupported findings, and duplicates. Cases with incomplete evidence remain unscored rather than counting as passes or misses. The September 23 hosted-agent report, used here as a concrete illustration, covered finance, travel, and support-ticket scenarios. Of 12 expected issues, 11 were scorable and 10 were detected. All three scorable healthy baselines had no confirmed unsupported findings. The figure shows the full outcome counts, including the missed and unscored cases. This end-to-end framework is separate from the 40-input synthetic-scenarios dataset in the unlabeled results. Figure 6. Controlled tests exercise healthy baselines and known defects through the Insights pipeline. The September 23 report records 10 detections among 11 scorable expected issues, one additional unscored issue, and no confirmed unsupported findings on three scorable baselines. No confirmed unsupported findings (noise) or duplicate findings were reported in the evaluated subset. This illustrative snapshot is not a representative product-wide rate. A broader view of quality Trace selection and rubric review are part of a broader quality framework. Category agreement is an exploratory benchmark diagnostic, not an assessment of the portal's category labels. Controlled scenarios also check for unsupported or duplicate findings. Figure 7. Five complementary quality questions. The labeled results above measure trace precision and trace recall; the unlabeled results assess findings with an LLM judge. Category agreement is an internal diagnostic, while controlled scenarios check noise and duplication. How we track quality over time Labeled benchmarks, unlabeled assessment, and controlled tests feed recurring quality reports and human investigation. Test inventories and assessment conditions can change, so daily scores are not automatically a comparable improvement trend. The reported results do not establish longitudinal recurrence or deduplication performance across runs. In the portal, Give feedback lets users report incorrect findings, categories, severity, grouping, or duplication. Start with scenarios whose expected failures and healthy controls are known. Track detection, trace precision, categorization, severity, distinctness, evidence grounding, and action quality instead of relying on one score. Review changes to data, models, prompts, and evaluation contracts as changes to the measurement system. Investigate weak results and newly reported failure patterns rather than tuning only for an aggregate. Keep human review in the loop, because benchmark labels and automated graders cannot determine business impact or remediation correctness. How practitioners should interpret an Insight Validate each Insight before acting on it. Microsoft Learn recommends this review sequence: Confirm the affected workflow, agent version, category, severity, and time. Open the highlighted traces and verify that the cited behavior is present. Compare problematic examples with healthy traces to test whether the grouping and likely cause are plausible. Decide whether the issue belongs to the agent, a tool, a model endpoint, a data source, or the platform. Turn confirmed recurring behavior into evaluation coverage, an optimization objective, owner routing, or a monitored no-action decision. An empty result does not prove that an agent is healthy, and a large linked-trace count does not prove business impact. Quality depends on representative traces, complete telemetry, a supported analysis model, and careful human validation. Get started Start with the Insights in Foundry documentation for prerequisites, portal steps, evidence-review guidance, SDK examples, pricing considerations, and preview limitations. Prerequisites include a connected Application Insights resource, recent representative traces, a supported GPT-5-or-newer Judge model deployment, and the required role assignments. Insight generation, including scheduled runs, uses your model deployment and can incur model charges. See the current documentation for the latest supported agents, models, regions, limits, pricing, and UI guidance. Python samples: on-demand Insights and scheduled Insights. Closing thoughts Agent quality work often starts with a simple question: what is repeatedly going wrong that we did not know to test? Insights in Foundry is designed to help teams answer that question with evidence-linked findings and a reviewable next step. Measuring those findings requires explicit definitions, diverse data, honest treatment of weak results, and human judgment where automated metrics stop. Labeled trace evaluation, unlabeled rubric assessment, and controlled end-to-end tests answer complementary questions. Newly observed patterns can then inform the next round of evaluation and review.546Views0likes1CommentVoice agents in Foundry Agent Service: architecture, trust boundaries, and real-audio latency
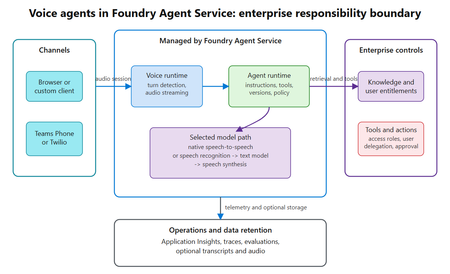
Assess where voice agents in Foundry Agent Service simplify the runtime, where enterprise trust boundaries remain, and what a 300-turn real-audio benchmark reveals about latency across six configurations.378Views0likes0CommentsEvaluate More, Spend Less: Batching Microsoft Foundry Evaluators for Efficient Evaluation
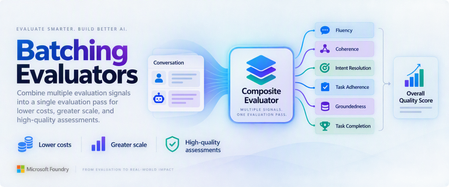
Authors: Salma Elshafey, Ali Mahmoudzadeh, Kayla Ames, Ahmad Qardahji, Vivek Bhadauria, Morteza Ziyadi, April Kwong A single agent trajectory may need to be evaluated for groundedness, coherence, instruction following, task completion, and correct tool use. In a conventional pipeline, each evaluator receives the same messages, tool calls, tool results, and tool definitions in a separate model call. As trajectories grow, evaluation repeatedly pays to process the same context. Can one LLM judge call apply five or six evaluators without losing the signal that makes evaluation useful? This study tests a simple design: send the shared context once and ask one composite evaluator to score several criteria in the same call. In summary: On 100-row quality and tool use samples, composite evaluation required 5-6x fewer model calls, reduced total input-token use by 61.25–71.07%, completion tokens by 46.63–63.89%, and measured run wall time by 35.74–46.10%. Across the tested workloads, frontier judge models maintained stable quality across several high-value dimensions. The results support composite evaluation as a cost-efficient default, with targeted individual evaluation for workload-sensitive rubric criteria. Why Evaluation Becomes Expensive Evaluating a single conversation rarely involves just one evaluation dimension. A typical assessment examines multiple dimensions of quality, such as whether the response is coherent, follows instructions, completes the user's task, remains grounded in available evidence, and uses tools correctly. Because each dimension is typically evaluated through a separate prompt and model call, the same conversation trajectory, tool calls, tool outputs, and tool definitions are processed repeatedly. As a result, cost grows with both the number of evaluation criteria and the amount of shared context, making long agent trajectories especially expensive to evaluate. The Composite-Evaluator Approach Rather than evaluating each dimension independently, composite evaluation scores multiple criteria within a single judge-model call, allowing the shared context to be processed once instead of repeatedly. We built two composite evaluators. The Output Quality Evaluator The Output Quality Evaluator scores six Microsoft Foundry evaluators in one LLM call: Evaluator Question Fluency Is the response clear and well formed? Coherence Is it logically consistent with the conversation? Intent Resolution Did the assistant understand the user's goal? Task Adherence Did it follow the user's instructions? Groundedness Are its claims supported by the available evidence? Task Completion Did it complete the requested task? Tool Use Quality Evaluator The Tool Use Quality Evaluator scores five Microsoft Foundry evaluators in one LLM call: Evaluator Question Tool Call Accuracy Was the tool call correct overall? Tool Call Success Did the invocation succeed? Tool Input Accuracy Were the arguments correct? Tool Output Utilization Did the response use the tool output correctly? Tool Selection Was the appropriate tool selected? Each composite prompt includes the shared trajectory and tool definitions once, followed by the full definition, rating scale, and applicability rules for every evaluator. It instructs the judge to assess each evaluator independently so that one verdict does not bias another. The judge returns structured results for each criterion, including a score, rationale, and applicability status. For multi-turn evaluations, it can also identify the earliest turn where a failure occurred. How We Validated Evaluator Quality The study compares individual and composite evaluators across: Two modes: Single-Turn and Multi-Turn. Nine judge models: GPT-4o, GPT-5.4, GPT-5.4 mini, GPT-5.6 Luna, GPT-5.6 Sol, GPT-5.6 Terra, DeepSeek V4 Flash, DeepSeek V4 Pro, and Grok 4.1 Fast Reasoning. Multiple datasets, as shown in the table below Dataset Mode Rows Primary validation target Reference labels Internal quality set Single-Turn and Multi-Turn 283 Six quality evaluators Existing per-evaluator labels Internal tool use set Single-Turn and Multi-Turn 200 Five tool use evaluators Existing per-evaluator labels BFCL v4 Multi-Turn 200 Task Completion, Tool Call Accuracy, and failed-turn localization Deterministic state and tool-call checks AgentIF Multi-Turn 148 Task Adherence Constraint-level majority-vote reference FaithDial Multi-Turn 300 Groundedness Faithful versus hallucinated responses FED Multi-Turn 125 Coherence Five-annotator human scores Tau-Voice Multi-Turn 278 Task Completion Reward-derived completion labels AgentRx tau_retail Multi-Turn 29 Failed-turn localization Human failure annotations We measured several distinct properties: Input tokens, output tokens, model calls, and latency Accuracy, macro-F1, and Cohen's kappa where labels were available Agreement and correlation structure between individual and composite modes Repeatability across four evaluation runs Finding 1: Composites Cut Input Tokens by 61.25–71.07% and Latency by 35.74–46.10% We measured cost and latency on matched 100-row Single-Turn samples: one for Output Quality and one for Tool Use, comparing parallel individual evaluators with one composite evaluator per row. For each row, evaluator context includes the query and response, any tool calls and results, and the serialized tool definitions. Note: Single-turn means that the evaluator's focus is the last agent response only, but the entire conversation history is passed to the evaluator as context. Trajectory Length in the Cost Sample The log-scale distributions show that most rows clustered around a few thousand tokens, with a smaller number of substantially longer trajectories. In both samples, longer evaluator contexts produced larger absolute token savings. The Measured Cost Reduction Across the sample: Repeated context is the main saving. Total input-token volume fell from 2,058,930 to 797,843 for Output Quality, a 61.25% reduction, and from 2,036,122 to 589,097 for Tool Use, a 71.07% reduction. Uncached input fell by 57.51% and 53.29%, respectively. For Output Quality, 52.72% of composite input tokens were cached versus 56.88% across the individual suite; for Tool Use, the figures were 46.22% versus 66.69%. However, the composites still processed substantially fewer tokens overall. Call volume collapses. Output Quality fell from 600 individual evaluator calls to 100 composite calls. Tool Use fell from 494 calls to 100. In six rubric-row combinations, native applicability rules legitimately returned no score, such as when there was no tool call to evaluate; those skips explain why the individual Tool Use baseline is below 500. Measured runs finish sooner. Output Quality wall time fell from 504.41 seconds to 324.12 seconds, a 35.74% reduction, while Tool Use fell from 536.95 seconds to 289.42 seconds, a 46.10% reduction. Per sample row, that is 5.044 to 3.241 seconds for Output Quality and 5.369 to 2.894 seconds for Tool Use. Completion tokens fell by 46.63% and 63.89%, respectively. On the quality sample, the composite used 797,843 total input tokens and 36,919 completion tokens, compared with 2,058,930 and 69,180 for parallel individual evaluation. On the tool use sample, the composite used 589,097 total input tokens and 28,358 completion tokens, compared with 2,036,122 and 78,522. These are measured run totals, not prompt-length estimates. The broader experiments showed the same benefit. The full six-evaluator rubric Single-Turn study used about 68% fewer input tokens, while the 283-row Multi-Turn quality study used about 77% fewer: 28,715 rendered input tokens per row for a six-call equivalent versus 6,608 for the composite call. Exact currency savings depend on model and deployment pricing, but batching consistently removed duplicated input and round-trip overhead. Finding 2: Quality Tradeoffs Depend on Rubric and Judge Model Output Quality Rubric Benchmark Results On the internal Single-Turn quality set, composite Task Adherence accuracy improved for every judge, while Task Completion remained close to individual evaluation. External Multi-Turn benchmarks showed a more varied pattern across rubric, judge, and workload. This figure reports Δκ = κComposite - κIndividual: blue favors composite evaluation and orange favors individual evaluation. The mixed directions reinforce the need to validate the selected rubric and judge on production-like data. BFCL provided the strongest labeled Multi-Turn example for Task Completion. With GPT-5.6 Luna, the composite evaluator reached macro-F1 0.848 and κ = 0.696, compared with 0.836 and 0.672 for the individual evaluator. Across the other judges, composite and individual Task Completion remained close for Sol, Terra, and DeepSeek V4 Flash, while results for DeepSeek V4 Pro and Grok 4.1 Fast favored individual evaluation. Tool Use Quality Rubric Benchmark Results The five-rubric tool composite was evaluated on production-style tool traces. Each row carries ground truth for one source rubric, so the table reports accuracy on the available per-evaluator subsets. Judge Tool Call Accuracy Tool Call Success Tool Input Accuracy Tool Output Utilization Tool Selection gpt-4o 0.800 0.902 0.850 0.800 0.878 gpt-5.4 0.800 0.902 0.775 0.737 0.829 gpt-5.4-mini 0.750 0.902 0.725 0.763 0.756 gpt-5.6-luna 0.914 0.902 0.848 0.775 0.901 gpt-5.6-sol 0.886 0.902 0.750 0.743 0.854 gpt-5.6-terra 0.857 0.902 0.750 0.794 0.854 DeepSeek-V4-Flash 0.775 0.902 0.800 0.848 0.854 DeepSeek-V4-Pro 0.800 0.878 0.800 0.789 0.902 grok-4-1-fast-reasoning 0.946 0.902 0.925 0.745 0.823 Across the production-style corpus, the composite reached 0.75-0.95 accuracy across the five rubric criteria. The results show model-specific strengths: Grok 4.1 Fast led Tool Call Accuracy and Tool Input Accuracy, DeepSeek V4 Flash led Tool Output Utilization, and DeepSeek V4 Pro led Tool Selection. Tool Call Success remained tied at 0.902 for most judges. Luna remained among the strongest overall, but no single judge dominated each of the rubric criteria. Classification Accuracy On the truly multi-turn BFCL benchmark, Tool Call Accuracy is the only tool rubric criterion with native ground truth. GPT-5.6 Terra led the single-run panel at 0.864 macro-F1, followed by GPT-5.6 Sol at 0.858 and GPT-5.6 Luna at 0.828. Other models showed lower results, with Grok 4.1 Fast at 0.626, DeepSeek V4 Pro at 0.625, and V4 Flash at 0.521. This shows that with the correct model, the composite evaluator can classify overall tool-call correctness on full conversations as well as production-style traces. Failure Localization The same BFCL run also tested where failures occurred. GPT-5.6 Terra led at 0.78 member-any failed-turn localization: in 78% of failing conversations, the turn predicted by the Tool Call Accuracy rubric criterion matched at least one turn in BFCL's set of failing turns. It produced 22 false alarms across 75 passing conversations. GPT-5.6 Sol reached 0.75 member-any, and GPT-5.6 Luna reached 0.74. The Tool Selection channel with Luna provided a high-precision secondary signal, identifying a failing turn in 50% of failures with only 3 false alarms. To test whether localization generalizes beyond mechanically checked BFCL traces, we also used the 29-row AgentRx tau_retail set with human failure annotations. On the eight in-scope tool-mechanics failures, Sol localized 8 of 8 root causes, while Terra and Luna localized 7 of 8. Meanwhile, Grok 4.1 Fast only localized 2/8, and the two DeepSeek models 1/8. This result is directional because of the small sample. Does Batching Preserve Rubric Relationships? After testing direct accuracy, we examined whether batching also preserves how rubric verdicts relate to one another. This is supporting structural evidence, not an accuracy measure against ground truth. The heatmaps compare Spearman correlations between GPT-5.6 Luna's binarized rubric verdicts on rows scored by both modes. The tool use structure was especially stable, including the strongest relationship between Tool Call Accuracy and Tool Input Accuracy (0.76 in both modes). Quality relationships were more mixed. For example, Single-Turn Intent Resolution and Task Completion fell from 0.71 to 0.31, while Multi-Turn Task Adherence and Task Completion fell from 0.53 to 0.23. This shows that batching can preserve the broad rubric structure without preserving every relationship equally. Finding 3: Reliability Depends on Both Rubric and Judge Multi-Turn Quality Reliability We repeated the six-evaluator composite call four times on the same 200 BFCL rows. Across the nine-judge panel, DeepSeek V4 Flash had the lowest average flip rate at 3.9%. GPT-5.6 Sol and Grok 4.1 Fast followed at 5.2%, DeepSeek V4 Pro at 5.6%, GPT-5.6 Luna at 6.8%, GPT-4o at 7.4%, GPT-5.6 Terra at 7.8%, GPT-5.4 mini at 10.9%, and GPT-5.4 at 15.6%. The rubric criteria-level result is more important than the leaderboard: Fluency: 0.0% average flip rate Coherence: 2.4% Intent Resolution: 8.6% Task Adherence: 6.7% Task Completion: 11.5% Groundedness: 16.4% The same judge can be highly stable on one rubric criterion and noisy on another. Reliability should therefore be monitored at the criterion level, not inferred from a single aggregate score. Multi-Turn Tool Use Reliability The five-evaluator MT tool study showed the same need for criterion-level monitoring. Across four BFCL repeats, GPT-5.6 Terra and DeepSeek V4 Flash had the lowest average flip rate at 6.0%, GPT-5.6 Sol reached 6.1%, and GPT-5.6 Luna and GPT-4o were at 7.0%. GPT-5.6 Sol achieved the strongest mode-of-four Tool Call Accuracy kappa at 0.759, while Terra led the single-run quality/localization results. Tool Call Success was the most stable criterion, with a 4.7% average flip rate across judges. Practical Recommendations Based on the results across quality, tool-use, localization, and reliability studies, we can derive practical guidance for both judge selection and evaluator batching. Recommended Judges: The GPT-5.6 Family Across the quality, tool-use, localization, and reliability experiments, the GPT-5.6 family consistently delivered the strongest overall results. While individual benchmarks occasionally favored other models or specific GPT-5.6 variants, Luna, Sol, and Terra repeatedly ranked among the top performers and showed the most balanced performance across workloads. Sol was generally the most reliable across repeated quality and tool-use studies, Terra led several BFCL tool-use and failed-turn localization evaluations, and Luna achieved the highest average quality across the tested workloads. For workloads similar to those evaluated here, we recommend starting with GPT-5.6 judges and selecting between Sol, Terra, and Luna based on your specific priorities. When available at a lower deployment cost, Luna is a particularly attractive option because it maintained frontier-level evaluation quality while achieving the strongest average performance in our experiments. By comparison, lower-cost models often involved larger tradeoffs between quality, reliability, and benchmark performance. Exact cost savings depend on model pricing and deployment configuration, so benchmark candidate judges on production-like workloads before optimizing solely for cost. Which Evaluators to Batch These evaluators performed as well in the composite evaluator as they did individually — they're strong candidates for batching right away: Fluency and Coherence — highly stable across all nine judges and repeats Tool Call Success and Tool Selection — robust across the tested judge models Task Completion — close to individual evaluation across benchmarks; slightly stronger with GPT-5.6 Luna on BFCL Tool Call Accuracy, Tool Input Accuracy, and Tool Output Utilization — strong on production-style traces, with accuracy ranging from 0.75 to 0.95 depending on evaluator and judge Which Evaluators to Watch These evaluators showed workload- or judge-dependent results. They can still be batched, but we recommend checking the results on your own data: Task Adherence — performed well on typical conversations but struggled when a single request contained many independent constraints Intent Resolution — results varied across datasets even though agreement was strong in some cases Groundedness — the least consistent evaluator in our tests, with scores changing across repeated runs more often than any other dimension, albeit having better performance on frontier models, like GPT-5.6 Luna and GPT-5.4. If grounding accuracy is critical for your use case, consider keeping the individual evaluator as a fallback Where This Approach Fits Composite evaluation is most effective as a selective default rather than a universal replacement for every standalone evaluator. GPT-5.6 Sol offered the strongest overall balance, Terra led the single-run BFCL tool results, and Luna is the recommended cheaper high-quality option. Judge and rubric selection should therefore be validated on production-like data. The Multi-Turn comparison has one structural boundary: native individual evaluators do not exist for Multi-Turn Fluency and Intent Resolution. The composite evaluator can produce both dimensions, but a direct individual-versus-composite validation is not available for them in that setting. Finally, token savings do not translate to one fixed currency percentage. Pricing varies by model and deployment, while output length and retry behavior vary by workload. Takeaway Composite evaluators are a practical way to remove repeated context from evaluation pipelines. In the updated 100-row comparisons, they reduced total input-token use by 61.25% for six quality evaluators and 71.07% for five tool use evaluators, reducing completion tokens by 46.63–63.89%, while reducing measured run wall time by 35.74% and 46.10%, respectively, and preserving comparable quality across many dimensions. The strongest deployment pattern is selective rather than absolute: start with a model from the GPT-5.6 family; batch the evaluators that remain stable, monitor them independently, and keep focused fallbacks for the evaluators that do not. Composite evaluation is ultimately about removing unnecessary work. By evaluating multiple dimensions in a single judge call, teams can dramatically reduce repeated context processing while maintaining the evaluation coverage needed to monitor production systems. Get Started Start with the composite evaluator on a small set of known-good and known-bad agent conversations. Choose Output Quality to assess the six quality criteria or Tool Use Quality to assess the five tool use criteria. Review each criterion’s score and applicability status, then spot-check the results against individual evaluators for the failure modes that matter most to your application. The GPT-5.6 family is the recommended starting point for judge models. Re-check results when you change the judge model or the domains of conversations being evaluated. Try these evaluators in the Microsoft Foundry portal now. You can explore the docs on how to use them Agent Evaluators for Generative AI - Microsoft Foundry | Microsoft Learn.438Views0likes0CommentsHow to make AI responses faster on Microsoft Foundry: lessons from 2,040 measurements
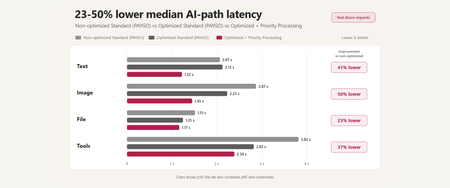
A reproducible Microsoft Foundry performance study covering prompt caching, multimodal input, tool orchestration, MCP lifecycle, Toolbox tool search, and Priority Processing - with correctness and reliability measured alongside latency.499Views0likes0CommentsIs "uncertainty" the feedback signal Copilot Studio agents are actually missing?
At today's M365 Platform Weekly session, we were asked for our input on what feedback we wish we could pull beyond thumbs up/down and verbatims. Is it trends over time, sentiment themes, the response-to-triage loop, etc. Here's an angle: What if the primitive itself is wrong? Thumbs up/down measures satisfaction after the fact. What if we measured confidence instead? How often an agent actually knows it's on shaky ground, and whether the user's reaction matches that? If an agent flags its own uncertainty at the point of response instead of a static thumbs up/down, a feedback prompt gets generated from whatever's trending in that uncertainty instead of the same generic question every time, and "trends over time" becomes "did this agent get more confident or less confident since the last update" rather than a flat satisfaction line. It might also solve the silence problem that most users rarely click anything. A reaction that's actually specific ("you caught something the agent flagged as shaky") seems easier to engage with than a binary good or bad. To be clear, confidence signals already exist in adjacent forms. Copilot Studio and most conversational AI platforms already use a confidence score internally to decide whether to answer directly, ask a clarifying question, or escalate to a human. GitHub Copilot has used a confidence score since its earliest versions too, ranking code suggestions and defaulting to the highest-scoring one. None of that is new. So rather than "add a percentage next to the answer", what if there is a specific flag pointing at the exact claim or step the agent is unsure about, feeding into the feedback loop? Curious if anyone else building in Copilot Studio has run into this: Do you ever wish your agent had hedged when it didn't? What would you actually do with an uncertainty score if you had one? And would just love others thoughts on this :)301Views0likes2Comments
What is the best file format for an AI agent knowledge base?
This is a best practice sharing the best format for an agent and show you why you should convert your PPT, PDF, WORD into a TXT markdown. I had an issue with my agent, time taken to answer was too long, and usually we spend a lot of time asking: What is the best prompt? Why is my agent slow? Why does retrieval sometimes work and sometimes fail? How can I improve answer quality? But I realised I was asking another question much less often: What is actually the best file format for the knowledge base? PDF? Raw text? Markdown? Pre-chunked text? Semantic sections? Context-enriched text? And more importantly: How much does the format alone affect agent performance? I tried to find a quantified benchmark answering this specific question, with the same agent, same source knowledge and same questions, but different knowledge representations. I couldn't find one that really answered what I wanted to measure. So I decided to run the experiment myself on a real case. My first exploratory tests were already surprising: depending on the representation, the agent could be significantly faster and more accurate, despite working from the exact same source information. So I decided to push the test further. My objective I want to identify, without assumptions and based on actual evaluation data, how a long document should be prepared for an LLM knowledge base so that the agent can retrieve, understand, ground and answer from it as reliably as possible. I focused on five dimensions: Answer quality Retrieval reliability Source grounding / citations Execution time Robustness across single-turn and multi-turn questions The broader question I'm trying to answer is: How should we structure knowledge so that an LLM can retrieve and use it as reliably as possible? The test case I deliberately chose a document that isn't particularly friendly for RAG: a 46-page European regulation, https://eur-lex.europa.eu/eli/reg/2011/1169/oj?locale=fr, on the provision of food information to consumers. The information is distributed across articles, definitions, exceptions, annexes, tables, numerical thresholds and cross-references. That makes it useful for testing retrieval: answering correctly often requires finding a very specific piece of information while preserving enough context to understand how it applies. I used the native PDF as the baseline and created 6 additional knowledge-base representations of the same document: Raw TXT Markdown Chunk-ready TXT RAG-oriented units Semantic TXT Contextual TXT One rule: same knowledge, same agent, same instructions, same questions. Only the knowledge representation changes. The benchmark I used two evaluation sets: 42 single-turn questions testing broad coverage of the document: direct facts, thresholds, exceptions, annexes, lists and cross-references. 5 multi-turn conversations containing 13 questions, to see what happens when a user asks a question and then follows up with things like: "And in this case?" "What are the exceptions?" "And for dietary fibre?" This gave me: 47 evaluated test cases / 55 actual questions per format Across all 7 formats: 329 evaluated conversations 385 user questions executed First results Metric Native PDF Best structured representation Overall pass rate 66.0% 85.1% - Contextual TXT Best single-turn score 69.0% 88.1% - Chunk-ready TXT Multi-turn benchmark 40% 80% - Contextual TXT Multi-turn execution time 14m24 5m54 Total benchmark time 44m31 24m49 The quality gap was already substantial: 66.0% → 85.1% That's +19.1 percentage points while keeping the underlying knowledge unchanged. I also saw a major difference in execution time. On the multi-turn test: 14m24 → 5m54 That's approximately 2.4× faster. Across the complete benchmark: 44m31 → 24m49 Around 44% less execution time. These timings represent the complete agent evaluation pipeline, so they shouldn't be interpreted as pure LLM inference latency. But the difference under identical test conditions is large enough that I want to understand it better. Findings There wasn't one format dominating every benchmark. Chunk-ready TXT scored highest on independent questions: 88.1%, while Contextual TXT performed better across multi-turn conversations and finished with the highest overall score. That may suggest that the way we optimise a document for isolated retrieval isn't exactly the same as the way we should prepare it for conversational retrieval. In the contextual version, I tried to make every section understandable when retrieved independently by keeping useful information around it: Source references Section context Retrieval cues Relevant cross-references For regulatory documents, this seems particularly important. A numerical value retrieved alone can be meaningless without knowing which rule it belongs to, under which conditions it applies, and whether another article contains an exception. Where I am now This remains an exploratory benchmark: One document One domain One agent setup One evaluation framework One run per configuration There are plenty of things I still want to test: repeated runs, retrieval-level evaluation, token consumption, larger knowledge bases, other document types, chunk sizes, overlap, contextual headers, and more. But these first results already convinced me that the preparation of the knowledge base deserves much more attention when evaluating an agent. We often spend hours refining instructions while the same information may behave very differently depending on how it reaches the retrieval layer. Next step I'll share the prompts, knowledge-base formats and evaluation methodology on GitHub so the experiment can be reproduced and challenged. I'll keep enriching the repository as I test new formats, improve the evaluation set and add new results. If people here have ideas, edge cases or formats worth testing, I'd genuinely like to include some of them in the next iteration. What would you test next?897Views3likes3CommentsUnanswered Questions on GitHub Copilot Harness in Copilot Studio
We're piloting the GitHub Copilot harness in Copilot Studio (GA August 2026) and several operational and architectural details remain undocumented in the GA FAQ, Microsoft Learn, or licensing guides. Looking for official answers or PM contacts on: Architecture & Execution – When the harness breaks tasks into subtasks, does it use internal sub-agents or only skills/connected agents, what are the exact timeout/retry/max-execution-duration limits for long-running workflows, and are planning/context-retrieval/orchestration internals documented anywhere or is the orchestrator a black box? Model Selection – Can individual skills within one agent use different models or is selection strictly agent-level, how are models chosen internally when multiple skills execute, are any internal models developer-configurable, and what's the roadmap for models being added/retired/deprecated plus the lag between public release and Copilot Studio availability? Cost & Token Optimization – How exactly is the ~45% token reduction achieved, how much control do makers have over context/caching/retrieval/tool calls, what are per-model credit consumption characteristics, which models are most cost-effective for specific workloads, and what's the minimum credit cost for trivial interactions? Memory Management – What are retention periods for session/working/agent memory beyond the documented 28-day user-memory expiry, is true long-term memory supported, and what changed versus earlier implementations? Knowledge Retrieval – Can skills or system instructions influence retrieval strategy/document selection/prioritization/filtering, can planning stages perform conflict/duplicate/version detection before retrieval, and how does the harness decide which sources to search? Apps Feature – What is the "Apps (preview)" capability for, when does it GA, and how does it differ from workflows/skills/adaptive cards/agents? Billing & Credit Sizing – Is there a framework to classify users/agents by expected consumption and size credit allocation per group (citizen vs pro developers), and what's the minimum/typical consumption for simple/medium/heavy interactions? Governance & Admin – Can usage limits be set at user level (not just environment/agent), is there an API/IaC path for large-scale credit assignment, can non-admins view their own consumption/remaining allocation, and is there a self-service request-more-credits dashboard? ALM & Environments – What's the recommended path to move harness agents across Dev/Test/UAT/Prod (Solutions/ALM "setup differs" per parity chart—how?), does GitHub integration replace or complement solution-based deployment, are there recommended AgentOps practices for source control/releases/versioning, and what baseline credits and onboarding model are suggested for citizen developers under usage billing—any enterprise reference implementations?623Views2likes1Comment