enterprise
256 TopicsSyncing Multiple Azure DevOps Orgs to One ServiceNow Instance Without Forcing a Shared Workflow
If your organization runs more than one Azure DevOps org, whether from an acquisition, a spun-up subsidiary, or business units that never consolidated onto one instance, you already know the visibility gap. Central ServiceNow has no idea what's happening in any of them unless someone checks manually. Your team ends up pulling status updates by hand, chasing changes across orgs, and reconciling what got closed where. That works well for a couple of orgs, but it falls apart past that. Why a Shared Workflow Usually Creates a Bigger Problem Migrating everyone onto a single Azure DevOps org would close the visibility gap on paper. Each org's area paths, iterations, states, and processes took years to get right, and a forced migration undoes all of it. A sync layer between each Azure DevOps org and your central ServiceNow instance closes the same gap without touching how any individual org works day to day. Each org keeps its own configuration. ServiceNow ends up with a rolled-up view across all of them. Common Use Cases Post-Acquisition Org Sprawl Current Setup: A company acquires another company, or runs several business units, each with its own Azure DevOps org and its own way of working. Problem: Central ops has no single view across orgs, and checking each one by hand doesn't scale past a few teams. Solution: Connect each Azure DevOps org to the central ServiceNow instance separately, each with its own sync rules. ServiceNow gets one rolled-up view, and no org has to change how it works. Bi-Directional Status Sync Between Delivery and Support Current Setup: Support logs incidents in ServiceNow. Development tracks the corresponding work in Azure DevOps, sometimes across several orgs. Problem: Support has to ask developers for status or check Azure DevOps boards directly, and developers end up relaying the same update twice. Solution: Sync status, comments, and priority both ways, so an update in either system shows up automatically on the other side. Field-Level Control Per Org Current Setup: Each business unit or subsidiary has its own rules about what data can leave its Azure DevOps org. Problem: A single shared integration with one set of mapping rules risks exposing fields an org never agreed to share outside its own boundary. Solution: Give each org's connection its own outgoing rules, so a subsidiary decides exactly which fields leave its Azure DevOps org, field by field. Handling Closed and Read-Only Work Items Current Setup: ServiceNow blocks writes to closed incidents through ACLs, and Azure DevOps can hit a similar restriction on closed or read-only work items. Problem: A sync that keeps trying to write to a closed item throws the same error repeatedly, and the real problems get buried under the noise. Solution: Filter closed and read-only states out of the sync, or let the errors surface if operations wants visibility into them. What to Evaluate When Choosing an Approach A few criteria matter more than others once you're running this across multiple orgs. Decentralized configuration: does each Azure DevOps org get its own connection and its own rules, or does everything route through one shared setup? Filtering: can you scope the sync with something like WIQL queries on the Azure DevOps side, by area path, iteration, work item type, or tag? Field mapping: does it handle the difference between ServiceNow's field structure and Azure DevOps work item fields without dropping data? Common pairs are ServiceNow State to Azure DevOps State, ServiceNow Priority to Azure DevOps Priority, and ServiceNow Assignment Group to Azure DevOps Area Path. Custom fields usually need explicit mapping rules. Conflict handling: what happens when both sides update the same field at the same time, and what happens with closed or read-only items specifically? Security: Entra ID or OAuth authentication, PAT management per org, role-based access, audit logging, and whatever compliance certifications your security team asks for during review. Direction: bidirectional where both teams update shared fields, one-way where only one side should ever write. Technical Approaches Service Hooks and REST APIs Azure DevOps Service Hooks paired with the ServiceNow REST API give you sync in both directions. A change in Azure DevOps triggers a Service Hook, which calls the ServiceNow API to update the record, and the same flow runs in reverse. This is the most direct route if you're comfortable building and maintaining the webhook logic yourself. Custom Middleware For anything more complex, custom middleware gives you full control over field transformation, routing, and error handling. Azure Functions, Logic Apps, or a small Node.js or Python service usually does the job. The trade-off is maintenance. You own the retry logic, the error handling, and every update when either platform changes its API. Dedicated Integration Platforms Plenty of teams skip building this from scratch and use a dedicated integration platform instead. These typically come with pre-built connectors for both Azure DevOps and ServiceNow, a way to configure field mapping and filters without writing much code, and managed infrastructure so you're not hosting your own sync server. What they usually cover: Pre-configured connectors that already understand both platforms' data structures Visual or scripting configuration for field mapping and filters Managed infrastructure, so nothing runs on your own servers Built-in retry and error handling for API failures Audit logging for tracking what synced and when Support for multi-org routing and conditional logic out of the box The trade-off runs the other way: a subscription cost instead of a one-time build, less control over the exact implementation, and your data passing through a third party's infrastructure. For teams running more than 2 or 3 orgs against one ServiceNow instance, this usually ends up being less overhead than maintaining custom middleware long-term. Every org here has probably solved a version of this differently. Curious what's worked for you, especially with 3 or more Azure DevOps orgs feeding into one ServiceNow instance, and which part of the setup gave you the most trouble.82Views1like0Comments
Passkey best practices for Windows 365 users on unmanaged devices (BYOD)?
I have global contractors who work from home so spinning up Windows 365 Enterprise Cloud PCs are ideal. The contractors work from from either their personal Mac or personal Windows PC using the Microsoft Windows app so each user can access their dedicated Windows 365 Cloud PC and everything has been working well so far using standard MFA. We are looking to move everyone to passkeys but there is no intuitive documentation on how end users are expected to adopt it so they can use passkeys to 1) access the virtual PC and then use passkeys while in the virtual PC itself. Seems Microsoft explains everything under the hood except how to practically roll it out to reliably replace standard MFA. What is the recommended path forward to migrate my BYOD virtual PC users to passkeys? Thanks, Charlie196Views0likes1CommentUsers prompted for WHfB auth for Entra SSO resources
My colleagues and I have noticed that we are frequently being prompted to perform a Windows Hello for Business authentication when we use Edge to access resources that use Entra for authentication. Previously, this authentication occurred transparently. Has something changed recently?Solved203Views0likes3Comments
Windows 365 and developer environments: how do you balance security and productivity?
Hi everyone, I’d like to raise a topic that we are currently struggling with, and I suspect many other organizations are facing the same challenge. We are in the process of establishing a Windows 365–based development environment, where developers work in Cloud PCs. This is largely driven by: a BYOD strategy security requirements (no sensitive code on unmanaged devices) the need for standardization However, this quickly becomes complex in practice. The core challenge We are trying to balance three competing priorities: 1. Security requirements No sensitive code on local devices Minimal attack surface Zero Trust principles and Conditional Access Full traceability of identity and actions 2. Developer needs Local admin rights to be able to do their work Freedom to install tools, SDKs, and runtimes Flexibility without constant blocking Fast iteration cycles The reality is that if it takes too long to get access or permissions, it breaks the developer workflow. 3. IT and governance Standardization of environments Manageability and patching License and cost control Compliance and auditability The practical dilemma Developers want to be local admins on their machines Security teams prefer: Just-In-Time access (PIM), or No admin privileges at all In practice: PIM tends not to work well for developers It introduces too much friction It disrupts flow and often leads to workarounds What we are currently exploring We are testing a model where: Developers work in Windows 365 Cloud PCs They use their regular corporate identity (Entra ID) Isolation is achieved through the environment, not separate accounts Developers have local admin rights within the Cloud PC However, this raises a new question: How do we secure an environment where the user is an admin? Questions to the community I would really appreciate insights from others who have been through similar scenarios: 1. Identity vs privilege Do you use the same identity for everything, or separate user/admin accounts? How far do you take identity separation? 2. Local admin rights Do you allow developers to have local admin rights? Is it permanent or Just-In-Time? If JIT, how do you make it work without impacting productivity? 3. Cloud-based development environments If you are using Windows 365, Dev Box, or AVD: Has this made it easier to relax restrictions? Or are you facing the same challenges, just in the cloud? 4. Guardrails instead of restrictions Instead of trying to prevent everything: EDR / endpoint protection Conditional Access Network isolation Monitoring and detection Has anyone successfully shifted from strict control to strong guardrails and detection? Current reflection I am starting to think that: Focusing on secure, isolated environments for development may be more effective than trying to tightly control every individual action. In other words: secure the platform not every single user behavior But this is far from straightforward. Purpose of this discussion The goal is to find a realistic blueprint that: maintains high developer productivity meets security requirements minimizes friction in day-to-day work Not something theoretically perfect, but something that actually works. If you have experience in this area, I would really value your input: what has worked well what has not worked key design decisions you would recommend Thanks in advance.173Views0likes1Comment
Windows Hello for Business - W365 Cloud PC
Hello All, We are currently attempting to use Yubikey USB-A and C devices for authentication. For Laptop authentication it works, but we are trying to implement this on a Windows 365 Cloud PC while signing into Windows App. Has anyone tried this method? This is the device we are trying to use: https://www.yubico.com/product/yubikey-5-series/yubikey-5c-nfc/ This is what i seen when i did my research: High‑level architecture (important context) On Windows 365 Cloud PCs: ✅ WHfB is PIN‑based (this is the supported model) ⚠️ Biometrics (face/fingerprint) are usually not available ✅ WHfB is user‑scoped, not just device‑scoped ✅ WHfB requires a healthy PRT first ❌ WHfB cannot provision if AzureAdPrt = NO If PRT/WAM aren’t healthy, WHfB setup will never appear, even if policy is correct. Any input, insight, or feedback is grreatly appreciated!!428Views0likes1CommentExpanding the Reach of AI-enabled Cloud PCs for Frontier Firms
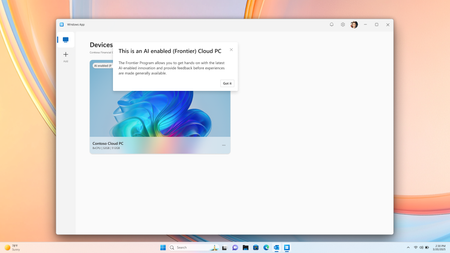
Co-Authored by Lakshmi Rayasam Over the past several months, we’ve been focused on a clear goal: making AI-enabled Cloud PCs easier to adopt, easier to deploy, and available to more customers—wherever they are. Following the momentum from Ignite, releasing Improved Search & Click to Do, we’ve continued to evolve the AI-enabled Cloud PC experience in Frontier Preview, prioritizing scale, accessibility, and product market fit. The latest set of enhancements removes deployment blockers and expands where—and how—customers can get started. We’ve also added a new refreshing AI-enabled end-user experience explaining the value of Frontier while users hover over the AI-enabled (Frontier) tag. Note: Future availability of these features is dependent on the results of this Frontier Preview and is subject to change Removing the need for Windows Insiders AI‑enabled Cloud PCs now work with standard Windows 11 retail builds, eliminating the need for Windows Insider participation. This change alone unlocks broader enterprise deployment scenarios and removes a major barrier for production use. AI-enabled Cloud PCs are just one toggle away as IT admins can join our Frontier Program and enable AI-enabled Cloud PCs via a newly introduced policy setting within the Devices – Onboarding: Windows 365 > User Settings blade, and further filter access based on Microsoft Entra ID group access. Note: After enrolling the latest Windows 11 25H2 (OS Build 26200.7840 or higher) you must reboot your Cloud PC. Expanded regional availability To meet customers where they operate, we’ve expanded AI‑enabled Cloud PCs to additional Azure regions:‑ Japan East Germany West Central South Central US Canada Central This expansion improves latency, supports data residency needs, and enables more global customers to participate in the Frontier Preview. 128GB disk support for Windows 365 Enterprise We’ve added support for 128GB disk size Windows 365 Enterprise licenses, offering greater flexibility for customers who don’t require larger footprints while still enabling AI‑driven workflows. These right‑sized deployments and makes it easier to scale across broader user populations. Together, these updates directly address the most common Ignite feedback and are expected to unlock large‑scale deployments, including enterprise pilots transitioning into sustained usage. What Comes Next Following the March rollout, our CY26 focus shifts to closing parity gaps using cloud‑based models, in close partnership with Windows platform teams. Initial work centers on enabling Text Actions for Click‑to‑Do via a cloud models within Frontier Preview—one of the most requested capabilities from customers.‑‑‑ In parallel, we’ll continue investing in foundational improvements that increase perceived feature depth and usage signals, including cost optimization, reliability enhancements, and productivity scenarios that compound value across the Cloud PC experience.547Views1like2Comments
Is it possible to migrate Windows 365 between two Entra ID/MS365 tenants?
Hello, we're merging two companies, and as part of this merger, we want to migrate one Entra/MS365 tenant to another. Migrating mailboxes, OneDrive, SPO sites, and other 365 services is no problem for us, but we'd also like to migrate ~40 Windows 365 instances (Entra-Joined, hot Hybrid). Is this possible? Regular workstations can be migrated without a wipe using third-party services (like PowerSyncPro and similar), but in this case, these are VMs managed by Windows 365 service.Solved239Views1like1CommentMS designer is NOT WORKING!
It only makes 1 image not 4, it takes way too long time,. and it doesnt follow prompting,. and it makes imegs in 3:2 not 16:9... thsi has been goign on for over 2 weeks,... alsmot 3.. i have been in contact with support many times woith zero help.. HOW can you have a product in your office bunlde ant it not workign an zero supprot on it? I need teh application to make my videos,. im just abptu to cancel all subscritopons to micrposft an switch to apple..226Views0likes0CommentsSupporting ChatGPT on PostgreSQL in Azure
Affan Dar, Vice President of Engineering, PostgreSQL at Microsoft Adam Prout, Partner Architect, PostgreSQL at Microsoft Panagiotis Antonopoulos, Distinguished Engineer, PostgreSQL at Microsoft The OpenAI engineering team recently published a blog post describing how they scaled their databases by 10x over the past year, to support 800 million monthly users. To do so, OpenAI relied on Azure Database for PostgreSQL to support important services like ChatGPT and the Developer API. Collaborating with a customer experiencing rapid user growth has been a remarkable journey. One key observation is that PostgreSQL works out of box for very large-scale points. As many in the public domain have noted, ChatGPT grew to 800M+ users before OpenAI started moving new and shardable workloads to Azure Cosmos DB. Nevertheless, supporting the growth of one of the largest Postgres deployments was a great learning experience for both of our teams. Our OpenAI friends did an incredible job at reacting fast and adjusting their systems to handle the growth. Similarly, the Postgres team at Azure worked to further tune the service to support the increasing OpenAI workload. The changes we made were not limited to OpenAI, hence all our Azure Database for PostgreSQL customers with demanding workloads have benefited. A few of the enhancements and the work that led to these are listed below. Changing the network congestion protocol to reduce replication lag Azure Database for PostgreSQL used the default CUBIC congestion control algorithm for replication traffic to replicas both within and outside the region. Leading up to one of the OpenAI launch events, we observed that several geo-distributed read replicas occasionally experienced replication lag. Replication from the primary server to the read replicas would typically operate without issues; however, at times, the replicas would unexpectedly begin falling behind the primary for reasons that were not immediately clear. This lag would not recover on its own and would grow to a point when, eventually, automation would restart the read replica. Once restarted, the read replica would once again catch up, only to repeat this cycle again within a day or less. After an extensive debugging effort, we traced the root cause to how the TCP congestion control algorithm handled a higher rate of packet drops. These drops were largely a result of high point-to-point traffic between the primary server and its replicas, compounded by the existing TCP window settings. Packet drops across regions are not unexpected; however, the default congestion control algorithm (CUBIC) treats packet loss as a sign of congestion and does an aggressive backoff. In comparison, the Bottleneck Bandwidth and Round-trip propagation time (BBR) congestion control algorithm is less sensitive to packet drops. Switching to BBR, adding SKU specific TCP window settings, and switching to fair queuing network discipline (which can control pacing of outgoing packets at hardware level) resolved this issue. We’ll also note that one of our seasoned PostgreSQL committers provided invaluable insights during this process, helping us pinpoint the issue more effectively. Scaling out with Read replicas PostgreSQL primaries, if configured properly, work amazingly well in supporting a large number of read replicas. In fact, as noted in the OpenAI engineering blog, a single primary has been able to power around 50+ replicas across multiple regions. However, going beyond this increases the chance of impacting the primary. For this reason, we added the cascading replica support to scale out reads even further. But this brings in a number of additional failure modes that need to be handled. The system must carefully orchestrate repairs around lagging and failing intermediary nodes, safely repointing replicas to new intermediary nodes while performing catch up or rewind in a mission critical setup. Furthermore, disaster recovery (DR) scenarios can require a fast rebuild of a replica and as data movement across regions is a costly and time-consuming operation, we developed the ability to create a geo replica from a snapshot of another replica in the same region. This feature avoids the traditional full data copy process, which may take hours or even days depending on the size of the data, by leveraging data for that cluster that already exists in that region. This feature will soon be available for all our customers as well. Scaling out Writes These improvements solved the read replica lag problems and read scale but did not help address the growing write scale for OpenAI. At some point, the balance tipped and it was obvious that the IOPs limits of a single PostgreSQL primary instance will not cut it anymore. As a result OpenAI decided to move new and shardable workloads to Azure Azure Cosmos DB, which is our default recommended NoSQL store for fully elastic workloads. However, some workloads, as noted in the OpenAI blog are much harder to shard. While OpenAI is using Azure Database for PostgreSQL flexible server, several of the write scaling requirements that came up have been baked into our new Azure HorizonDB offering, which entered private preview in November 2025. Some of the architectural innovations are described in the following sections. Azure HorizonDB scalability design To better support more demanding workloads, Azure HorizonDB introduces a new storage layer for Postgres that delivers significant performance and reliability enhancements: More efficient read scale out. Postgres read replicas no longer need to maintain their own copy of the data. They can read pages from the single copy maintained by the storage layer. Lower latency Write-Ahead Logging (WAL) writes and higher throughput page reads via two purpose-built storage services designed for WAL storage and Page storage. Durability and high availability responsibilities are shifted from the Postgres primary to the storage layer, allowing Postgres to dedicate more resources to executing transactions and queries. Postgres failovers are faster and more reliable. To understand how Azure HorizonDB delivers these capabilities, let’s look at its high‑level architecture as shown in Figure 1. It follows a log-centric storage model, where the PostgreSQL writeahead log (WAL) is the sole mechanism used to durably persist changes to storage. PostgreSQL compute nodes never write data pages to storage directly in Azure HorizonDB. Instead, pages and other on-disk structures are treated as derived state and are reconstructed and updated from WAL records by the data storage fleet. Azure HorizonDB storage uses two separate storage services for WAL and data pages. This separation allows each to be designed and optimized for the very different patterns of reads and writes PostgreSQL does against WAL files in contrast to data pages. The WAL server is optimized for very low latency writes to the tail of a sequential WAL stream and the Page server is designed for random reads and writes across potentially many terabytes of pages. These two separate services work together to enable Postgres to handle IO intensive OLTP workloads like OpenAI’s. The WAL server can durably write a transaction across 3 availability zones using a single network hop. The typical PostgreSQL replication setup with a hot standby (Figure 2) requires 4 hops to do the same work. Each hop is a component that can potentially fail or slow down and delay a commit. Azure HorizonDB page service can scale out page reads to many hundreds of thousands of IOPs for each Postgres instance. It does this by sharding the data in Postgres data files across a fleet of page servers. This spreads the reads across many high performance NVMe disks on each page server. 2 - WAL Writes in HorizonDB Another key design principle for Azure HorizonDB was to move durability and high availability related work off PostgreSQL compute allowing it to operate as a stateless compute engine for queries and transactions. This approach gives Postgres more CPU, disk and network to run your application’s business logic. Table 1 summarizes the different tasks that community PostgreSQL has to do, which Azure HorizonDB moves to its storage layer. Work like dirty page writing and checkpointing are no longer done by a Postgres primary. The work for sending WAL files to read replicas is also moved off the primary and into the storage layer – having many read replicas puts no load on the Postgres primary in Azure HorizonDB. Backups are handled by Azure Storage via snapshots, Postgres isn’t involved. Task Resource Savings Postgres Process Moved WAL sending to Postgres replicas Disk IO, Network IO Walsender WAL archiving to blob storage Disk IO, Network IO Archiver WAL filtering CPU, Network IO Shared Storage Specific (*) Dirty Page Writing Disk IO background writer Checkpointing Disk IO checkpointer PostgreSQL WAL recovery Disk IO, CPU startup recovering PostgreSQL read replica redo Disk IO, CPU startup recovering PostgreSQL read replica shared storage Disk IO background, checkpointer Backups Disk IO pg_dump, pg_basebackup, pg_backup_start, pg_backup_stop Full page writes Disk IO Backends doing WAL writing Hot standby feedback Vacuum accuracy walreceiver Table 1 - Summary of work that the Azure HorizonDB storage layer takes over from PostgreSQL The shared storage architecture of Azure HorizonDB is the fundamental building block for delivering exceptional read scalability and elasticity which are critical for many workloads. Users can spin up read replicas instantly without requiring any data copies. Page Servers are able to scale and serve requests from all replicas without any additional storage costs. Since WAL replication is entirely handled by the storage service, the primary’s performance is not impacted as the number of replicas changes. Each read replica can scale independently to serve different workloads, allowing for workload isolation. Finally, this architecture allows Azure HorizonDB to substantially improve the overall experience around high availability (HA). HA replicas can now be added without any data copying or storage costs. Since the data is shared between the replicas and continuously updated by Page Servers, secondary replicas only replay a portion of the WAL and can easily keep up with the primary, reducing failover times. The shared storage also guarantees that there is a single source of truth and the old primary never diverges after a failover. This prevents the need for expensive reconciliation, using pg_rewind, or other techniques and further improves availability. Azure HorizonDB was designed from the ground up with learnings from large scale customers, to meet the requirements of the most demanding workloads. The improved performance, scalability and availability of the Azure HorizonDB architecture make Azure a great destination for Postgres workloads.5KViews11likes0Comments