c#
6 TopicsScaling Write Throughput in Azure Database for MySQL Using Application-Level Sharding
This blog post walks through scaling write throughput in Azure Database for MySQL using application level sharding. It starts with the why behind sharding and then builds a complete C# implementation that spreads writes across three Azure Database for MySQL Flexible Servers. Why Shard in the First Place? This post focuses specifically on scaling write throughput. A well-tuned single primary node can take you remarkably far, and techniques such as indexing strategies, write batching, redo log optimization, and vertical compute scaling each deliver real, lasting value. For many workloads, these optimizations are all you will ever need. That said, as write volume continues to grow, a single primary eventually approaches its practical capacity, and at that point the most durable way to keep scaling is to distribute the write workload across multiple primary instances. This architecture is what we call sharding. When you reach this inflection point, there are two primary patterns for managing multiple write nodes: Proxy or Middleware Layer Sharding: A sharding aware proxy sits between the application and a pool of Azure Database for MySQL instances, routing queries based on a shard key. While this abstracts the underlying topology from the application layer, it introduces an additional, complex component to operate, secure, scale, and patch. Application Layer Sharding: The application itself resolves the destination shard key and determines which of the N Azure Database for MySQL instances should receive a write before ever opening a database connection. Each backend target remains a completely standard, independent Azure Database for MySQL instance. This post explores the second approach. The core appeal of application layer sharding is architectural simplicity: it introduces zero infrastructure overhead and eliminates an extra network hop. Every shard behaves exactly like a standalone instance, meaning your existing backup, restore, monitoring pipelines, and the Azure portal function seamlessly without modification. The explicit tradeoff is that you forgo cross shard joins and distributed transactions in exchange for absolute predictability and control over data access patterns. The Plan We will build a small order management service that distributes its data across three Azure Database for MySQL instances that already exist. The application, written in C# on .NET 8, owns the partitioning logic. The premise: the three servers are already provisioned, the firewalls are configured, the network paths are established, and each server has its own administrative credentials. We are not provisioning infrastructure in this post. we are writing the application code that consumes it. mysql-shard-0.mysql.database.azure.com user: shard0_admin pwd: <secret-0> mysql-shard-1.mysql.database.azure.com user: shard1_admin pwd: <secret-1> mysql-shard-2.mysql.database.azure.com user: shard2_admin pwd: <secret-2> Each server hosts an identical appdb database with the same schema: CREATE TABLE users ( user_id BIGINT NOT NULL PRIMARY KEY, email VARCHAR(255) NOT NULL, created_at DATETIME NOT NULL DEFAULT CURRENT_TIMESTAMP, UNIQUE KEY uq_email (email) ); CREATE TABLE orders ( order_id BIGINT NOT NULL PRIMARY KEY, user_id BIGINT NOT NULL, amount_cents INT NOT NULL, created_at DATETIME NOT NULL DEFAULT CURRENT_TIMESTAMP, KEY ix_user (user_id) ); Two design decisions in this schema warrant explanation: No AUTO_INCREMENT for user_id or order_id. Two shards would otherwise generate the same value 42 independently. Instead, we assign identifiers in the application, using a scheme such as Snowflake, ULID, or UUIDv7. orders carries user_id, and we route by it. This is the single most important rule of sharding: choose a shard key that keeps related data colocated, so that the common queries remain on a single shard. A note on UNIQUE KEY uq_email. A unique index enforces uniqueness only within a single physical shard. Because we route by user_id, two users with different IDs and the same email may land on different shards, and both inserts will succeed. If you require globally unique emails, two options exist: (a) maintain a separate email → user_id lookup table on a single "directory" server and write to it first within an idempotent flow, or (b) shard the users table by a hash of email instead. We retain user_id routing throughout this post because it is the correct choice for orders, and we treat per shard email uniqueness as a best effort guard rather than a hard global invariant. How the Partitioning Works The naive approach to sharding is shard = hash(key) % N. This works until you need to add a fourth server, at which point roughly 75% of your data must move. In any system of meaningful size, that is prohibitively expensive. The established solution is virtual buckets. You hash the key into a large, fixed bucket space (here, 1024), then map buckets to physical shards. When you add capacity, you relocate only buckets; you never rehash the entire dataset. In production, the bucket_to_shard_map typically resides in a system such as Azure App Configuration or etcd, so that you can rebalance without redeploying. For this post, we keep it as an in-memory array seeded at startup, which is straightforward to replace later. The Project ShardingDemo/ ├── ShardingDemo.csproj ├── appsettings.json ├── Models.cs ├── ShardRouter.cs ├── UserRepository.cs └── Program.cs ShardingDemo.csproj <Project Sdk="Microsoft.NET.Sdk"> <PropertyGroup> <OutputType>Exe</OutputType> <TargetFramework>net8.0</TargetFramework> <Nullable>enable</Nullable> <ImplicitUsings>enable</ImplicitUsings> </PropertyGroup> <ItemGroup> <PackageReference Include="MySqlConnector" Version="2.6.0" /> <PackageReference Include="Microsoft.Extensions.Hosting" Version="8.0.0" /> <PackageReference Include="Microsoft.Extensions.Configuration.Binder" Version="8.0.0" /> </ItemGroup> <ItemGroup> <Content Include="appsettings.json" CopyToOutputDirectory="PreserveNewest" /> </ItemGroup> </Project> appsettings.json Shards is an ordered list, and a shard's position in the array is its logical ID. { "Shards": [ { "Host": "mysql-shard-0.mysql.database.azure.com", "Database": "appdb", "User": "shard0_admin", "Password": "REPLACE_ME_0" }, { "Host": "mysql-shard-1.mysql.database.azure.com", "Database": "appdb", "User": "shard1_admin", "Password": "REPLACE_ME_1" }, { "Host": "mysql-shard-2.mysql.database.azure.com", "Database": "appdb", "User": "shard2_admin", "Password": "REPLACE_ME_2" } ] } Models.cs namespace ShardingDemo; public sealed record User(long UserId, string Email, DateTime CreatedAt); public sealed record Order(long OrderId, long UserId, int AmountCents, DateTime CreatedAt); public sealed class ShardConfig { public required string Host { get; init; } public required string Database { get; init; } public required string User { get; init; } public required string Password { get; init; } } ShardRouter.cs using System.Security.Cryptography; using System.Text; using MySqlConnector; namespace ShardingDemo; public sealed class Shard : IAsyncDisposable { public int Id { get; } public MySqlDataSource DataSource { get; } public Shard(int id, ShardConfig cfg) { Id = id; var csb = new MySqlConnectionStringBuilder { Server = cfg.Host, Port = 3306, Database = cfg.Database, UserID = cfg.User, Password = cfg.Password, SslMode = MySqlSslMode.Required, Pooling = true, MinimumPoolSize = 2, MaximumPoolSize = 100, ConnectionTimeout = 10, DefaultCommandTimeout = 30, }; DataSource = new MySqlDataSourceBuilder(csb.ConnectionString).Build(); } public ValueTask DisposeAsync() => DataSource.DisposeAsync(); } public sealed class ShardRouter : IAsyncDisposable { private const int VirtualBuckets = 1024; private readonly IReadOnlyList<Shard> _shards; private readonly int[] _bucketToShardId; public ShardRouter(IEnumerable<ShardConfig> configs) { _shards = configs.Select((c, i) => new Shard(i, c)).ToList(); // Even distribution. Replace with a map loaded from your control plane for live rebalancing. _bucketToShardId = new int[VirtualBuckets]; for (int i = 0; i < VirtualBuckets; i++) _bucketToShardId[i] = i % _shards.Count; } public IReadOnlyList<Shard> AllShards => _shards; private static int BucketFor(long shardKey) { byte[] hash = MD5.HashData(Encoding.ASCII.GetBytes(shardKey.ToString())); // Use the first byte pair as an unsigned value, then map it into the bucket space. int value = (hash[0] << 8) | hash[1]; return value % VirtualBuckets; } public Shard ShardForKey(long shardKey) { int bucket = BucketFor(shardKey); return _shards[_bucketToShardId[bucket]]; } public async ValueTask DisposeAsync() { foreach (var s in _shards) await s.DisposeAsync(); } } UserRepository.cs Observe that every per user method calls ShardForKey(userId), even when inserting an order. This is the colocation rule at work. An order and its owning user always reside on the same shard, so queries for a single user only ever reach one shard. Only the cross-shard aggregate (TotalRevenueCentsAsync) must fan out. using MySqlConnector; namespace ShardingDemo; public sealed class UserRepository { private readonly ShardRouter _router; public UserRepository(ShardRouter router) { _router = router; } public async Task CreateUserAsync(long userId, string email, CancellationToken ct = default) { var shard = _router.ShardForKey(userId); await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = "INSERT INTO users (user_id, email) VALUES (@id, Email)"; cmd.Parameters.AddWithValue("@id", userId); cmd.Parameters.AddWithValue("@email", email); await cmd.ExecuteNonQueryAsync(ct); } public async Task<User?> GetUserAsync(long userId, CancellationToken ct = default) { var shard = _router.ShardForKey(userId); await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = "SELECT user_id, email, created_at FROM users WHERE user_id = ID"; cmd.Parameters.AddWithValue("@id", userId); await using var reader = await cmd.ExecuteReaderAsync(ct); if (!await reader.ReadAsync(ct)) return null; return new User(reader.GetInt64(0), reader.GetString(1), reader.GetDateTime(2)); } public async Task AddOrderAsync(long orderId, long userId, int amountCents, CancellationToken ct = default) { // Routed by user_id, so orders colocate with their owning user. var shard = _router.ShardForKey(userId); await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = """ INSERT INTO orders (order_id, user_id, amount_cents) VALUES (@oid, @uid, amt) """; cmd.Parameters.AddWithValue("@oid", orderId); cmd.Parameters.AddWithValue("@uid", userId); cmd.Parameters.AddWithValue("@amt", amountCents); await cmd.ExecuteNonQueryAsync(ct); } public async Task<IReadOnlyList<Order>> GetOrdersForUserAsync(long userId, CancellationToken ct = default) { var shard = _router.ShardForKey(userId); await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = """ SELECT order_id, user_id, amount_cents, created_at FROM orders WHERE user_id = @uid """; cmd.Parameters.AddWithValue("@uid", userId); var list = new List<Order>(); await using var reader = await cmd.ExecuteReaderAsync(ct); while (await reader.ReadAsync(ct)) { list.Add(new Order( reader.GetInt64(0), reader.GetInt64(1), reader.GetInt32(2), reader.GetDateTime(3))); } return list; } /// <summary>Cross shard fanout.</summary> public async Task<long> TotalRevenueCentsAsync(CancellationToken ct = default) { var tasks = _router.AllShards.Select(async shard => { await using var conn = await shard.DataSource.OpenConnectionAsync(ct); await using var cmd = conn.CreateCommand(); cmd.CommandText = "SELECT COALESCE(SUM(amount_cents), 0) FROM orders"; var result = await cmd.ExecuteScalarAsync(ct); return Convert.ToInt64(result); }); var perShard = await Task.WhenAll(tasks); return perShard.Sum(); } } Program.cs using Microsoft.Extensions.Configuration; using Microsoft.Extensions.DependencyInjection; using Microsoft.Extensions.Hosting; using ShardingDemo; var builder = Host.CreateApplicationBuilder(args); // Bind Shards:[] from appsettings.json (override with user-secrets / env vars / Key Vault) var shardConfigs = builder.Configuration .GetSection("Shards") .Get<List<ShardConfig>>() ?? throw new InvalidOperationException("No 'Shards' section configured."); if (shardConfigs.Count == 0) throw new InvalidOperationException("At least one shard must be configured."); builder.Services.AddSingleton(_ => new ShardRouter(shardConfigs)); builder.Services.AddSingleton<UserRepository>(); using var host = builder.Build(); var repo = host.Services.GetRequiredService<UserRepository>(); var router = host.Services.GetRequiredService<ShardRouter>(); (long Id, string Email)[] users = { (1001, "ada@example.com"), (2002, "linus@example.com"), (3003, "grace@example.com"), (4004, "alan@example.com"), }; foreach (var (id, email) in users) { await repo.CreateUserAsync(id, email); Console.WriteLine($"user {id} -> shard {router.ShardForKey(id).Id}"); } await repo.AddOrderAsync(orderId: 9001, userId: 1001, amountCents: 4999); await repo.AddOrderAsync(orderId: 9002, userId: 1001, amountCents: 1299); await repo.AddOrderAsync(orderId: 9003, userId: 2002, amountCents: 8800); Console.WriteLine($"\nAda: {await repo.GetUserAsync(1001)}"); Console.WriteLine($"Ada's orders: {(await repo.GetOrdersForUserAsync(1001)).Count}"); Console.WriteLine($"\nTotal revenue across 3 shards: " + $"${await repo.TotalRevenueCentsAsync() / 100m:F2}"); await router.DisposeAsync(); Tracing One Request End to End Consider GetOrdersForUserAsync(1001): ShardForKey(1001) → MD5("1001") → first two bytes as a number → % 1024 → a bucket in the range 0..1023. bucket % 3 → a physical shard → for example mysql-shard-2.mysql.database.azure.com. The MySqlDataSource provides a pooled, TLS encrypted connection authenticated as shard2_admin. The query runs against shard 2's local ix_user index, with no fan out and at single server speed. Every call with userId = 1001, whether GetUser, AddOrder, or GetOrdersForUser, lands on the same shard. That is why orders JOIN users ON orders.user_id = users.user_id WHERE user_id = 1001 executes within a single shard, with no cross-shard traffic. Conclusion The essential point is this. Once a single primary can no longer absorb your write load, sharding becomes a durable answer, and implementing it at the application layer keeps every part of the system explicit and comprehensible. When write volume or dataset size outgrows a single primary, application layer sharding provides several benefits. N independent Azure Database for MySQL instances, each absorbing 1/N of the write traffic. Queries by user that remain on a single shard and behave like an ordinary, modestly sized database. A bucket map approach that allows you to add a fourth, fifth, or Nth shard later by relocating slices of data rather than rehashing the entire dataset. A failure of one shard that affects 1/N of your users rather than all of them. These benefits come at a genuine cost. You must generate identifiers in the application, global uniqueness requires a secondary lookup table, and aggregate queries fan out across shards. A cross shard write, one that must atomically update data on two different shards, can no longer rely on a single database transaction. Instead it needs an orchestrated sequence of local transactions, where each step carries a compensating action that undoes its effect if a later step fails. None of these are insurmountable. They are simply responsibilities you now assume. Sharding is a deliberate step to take only once a single primary has genuinely exhausted its write headroom. When you reach that point, the implementation in this post is a representative blueprint. Stay Connected We welcome your feedback and invite you to share your experiences or suggestions at AskAzureDBforMySQL@service.microsoft.com Thank you for choosing Azure Database for MySQL!230Views2likes0Comments
C# MIP SDK v1.17.x - AccessViolationException on creation of MIPContext in 64-bit console app
I first logged this on https://stackoverflow.com/questions/79746967/accessviolationexception-when-creating-mipcontext-after-upgrade-to-v1-17 and the responses there have indicated I should raise with Microsoft a a likely bug, but I don't see a clear route to reporting other than here so any response would be appreciated, even if just to direct me to the appropriate reporting location. I've built a simple console app that demonstrates this issue that I'm happy to provide but we're seeing an issue with the 1.17.x version of the C# MIP SDK where an AccessViolationException is being thrown when trying to create an MIP context object. This is for a .Net Framework 4.8 console app built in 64-bit configuration, deployed to a Windows Server 2016 with the latest VC++ redistributable (14.44.35211) installed (both x86 and x64 versions), though we've seen the same on Windows Server 2019 and 2022. When the same app is built in 32-bit and deployed to the same environment the exception doesn't occur. The following code is what I've used to repro the issue: MIP.Initialize(MipComponent.File); var appInfo = new ApplicationInfo { ApplicationId = string.Empty, ApplicationName = string.Empty, ApplicationVersion = string.Empty }; var diagnosticConfiguration = new DiagnosticConfiguration { IsMinimalTelemetryEnabled = true }; var mipConfiguration = new MipConfiguration(appInfo, "mip_data", LogLevel.Info, false, CacheStorageType.InMemory) { DiagnosticOverride = diagnosticConfiguration }; //Expect BadInputException here due to empty properties of appInfo //When built as part of a 64-bit console app this causes AccessViolationException instead MIP.CreateMipContext(mipConfiguration); The AccessViolationException crashes the console app, with the following logged in the Windows Event Log: Framework Version: v4.0.30319 Description: The process was terminated due to an unhandled exception. Exception Info: System.AccessViolationException at Microsoft.InformationProtection.Internal.SdkWrapperPINVOKE.MipContext_Create__SWIG_1(System.Runtime.InteropServices.HandleRef) at Microsoft.InformationProtection.Internal.MipContext.Create(Microsoft.InformationProtection.Internal.MipConfiguration) at Microsoft.InformationProtection.Utils.MIPHelper.CreateMipContext(Microsoft.InformationProtection.MipConfiguration) The issue doesn't occur with the latest 1.16 version (1.16.149) of the SDK but does appear to be in all versions of the 1.17 release. Library: C# MIP SDK v1.17.x Target App: .Net Framework 4.8 console app Deployed OS: Windows Server 2016, 2019 and 2022 (With .Net Framework 4.8 and latest VC++ redist installed)328Views0likes1CommentIntroducing AzureImageSDK — A Unified .NET SDK for Azure Image Generation And Captioning
Hello 👋 I'm excited to share something I've been working on — AzureImageSDK — a modern, open-source .NET SDK that brings together Azure AI Foundry's image models (like Stable Image Ultra, Stable Image Core), along with Azure Vision and content moderation APIs and Image Utilities, all in one clean, extensible library. While working with Azure’s image services, I kept hitting the same wall: Each model had its own input structure, parameters, and output format — and there was no unified, async-friendly SDK to handle image generation, visual analysis, and moderation under one roof. So... I built one. AzureImageSDK wraps Azure's powerful image capabilities into a single, async-first C# interface that makes it dead simple to: 🎨 Inferencing Image Models 🧠 Analyze visual content (Image to text) 🚦 Image Utilities — with just a few lines of code. It's fully open-source, designed for extensibility, and ready to support new models the moment they launch. 🔗 GitHub Repo: https://github.com/DrHazemAli/AzureImageSDK Also, I've posted the release announcement on the Azure AI Foundry's GitHub Discussions 👉🏻 feel free to join the conversation there too. The SDK is available on NuGet too. Would love to hear your thoughts, use cases, or feedback!209Views1like0CommentsIntroducing AzureSoraSDK: A Community C# SDK for Azure OpenAI Sora Video Generation
Hello everyone! I’m excited to share the first community release of AzureSoraSDK, a fully-featured .NET 6+ class library that makes it incredibly easy to generate AI-driven videos using Azure’s OpenAI Sora model and even improve your prompts on the fly. 🔗 Repository: https://github.com/DrHazemAli/AzureSoraSDK551Views0likes2Comments
Setting up Code Coverage data in Azure DevOps Pipeline, C# .NET 9
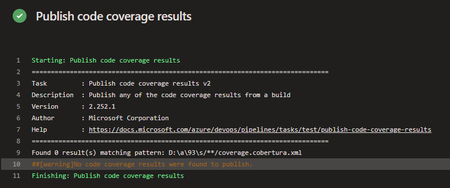
Hello everyone, I would like some assistance with my Azure DevOps pipeline. I am trying to set up Tasks in my Azure DevOps pipeline to collect Code Coverage results, after running UTs using the VsTest Task, to then have a Powershell Task in the Pipeline write to a SQL db the contents of those metrics. The main issue I am encountering is actually finding the published results after the UTs successfully run. I have set up Tasks to publish the results, then find them & then insert, but the publish doesn't seem to actually publish to the directory I specify, or if it does publish, I cannot see where to. Here are the Tasks I currently have set-up. Task to run UTs: steps: - task: VSTest@2 displayName: 'VsTest - testAssemblies' inputs: testAssemblyVer2: | **\$(BuildConfiguration)\*\*test*.dll !**\obj\** runSettingsFile: '$/B3API/Main/B3API.Tests/codecoverage.runsettings' runInParallel: true runTestsInIsolation: false codeCoverageEnabled: true platform: '$(BuildPlatform)' configuration: '$(BuildConfiguration)' failOnMinTestsNotRun: true codecoverage.runsettings file: <?xml version="1.0" encoding="utf-8"?> <RunSettings> <DataCollectionRunSettings> <DataCollectors> <DataCollector friendlyName="Code Coverage"> <Configuration> <Format>cobertura</Format> </Configuration> </DataCollector> </DataCollectors> </DataCollectionRunSettings> </RunSettings> Task to publish results: steps: - task: PublishCodeCoverageResults@2 displayName: 'Publish code coverage results' inputs: summaryFileLocation: '$(System.DefaultWorkingDirectory)/**/coverage.cobertura.xml' pathToSources: '$(System.DefaultWorkingDirectory)/**/coverage' Task to find published file & store into variable: steps: - powershell: | $coverageFile = "$(System.DefaultWorkingDirectory)/**/coverage.cobertura.xml" [xml]$coverageData = Get-Content $coverageFile $coveragePercentage = $coverageData.coverage.@line-rate # Store the coverage data in a variable Write-Host "##vso[task.setvariable variable=coveragePercentage]$coveragePercentage" displayName: 'Store Coverage in variable' The main issue it the Task to publish, it does not publish the results, I think it is due to not finding them in the first place. Thank you for taking the time to read my post, any help would be greatly appreciated, thanks!479Views0likes3Comments
Pet project on SQL Server 2022 platform
Hello, world! I would like to share my pet project on SQL Server 2022 platform. I have created a DWH solution that includes many MS's best practices and interesting features such us: ETL process with data cleansing and MDM that easy expand Documentation CI/CD Functional ETL test Ready analytical templates Time intelligence New & returning customers Cluster customers based on spending volume Product ABC classification Basket analysis Events in progress https://dev.azure.com/zinykov/NorthwindBI Unfortunately in SQL Server 2025 will be no DQS & MDS...113Views0likes0Comments