azure monitor
1352 Topics
Azure VMs host (platform) metrics (not guest metrics) to the log analytics workspace ?
Hi Team, Can some one help me how to send Azure VMs host (platform) metrics (not guest metrics) to the log analytics workspace ? Earlier some years ago I used to do it, by clicking on “Diagnostic Settings”, but now if I go to “Diagnostic Settings” tab its asking me to enable guest level monitoring (guest level metrics I don’t want) and pointing to a Storage Account. I don’t see the option to send the these metrics to Log analytics workspace. I have around 500 azure VMs whose host (platform) metrics (not guest metrics) I want to send it to the log analytics workspace.253Views0likes3CommentsUnderstanding billing for the Azure Copilot Observability Agent
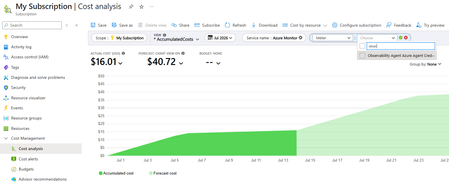
The Azure Copilot Observability Agent brings an agentic investigation experience directly into Azure Monitor. Teams can chat with their observability data, run deep investigations across application and infrastructure signals, and, in preview, use autonomous operations to correlate alerts and create issues for review. The common thread across these experiences is that the agent performs AI work on behalf of the user or configured workflow, and that work has a cost. Azure Copilot Observability Agent billing went into effect July 1, 2026. This post explains the billing model at a practical level: what is measured, which agent operations are billable today, how usage appears to users, and how this differs from the standard Azure Monitor costs customers already manage for telemetry ingestion, retention, alerting, and other monitoring capabilities. For current list pricing and the most detailed billing guidance, always refer to the official billing documentation and the Azure Monitor pricing page. A consumption-based model for agentic work The Observability Agent uses a consumption-based pricing model: customers pay for the AI work the agent performs. This consumption is measured in Azure Agent Credits, or AAC. AAC provides a consistent unit for agent work across models and tokens used. AAC is designed to reflect the amount of agentic processing required to complete a task. Simple questions, such as "what was the maximum latency of this app yesterday?", typically use few tokens. A deep investigation consumes more agent and tool work, and therefore typically incurs higher cost. Note that a single agent operation - be it a chat question or a deep investigation - is currently capped at 500 AACs. Charges are scoped to the Azure subscription of the monitored resource, or to the subscription of the named agent instance if one is used (required for autonomous operations). This keeps the cost associated with the environment where the agent is being used, and lets teams review agent consumption alongside other subscription-level Azure costs. What is billable today There are three main usage patterns to understand. Chat - the agent's chat allows users to explore and analyze their observability data through natural-language questions about their Azure resources and their logs, metrics, traces, or related telemetry, and the agent performs the work needed to answer. This is typically the lowest-cost pattern because the scope is often focused and iterative. Deep investigation - can be initiated through a number of entry points in the Azure Portal, and also through the chat (users can tell the agent to run a deep investigation). A deep investigation performs a broader analysis - it gathers signals, correlates findings, reasons across application, infrastructure, and Azure platform context, and produces an investigation report. Because this workflow runs multiple agent and tool steps, it typically consumes more AAC than chat. Autonomous operations are currently in preview. Autonomous alert processing, triage and optional correlation can run in the background to group related alerts and reduce noise. Alert correlation itself isn’t billed during preview. If autonomous operations automatically run a deep investigation on an agent-created issue, that deep investigation is billable. This is an important distinction: preview correlation and issue creation are different from the investigation work that may be triggered as part of that flow. How users see usage in the product Cost transparency is part of the experience. After the agent returns a response in chat, users can open the usage indicator (hexagon-shaped icon) located next to the thumbs-up/down icons, to see how many AACs were used to generate that response. This makes consumption visible at the point where the user sees the value of the answer, rather than only later in a billing report. This is especially useful because not all agent interactions are equal. A short question that summarizes a recent trend can require much less agent work than a long-running investigation that reviews multiple signals and hypotheses. Showing AAC usage per response helps users understand that relationship and adjust how they use the agent when needed. How costs appear in Azure Cost Management Teams can review the overall agent cost in subscription Cost Management. The product name appears as Azure Monitor Observability Agent, and the meter name appears as Observability Agent Azure Agent Credits. This gives admins a familiar place to monitor consumption. The agent cost is not a replacement for standard Azure Monitor charges. Existing Azure Monitor costs — such as logs ingestion, retention, alerting, web tests, and other metered monitoring capabilities — continue to follow their own billing models. Through Cost Analysis smart views, such as Services, users can select the Azure Monitor service and review specific entries of the Azure Monitor Observability Agent. Practical guidance for teams Start by using chat for focused exploration: ask about trends, errors, performance, anomalies, or a specific resource. Use deep investigations when you need a broader, multi-signal analysis of an incident or suspected root cause. Review the AAC usage shown after agent responses so users can build intuition about which prompts stay lightweight and which workflows require deeper analysis. Use Azure Cost Management to monitor the subscription-level cost of agent usage, and keep the Observability Agent cost distinct from standard Azure Monitor telemetry costs such as logs ingestion, retention, alerting, and web tests. For current pricing details, billable behavior, and any updates to what is billed in preview or GA experiences, use the official billing documentation as the source of truth. Coming up... Looking ahead, we plan to introduce billing caps for the Observability Agent, giving customers greater control over monthly token consumption, capacity usage, and overall costs. Learn more Billing and cost management for Azure Copilot Observability Agent Azure Copilot Observability Agent overview Chat with your observability data Deep investigations in the Azure Copilot Observability Agent Autonomous operations in the Observability Agent Azure Monitor pricing We’d love your feedback The Observability Agent continues to evolve based on real-world usage and operator feedback. Share feedback through the Give Feedback option in the product, or reach us at noakuper@microsoft.com.558Views0likes1CommentAnnouncing new security, maintenance and analytics features for PostgreSQL at Microsoft Build 2026
At Microsoft Build 2026, we’re announcing a major wave of PostgreSQL innovation across Azure. Alongside the public preview of Azure HorizonDB, we’re delivering a broad set of enhancements for our fully managed open-source PostgreSQL service: Azure Database for PostgreSQL flexible server. These updates span performance, analytics, security, operations, resilience and migration - helping you build faster, operate with more control, secure your workloads, and modernize with confidence. Here’s a quick tour of the top flexible server announcements at Build 2026. Feature Highlights pg_ivm Extension Defender Security assessments temporal_tables Extension Cross-tenant CMK Automatic Entra token refresh libraries New Powershell module: Az.PostgreSQLFlexibleServer More control over planned maintenance Pre-Upgrade validation checks New Built-in Grafana dashboards Chaos Studio supports Azure Database for PostgreSQL AI-assisted Oracle to PostgreSQL migration Migration Service for Azure Database for PostgreSQL improvements (EDB, AlloyDB) Performance, Scale & Analytics pg_ivm Extension Generally Available Materialized views are a useful way to optimize performance for queries that run regularly, but if underlying data becomes stale the result set needs to be recomputed. With the pg_ivm extension you can automatically maintain materialized views as the underlying data changes. This is particularly valuable for large datasets with small incremental changes that need real-time freshness, like dashboards, catalog analytics and SaaS usage reporting. We are pleased to announce the pg_ivm extension is now generally available in Azure Database for PostgreSQL. Learn more: pg_ivm. Security, Auditing & Identity Defender security assessments Preview Microsoft Defender Security Assessments for Azure Database for PostgreSQL enables continuous evaluation of your database security posture, helping identify vulnerabilities and misconfigurations across server and database configurations. Previously limited to reactive threat detection, in the latest preview release, Defender now provides proactive, risk-based insights through assessments tailored to PostgreSQL-specific best practices, delivering more relevant and actionable guidance. This helps you strengthen your security baseline, prioritize remediation, and align with best practices and compliance requirements. Learn more: https://aka.ms/Defender-Assessments-for-PG-Preview temporal_tables Extension Generally Available We’ve had many customer requests to support the temporal_tables extension, which provides built-in support for tracking and querying historical changes to data over time. Temporal tables are now generally available in Azure Database for PostgreSQL. With this extension enabled you can easily perform time-based queries, audit data changes, and maintain historical records without building custom tracking logic, simplifying application development and compliance scenarios. Learn more: temporal_tables Cross-tenant CMK Preview Azure Database for PostgreSQL now supports cross-tenant customer-managed keys (CMK) in public preview, allowing you to encrypt your data at rest using an Azure Key Vault key that resides in a separate Microsoft Entra tenant from the database service. This feature is designed for SaaS providers and enterprises that need to maintain strict separation of duties and ownership of encryption keys, enabling you to retain full control over key lifecycle management while PostgreSQL runs in a service provider’s tenant. Learn more: Data encryption at rest in Azure Database for PostgreSQL Automatic Entra token refresh libraries Preview We’re making it easier to use Entra ID authentication with Azure Database for PostgreSQL throughout the application stack by introducing new token refresh libraries for .NET, JavaScript, and Python. With Entra ID, access tokens are short-lived which can make managing their lifecycle complex in real-world applications. Developers need to be aware of token refresh and build additional handling around token expiration, connection retry, and session continuity. These new libraries remove that friction. By handling Entra token refresh seamlessly in the background, they allow applications to stay connected without interruption and with no custom logic required. The result is a simpler development experience and more resilient applications, especially for long-running or connection-heavy workloads. Across languages, the libraries provide a consistent and streamlined way to adopt secure, passwordless authentication, helping teams focus more on building their applications and less on managing authentication. Learn more: .NET, JavaScript, and Python. Operations, Maintenance & Monitoring New Powershell module: Az.PostgreSQLFlexibleServer Generally Available We’re excited to introduce the newly renamed Az.PostgreSQLFlexibleServer PowerShell module, delivering a streamlined experience for managing Azure Database for PostgreSQL with PowerShell. Building on the capabilities of the previous Az.PostgreSql module, the updated module aligns with the new features in the 2026-01-01 preview REST API. This module brings support for PostgreSQL 18, elastic clusters for scalable workloads and a range of enhancements designed to simplify management and improve performance. Whether you're provisioning new deployments or managing complex environments, this module ensures you can take full advantage of the latest platform capabilities directly from PowerShell. To learn more, visit our official documentation on PowerShell: Az.PostgreSql Module | Microsoft Learn More control over planned maintenance Generally Available We’ve seen many requests to provide more control when a maintenance update is applied to Azure Database for PostgreSQL. Sometimes when a critical workload is running you want to apply the maintenance when you’re ready. Announcing general availability this week, we’re building on the existing System and Custom maintenance window options and adding new self-service maintenance capabilities to the Azure portal. You can now reschedule upcoming maintenance updates for up to two weeks and apply maintenance on demand at a time that suits you. You can also view scheduled maintenance and review your server’s maintenance history after updates are complete. These options help you better align maintenance with your business schedules, reduce disruption during critical workload periods, and minimize the need for support-driven deferral requests. CLI and API support are coming soon. Learn more: https://aka.ms/azure-postgres-reschedule-maintenance Pre-Upgrade validation checks Preview Major version upgrades are critical for staying current with PostgreSQL features, security updates, and performance improvements, but you often discover blockers only after starting the upgrade workflow. Pre-Upgrade Validation Checks lets you validate upgrade readiness before initiating the actual upgrade by running Azure-specific upgrade checks and PostgreSQL pg_upgrade --check validations independently. The shift is simple: you can identify and fix upgrade blockers before the upgrade window begins. The feature surfaces actionable issues across configurations, extensions, dependencies, replication slots, event triggers, and other upgrade-sensitive objects. You can fix blockers, re-run validation until all checks pass, and proceed with the upgrade with greater predictability. Learn more: https://aka.ms/pg-flex-upgrade-checks New Built-in Grafana dashboards Generally Available Grafana dashboards are now built directly into the Azure portal for Azure Database for PostgreSQL - no setup, no extra cost, and no separate service to manage. You can open your PostgreSQL resource in the portal and immediately access prebuilt dashboards for key health and performance signals such as CPU, memory, storage, IOPS, connections, transactions, and availability. The key value is metrics + logs in one place. You can quickly correlate performance spikes with PostgreSQL logs, understand what changed, and troubleshoot faster using the familiar Grafana experience. Dashboards can also be customized, saved to your subscription, and shared across teams for ongoing operations. Learn more: https://aka.ms/azure-postgres-dashboards-grafana Resilience & Business Continuity Chaos Studio supports Azure Database for PostgreSQL Preview No matter how much you prepare, you only really know how good your database disaster recovery plan is when something breaks. With Chaos Studio support for Azure Database for PostgreSQL, you can simulate zone-down scenarios on PostgreSQL HA-enabled instances and validate the resilience of your mission-critical workloads. With Chaos Studio integration, you can proactively test failover behavior and gain confidence in how your applications respond to real-world zonal failures. This feature is currently available through a gated private preview. To get started, submit your subscription details using the form. Once reviewed, our team will enable the feature for your subscription, with guidance to help you begin testing. Getting started is simple: Create a Chaos Studio workspace via the Chaos Studio portal and configure your subscription, resource group, and region. Define the scope and assign the required managed identity and permissions. Review and verify your workspace setup. Browse available scenarios and select the PostgreSQL zone-down scenario. Configure the test (name, duration), then run it from My Library to begin validating failover behavior. With just a few steps, you’ll be able to simulate real-world failure conditions and gain confidence in your application’s resilience. To get started, please submit your details using this link: Private Preview Support for Chaos Studio Migration & Modernization AI-assisted Oracle to PostgreSQL migration Generally Available AI-assisted migration tooling has dramatically lowered the bar for moving between different databases and is changing the way people look at the return on investment for migration. The VS Code PostgreSQL extension comes with AI-Assisted migration tooling which converts Oracle schema and application code to Azure Database for PostgreSQL. This tooling uses GitHub Copilot, Microsoft Foundry, and custom Language Model tools to convert Oracle schema, database code and client applications into the PostgreSQL equivalents, and validates every change against a running flexible server instance. Learn more: Schema conversion, App conversion. Migration Service for Azure Database for PostgreSQL improvements (EDB, AlloyDB) Generally Available We’ve added AlloyDB and EDB Extended Server as new sources for migrating to PostgreSQL in the Azure Database for PostgreSQL Migration Service, with support for both online and offline migration support. Learn more: Migrate from AlloyDB, Migrate from EDB. Looking ahead That wraps up the Build 2026 announcements for Azure Database for PostgreSQL flexible server. There are also many great PostgreSQL technical sessions at Build this week, covering cloud-native app & AI development and migration. To find out more, here's a link to the Build session catalog for PostgreSQL sessions: https://aka.ms/Postgres-on-Azure_Build-2026. We'll continue to build out our roadmap over the coming months to deliver on your asks to improve the performance, security and stability of your PostgreSQL workloads. Check the Microsoft Blog for PostgreSQL for a regular monthly recap where we share the latest enhancements and product updates.1.5KViews2likes0CommentsGoverning Log Analytics retention at scale
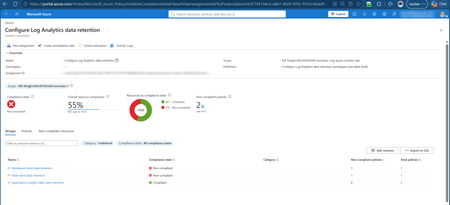
A Log Analytics workspace stores its data in tables, and data retention can be configured at two levels: Workspace level: a default interactive (Analytics) retention that applies to the whole workspace (30–730 days). Table level: each table has its own Analytics retention and its own total retention (Analytics + long-term/archive). By default a table's Analytics retention is set to "Workspace default", i.e. it inherits the workspace value. Two ideas are worth keeping in mind: Analytics vs. long-term (archive) retention. Analytics retention is the "hot", fully queryable period. Beyond that, data can be kept in cheaper long-term retention for compliance, and restored or searched when needed. See Manage data retention in a Log Analytics workspace. Tables can be configured individually: instead of configuring retention on the highest level, the workspace, this can also be done at a table level. The cost optimization opportunity Here's a concrete, very common scenario. A customer needs to retain data for 2 years. The typical reaction: set the workspace retention to 730 days. The catch: because every table's Analytics retention defaults to "Workspace default", this quietly sets the interactive (Analytics) retention of all tables to two years. Analytics retention is the expensive tier; so in many cases this drives up storage cost significantly, for data that nobody queries interactively after the first few weeks. A more cost-effective pattern is usually: Keep the workspace default retention low (for example 30 or 90 days - depending whether Sentinel and/or Application Insights are enabled). Set each table's Analytics retention to what it actually needs interactively (often 30–90 days). Use long-term (non-interactive) retention at the table level where you genuinely need to keep data longer (e.g. 2 years) for compliance, at a fraction of the Analytics cost. With a maximum of 12 years of retention. The result is the same "keep data for 2 years" outcome, but only the data you actually query interactively sits in the expensive tier. The governance opportunity Configuring this once in the portal is straightforward. The real win is making it consistent, scalable, and self-maintaining - and that's very achievable with the right approach: A single workspace can expose hundreds to well over a thousand tables, so a repeatable, automated method pays off quickly. With a central definition of your target retention model, you can apply it uniformly across many workspaces and subscriptions. Add drift detection and you'll always know when a table's retention changes - and can bring it back automatically. In other words, retention governance is a great candidate for policy-driven automation. To make it easy, I built a reusable solution and open-sourced it. The solution: law-retention-guardrails Repository: claestom/law-retention-guardrails The solution is Azure Policy, end to end. Two custom policy definitions, grouped into one initiative, both using the DeployIfNotExists effect: Definition Target What it sets Workspace retention Microsoft.OperationalInsights/workspaces the workspace default analytics retention Table retention Microsoft.OperationalInsights/workspaces/tables per-table analytics and total retention Because it's DeployIfNotExists, the policy does both jobs at once: Audit: Azure Policy → Compliance shows every workspace and table whose retention drifts from your target, fleet-wide. Remediate: new and updated resources are configured automatically, and a remediation task brings existing workspaces and tables into compliance. The assignment's managed identity (granted Log Analytics Contributor) performs the change. Keeping the free 90 days: Sentinel & Application Insights One nuance worth calling out. Enabling Microsoft Sentinel on a workspace, or using workspace-based Application Insights, grants 90 days of interactive (analytics) retention for free. A blanket 30-day target would throw that away. Application Insights is handled for you. The initiative ships a dedicated third policy that targets exactly the 11 workspace-based App Insights tables (AppRequests, AppDependencies, AppExceptions, AppTraces, ...). The general table policy excludes those same tables, so the two never overlap: a single assignment governs everything, with App Insights keeping its own values (appInsightsRetentionInDays / appInsightsTotalRetentionInDays, defaulting to 90 / 90) while the rest of your tables sit at the baseline. No second assignment, no wildcard juggling. Sentinel is a scope split. Sentinel's free 90 days apply at the workspace level, which the table exclusions don't cover. Since Sentinel usually lives in a dedicated workspace or resource group, assign 90-day values there and carve that scope out of the baseline with -NotScopes. Keep any such extra assignments mutually exclusive, two DeployIfNotExists assignments that both match the same resource will fight over it. How to deploy You need rights to create policy and role assignments at the target scope (e.g. Owner). Pick one of two paths. Option A: One click The repo ships a Deploy to Azure button backed by a subscription-scoped ARM template. It creates the three definitions, the initiative, the assignment (with a managed identity), and the Log Analytics Contributor role assignment — then you fill in the retention values in the portal form. You can optionally scope the assignment to a single resource group right in the form. Option B: The deploy script git clone https://github.com/claestom/law-retention-guardrails.git cd law-retention-guardrails ./deploy.ps1 -SubscriptionId <sub-id> ` -WorkspaceRetentionInDays 30 ` -TableRetentionInDays 30 ` -TableTotalRetentionInDays 730 ` -AppInsightsRetentionInDays 90 ` -AppInsightsTotalRetentionInDays 90 That single command creates the definitions and initiative, assigns it with a system-assigned managed identity, grants the identity Log Analytics Contributor, and starts a remediation task to fix existing resources. Scope it as narrowly or broadly as you like: # A management group ./deploy.ps1 -ManagementGroupId <mgId> # A single resource group ./deploy.ps1 -SubscriptionId <sub> -ResourceGroupName rg-monitoring # A single Log Analytics workspace ./deploy.ps1 -SubscriptionId <sub> ` -Scope /subscriptions/<sub>/resourceGroups/<rg>/providers/Microsoft.OperationalInsights/workspaces/<workspace> Prefer the portal? Paste each definition's azurepolicy.portal.json into Policy → Definitions → + Policy definition, then assign at the scope you want with a managed identity and a remediation task. A note on valid retention values Azure accepts these total retention values: 4–730 days, and beyond two years only full years: 1095, 1460, 1826, 2191, 2556, 2922, 3288, 3653, 4018, 4383. The solution validates this up front so you get a clear message instead of per-table errors. (Note: Basic/Auxiliary plan tables have a fixed analytics retention and will always report non-compliant - exempt them or treat as noise.) Wrapping up Configuring retention per table, keeping the workspace default low, trimming interactive retention, and pushing long-lived data into cheaper long-term retention, can meaningfully reduce Azure Monitor cost while still meeting compliance requirements. With law-retention-guardrails, that model is enforceable and auditable across your whole environment using nothing but Azure Policy: it tells you where you stand and fixes drift, with no Automation Account to run. I'd love your feedback and contributions on the repository. Resources Manage data retention in a Log Analytics workspace | Microsoft Learn Log Analytics workspace overview | Microsoft Learn Azure Policy documentation | Microsoft Learn Remediate non-compliant resources with Azure Policy | Microsoft Learn Azure Policy DeployIfNotExists effect | Microsoft Learn claestom/law-retention-guardrails (GitHub) Thank you!459Views2likes0CommentsLog Insights in Minutes: A Simpler pgBadger Workflow
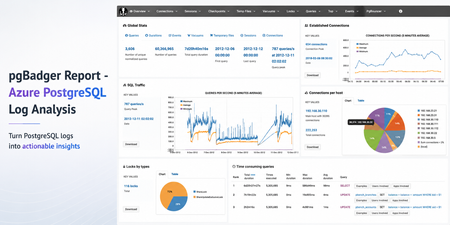
Sometimes the fastest way to understand a PostgreSQL workload is not another dashboard. It is a good log report. pgBadger is a PostgreSQL log analysis tool that turns raw PostgreSQL logs into an interactive HTML report. It helps summarize query activity, connection patterns, errors, temporary files, lock waits, autovacuum activity, and more. Earlier guidance for generating pgBadger reports from Azure Database for PostgreSQL Flexible Server focused on exporting logs through Diagnostic Settings, storing them in a storage account, and then using tools such as BlobFuse and jq to extract PostgreSQL log lines from JSON files. That workflow is still useful when customers centralize logs across multiple servers. However, if you are already using the Server logs feature in Azure Database for PostgreSQL Flexible Server, there is a much simpler path. In this post: You’ll learn how to generate a pgBadger HTML report from Azure Database for PostgreSQL Flexible Server by downloading native PostgreSQL .log files directly from the Azure portal. No storage account, BlobFuse mount, or JSON extraction required. Fast path Configure log_line_prefix . Enable Server logs for download. Download the PostgreSQL .log files. Run pgBadger with the matching prefix. Open pgbadger-report.html . Why use this workflow? With Server logs, you can download native PostgreSQL .log files directly from the Azure portal and run pgBadger locally. Older path Simpler path in this blog Diagnostic Settings → Storage account → BlobFuse → JSON extraction → pgBadger Server logs → Download .log files → pgBadger Area Older Diagnostic Settings workflow Server logs workflow Export path Diagnostic Settings to storage account Download .log files directly from the portal Format JSON payloads need extraction Native PostgreSQL .log files Extra tooling BlobFuse and jq JSON parsing None Best suited for Centralized or multi-server logging Quick per-server analysis Outcome Flexible, but more setup Faster path to pgBadger Recommended: Use the Server logs workflow when you want a fast, low-friction way to generate a pgBadger report from one Azure Database for PostgreSQL Flexible Server. When should you use this workflow? Use this workflow when... Use Diagnostic Settings when... You need a quick report for one Flexible Server. You centralize logs from many servers. You want to run pgBadger locally. You need long-term retention or workspace-level querying. You want to avoid JSON extraction. You already have automated log export pipelines. Before you start A machine where you can install or run pgBadger. A working Perl runtime. Git Bash on Windows, so the multi-line shell commands work as shown. Portal access to your Azure Database for PostgreSQL Flexible Server. Permission to update server parameters and enable Server logs. Important: pgBadger can only analyze what PostgreSQL logs capture. To populate query timing and slow-query sections in the report, enable log_min_duration_statement before collecting logs. Logs collected before that change will not include duration data. Workflow overview Task Type Rough effort Install or prepare pgBadger One-time setup per analysis machine 5–10 minutes Configure log_line_prefix One-time setup per server 2–3 minutes Enable Server logs One-time setup per server 2–3 minutes Download logs and run pgBadger Repeatable 2–5 minutes Install or prepare pgBadger on the machine where you will analyze logs. Configure log_line_prefix so pgBadger can parse each log line. Enable Server logs, so PostgreSQL logs are available for download. Download the logs and run pgBadger locally. 💡Pro tip: Start with a narrow log window first. Use one or two hourly log files, confirm the report looks right, and then expand the analysis window if needed. Step 1: Install pgBadger Before generating a report, you need pgBadger available on the machine where you plan to analyze the downloaded PostgreSQL log files. Run this on a Linux VM, WSL, or another Linux-based environment where you can install packages. Note: Azure Cloud Shell may work for quick testing, but package installation and build-tool availability can vary by session. For repeatable analysis, use a Linux VM, WSL, or another environment you control. Copy and run sudo apt-get update && sudo apt-get install -y git perl make gcc && \ git clone https://github.com/darold/pgbadger.git && \ cd pgbadger && \ perl Makefile.PL && \ make && \ sudo make install && \ pgbadger -V What good looks like: The install command completes successfully and pgbadger -V returns the installed pgBadger version. Step 2: Configure log_line_prefix This is a one-time server configuration step. The log_line_prefix parameter controls the beginning of each PostgreSQL log line. pgBadger uses this prefix to extract useful fields such as timestamp, user, database, and process ID. In the Azure portal, open your Flexible Server and go to Server parameters. Search for: Parameter log_line_prefix Set this value %m user=%u db=%d pid=%p: Then select Save. In Server parameters, confirm that the custom value is saved for log_line_prefix . Figure 1: Set log_line_prefix so pgBadger can correctly parse timestamp, user, database, and process ID from each log line. Prefix tokens Token Meaning %m Timestamp with milliseconds %u Username %d Database name %p Process ID After this change, log lines should look like this: Example log line 2026-06-22 19:00:00.070 UTC user=pgadmin db=highcpu pid=3805603: LOG: statement: SELECT 1 FROM pg_extension WHERE extname='pg_stat_statements' The matching pgBadger prefix for this log format is: Matching pgBadger prefix %m user=%u db=%d pid=%p: You will use this same value later in the pgBadger command. What good looks like: The server parameter is saved, and new PostgreSQL log lines begin with timestamp, user, database, and process ID fields that match the pgBadger prefix. Step 3: Enable Server logs for download This is also a one-time setup step. In the Azure portal, open your Flexible Server and go to Server logs. Enable: Portal setting Capture logs for download Set the retention period based on how long you want logs to remain available for download. For example, a 7-day retention period keeps logs available for download for 7 days. In Server logs, enable Capture logs for download and choose the retention window. Figure 2: Enable Capture logs for download and set a retention period long enough to cover the analysis window you want to inspect. What good looks like: After Server logs are enabled, hourly PostgreSQL log files appear in the Server logs blade and can be downloaded from the Azure portal. Once enabled, hourly log files appear in the Server logs blade. The files are named by date and hour, for example: Example log files postgresql_2026_06_22_19_00_00.log postgresql_2026_06_22_20_00_00.log Step 4: Download and organize the logs locally From the Server logs page, select the .log files for the time window you want to analyze and download them. For example, to analyze activity between 19:00 and 21:00 UTC, download: Example files to download postgresql_2026_06_22_19_00_00.log postgresql_2026_06_22_20_00_00.log On your local machine, create a folder for that analysis window. A simple convention is to use the Mon-DD format. Folder name Jun-22 Place the downloaded .log files inside that folder. Your local folder structure should look like this: Folder structure pgbadger-13.1/ pgbadger Jun-22/ postgresql_2026_06_22_19_00_00.log postgresql_2026_06_22_20_00_00.log Step 5: Generate the pgBadger report Open Git Bash from the folder where pgBadger is located. For example, if pgBadger is inside the pgbadger-13.1 folder, open Git Bash from that folder. # Action Command 1 Set the folder FOLDER=Jun-22 2 Confirm files ls -lh ./$FOLDER 3 Run pgBadger Use the full command below. Copy and run FOLDER=Jun-22 ls -lh ./$FOLDER perl -X ./pgbadger -f stderr \ --prefix '%m user=%u db=%d pid=%p:' \ ./$FOLDER/*.log \ -o ./$FOLDER/pgbadger-report.html Command breakdown Part of command Purpose perl -X ./pgbadger Runs pgBadger and suppresses non-critical Perl warnings. -f stderr Parses PostgreSQL stderr log files. --prefix '%m user=%u db=%d pid=%p:' Matches the log_line_prefix set on the server. ./$FOLDER/*.log Analyzes every .log file in the selected folder. -o ./$FOLDER/pgbadger-report.html Writes the HTML report into the same folder. When the command completes successfully, you should see output like this: Expected output Parsed 12134249 bytes of 12134249 (100.00%), queries: 26684, events: 83 LOG: Ok, generating html report... What good looks like: pgBadger finishes parsing the logs and creates pgbadger-report.html in the selected folder. Step 6: Open the report Open the generated report: Copy and run start ./$FOLDER/pgbadger-report.html The report opens in your default browser. The final report is created here: Generated report path Jun-22/pgbadger-report.html What the report can show The pgBadger report gives you a quick view into the workload shape for the selected log window. For example, in a sample run across two hourly log files, pgBadger summarized: Total number of queries. Number of unique normalized queries. Query traffic over time. Events such as errors and fatal messages. Session and connection patterns. Once the report opens, start with Global Stats to confirm the time range, total queries, normalized queries, and query peak. Figure 3: Start with Global Stats to validate the selected time range, total query count, normalized query count, and query peak. Query volume and normalized queries Many raw queries can often reduce to a smaller number of normalized query patterns. This helps identify whether the workload is spread across many different query shapes or dominated by a smaller set of repeated statements. Example: In this sample run, 26,684 queries reduced to 59 normalized query shapes. That suggests the workload is mostly a small set of repeated statements, which can help focus tuning effort. Traffic patterns The SQL Traffic section helps identify spikes, quiet periods, and workload changes over time. Figure 4: Use SQL Traffic to identify query spikes, quiet periods, and workload changes during the selected log window. Figure 5: Review the query breakdown to compare read vs. write volume and query-type distribution for the selected Server logs window. For example, if the report shows a steady baseline followed by a sharp spike, that spike can be correlated with application activity, batch jobs, synthetic tests, or operational events during the same time window. Query duration If query duration shows 0 ms or the slow query sections are empty, it usually means duration logging was not enabled when the logs were collected. In that case, pgBadger can still show query counts and events, but it cannot calculate the slowest queries, total execution time, average duration, or maximum duration. To unlock those timing sections, enable log_min_duration_statement , collect fresh logs, and rerun pgBadger. What pgBadger cannot infer from missing logs pgBadger reports are only as complete as the log data you provide. If PostgreSQL did not log duration, lock waits, temporary files, or autovacuum activity during the selected time window, pgBadger cannot reconstruct those details later. To analyze... Enable before collecting logs Slow queries log_min_duration_statement Lock waits log_lock_waits Temporary files log_temp_files Autovacuum activity log_autovacuum_min_duration Repeatable copy/paste block Reusable command block Change only FOLDER for each new analysis window. Copy and run FOLDER=Jun-22 ls -lh ./$FOLDER perl -X ./pgbadger -f stderr \ --prefix '%m user=%u db=%d pid=%p:' \ ./$FOLDER/*.log \ -o ./$FOLDER/pgbadger-report.html start ./$FOLDER/pgbadger-report.html For another date, change only this line: Update this value FOLDER=Jun-22 Examples: Example folder values FOLDER=Jun-23 FOLDER=Jul-01 FOLDER=Aug-15 Optional: Improve report quality pgBadger can only analyze the information captured in PostgreSQL logs. The default logs may be enough for query frequency, connection activity, and errors. For deeper performance troubleshooting, consider enabling additional logging parameters based on your scenario. Scenario Parameter Suggested value Notes Slow query analysis log_min_duration_statement 1000 Logs statements slower than 1 second. Short controlled test log_min_duration_statement 0 Logs every statement. Use carefully. Lock troubleshooting log_lock_waits on Helps identify lock waits. Temporary file analysis log_temp_files 0 Logs all temporary files. Autovacuum visibility log_autovacuum_min_duration 0 Useful during focused analysis. Useful parameters include: Recommended logging parameters log_lock_waits = on log_temp_files = 0 log_autovacuum_min_duration = 0 To capture query durations, configure: Duration logging log_min_duration_statement = 1000 This logs statements that run longer than 1000 milliseconds. For short test runs, you can temporarily use: Short test run only log_min_duration_statement = 0 Caution: Use log_min_duration_statement = 0 carefully on busy production servers. It logs every statement and can generate a large volume of logs. Duration matters: If duration logging is not enabled, pgBadger can still show query counts and events, but slowest-query, total duration, average duration, and maximum duration sections will be limited or empty. Common mistakes and quick fixes Symptom Likely cause Fix Report is empty Prefix mismatch Match --prefix with log_line_prefix . No duration data Duration logging was not enabled Set log_min_duration_statement before collecting logs. No files visible Server logs disabled or retention expired Enable capture and check retention. pgBadger command fails pgBadger is not in the current folder or path Run pgbadger -V to confirm installation. Common troubleshooting FAQs 1. Report is created but empty This usually means the pgBadger prefix did not match the actual log format. Check the first few lines: Copy and run head -5 ./$FOLDER/*.log Make sure the pgBadger --prefix matches the server’s log_line_prefix . 2. Report shows queries but no duration PostgreSQL logged statements but did not log durations. Enable one of the following, collect fresh logs, and rerun pgBadger: Parameter options log_min_duration_statement = 1000 # or temporarily for testing log_min_duration_statement = 0 3. No .log files are visible Confirm that Server logs are enabled: Portal setting Capture logs for download Also check the retention period. If the retention period has expired, older logs may no longer be available for download. 4. pgBadger command fails Confirm that pgBadger is available in the current folder or installed in your path. Copy and run pgbadger -V If you are running pgBadger from the local folder, use: Copy and run perl -X ./pgbadger Summary For customers already using Azure Database for PostgreSQL Flexible Server logs, the pgBadger workflow is straightforward: Install pgBadger. Configure log_line_prefix . Enable Server logs for download. Download the .log files. Place them in a local date-based folder. Run pgBadger with the matching prefix. Open pgbadger-report.html . Bottom line: Server logs give you the shortest path from Azure Database for PostgreSQL Flexible Server logs to a pgBadger report. Download the native .log files, run pgBadger with the matching prefix, and open the generated HTML report. References pgBadger - source and documentation GitHub pgBadger - project site Azure - Download server logs from the portal Flexible Server Azure - Logging concepts Flexible Server Azure - Configure server parameters via the portal PostgreSQL - log_line_prefix and logging parameters545Views2likes0CommentsAzure Monitor Health Model (Preview): What's New!
Azure Monitor Health Model is a modern observability capability that brings together telemetry, architecture, and business context of your workloads to generate health insights. It continuously aggregates signals across dependencies, producing a single, actionable health state which reduces alert noise and shifts team toward proactive operations with cohesive system view, clearer insights, and faster troubleshooting. It addresses the common operation question 'Is my system/service/app healthy?' and 'Which underlying unit / component is impacting health?' This refresh introduces flexible, workload-centric discovery (use application insights topology, Azure resource graph queries in addition to designing user and system flows) and smarter, faster health signal creation (use recommended signals, import existing alert rules, set dynamic thresholds). Expanded Discovery Scope As customers began modeling increasingly complex applications, we identified an opportunity to make discovery more flexible and intuitive. Teams naturally reason about their systems differently; some at the application level, others through infrastructure fleets or telemetry views. By expanding discovery options, we enable customers to build health models using the constructs they already use, making it easier to evolve health models as applications and architectures change. Azure Monitor health models now support multiple discovery mechanisms: Application Insights–based discovery for application-centric modelling Azure Resource Graph (ARG) discovery for scalable, query-based resource selection Continued support for Service Groups, now including nested Service Groups, as part of a broader set of discovery options This evolution reflects a shift toward loosely coupled modelling, enabling customers to define health based on application architecture rather than infrastructure-centric grouping. Learn more about Discovery Extended Health Signals Our goal has been to help customers achieve meaningful health insights faster with less manual effort. By introducing platform defaults and surfacing recommended signals, we make it easier to align health models with proven Azure best practices from day one. At the same time, we preserve support for existing alerting strategies and investments, ensuring customers can extend rather than replace what they already have. These enhancements balance simplicity, guidance, and flexibility as environments scale. Health Models now supports the following health signal capabilities: Resource Health as a default signal, ensuring every model starts with a reliable platform-provided baseline Recommended signals, automatically surfaced based on Azure service best practices and enhanced through Azure Monitor Baseline Alerts (AMBA) integration Reuse of existing signals, enabled by importing Azure Monitor alert rules as health signals Learn more about Signals Introducing Health Aggregation Rules Modern cloud applications are built for resiliency, redundancy, and tolerance of partial failure. Health Models are designed to reflect this reality by enabling customers to define what “healthy” means for their architecture. Flexible aggregation rules allow teams to model intent rather than individual component states, producing health views that better align with operational priorities and business impact. Health Models now supports advanced aggregation logic, enabling the following types of scenarios: Regional resiliency aggregation using numeric thresholds (e.g., 2 out of 4 regions must remain healthy) Cluster and fleet health aggregation using percentage thresholds (e.g., 60% of VMs in a cluster must be healthy) This enables modelling resiliency patterns, partial failures, and graceful degradation, providing a more accurate view of real business impact. Import Custom Signal Health is most valuable when it reflects both system behavior and application context. By enabling custom health inputs, customers can incorporate signals that are closest to their business logic and application state. Contextual annotations further enrich analysis, making health timelines easier to interpret and correlate with change events. To support this, Health Models now provides for: Custom health report ingestion for external application and system health signals Data annotations to overlay deployments, incidents, and configuration changes on health state Alert Experience To proactively learn about health state change, health models allow creating Alert rules and associated action group trigger automated responses sich as notifying user. It is now possible to view all the alerts on a Health Model and start troubleshooting. Alerts in Health Model Note: To avail these new capabilities, upgrade your health models to the new API version using built-in migration wizard in Azure portal for a simple, guided experience. Note: To avail these new capabilities, upgrade your health models to the new API version using built-in migration wizard in Azure portal for a simple, guided experience.1.2KViews0likes3CommentsShare Azure Monitor Logs to Microsoft Fabric (preview)
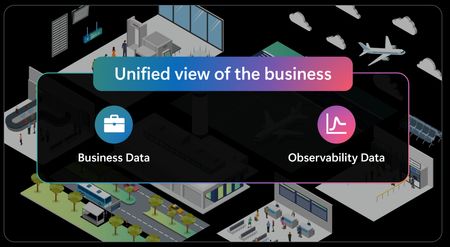
Azure Monitor Logs sharing to Microsoft Fabric is now in public preview. In just a few steps, you can share the logs you already send to a Log Analytics workspace with OneLake in Delta Parquet—the open format—without duplication, at no additional cost. This opens your observability data to all analytics, data science, and business intelligence tools available in Fabric. Today, observability, operational, and business data often live in separate silos. While Microsoft Fabric already provides a unified foundation in OneLake for business and operational data, observability data is frequently disconnected—hard to reach with the broader tools of your data estate, and disconnected from the business context needed to act. Sharing Azure Monitor data to Microsoft Fabric closes these gaps. Let's see how: Open format: your logs as Delta Parquet in OneLake In just a few steps, you can share every log you send to a Log Analytics workspace—across all tiers, including Analytics, Basic, and Auxiliary—to OneLake as Delta Parquet. Once setup completed, telemetry is available in Fabric without duplication, at no additional cost, and with near real-time availability. Because Delta Parquet is an open standard, you can read the same data with any engine that understands it—no proprietary export, no copy to maintain. Bring the full breadth of Fabric analytics to your telemetry With your logs in OneLake, you can apply the full range of Fabric analytics to your telemetry. Examples of what you can do: Build Power BI reports over long-term telemetry for trend analysis and reporting. Run Spark for large-scale processing, machine learning, and analysis across long ranges of historical telemetry. Query and correlate telemetry alongside operational and business data in one place—we'll explore this further in the next section. Going further: cross-domain intelligence The biggest shift comes when observability data is combined with business context and acted on in near real time. By bringing Azure Monitor telemetry together with business data such as ERP and CRM, organizations can reason and act across domains as events happen: Signals are evaluated with full business context, not as isolated alerts—so you can see who and what is affected, and how much it's costing. Signals turn into operational and business action—triggering the right response to mitigate the business impact of incidents before it grows. . Scenario in action: airport check-in disruption At Zava Airport, self-check-in kiosks stream telemetry into Azure Monitor. Following a deployment issue, customers are unable to complete self check-in. The Fabric Operations Agent detects the problem, enriches it with business context from ERP and CRM systems, and helps Vic, the operations manager, quickly understand that high-value loyalty customers are affected and that operational costs are rising. Based on this context, Vic approves the Operations Agent’s recommendations to open a dedicated counter to reduce customer impact and to escalate the issue to IT for faster resolution, given the high business impact. Instead of reacting after the fact, she makes decisions in the moment, based on full business context. Learn how organizations can move from operational signals to business action: So how is this powered in Fabric? Behind the scenes: how it's built in Fabric This experience runs on a simple, unified setup in Fabric: Azure Monitor data in OneLake — Telemetry from the Log Analytics workspace is brought in through a Mirrored Azure Monitor item, without duplication. Cross-domain data ready in Eventhouse — Telemetry and business data such as ERP and CRM are made available in one place, ready for real-time analysis and action. Real-time analytics and action — A Real-Time Dashboard and the Operations Agent run on this combined data, triggering automated actions across systems. Together, this creates a continuous flow from data to insight to action on a single data foundation. Learn how this solution is built in Microsoft Fabric: Key takeaways Multiple data domains, unified in OneLake — In a few steps, you can share your Azure Monitor Logs, across all tiers, to OneLake as open Delta Parquet, without duplication and at no additional cost. Full Fabric analytics — Power BI, Spark, and machine learning apply directly to your telemetry, alongside your business data. Real-time cross-domain intelligence — Observability and business data are reasoned about together in seconds, not passed sequentially between teams. Drive action, not just reports — The system detects, decides, and triggers actions based on all available context. Looking ahead... Fabric IQ and Ontology will further enrich the experience by helping organizations model business entities and relationships across domains, enabling even deeper understanding of business context. Next steps Explore how Azure Monitor data and business data come together in Microsoft Fabric to enable cross-domain intelligence, analytics, and action. We'd love to hear how this experience works for you. Drop us a comment or reach out to azmon-in-fabric@microsoft.com. Your input directly shapes what comes next.511Views2likes0CommentsJune 2026 Recap: Azure Database for PostgreSQL
POSETTE 2026 We hosted POSETTE: An Event for Postgres 2026 in June! This year marked our 5th annual event featuring 50 speakers and a total of 44 talks. PostgreSQL developers, contributors, and community members came together to share insights on topics covering everything from AI-powered applications to deep dives into PostgreSQL internals. If you missed it, you can catch up by watching the POSETTE livestream sessions. If this conference sounds interesting to you and want to be part of it next year, don’t forget to subscribe to POSETTE news. Features 💡 Chaos Studio Workspaces for Azure Database for PostgreSQL Flexible Server – Public Preview Chaos Studio Workspaces now support Azure Database for PostgreSQL Flexible Server in Public Preview. You point a Workspace at a subscription or resource group, and Chaos Studio discovers your Flexible Server instances and recommends a PostgreSQL zone-down failover Scenario. The Scenario requires a Flexible Server with High Availability enabled. Running the Scenario simulates an availability-zone outage, drives an HA failover, and produces a Scenario report of exactly what happened. Read more here: https://aka.ms/ChaosStudioPostgreSQL Try it today: https://aka.ms/chaos-portal Microsoft Defender Security Assessment for Azure Database for PostgreSQL - General Availability Microsoft Defender security posture assessments for Azure Database for PostgreSQL Flexible Server are now generally available. Built-in assessments continuously evaluate PostgreSQL configurations against PostgreSQL-specific security best practices, helping identify vulnerabilities and misconfigurations with actionable remediation guidance. Customers can use these assessments to strengthen their security baseline, prioritize remediation efforts, and support compliance requirements. Assessments are automatically available for servers already protected by Microsoft Defender for Cloud Security Posture Management (CSPM), with no additional setup required. An initial set of assessments is available today, with additional coverage planned for future releases to help strengthen the security posture of PostgreSQL workloads. Read more here: Microsoft Defender for Cloud - Azure Database for PostgreSQL | Microsoft Learn DROP CAST Support added Custom casts can be useful when applications need to convert between data types in a way that matches their business logic or migration requirements. Previously, while you could create custom casts, it wasn’t possible to drop them once they were no longer needed. With this update, you can now use the PostgreSQL DROP CAST command to clean up unused or obsolete casts, making it easier to manage schema customizations over time. Example: CREATE CAST (bigint AS text) WITH INOUT; … DROP CAST IF EXISTS (bigint AS text); Latest PostgreSQL minor versions: 18.4, 17.10, 16.14, 15.18, 14.23 Azure Database for PostgreSQL now supports the latest PostgreSQL minor versions: 18.4, 17.10, 16.14, 15.18, and 14.23. These updates are applied automatically during planned maintenance windows, helping keep your databases current with the latest PostgreSQL community fixes and reliability improvements, with no manual action required. This release includes fixes across query correctness, planner behavior, replication, backup and restore tooling, logical replication, foreign data wrapper behavior, and timezone data, improving overall stability and correctness of database operations. For details about the minor release, see the PostgreSQL announcement. Azure PostgreSQL Learning Bytes 🎓 Generate a pgBadger report from Server Logs Need a quick workload readout from PostgreSQL logs? Use pgBadger with Azure PostgreSQL Server Logs. Fast path: Server logs → Download '.log' files → Generate pgBadger report Before collecting logs, set log_line_prefix in Server parameters: %m user=%u db=%d pid=%p: Then enable Server logs > Capture logs for download, download the .log files for the time window you want to analyze, place them in a local folder, and run: FOLDER=<logs-folder-name> pgbadger -f stderr \ --prefix '%m user=%u db=%d pid=%p:' \ ./$FOLDER/*.log \ -o ./$FOLDER/pgbadger-report.html Open the generated report: start ./$FOLDER/pgbadger-report.html This gives you a quick HTML report for query activity, connection patterns, events, lock waits, and workload spikes - without setting up a storage account, BlobFuse mount, or JSON extraction pipeline. 💡Tip: Start with one or two hourly log files first. Confirm the report looks right, then expand the log analysis window. Learn more: Log Insights in Minutes: A Simpler pgBadger Workflow223Views1like0CommentsPublic Preview: Advanced platform metrics in Azure Monitor
We are excited to announce the Public Preview of advanced platform metrics for Azure Monitor, delivering more granular telemetry to help customers monitor and optimize their workloads more effectively. This new capability builds on Azure Monitor platform metrics, which continue to provide broad insight into the health, activity, and consumption of Azure resources. Advanced platform metrics add finer-grained signals, helping customers pinpoint changes and trends within resources more quickly and accurately. Azure Storage is the first Azure resource to provide advanced platform metrics to customers. Today, Azure Storage users rely on platform metrics to understand overall storage account trends, but this account-level telemetry does not always show what is driving change. For example, a storage account may show steady capacity growth without revealing which specific container is responsible. That growth could be coming from one container used for backups, another storing application logs, or a staging container used by a data pipeline. Advanced platform metrics for Azure Monitor address this scenario by providing container-level visibility, helping customers quickly identify where growth is occurring, investigate unexpected consumption increases, and make more informed cost and capacity planning decisions. What is available in Public Preview? In Public Preview, the following advanced platform metrics are available for Azure Storage across all Azure public cloud regions: Container Blob Capacity: The amount of storage used by a specific container in a storage account. Container Blob Count: The number of blob objects in a specific container in a storage account. Pricing and billing Advanced platform metrics for Azure Monitor are offered as a paid capability during Public Preview. For the latest pricing details, see Azure Monitor pricing. Getting started Advanced platform metrics can be enabled per storage account through PowerShell or Azure CLI. For instructions on enabling, managing, and viewing Azure Storage advanced platform metrics, see Azure Platform Metrics for Azure Blob Storage (preview). After advanced platform metrics are enabled for a storage account, they can be queried, visualized, and used for alerts through the same existing platform metrics experiences. Container Blob Capacity and Container Blob Count will appear in the Metric dropdown menu in Metrics Explorer, alongside all existing Azure Storage platform metrics. Users can then select Apply splitting and choose Container name to view metrics for individual containers. The chart below shows container-level capacity data for three containers. Azure Storage scenarios enabled by advanced platform metrics Standard Azure Monitor platform metrics provide visibility into the storage account as a whole, such as total blob capacity or total object count. With the addition of advanced platform metrics for Azure Storage, customers can understand which individual containers are contributing to growth, object count increases, or operational issues, enabling scenarios such as: Cost analysis and internal attribution: In shared storage accounts, identify which containers are consuming the most storage so teams can better understand which applications, environments, or business functions are driving usage without building custom reporting pipelines for this scenario. Capacity planning and growth forecasting: Track storage growth at the container level to see which workloads are driving overall account growth and make more informed planning and budgeting decisions. Runaway storage growth detection: Quickly isolate individual containers experiencing unexpected increases in capacity or object count, reducing investigation time when usage changes unexpectedly. What's next? As the feature moves toward General Availability (GA) and beyond, customers can expect to see more advanced platform metrics for Azure Storage, as well as new advanced platform metrics for other Azure resources. Continue to follow the Azure Observability Blog for the latest updates. Feedback We would love to hear your feedback on advanced platform metrics, including how your teams are using the feature to optimize workloads and additional advanced platform metrics that you would like to see onboarded to Azure Monitor. Please fill out this Azure Monitor advanced platform metrics feedback form, or email advancedplatformmetrics@microsoft.com.1.1KViews1like0CommentsAzure Monitor Observability Agent goes autonomous (preview)
Autonomous operations for the Azure Copilot Observability Agent are now in public preview, alongside the agent's general availability. With autonomous operations enabled, the Observability Agent listens to your alerts as they fire, triages them in the background, and runs deep investigations on the issues it creates. Along the way, it correlates related alerts into a single issue - so your team starts from a small set of explained, investigated issues instead of a stream of raw alerts. Until now, teams invoked the agent when they needed it - an interactive assistant, ready to investigate when you pointed it at a problem. Now it also prepares triage context continuously, on its own, while people stay responsible for decisions and any change to the environment. See autonomous operations in action. The Observability Agent triages incoming alerts, correlates related ones into a single Azure Monitor issue, and runs a deep investigation automatically, with no human trigger. From alerts to answers Azure Monitor already gives you strong signals when something is wrong - across both metric and log alerts. Dynamic thresholds learn normal behavior and flag anomalies automatically, and that same anomaly detection now extends to log search alerts and, in preview, to Prometheus and OpenTelemetry metrics. Smart detection in Application Insights surfaces failures and performance anomalies without manual rules. The hard part is what happens next: connecting dozens of alerts, working out what they share, and figuring out what's actually going on - before anyone can act. That's the work that still lands on a person, often in the middle of the night. It's exactly where the Observability Agent comes in. What's in the public preview In public preview, you can enable the Observability Agent to: Promote individual prominent alerts into issues when you configure that with custom instructions. Run a deep investigation automatically on every issue it creates. Correlate related alerts into a single Azure Monitor issue, with a natural-language explanation of why they belong together. You provision the agent once as a resource in your Azure environment - a dedicated identity to scope, govern, and assign autonomous tasks to - then turn on autonomous operations and it gets to work. What it changes for your team The outcome is fewer things to look at and faster triage: Your team works from a short queue of meaningful issues, not a constant stream of alerts. Each issue arrives with context, reasoning, and an investigation already attached. Low-priority issues can be reviewed and dismissed in seconds. The assembly work that used to come first now happens before anyone is paged. People still make every decision and every change. The agent just makes sure they start with full context. How it works Your own instructions. Topology shows how services connect, but your team knows which boundaries matter: ownership, escalation paths, and the alerts that should always become issues. Custom instructions let you capture that in plain language and apply it going forward. For example: "The billing service is owned by a different team with a separate on-call rotation. Even when billing alerts fire alongside clinical service alerts, treat them as separate issues." Instructions shape how the agent correlates and creates issues. They don't grant permissions, bypass Azure RBAC, or change resources. Automatic topology discovery. Point the agent at your Application Insights resource and it maps services, dependencies, and how they relate. That map becomes persisted knowledge the agent builds and reuses - the same context that grounds both its correlation decisions and its deep investigations, so reasoning reflects your real architecture instead of starting from scratch each time. Deeper investigations. When the agent investigates a correlated issue, it starts from the whole picture: every related alert, every impacted resource, and the reasoning correlation already produced. The result is sharper root-cause hypotheses and recommendations that account for the full scope of impact. In practice A database latency spike triggers alerts across checkout, billing, and recommendation services. Without autonomous operations, each alert is triaged on its own. With autonomous operations enabled, the Observability Agent groups the related alerts into one issue, explains the shared timeline, and starts investigating automatically. Because your custom instructions define billing as a separate ownership boundary, its alerts become a distinct issue routed to that team's rotation. Responders start from two clear, ownership-aligned issues - each already investigated - instead of dozens of isolated alerts. What's next Autonomous operations mark the next step for the Observability Agent: from user-invoked analysis to continuous preparation. The agent assembles the context, explains the issue, and runs the investigation; your team reviews the evidence and decides what to do. And once issues are created, you can act on them. Azure Monitor issues connect to Action Groups, so approved actions can flow into your existing workflows - more on that in a future post. Next steps Learn how to get started with the Azure Copilot Observability Agent. Review the preview details in Autonomous operations in the Observability Agent. Explore how investigations work in Deep investigations in the Observability Agent. Learn how teams preserve context with Azure Monitor issues. Stay connected Follow this blog for ongoing deep dives, updates on current capabilities, and a preview of what's coming next. Live webinar A walkthrough of real Observability Agent scenarios, best practices, and what's available today, along with a look at what's coming next and live Q&A with the product team. Register for the Observability Agent webinar We'd love your feedback The Observability Agent continues to evolve based on real-world usage and operator feedback. Share your thoughts directly through the Give Feedback option in the experience or reach us at azureobsagent@microsoft.com. 487Views1like0Comments