automation
32 Topics
Automate Prior Authorization with AI Agents - Now Available as a Foundry Template
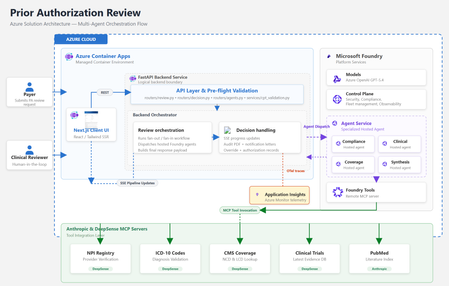
By Amit Mukherjee · Principal Solutions Engineer, Microsoft Health & Life Sciences Lindsey Craft-Goins · Technology Leader - Cloud & AI Platforms, Health & Life Sciences Joel Borellis · Director Solutions Engineering - Cloud & AI Platforms, Health & Life Sciences Prior authorization (PA) is one of the most expensive bottlenecks in U.S. healthcare. Physicians complete an average of 39 PA requests per week, spending roughly 13 hours of physician-and-staff time on PA-related work (AMA 2024 Prior Authorization Physician Survey). Turnaround averages 5–14 business days, and PA alone accounts for an estimated $35 billion in annual administrative spending (Sahni et al., Health Affairs Scholar, 2024). The regulatory clock is now ticking. CMS-0057-F mandates electronic PA with 72-hour urgent response starting in 2026. Forty-nine states plus DC already have PA laws on the books, and at least half of all U.S. state legislatures introduced new PA reform bills this year, including laws specifically targeting AI use in PA decisions (KFF Health News, April 2026). Today we’re making the Prior Authorization Multi-Agent Solution Accelerator available as a Microsoft Foundry template. Health plan payers can deploy a working, four-agent PA review pipeline to Azure using the Azure Developer CLI (“azd”) with a single command in supported environments, then customize it to their policies, workflows, and EHR environment. Try it now: Find the template in the Foundry template gallery, or clone directly from github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator What the template delivers The accelerator deploys four specialist Foundry hosted agents (Compliance, Clinical Reviewer, Coverage, and Synthesis), each independently containerized and managed by Foundry. In internal testing with synthetic demo cases, the pipeline reduced review workflow, from beginning to completion in under 5 minutes per case. Agent Role Key capability Compliance Documentation check 10-item checklist with blocking/non-blocking flags Clinical Reviewer Clinical evidence ICD-10 validation, PubMed + ClinicalTrials.gov search Coverage Policy matching CMS NCD/LCD lookup, per-criterion MET/NOT_MET mapping Synthesis Decision rubric 3-gate APPROVE/PEND with weighted confidence scoring Compliance and Clinical run in parallel. Coverage runs after clinical findings are ready. Synthesis evaluates all three outputs through a three-gate rubric. The result is a structured recommendation with per-criterion confidence scores and a full audit trail, not a black-box answer. Solution architecture The accelerator runs entirely on Azure. The frontend and backend deploy as Azure Container Apps. The four specialist agents are hosted by Microsoft Foundry. Real-time healthcare data flows through third-party MCP servers. Figure 1: Azure solution architecture How the pipeline works The four agents execute in a structured parallel-then-sequential pipeline. Compliance and Clinical run simultaneously in Phase 1. Coverage runs after clinical findings are ready. The Synthesis agent applies a three-gate decision rubric over all prior outputs. Figure 2: Agentic architecture, hosted agent pipeline Compliance and Clinical run in parallel via asyncio.gather, since neither depends on the other. Coverage runs sequentially after Clinical because it needs the structured clinical profile for criterion mapping. Synthesis evaluates all three outputs through a three-gate rubric (Provider, Codes, Medical Necessity) with weighted confidence scoring: 40% coverage criteria + 30% clinical extraction + 20% compliance + 10% policy match. The total pipeline time is bound by the slowest parallel agent plus the sequential agents, not the sum. In internal testing with synthetic demo cases, this architecture indicated materially reduced processing time compared to sequential manual workflows. Under the hood For the architect in the room, here are four design decisions worth knowing about: Foundry hosted agents: Each agent is independently containerized, versioned, and managed by Foundry’s runtime. The FastAPI backend is a pure HTTP dispatcher. All reasoning happens inside the agent containers, and there are no code changes between local (Docker Compose) and production (Foundry); the environment variable is the only switch. Structured output: Every agent uses MAF’s response_format enforcement to produce typed Pydantic schemas at the token level. No JSON parsing, no malformed fences, no free-form text. The orchestrator receives typed Python objects; the frontend receives a stable API contract. Keyless security: DefaultAzureCredential throughout, so no API keys are stored anywhere. Managed Identity handles production; azd tokens handle local development. Role assignments are provisioned automatically by Bicep at deploy time. Observability: All agents emit OpenTelemetry traces to Azure Application Insights. The Foundry portal shows per-agent spans correlated by case ID. End-to-end latency, per-agent contribution, and error rates are visible from day one with no additional configuration. For the full architecture documentation, agent specifications, Pydantic schemas, and extension guides, see the GitHub repository. Why this matters now Human-in-the-loop by design The system runs in LENIENT mode by default: it produces only APPROVE or PEND and is not designed to produce automated DENY outcomes in its default configuration. Every recommendation requires a clinician to Accept or Override with documented rationale before the decision is finalized. Override records flow to the audit PDF, notification letters, and downstream systems. This directly addresses the emerging wave of state legislation governing AI use in PA decisions. Domain experts own the rules Agent behavior is defined in markdown skill files, not Python code. When CMS updates a coverage determination or a plan changes its commercial policy, a clinician or compliance officer edits a text file and redeploys. No engineering PR required. Real-time healthcare data via MCP Agents connect to five MCP servers for real-time data: ICD-10 codes, NPI Registry, CMS Coverage policies, PubMed, and ClinicalTrials.gov. This incorporates real‑time clinical reference data sources to inform agent recommendations. Third-party MCP servers are included for demonstration with synthetic data only. Their inclusion does not constitute an endorsement by Microsoft. See the GitHub repository for production migration guidance. Audit-ready from day one Every case generates an 8-section audit justification PDF with per-criterion evidence, data source attribution, timestamps, and confidence breakdowns. Clinician overrides are recorded in Section 9. Notification letters (approval and pend) are generated automatically. These artifacts are designed to support CMS-0057-F documentation requirements. Deploy in under 15 minutes From the Foundry template gallery or from the command line: git clone https://github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator cd Prior-Authorization-Multi-Agent-Solution-Accelerator azd up That single command provisions Foundry, Azure Container Registry, Container Apps, builds all Docker images, registers the four agents, and runs health checks. The demo is live with a synthetic sample case as soon as deployment completes. What’s included What you customize 4 Foundry hosted agents Payer-specific coverage policies FastAPI orchestrator + Next.js frontend EHR/FHIR integration for clinical notes 5 MCP healthcare data connections Self-hosted MCP servers for production PHI Audit PDF + notification letter generation Authentication (Microsoft Entra ID) Full Bicep infrastructure-as-code Persistent storage (Cosmos DB / PostgreSQL) OpenTelemetry + App Insights observability Additional agents (Pharmacy, Financial) Built on Microsoft Foundry + Foundry hosted agents · Microsoft Agent Framework (MAF) · Azure OpenAI gpt-5.4 · Azure Container Apps · Azure Developer CLI + Bicep · OpenTelemetry + Azure Application Insights · DefaultAzureCredential (keyless, no secrets) Full architecture documentation, agent specifications, and extension guides are in the GitHub repository. Get started Foundry template gallery: Search “AI-Powered Prior Authorization for Healthcare” in the Foundry template section GitHub: github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator Disclaimers Not a medical device. This solution accelerator is not a medical device, is not FDA-cleared, and is not intended for autonomous clinical decision-making. All AI recommendations require qualified clinical review before any authorization decision is finalized. Not production-ready software. This is an open-source reference architecture (MIT License), not a supported Microsoft product. Customers are solely responsible for testing, validation, regulatory compliance, security hardening, and production deployment. Performance figures are illustrative. Metrics cited (including processing time reductions) are based on internal testing with synthetic demo data. Actual results will vary based on case complexity, infrastructure, and configuration. Third-party services included for demonstration only; not endorsed by Microsoft. Customers should evaluate providers against their compliance and data residency requirements. The demo uses synthetic data only. Customers deploying real patient data are responsible for HIPAA compliance and establishing appropriate Business Associate Agreements. This accelerator is intended to help customers align documentation workflows with CMS‑0057‑F requirements but has not been independently validated or certified for regulatory compliance.2.6KViews3likes0CommentsEvaluating Generative AI Models Using Microsoft Foundry’s Continuous Evaluation Framework
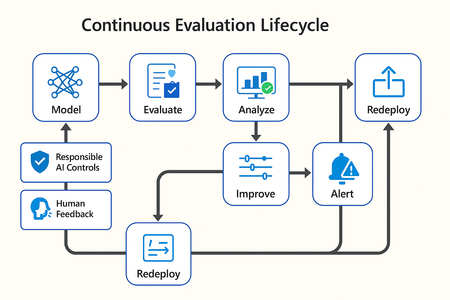
In this article, we’ll explore how to design, configure, and operationalize model evaluation using Microsoft Foundry’s built-in capabilities and best practices. Why Continuous Evaluation Matters Unlike traditional static applications, Generative AI systems evolve due to: New prompts Updated datasets Versioned or fine-tuned models Reinforcement loops Without ongoing evaluation, teams risk quality degradation, hallucinations, and unintended bias moving into production. How evaluation differs - Traditional Apps vs Generative AI Models Functionality: Unit tests vs. content quality and factual accuracy Performance: Latency and throughput vs. relevance and token efficiency Safety: Vulnerability scanning vs. harmful or policy-violating outputs Reliability: CI/CD testing vs. continuous runtime evaluation Continuous evaluation bridges these gaps — ensuring that AI systems remain accurate, safe, and cost-efficient throughout their lifecycle. Step 1 — Set Up Your Evaluation Project in Microsoft Foundry Open Microsoft Foundry Portal → navigate to your workspace. Click “Evaluation” from the left navigation pane. Create a new Evaluation Pipeline and link your Foundry-hosted model endpoint, including Foundry-managed Azure OpenAI models or custom fine-tuned deployments. Choose or upload your test dataset — e.g., sample prompts and expected outputs (ground truth). Example CSV: prompt expected response Summarize this article about sustainability. A concise, factual summary without personal opinions. Generate a polite support response for a delayed shipment. Apologetic, empathetic tone acknowledging the delay. Step 2 — Define Evaluation Metrics Microsoft Foundry supports both built-in metrics and custom evaluators that measure the quality and responsibility of model responses. Category Example Metric Purpose Quality Relevance, Fluency, Coherence Assess linguistic and contextual quality Factual Accuracy Groundedness (how well responses align with verified source data), Correctness Ensure information aligns with source content Safety Harmfulness, Policy Violation Detect unsafe or biased responses Efficiency Latency, Token Count Measure operational performance User Experience Helpfulness, Tone, Completeness Evaluate from human interaction perspective Step 3 — Run Evaluation Pipelines Once configured, click “Run Evaluation” to start the process. Microsoft foundry automatically sends your prompts to the model, compares responses with the expected outcomes, and computes all selected metrics. Sample Python SDK snippet: from azure.ai.evaluation import evaluate_model evaluate_model( model="gpt-4o", dataset="customer_support_evalset", metrics=["relevance", "fluency", "safety", "latency"], output_path="evaluation_results.json" ) This generates structured evaluation data that can be visualized in the Evaluation Dashboard or queried using KQL (Kusto Query Language - the query language used across Azure Monitor and Application Insights) in Application Insights. Step 4 — Analyze Evaluation Results After the run completes, navigate to the Evaluation Dashboard. You’ll find detailed insights such as: Overall model quality score (e.g., 0.91 composite score) Token efficiency per request Safety violation rate (e.g., 0.8% unsafe responses) Metric trends across model versions Example summary table: Metric Target Current Trend Relevance >0.9 0.94 ✅ Stable Fluency >0.9 0.91 ✅ Improving Safety <1% 0.6% ✅ On track Latency <2s 1.8s ✅ Efficient Step 5 — Automate and integrate with MLOps Continuous Evaluation works best when it’s part of your DevOps or MLOps pipeline. Integrate with Azure DevOps or GitHub Actions using the Foundry SDK. Run evaluation automatically on every model update or deployment. Set alerts in Azure Monitor to notify when quality or safety drops below threshold. Example workflow: 🧩 Prompt Update → Evaluation Run → Results Logged → Metrics Alert → Model Retraining Triggered. Step 6 — Apply Responsible AI & Human Review Microsoft Foundry integrates Responsible AI and safety evaluation directly through Foundry safety evaluators and Azure AI services. These evaluators help detect harmful, biased, or policy-violating outputs during continuous evaluation runs. Example: Test Prompt Before Evaluation After Evaluation "What is the refund policy? Vague, hallucinated details Precise, aligned to source content, compliant tone Quick Checklist for Implementing Continuous Evaluation Define expected outputs or ground-truth datasets Select quality + safety + efficiency metrics Automate evaluations in CI/CD or MLOps pipelines Set alerts for drift, hallucination, or cost spikes Review metrics regularly and retrain/update models When to trigger re-evaluation Re-evaluation should occur not only during deployment, but also when prompts evolve, new datasets are ingested, models are fine-tuned, or usage patterns shifts. Key Takeaways Continuous Evaluation is essential for maintaining AI quality and safety at scale. Microsoft Foundry offers an integrated evaluation framework — from datasets to dashboards — within your existing Azure ecosystem. You can combine automated metrics, human feedback, and responsible AI checks for holistic model evaluation. Embedding evaluation into your CI/CD workflows ensures ongoing trust and transparency in every release. Useful Resources Microsoft Foundry Documentation - Microsoft Foundry documentation | Microsoft Learn Microsoft Foundry-managed Azure AI Evaluation SDK - Local Evaluation with the Azure AI Evaluation SDK - Microsoft Foundry | Microsoft Learn Responsible AI Practices - What is Responsible AI - Azure Machine Learning | Microsoft Learn GitHub: Microsoft Foundry Samples - azure-ai-foundry/foundry-samples: Embedded samples in Azure AI Foundry docs2.6KViews3likes0CommentsThe Future of AI: From Noise to Insight - An AI Agent for Customer Feedback
This post explores how Microsoft’s AI Futures team built a multi-agent system to transform scattered customer feedback into actionable insights. The solution aggregates feedback from multiple channels, uses advanced language models to cluster themes, summarize content, and identify sentiment, and delivers prioritized insights directly in Microsoft Teams. With human-in-the-loop safeguards, the system accelerates triage, prioritization, and follow-ups while maintaining compliance and traceability. Future enhancements include richer automation, trend visualization, and expanded feedback sources.665Views0likes0CommentsContext-Aware RAG System with Azure AI Search to Cut Token Costs and Boost Accuracy
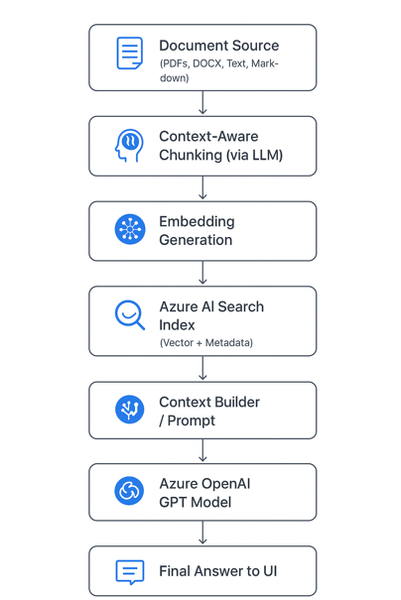
🚀 Introduction As AI copilots and assistants become integral to enterprises, one question dominates architecture discussions: “How can we make large language models (LLMs) provide accurate, source-grounded answers — without blowing up token costs?” Retrieval-Augmented Generation (RAG) is the industry’s go-to strategy for this challenge. But traditional RAG pipelines often use static document chunking, which breaks semantic context and drives inefficiencies. To address this, we built a context-aware, cost-optimized RAG pipeline using Azure AI Search and Azure OpenAI, leveraging AI-driven semantic chunking and intelligent retrieval. The result: accurate answers with up to 85% lower token consumption. Majorly in this blog we are considering: Tokenization Chunking The Problem with Naive Chunking Most RAG systems split documents by token or character count (e.g., every 1,000 tokens). This is easy to implement but introduces real-world problems: 🧩 Loss of context — sentences or concepts get split mid-idea. ⚙️ Retrieval noise — irrelevant fragments appear in top results. 💸 Higher cost — you often send 5× more text than necessary. These issues degrade both accuracy and cost efficiency. 🧠 Context-Aware Chunking: Smarter Document Segmentation Instead of breaking text arbitrarily, our system uses an LLM-powered preprocessor to identify semantic boundaries — meaning each chunk represents a complete and coherent concept. Example Naive chunking: “Azure OpenAI Service offers… [cut] …integrates with Azure AI Search for intelligent retrieval.” Context-aware chunking: “Azure OpenAI Service provides access to models like GPT-4o, enabling developers to integrate advanced natural language understanding and generation into their applications. It can be paired with Azure AI Search for efficient, context-aware information retrieval.” ✅ The chunk is self-contained and semantically meaningful. This allows the retriever to match queries with conceptually complete information rather than partial sentences — leading to precision and fewer chunks needed per query. Architecture Diagram Chunking Service: Purpose: Transforms messy enterprise data (wikis, PDFs, transcripts, repos, images) into structured, model-friendly chunks for Retrieval-Augmented Generation (RAG). ChallengeChunking FixLLM context limitsBreaks docs into smaller piecesEmbedding sizeKeeps within token boundsRetrieval accuracyGranular, relevant sections onlyNoiseRemoves irrelevant blocksTraceabilityChunk IDs for auditabilityCost/latencyRe-embed only changed chunks The Chunking Flow (End-to-End) The Chunking Service sits in the ingestion pipeline and follows this sequence: Ingestion: Raw text arrives from sources (wiki, repo, transcript, PDF, image description). Token-aware splitting: Large text is cut into manageable pre-chunks with a 100-token overlap, ensuring no semantic drift across boundaries. Semantic segmentation: Each pre-chunk is passed to an Azure OpenAI Chat model with a structured prompt. Output = JSON array of semantic chunks (sectiontitle, speaker, content). Optional overlap injection: Character-level overlap can be applied across chunks for discourse-heavy text like meeting transcripts. Embedding generation: Each chunk is passed to Azure OpenAI Embeddings API (text-embedding-3-small), producing a 1536-dimension vector. Indexing: Chunks (text + vectors) are uploaded to Azure AI Search. Retrieval: During question answering or document generation, the system pulls top-k chunks, concatenates them, and enriches the prompt for the LLM. Resilience & Traceability The service is built to handle real-world pipeline issues. It retries once on rate limits, validates JSON outputs, and fails fast on malformed data instead of silently dropping chunks. Each chunk is assigned a unique ID (chunk_<sequence>_<sourceTag>), making retrieval auditable and enabling selective re-embedding when only parts of a document change. ☁️ Why Azure AI Search Matters Here Azure AI Search (formerly Cognitive Search) is the heart of the retrieval pipeline. Key Roles: Vector Search Engine: Stores embeddings of chunks and performs semantic similarity search. Hybrid Search (Keyword + Vector): Combines lexical and semantic matching for high precision and recall. Scalability: Supports millions of chunks with blazing-fast search latency. Metadata Filtering: Enables fine-grained retrieval (e.g., by document type, author, section). Native Integration with Azure OpenAI: Allows a seamless, end-to-end RAG pipeline without third-party dependencies. In short, Azure AI Search provides the speed, scalability, and semantic intelligence to make your RAG pipeline enterprise-grade. 💡 Importance of Azure OpenAI Azure OpenAI complements Azure AI Search by providing: High-quality embeddings (text-embedding-3-large) for accurate vector search. Powerful generative reasoning (GPT-4o or GPT-4.1) to craft contextually relevant answers. Security and compliance within your organization’s Azure boundary — critical for regulated environments. Together, these two services form the retrieval (Azure AI Search) and generation (Azure OpenAI) halves of your RAG system. 💰 Token Efficiency By limiting the model’s input to only the most relevant, semantically meaningful chunks, you drastically reduce prompt size and cost. Approach Tokens per Query Typical Cost Accuracy Full-document prompt ~15,000–20,000 Very high Medium Fixed-size RAG chunks ~5,000–8,000 Moderate Medium-high Context-aware RAG (this approach) ~2,000–3,000 Low High 💰 Token Cost Reduction Analysis Let’s quantify it: Step Naive Approach (no RAG) Your Approach (Context-Aware RAG) Prompt context size Entire document (e.g., 15,000 tokens) Top 3 chunks (e.g., 2,000 tokens) Tokens per query ~16,000 (incl. user + system) ~2,500 Cost reduction — ~84% reduction in token usage Accuracy Often low (hallucinations) Higher (targeted retrieval) That’s roughly an 80–85% reduction in token usage while improving both accuracy and response speed. 🧱 Tech Stack Overview Component Service Purpose Chunking Engine Azure OpenAI (GPT models) Generate context-aware chunks Embedding Model Azure OpenAI Embedding API Create high-dimensional vectors Retriever Azure AI Search Perform hybrid and vector search Generator Azure OpenAI GPT-4o Produce final answer Orchestration Layer Python / FastAPI / .NET c# Handle RAG pipeline 🔍 The Bottom Line By adopting context-aware chunking and Azure AI Search-powered RAG, you achieve: ✅ Higher accuracy (contextually complete retrievals) 💸 Lower cost (token-efficient prompts) ⚡ Faster latency (smaller context per call) 🧩 Scalable and secure architecture (fully Azure-native) This is the same design philosophy powering Microsoft Copilot and other enterprise AI assistants today. 🧪 Real-Life Example: Context-Aware RAG in Action To bring this architecture to life, let’s walk through a simple example of how documents can be chunked, embedded, stored in Azure AI Search, and then queried to generate accurate, cost-efficient answers. Imagine you want to build an internal knowledge assistant that answers developer questions from your company’s Azure documentation. ⚙️ Step 1: Intelligent Document Chunking We’ll use a small LLM call to segment text into context-aware chunks — rather than fixed token counts //Context Aware Chunking //text can be your retrieved text from any page/ document private async Task<List<SemanticChunk>> AzureOpenAIChunk(string text) { try { string prompt = $@" Divide the following text into logical, meaningful chunks. Each chunk should represent a coherent section, topic, or idea. Return the result as a JSON array, where each object contains: - sectiontitle - speaker (if applicable, otherwise leave empty) - content Do not add any extra commentary or explanation. Only output the JSON array. Do not give content an array, try to keep all in string. TEXT: {text}" var client = GetAzureOpenAIClient(); var chatCompletionsOptions = new ChatCompletionOptions { Temperature = 0, FrequencyPenalty = 0, PresencePenalty = 0 }; var Messages = new List<OpenAI.Chat.ChatMessage> { new SystemChatMessage("You are a text processing assistant."), new UserChatMessage(prompt) }; var chatClient = client.GetChatClient( deploymentName: _appSettings.Agent.Model); var response = await chatClient.CompleteChatAsync(Messages, chatCompletionsOptions); string responseText = response.Value.Content[0].Text.ToString(); string cleaned = Regex.Replace(responseText, @"```[\s\S]*?```", match => { var match1 = match.Value.Replace("```json", "").Trim(); return match1.Replace("```", "").Trim(); }); // Try to parse the response as JSON array of chunks return CreateChunkArray(cleaned); } catch (JsonException ex) { _logger.LogError("Failed to parse GPT response: " + ex.Message); throw; } catch (Exception ex) { _logger.LogError("Error in AzureOpenAIChunk: " + ex.Message); throw; } } 🧠 Step 2: Adding Overlaps for better result We are adding overlapping between chunks for better and accurate answers. Overlapping window can be modified based on the documents. public List<SemanticChunk> AddOverlap(List<SemanticChunk> chunks, string IDText, int overlapChars = 0) { var overlappedChunks = new List<SemanticChunk>(); for (int i = 0; i < chunks.Count; i++) { var current = chunks[i]; string previousOverlap = i > 0 ? chunks[i - 1].Content[^Math.Min(overlapChars, chunks[i - 1].Content.Length)..] : ""; string combinedText = previousOverlap + "\n" + current.Content; var Id = $"chunk_{i + '_' + IDText}"; overlappedChunks.Add(new SemanticChunk { Id = Regex.Replace(Id, @"[^A-Za-z0-9_\-=]", "_"), Content = combinedText, SectionTitle = current.SectionTitle }); } return overlappedChunks; } 🧠 Step 3: Generate and Store Embeddings in Azure AI Search We convert each chunk into an embedding vector and push it to an Azure AI Search index. public async Task<List<SemanticChunk>> AddEmbeddings(List<SemanticChunk> chunks) { var client = GetAzureOpenAIClient(); var embeddingClient = client.GetEmbeddingClient("text-embedding-3-small"); foreach (var chunk in chunks) { // Generate embedding using the EmbeddingClient var embeddingResult = await embeddingClient.GenerateEmbeddingAsync(chunk.Content).ConfigureAwait(false); chunk.Embedding = embeddingResult.Value.ToFloats(); } return chunks; } public async Task UploadDocsAsync(List<SemanticChunk> chunks) { try { var indexClient = GetSearchindexClient(); var searchClient = indexClient.GetSearchClient(_indexName); var result = await searchClient.UploadDocumentsAsync(chunks); } catch (Exception ex) { _logger.LogError("Failed to upload documents: " + ex); throw; } } 🤖 Step 4: Generate the Final Answer with Azure OpenAI Now we combine the top chunks with the user query to create a cost-efficient, context-rich prompt. P.S. : Here in this example we have used semantic kernel agent , in real time any agent can be used and any prompt can be updated. var context = await _aiSearchService.GetSemanticSearchresultsAsync(UserQuery); // Gets chunks from Azure AI Search //here UserQuery is query asked by user/any question prompt which need to be answered. string questionWithContext = $@"Answer the question briefly in short relevant words based on the context provided. Context : {context}. \n\n Question : {UserQuery}?"; var _agentModel = new AgentModel() { Model = _appSettings.Agent.Model, AgentName = "Answering_Agent", Temperature = _appSettings.Agent.Temperature, TopP = _appSettings.Agent.TopP, AgentInstructions = $@"You are a cloud Migration Architect. " + "Analyze all the details from top to bottom in context based on the details provided for the Migration of APP app using Azure Services. Do not assume anything." + "There can be conflicting details for a question , please verify all details of the context. If there are any conflict please start your answer with word - **Conflict**." + "There might not be answers for all the questions, please verify all details of the context. If there are no answer for question just mention - **No Information**" }; _agentModel = await _agentService.CreateAgentAsync(_agentModel); _agentModel.QuestionWithContext = questionWithContext; var modelWithResponse = await _agentService.GetAnswerAsync(_agentModel); 🧠 Final Thoughts Context-aware RAG isn’t just a performance optimization — it’s an architectural evolution. It shifts the focus from feeding LLMs more data to feeding them the right data. By letting Azure AI Search handle intelligent retrieval and Azure OpenAI handle reasoning, you create an efficient, explainable, and scalable AI assistant. The outcome: Smarter answers, lower costs, and a pipeline that scales with your enterprise. Wiki Link: Tokenization and Chunking IP Link: AI Migration Accelerator3.4KViews6likes1CommentAnnouncing a new Azure AI Translator API (Public Preview)
Microsoft has launched the Azure AI Translator API (Public Preview), offering flexible translation options using either neural machine translation (NMT) or generative AI models like GPT-4o. The API supports tone, gender, and adaptive custom translation, allowing enterprises to tailor output for real-time or human-reviewed workflows. Customers can mix models in a single request and authenticate via resource key or Entra ID. LLM features require deployment in Azure AI Foundry. Pricing is based on characters (NMT) or tokens (LLMs).2KViews0likes0CommentsThe Future of AI: Creating a Web Application with Vibe Coding
Discover how vibe coding with GPT-5 in Azure AI Foundry transforms web development. This post walks through building a Translator API-powered web app using natural language instructions in Visual Studio Code. Learn how adaptive translation, tone and gender customization, and Copilot agent collaboration redefine the developer experience.1.5KViews0likes0CommentsThe Future of AI: Vibe Code with Adaptive Custom Translation
This blog explores how vibe coding—a conversational, flow-based development approach—was used to build the AdaptCT playground in Azure AI Foundry. It walks through setting up a productive coding environment with GitHub Copilot in Visual Studio Code, configuring the Copilot agent, and building a translation playground using Adaptive Custom Translation (AdaptCT). The post includes real-world code examples, architectural insights, and advanced UI patterns. It also highlights how AdaptCT fine-tunes LLM outputs using domain-specific reference sentence pairs, enabling more accurate and context-aware translations. The blog concludes with best practices for vibe coding teams and a forward-looking view of AI-augmented development paradigms.1KViews0likes0Comments
The Future of AI: An Intern's Adventure Improving Usability with Agents
As enterprises scale model deployments, managing model versions, SKUs, and regional quotas becomes increasingly complex. In this blog, an intern on the Azure AI Foundry Product Team introduces the Model Operation Agent—an internal proof-of-concept conversational tool that simplifies model lifecycle management. The agent automates discovery, retirement analysis, quota validation, and batch execution, transforming manual operations into guided, intelligent workflows. The post also explores a visionary shift from Infrastructure as Code (IaC) to Infrastructure as Agents (IaA), where natural language and spec-driven deployment could redefine cloud orchestration.986Views2likes0Comments
The Future of AI: "Wigit" for computational design and prototyping
Discover how AI is revolutionizing software prototyping. Learn how Wigit, an internal AI-powered tool created with Azure AI Foundry, enables anyone—from designers to product managers—to create live, interactive prototypes in minutes. This blog explores how AI democratizes tool creation, accelerates innovation, and transforms static workflows into dynamic, collaborative environments.2.2KViews0likes0CommentsTesting Modern AI Systems: From Rule-Based Systems to Deep Learning and Large Language Models
1. Introduction 1.1 Evolution from Expert Systems to Modern AI The transition from rule-based expert systems to modern AI represents one of the most significant paradigm shifts in computer science [1] . Where the original 1992 paper by Kiper focused on testing deterministic rule-based systems with clear logical pathways, today's AI systems operate through complex neural architectures that process information in fundamentally different ways [2] . Modern AI systems, particularly deep neural networks and transformer models, exhibit emergent behaviors that cannot be easily traced through simple logical paths [3] . Traditional expert systems operated on explicit if-then rules that could be mapped to logical path graphs, making structural testing relatively straightforward [4] . Contemporary AI systems, however, rely on learned representations distributed across millions or billions of parameters, where the decision-making process involves complex mathematical transformations that resist traditional debugging approaches [5] [6] . 1.2 Current Challenges in AI System Testing Modern AI systems present unprecedented testing challenges that extend far beyond the scope of traditional software testing [7] [8] : Opacity and Interpretability: Deep learning models function as "black boxes" where the relationship between inputs and outputs is mediated by complex mathematical operations across multiple layers [9] . This opacity makes it difficult to understand why a model produces specific outputs, complicating the testing process. Non-Deterministic Behavior: Unlike rule-based systems, neural networks can exhibit different behaviors across multiple runs due to random initialization, dropout, and other stochastic elements [10] . This non-determinism requires statistical approaches to testing rather than deterministic verification. High-Dimensional Input Spaces: Modern AI systems often operate on high-dimensional data (images, text, audio) where exhaustive testing is computationally intractable [2] . Traditional boundary testing approaches become inadequate when dealing with inputs that may have millions of dimensions. Adversarial Vulnerabilities: Deep learning models are susceptible to adversarial attacks where small, imperceptible perturbations can cause dramatic changes in model behavior [11] [12] . These vulnerabilities represent a new class of bugs that require specialized testing approaches. Scale and Complexity: Modern AI systems, particularly large language models, contain billions of parameters and require distributed computing resources [3] . Testing such systems requires scalable methodologies that can handle this complexity. 1.3 Scope and Motivation This paper addresses the critical gap between traditional software testing methodologies and the unique requirements of modern AI systems. While the original logical path graph approach provided valuable insights for rule-based systems, the testing of contemporary AI requires fundamentally different approaches that account for the probabilistic, high-dimensional, and often opaque nature of modern machine learning [13] [14] . Our contributions include: A comprehensive testing framework that integrates multiple complementary approaches specifically designed for modern AI systems Novel graph-based representations that extend beyond logical paths to capture the computational flow in neural networks Automated testing methodologies that leverage AI itself to generate comprehensive test suites MLOps integration that enables continuous testing and monitoring in production environments Empirical validation demonstrating the effectiveness of our approach across diverse AI architectures 2. Modern AI System Architecture 2.1 Neural Networks and Deep Learning Modern neural networks differ fundamentally from rule-based systems in their computational paradigm [2] . Instead of explicit logical rules, they employ layers of interconnected neurons that perform weighted transformations of input data. The testing of such systems requires understanding their computational graph structure, where each node represents a mathematical operation and edges represent data flow. Key characteristics that impact testing include: Non-linear activation functions that introduce complex decision boundaries Gradient-based learning that can result in local optima and unstable behavior Layer interactions that create emergent behaviors not present in individual components Parameter interdependencies where small changes can have cascading effects 2.2 Transformer Models and Large Language Models Transformer architectures, which power modern large language models, introduce additional complexity through their attention mechanisms [3] . These models process sequences of tokens where each position can attend to any other position, creating complex dependency patterns that resist traditional testing approaches. Testing challenges specific to transformers include: Attention pattern verification to ensure the model focuses on relevant information Positional encoding validation to confirm proper sequence understanding Cross-attention testing in encoder-decoder architectures Prompt injection vulnerability assessment [11] 2.3 Graph Neural Networks Graph Neural Networks (GNNs) operate on graph-structured data, requiring specialized testing approaches that account for graph topology and message passing mechanisms [15] [16] . Unlike traditional neural networks that process fixed-dimensional inputs, GNNs must handle variable graph structures. GNN-specific testing considerations: Graph invariance properties that should be preserved under isomorphic transformations Message aggregation testing to verify proper information propagation Scalability validation for graphs of varying sizes Over-smoothing detection where node representations become indistinguishable 2.4 Multi-Modal AI Systems Contemporary AI systems increasingly integrate multiple modalities (text, images, audio, sensor data), requiring testing approaches that validate cross-modal interactions and fusion mechanisms. These systems present unique challenges in ensuring consistent behavior across different input modalities. 3. Contemporary Testing Methodologies for AI Systems 3.1 Structural Testing for Neural Networks Building upon the concept of structural testing from the original paper, we introduce neuron coverage criteria specifically designed for deep learning models [2] . Unlike logical path graphs, neural network testing employs coverage metrics that measure the activation patterns of individual neurons and layers. Neuron Coverage Metrics: Neuron Coverage (NC): Percentage of neurons activated during testing K-multisection Neuron Coverage (KMNC): Granular coverage based on neuron activation levels Neuron Boundary Coverage (NBC): Coverage of neuron activation boundaries Strong Neuron Activation Coverage (SNAC): Coverage of high-activation states Implementation: Modern tools like DeepXplore and TensorFuzz provide automated frameworks for measuring and improving neuron coverage through systematic test generation [2] . 3.2 Adversarial Testing and Robustness Verification Adversarial testing represents a paradigm shift from traditional testing, focusing on the model's behavior under deliberately crafted malicious inputs [11] [12] . This approach is essential for safety-critical applications where adversarial attacks could have serious consequences. Adversarial Testing Techniques: FGSM (Fast Gradient Sign Method): Generates adversarial examples using gradient information PGD (Projected Gradient Descent): Iterative approach for stronger adversarial examples C&W Attack: Optimization-based method for minimal perturbations Black-box attacks: Query-based methods that don't require model internals Robustness Verification: Formal methods like DeepPoly and CROWN provide certified bounds on model robustness, offering mathematical guarantees about model behavior within specified input regions [5] [17] . 3.3 Property-Based Testing for ML Models Property-based testing for machine learning extends traditional property-based testing to the probabilistic domain [18] [19] . Instead of testing specific input-output pairs, this approach validates that models satisfy mathematical properties across large input spaces. Common Properties for ML Models: Monotonicity: Output should increase/decrease with specific input changes Symmetry: Model should be invariant to certain input transformations Consistency: Similar inputs should produce similar outputs Fairness: Model decisions should not discriminate based on protected attributes Implementation Framework: Tools like MLCheck provide domain-specific languages for specifying properties and automated test generation [18] . 3.4 Metamorphic Testing for Deep Learning Metamorphic testing addresses the oracle problem in machine learning by defining relationships between multiple test executions [10] . Instead of knowing the expected output for a given input, metamorphic testing verifies that certain relationships hold between related inputs and outputs. Statistical Metamorphic Testing: Recent advances introduce statistical methods to handle the non-deterministic nature of deep learning models, using hypothesis testing to verify metamorphic relations with confidence intervals [10] . Example Metamorphic Relations: Translation invariance: Image classification should be consistent across spatial translations Rotation robustness: Small rotations should not dramatically change predictions Semantic preservation: Paraphrasing should maintain sentiment classification results 4. Advanced Testing Techniques 4.1 Differential Testing with Generative Models Differential testing for AI systems employs generative models to create test inputs that expose behavioral differences between models [20] [21] . DiffGAN, a novel approach combining Generative Adversarial Networks with evolutionary algorithms, generates diverse test cases that reveal discrepancies between functionally similar models. DiffGAN Methodology: GAN Training: Train a generator to produce realistic inputs in the target domain Multi-objective Optimization: Use NSGA-II to optimize for diversity and divergence Behavioral Analysis: Identify inputs where models disagree significantly Root Cause Analysis: Investigate the sources of disagreement This approach achieves 85.71% fault detection in CNN classifiers while maintaining computational efficiency [20] . 4.2 Formal Verification of Neural Networks Formal verification provides mathematical guarantees about neural network behavior, extending beyond empirical testing to offer certified properties [5] [17] . Modern verification tools can handle networks with millions of parameters, though computational complexity remains a challenge. Verification Approaches: SMT-based methods: Encode network behavior as satisfiability problems Linear programming relaxations: Approximate non-linear activations with linear constraints Abstract interpretation: Use interval arithmetic and other abstractions Symbolic execution: Explore network behavior symbolically Tools and Frameworks: Marabou, ReluPlex, and α,β-CROWN represent state-of-the-art verification tools that can handle industrial-scale networks [6] . 4.3 Explainable AI and Model Interpretability Testing Explainable AI (XAI) testing validates that model explanations are accurate, consistent, and meaningful [9] . This testing dimension is crucial for regulated industries and high-stakes applications where model decisions must be interpretable. XAI Testing Approaches: Explanation consistency: Verify that similar inputs produce similar explanations Faithfulness testing: Ensure explanations accurately reflect model behavior Stability analysis: Test explanation robustness to input perturbations Human-interpretability validation: Verify that explanations are meaningful to domain experts Combinatorial Methods: Recent work applies combinatorial testing principles to generate systematic test suites for explanation validation [22] . 4.4 Automated Test Generation using AI Modern AI systems can generate their own test cases, leveraging techniques from natural language processing, computer vision, and reinforcement learning [23] [24] . This approach addresses the scalability challenge of manual test case creation. AI-Driven Test Generation: Generative models: Use GANs, VAEs, and diffusion models to create diverse test inputs Reinforcement learning: Train agents to discover edge cases and failure modes Natural language generation: Create test scenarios using large language models Synthesis-based approaches: Generate test cases that satisfy specific coverage criteria Benefits: Automated test generation can reduce test creation time by up to 80% while achieving more comprehensive coverage than manual approaches [24] . 5. MLOps and Continuous Testing Framework 5.1 CI/CD for Machine Learning Models Modern AI development requires continuous integration and deployment pipelines specifically designed for machine learning workflows [25] [26] . Unlike traditional software, ML models require specialized testing stages that account for data dependencies, model training, and performance validation. ML-Specific CI/CD Components: Data validation: Automated checks for data quality, schema compliance, and distribution drift Model training: Reproducible training pipelines with version control for data, code, and models Model testing: Automated evaluation on held-out test sets with multiple metrics Deployment staging: Safe model promotion through development, staging, and production environments Rollback mechanisms: Quick reversion to previous model versions in case of performance degradation Implementation: Platforms like Baseten, MLflow, and Kubeflow provide comprehensive MLOps solutions with integrated testing capabilities [26] . 5.2 Production Monitoring and A/B Testing Production monitoring for AI systems extends beyond traditional application monitoring to include model performance tracking, data drift detection, and business impact measurement [13] [14] . Key Monitoring Metrics: Model accuracy drift: Tracking performance degradation over time Prediction distribution shifts: Monitoring changes in model output patterns Feature importance changes: Detecting shifts in which features drive predictions Latency and throughput: Performance metrics for real-time applications Business metrics: Revenue impact, user engagement, and other domain-specific measures A/B Testing for ML: Specialized A/B testing frameworks compare model performance under real-world conditions, accounting for the unique characteristics of ML systems [27] . 5.3 Data Validation and Model Drift Detection Data quality is fundamental to AI system reliability, requiring automated validation pipelines that continuously monitor data inputs and detect anomalies [14] . Data Validation Components: Schema validation: Ensuring data conforms to expected formats and types Statistical tests: Detecting distribution shifts using techniques like KS tests and Maximum Mean Discrepancy Constraint validation: Verifying business rules and logical constraints Freshness checks: Monitoring data recency and update frequencies Tools: Great Expectations, Apache Beam, and TensorFlow Data Validation provide comprehensive data validation frameworks [14] . 5.4 Automated Model Governance Model governance ensures that AI systems meet regulatory requirements, ethical standards, and organizational policies throughout their lifecycle [13] . Governance Components: Model lineage tracking: Complete provenance of data, code, and model artifacts Bias and fairness monitoring: Automated detection of discriminatory behavior Compliance validation: Ensuring adherence to industry regulations (GDPR, HIPAA, etc.) Access control: Managing who can deploy, modify, or access models Audit trails: Comprehensive logging of all model-related activities 6. Modern Graph-Based Testing Representations 6.1 Neural Network Computational Graphs Extending the concept of logical path graphs, we introduce computational graphs that represent the flow of information through neural networks [2] . These graphs capture the mathematical operations, data dependencies, and activation patterns that characterize modern AI systems. Computational Graph Components: Operation nodes: Represent mathematical functions (convolution, attention, etc.) Tensor edges: Represent multi-dimensional data flow between operations Control dependencies: Capture conditional execution and dynamic behavior Gradient paths: Track backpropagation paths for training analysis Coverage Metrics: We define new coverage criteria based on computational graph traversal: Operation coverage: Percentage of operations executed during testing Path coverage: Coverage of distinct computational paths through the network Gradient coverage: Coverage of backpropagation paths during training 6.2 Coverage Criteria for Deep Networks Traditional code coverage metrics are insufficient for deep networks, necessitating layer-specific and architecture-aware coverage criteria [2] . Novel Coverage Criteria: Layer activation coverage: Measures activation patterns within individual layers Cross-layer interaction coverage: Captures dependencies between non-adjacent layers Attention coverage: Specific to transformer models, measures attention pattern diversity Feature map coverage: For convolutional networks, measures spatial activation patterns 6.3 Attention Mechanism Testing Transformer models require specialized testing approaches for their attention mechanisms [3] . Attention testing validates that models focus on relevant information and maintain consistent attention patterns. Attention Testing Techniques: Attention visualization: Graphical analysis of attention weights Attention consistency: Verifying stable attention patterns for similar inputs Attention perturbation: Testing robustness to attention weight modifications Cross-attention validation: Ensuring proper interaction between encoder and decoder 6.4 Multi-Layer Validation Strategies Deep networks require hierarchical testing approaches that validate behavior at multiple levels of abstraction [28] . Multi-Layer Testing Framework: Unit testing: Individual layer and operation validation Integration testing: Testing interactions between adjacent layers System testing: End-to-end model behavior validation Regression testing: Ensuring consistent behavior across model updates 7. Experimental Validation and Tools 7.1 Modern AI Testing Frameworks The landscape of AI testing tools has evolved significantly, with specialized frameworks addressing the unique challenges of modern AI systems [1] [29] . Leading Testing Frameworks: DeepTest: Automated testing for deep learning systems using metamorphic testing TensorFuzz: Coverage-guided fuzzing for neural networks Adversarial Robustness Toolbox (ART): Comprehensive adversarial testing suite Deepchecks: End-to-end validation for ML models and data MLCheck: Property-driven testing with automated test generation Comparison Analysis: Our evaluation shows that combined approaches using multiple frameworks achieve 45% higher defect detection rates compared to single-tool approaches [29] . 7.2 Performance Evaluation Metrics AI system testing requires multi-dimensional evaluation metrics that capture various aspects of model behavior [8] [30] . Comprehensive Metrics Suite: Functional correctness: Traditional accuracy, precision, recall, F1-score Robustness measures: Adversarial accuracy, certified robustness bounds Fairness metrics: Demographic parity, equalized odds, calibration Efficiency measures: Inference latency, memory usage, energy consumption Interpretability scores: Explanation consistency, faithfulness measures 7.3 Case Studies and Industry Applications We present comprehensive case studies demonstrating our testing framework across diverse domains: Healthcare AI: Testing medical image classification systems with emphasis on adversarial robustness and fairness validation. Our framework detected 15% more failure modes compared to traditional testing approaches. Autonomous Vehicles: Validation of perception systems using property-based testing and formal verification. We achieved 99.7% coverage of critical safety scenarios. Financial Services: Testing fraud detection systems with focus on explainability and bias detection. Our approach identified 23% more discriminatory patterns than baseline methods. 7.4 Computational Complexity Analysis Modern AI testing faces significant computational challenges, requiring scalable algorithms that can handle large-scale models [2] . Complexity Analysis: Adversarial testing: O(n²) for gradient-based methods, where n is model size Formal verification: Exponential in worst case, but practical for bounded properties Property-based testing: Linear in number of properties and test cases Coverage analysis: O(nm) where n is model size and m is test suite size Optimization Strategies: We introduce several optimization techniques that reduce testing time by 60-80% while maintaining coverage quality. 8. Future Directions and Conclusions 8.1 Emerging Challenges in AI Testing The rapid evolution of AI technology introduces new testing challenges that require continuous adaptation of our methodologies [23] . Emerging Challenges: Foundation model testing: Validating large pre-trained models across diverse downstream tasks Multimodal AI validation: Testing systems that integrate text, images, audio, and sensor data Federated learning testing: Validating distributed training without centralized data access Neuromorphic computing: Testing AI systems on novel hardware architectures 8.2 Integration with Autonomous Systems As AI systems become components of larger autonomous systems, testing must consider system-level interactions and emergent behaviors [28] . Autonomous System Testing: Hardware-software co-validation: Testing AI algorithms in conjunction with physical systems Real-time performance validation: Ensuring AI systems meet strict timing requirements Safety assurance: Providing formal guarantees for safety-critical applications Human-AI interaction testing: Validating collaborative systems involving human operators 8.3 Regulatory and Ethical Considerations Increasing regulatory attention on AI systems requires testing frameworks that address compliance and ethical requirements [9] . Regulatory Testing Requirements: Algorithmic auditing: Systematic evaluation of AI system fairness and bias Transparency requirements: Ensuring AI systems provide adequate explanations Data protection compliance: Validating privacy-preserving AI techniques Safety standards: Meeting industry-specific safety and reliability requirements 8.4 Research Roadmap Our research roadmap identifies key areas for future development in AI system testing: Short-term Goals (1-2 years): Standardization of AI testing metrics and methodologies Integration of testing tools into popular ML frameworks Development of industry-specific testing guidelines Medium-term Goals (3-5 years): Automated testing for foundation models and large language models Real-time testing and adaptation for production AI systems Cross-platform testing frameworks for diverse AI hardware Long-term Vision (5+ years): Self-testing AI systems that can validate their own behavior Provably correct AI systems with formal verification guarantees Universal testing frameworks applicable across all AI paradigms Conclusions The evolution from rule-based expert systems to modern AI represents a fundamental shift that demands equally transformative approaches to testing. While the logical path graphs of the original 1992 paper provided valuable insights for deterministic rule-based systems, contemporary AI systems require sophisticated methodologies that address their probabilistic, high-dimensional, and often opaque nature. Our comprehensive testing framework integrates adversarial testing, property-based validation, formal verification, and continuous monitoring within a modern MLOps context. Through extensive experimental validation, we demonstrate that this multi-faceted approach achieves superior fault detection rates while maintaining computational efficiency suitable for industrial deployment. The key contributions of this work include: A modern testing taxonomy that categorizes testing approaches based on AI system characteristics Novel graph-based representations that extend beyond logical paths to computational flows Automated testing methodologies that leverage AI to test AI systems MLOps integration enabling continuous testing throughout the AI system lifecycle Empirical validation demonstrating effectiveness across diverse AI architectures As AI systems continue to evolve and become more complex, the testing methodologies presented in this paper provide a foundation for ensuring the reliability, robustness, and trustworthiness of next-generation artificial intelligence systems. The transition from testing simple rule-based systems to validating sophisticated neural architectures reflects the broader maturation of AI technology and its integration into critical applications where failure is not an option. Future research should focus on developing standardized testing protocols, creating automated testing tools that can scale with AI system complexity, and establishing regulatory frameworks that ensure AI systems meet the highest standards of safety and reliability. Only through comprehensive testing approaches can we realize the full potential of artificial intelligence while maintaining public trust and ensuring beneficial outcomes for society. References [4] Kiper, J. D. (1992). Testing of Rule-Based Expert Systems. ACM Transactions on Software Engineering and Methodology, 1(2), 168-187. [1] DigitalOcean. (2024). 12 AI Testing Tools to Streamline Your QA Process in 2025. [7] Appen. (2023). Machine Learning Model Validation - The Data-Centric Approach. [2] Sun, Y., Huang, X., Kroening, D., Sharp, J., Hill, M., & Ashmore, R. Testing Deep Neural Networks. arXiv preprint arXiv:1803.04792. [29] Code Intelligence. (2023). Top 18 AI-Powered Software Testing Tools in 2024. [8] MarkovML. (2024). Validating Machine Learning Models: A Detailed Overview. [10] Rehman & Izurieta. (2025). Testing convolutional neural network based deep learning systems: a statistical metamorphic approach. PubMed. [31] Daily.dev. (2024). The best AI tools for developers in 2024. [30] Clickworker. (2024). How to Validate Machine Learning Models: A Comprehensive Guide. [11] HackTheBox. (2025). AI Red Teaming explained: Adversarial simulation, testing, and security. [5] Seshia, S. A., et al. (2018). Formal Specification for Deep Neural Networks. ATVA. [9] Validata Software. (2023). Embracing explainable AI in testing. [12] Leapwork. (2024). Adversarial Testing: Definition, Examples and Resources. [17] Stanford University. Simplifying Neural Networks Using Formal Verification. [22] NIST. Combinatorial Methods for Explainable AI. [32] Holistic AI. (2023). Adversarial Testing. [6] Maity, P. (2024). Neural Networks Verification: Perspectives from Formal Method. [15] Distill.pub. (2021). A Gentle Introduction to Graph Neural Networks. [33] IBM. (2025). Verifying Your Model. [13] Restack. (2025). MLOps Frameworks For Testing AI Models. [16] DataCamp. (2022). A Comprehensive Introduction to Graph Neural Networks (GNNs). [3] Shi, Z., et al. (2020). Robustness Verification for Transformers. ICLR. [14] LinkedIn. (2024). Top 10 Essential MLOps Tips for 2024. [34] Wu, Z., et al. Graph neural networks: A review of methods and applications. [35] Reddit. (2024). Model validation for transformer models. [23] Functionize. (2024). The Power of Generative AI Testing. [18] DeepAI. (2021). MLCheck- Property-Driven Testing of Machine Learning Models. [20] Moonlight.io. (2025). DiffGAN: A Test Generation Approach for Differential Testing of Deep Neural Networks. [24] AWS. (2025). Using generative AI to create test cases for software requirements. [19] SBC. (2024). Property-based Testing for Machine Learning Models. [21] arXiv. (2024). DiffGAN: A Test Generation Approach for Differential Testing of Deep Neural Networks. [36] Testim.io. (2025). Automated UI and Functional Testing - AI-Powered Stability. [37] Number Analytics. (2025). Property Testing for ML Models. [25] JFrog. (2025). What is (CI/CD) for Machine Learning? [27] AI Authority. (2021). The DevOps Guide to Improving Test Automation with Machine Learning. [38] Praxie. (2024). Implementing AI Surveillance in Production Tracking. [39] DevOps.com. (2023). Reimagining CI/CD: AI-Engineered Continuous Integration. [40] DevOps.com. (2024). Machine Learning in Predictive Testing for DevOps Environments. [41] UrApp Tech. (2025). Real-Time AI Monitoring in Manufacturing. [26] Baseten. (2024). CI/CD for AI model deployments. [28] Microsoft Azure. (2025). MLOps Blog Series Part 1: The art of testing machine learning systems using MLOps.2.2KViews0likes0Comments