automation
32 TopicsUse generative AI to extract structured data out of emails
One thing we regularly hear from clients is that they receive information that are key to their business such as order requests via email in an unstructured format and sometimes there are structured information within the body of those emails in a variety of table formats. In today’s fast-paced digital world, businesses need a way to automatically extract, structure, and integrate this information into their existing applications. Whether it’s leveraging AI-powered document processing, natural language processing (NLP), or intelligent automation, the right approach can transform email-based orders into structured, actionable data. In this blog, we’ll explore one such scenario where AI can be leveraged to extract information in tabular format that has been provided within an email. The emails contextually belong to a specific domain, but the tables are not with consistent headers or shapes. Sometimes in the body of one email there could be multiple tables. The problem Statement Extract tabular information with varying table formats from emails The typical approach to this problem involves rule-based processing, where individual tables are extracted and merged based on predefined logic. However, given the variety of email formats from hundreds or even thousands of different senders, maintaining such rule-based logic becomes increasingly complex and difficult to manage. A more optimal solution is leveraging the cognitive capabilities of generative AI, which can dynamically adapt to different table structures, column names, and formatting variations—eliminating the need for constant rule updates while improving accuracy and scalability. To create this sample code, I used below email with test data, with two tables with inconsistent column names. It is going to provide some upcoming trainings information. Please note the difference between the column headers: Hi there, Regarding the upcoming trainings, this is the list: Event Date Description of Event Length Grade 2025-01-21 Digital environments 20 hours 5 2025-03-01 AI for Industry A 10 hours 3 and some further events in below list Date Subject Duration Grade 2025-01-21 Digital environments 2 2 days 1 2025-03-01 AI for Industry B 2 weeks 4 These sessions are designed to be interactive and informative, so your timely participation is crucial. Please make sure to log in or arrive on time to avoid missing key insights. If you have any questions or need assistance, feel free to reach out. Looking forward to seeing you there! Thanks, Azadeh These are the two tables within the email, and we need to extract one consistent table format with all the rows from these two tables. Table 1 Event Date Description of Event Length Grade 2025-01-21 Digital environments 20 hours 5 2025-03-01 AI for Industry A 10 hours 3 Table 2 Date Subject Duration Grade 2025-01-21 Digital environments 2 2 days 1 2025-03-01 AI for Industry B 2 weeks 4 To extract the tabular data into one single table in json format, I am using python with below libraries installed in my environment: pandas beautifulsoup4 openai lxml The Code I use azure OpenAI service with a gpt 4o deployment. Below code is just one way of solving this type of problem and can be customized or improved to fit to other similar problems. I have provided some guidelines about merging the tables and column names similarity in the user prompt. This sample code is using an email message that is saved in 'eml' format in a local path, but the email library has other capabilities to help you connect to a mailbox and get the emails. import email import pandas as pd from bs4 import BeautifulSoup import os from openai import AzureOpenAI endpoint = os.getenv("ENDPOINT_URL", "https://....myendpointurl....openai.azure.com/") deployment = os.getenv("DEPLOYMENT_NAME", "gpt-4o") subscription_key = os.getenv("AZURE_OPENAI_API_KEY", "myapikey) # Initialize Azure OpenAI Service client with key-based authentication client = AzureOpenAI( azure_endpoint=endpoint, api_key=subscription_key, api_version="2024-05-01-preview", ) # Process email content with GPT-4 def extract_information(email_body, client): soup = BeautifulSoup(email_body, "html.parser") body = soup.get_text() print(body) #Prepare the chat prompt chat_prompt = [ { "role": "system", "content": [ { "type": "text", "text": "You are an AI assistant that is expert in extracting structured data from emails." } ] }, { "role": "user", "content": [ { "type": "text", "text": f"Extract the required information from the following email and format it as JSON and consolidate the tables using the common column names. For example the columns length and duration are the same and the columns Event and Subject are the same:\n\n{body}" } ] } ] messages = chat_prompt # Generate the completion completion = client.chat.completions.create( model=deployment, messages=messages, max_tokens=800, temperature=0.1, top_p=0.95, frequency_penalty=0, presence_penalty=0, stop=None, stream=False ) return completion.choices[0].message.content email_file_name = r'...path to your file....\Test Email with Tables.eml' with open(email_file_name, "r") as f: msg = email.message_from_file(f) email_body = "" for part in msg.walk(): if part.get_content_type() == "text/plain": email_body = part.get_payload(decode=True).decode() elif part.get_content_type() == "text/html": email_body = part.get_payload(decode=True).decode() extracted_info = extract_information(email_body, client) print(extracted_info) The output is: ``` [ { "Event": "Digital environments", "Date": "2025-01-21", "Length": "20 hours", "Grade": 5 }, { "Event": "AI for Industry A", "Date": "2025-03-01", "Length": "10 hours", "Grade": 3 }, { "Event": "Digital environments 2", "Date": "2025-01-21", "Length": "2 days", "Grade": 1 }, { "Event": "AI for Industry B", "Date": "2025-03-01", "Length": "2 weeks", "Grade": 4 } ] ``` Key points in the code: Read an email and extract the body Use a gen AI model with the right instructions prompt to complete the task Gen AI will follow the instructions and create a combined consistent table Get the output in the right format, e.g. 'json' I hope you find this blog post helpful, and you can apply it to your use case/domain. Or you can simply get the idea of how to use generative AI to solve a problem, instead of building layers of custom logic.4.8KViews7likes1CommentContext-Aware RAG System with Azure AI Search to Cut Token Costs and Boost Accuracy
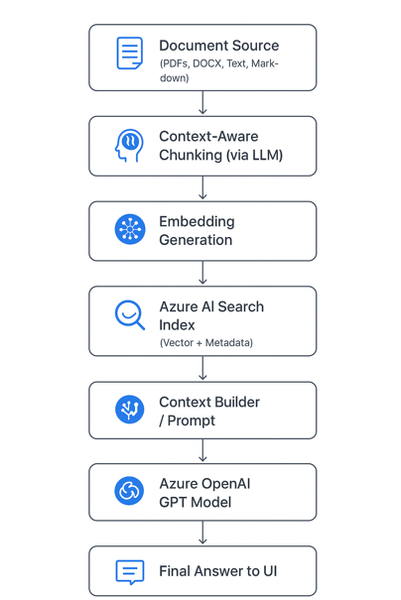
🚀 Introduction As AI copilots and assistants become integral to enterprises, one question dominates architecture discussions: “How can we make large language models (LLMs) provide accurate, source-grounded answers — without blowing up token costs?” Retrieval-Augmented Generation (RAG) is the industry’s go-to strategy for this challenge. But traditional RAG pipelines often use static document chunking, which breaks semantic context and drives inefficiencies. To address this, we built a context-aware, cost-optimized RAG pipeline using Azure AI Search and Azure OpenAI, leveraging AI-driven semantic chunking and intelligent retrieval. The result: accurate answers with up to 85% lower token consumption. Majorly in this blog we are considering: Tokenization Chunking The Problem with Naive Chunking Most RAG systems split documents by token or character count (e.g., every 1,000 tokens). This is easy to implement but introduces real-world problems: 🧩 Loss of context — sentences or concepts get split mid-idea. ⚙️ Retrieval noise — irrelevant fragments appear in top results. 💸 Higher cost — you often send 5× more text than necessary. These issues degrade both accuracy and cost efficiency. 🧠 Context-Aware Chunking: Smarter Document Segmentation Instead of breaking text arbitrarily, our system uses an LLM-powered preprocessor to identify semantic boundaries — meaning each chunk represents a complete and coherent concept. Example Naive chunking: “Azure OpenAI Service offers… [cut] …integrates with Azure AI Search for intelligent retrieval.” Context-aware chunking: “Azure OpenAI Service provides access to models like GPT-4o, enabling developers to integrate advanced natural language understanding and generation into their applications. It can be paired with Azure AI Search for efficient, context-aware information retrieval.” ✅ The chunk is self-contained and semantically meaningful. This allows the retriever to match queries with conceptually complete information rather than partial sentences — leading to precision and fewer chunks needed per query. Architecture Diagram Chunking Service: Purpose: Transforms messy enterprise data (wikis, PDFs, transcripts, repos, images) into structured, model-friendly chunks for Retrieval-Augmented Generation (RAG). ChallengeChunking FixLLM context limitsBreaks docs into smaller piecesEmbedding sizeKeeps within token boundsRetrieval accuracyGranular, relevant sections onlyNoiseRemoves irrelevant blocksTraceabilityChunk IDs for auditabilityCost/latencyRe-embed only changed chunks The Chunking Flow (End-to-End) The Chunking Service sits in the ingestion pipeline and follows this sequence: Ingestion: Raw text arrives from sources (wiki, repo, transcript, PDF, image description). Token-aware splitting: Large text is cut into manageable pre-chunks with a 100-token overlap, ensuring no semantic drift across boundaries. Semantic segmentation: Each pre-chunk is passed to an Azure OpenAI Chat model with a structured prompt. Output = JSON array of semantic chunks (sectiontitle, speaker, content). Optional overlap injection: Character-level overlap can be applied across chunks for discourse-heavy text like meeting transcripts. Embedding generation: Each chunk is passed to Azure OpenAI Embeddings API (text-embedding-3-small), producing a 1536-dimension vector. Indexing: Chunks (text + vectors) are uploaded to Azure AI Search. Retrieval: During question answering or document generation, the system pulls top-k chunks, concatenates them, and enriches the prompt for the LLM. Resilience & Traceability The service is built to handle real-world pipeline issues. It retries once on rate limits, validates JSON outputs, and fails fast on malformed data instead of silently dropping chunks. Each chunk is assigned a unique ID (chunk_<sequence>_<sourceTag>), making retrieval auditable and enabling selective re-embedding when only parts of a document change. ☁️ Why Azure AI Search Matters Here Azure AI Search (formerly Cognitive Search) is the heart of the retrieval pipeline. Key Roles: Vector Search Engine: Stores embeddings of chunks and performs semantic similarity search. Hybrid Search (Keyword + Vector): Combines lexical and semantic matching for high precision and recall. Scalability: Supports millions of chunks with blazing-fast search latency. Metadata Filtering: Enables fine-grained retrieval (e.g., by document type, author, section). Native Integration with Azure OpenAI: Allows a seamless, end-to-end RAG pipeline without third-party dependencies. In short, Azure AI Search provides the speed, scalability, and semantic intelligence to make your RAG pipeline enterprise-grade. 💡 Importance of Azure OpenAI Azure OpenAI complements Azure AI Search by providing: High-quality embeddings (text-embedding-3-large) for accurate vector search. Powerful generative reasoning (GPT-4o or GPT-4.1) to craft contextually relevant answers. Security and compliance within your organization’s Azure boundary — critical for regulated environments. Together, these two services form the retrieval (Azure AI Search) and generation (Azure OpenAI) halves of your RAG system. 💰 Token Efficiency By limiting the model’s input to only the most relevant, semantically meaningful chunks, you drastically reduce prompt size and cost. Approach Tokens per Query Typical Cost Accuracy Full-document prompt ~15,000–20,000 Very high Medium Fixed-size RAG chunks ~5,000–8,000 Moderate Medium-high Context-aware RAG (this approach) ~2,000–3,000 Low High 💰 Token Cost Reduction Analysis Let’s quantify it: Step Naive Approach (no RAG) Your Approach (Context-Aware RAG) Prompt context size Entire document (e.g., 15,000 tokens) Top 3 chunks (e.g., 2,000 tokens) Tokens per query ~16,000 (incl. user + system) ~2,500 Cost reduction — ~84% reduction in token usage Accuracy Often low (hallucinations) Higher (targeted retrieval) That’s roughly an 80–85% reduction in token usage while improving both accuracy and response speed. 🧱 Tech Stack Overview Component Service Purpose Chunking Engine Azure OpenAI (GPT models) Generate context-aware chunks Embedding Model Azure OpenAI Embedding API Create high-dimensional vectors Retriever Azure AI Search Perform hybrid and vector search Generator Azure OpenAI GPT-4o Produce final answer Orchestration Layer Python / FastAPI / .NET c# Handle RAG pipeline 🔍 The Bottom Line By adopting context-aware chunking and Azure AI Search-powered RAG, you achieve: ✅ Higher accuracy (contextually complete retrievals) 💸 Lower cost (token-efficient prompts) ⚡ Faster latency (smaller context per call) 🧩 Scalable and secure architecture (fully Azure-native) This is the same design philosophy powering Microsoft Copilot and other enterprise AI assistants today. 🧪 Real-Life Example: Context-Aware RAG in Action To bring this architecture to life, let’s walk through a simple example of how documents can be chunked, embedded, stored in Azure AI Search, and then queried to generate accurate, cost-efficient answers. Imagine you want to build an internal knowledge assistant that answers developer questions from your company’s Azure documentation. ⚙️ Step 1: Intelligent Document Chunking We’ll use a small LLM call to segment text into context-aware chunks — rather than fixed token counts //Context Aware Chunking //text can be your retrieved text from any page/ document private async Task<List<SemanticChunk>> AzureOpenAIChunk(string text) { try { string prompt = $@" Divide the following text into logical, meaningful chunks. Each chunk should represent a coherent section, topic, or idea. Return the result as a JSON array, where each object contains: - sectiontitle - speaker (if applicable, otherwise leave empty) - content Do not add any extra commentary or explanation. Only output the JSON array. Do not give content an array, try to keep all in string. TEXT: {text}" var client = GetAzureOpenAIClient(); var chatCompletionsOptions = new ChatCompletionOptions { Temperature = 0, FrequencyPenalty = 0, PresencePenalty = 0 }; var Messages = new List<OpenAI.Chat.ChatMessage> { new SystemChatMessage("You are a text processing assistant."), new UserChatMessage(prompt) }; var chatClient = client.GetChatClient( deploymentName: _appSettings.Agent.Model); var response = await chatClient.CompleteChatAsync(Messages, chatCompletionsOptions); string responseText = response.Value.Content[0].Text.ToString(); string cleaned = Regex.Replace(responseText, @"```[\s\S]*?```", match => { var match1 = match.Value.Replace("```json", "").Trim(); return match1.Replace("```", "").Trim(); }); // Try to parse the response as JSON array of chunks return CreateChunkArray(cleaned); } catch (JsonException ex) { _logger.LogError("Failed to parse GPT response: " + ex.Message); throw; } catch (Exception ex) { _logger.LogError("Error in AzureOpenAIChunk: " + ex.Message); throw; } } 🧠 Step 2: Adding Overlaps for better result We are adding overlapping between chunks for better and accurate answers. Overlapping window can be modified based on the documents. public List<SemanticChunk> AddOverlap(List<SemanticChunk> chunks, string IDText, int overlapChars = 0) { var overlappedChunks = new List<SemanticChunk>(); for (int i = 0; i < chunks.Count; i++) { var current = chunks[i]; string previousOverlap = i > 0 ? chunks[i - 1].Content[^Math.Min(overlapChars, chunks[i - 1].Content.Length)..] : ""; string combinedText = previousOverlap + "\n" + current.Content; var Id = $"chunk_{i + '_' + IDText}"; overlappedChunks.Add(new SemanticChunk { Id = Regex.Replace(Id, @"[^A-Za-z0-9_\-=]", "_"), Content = combinedText, SectionTitle = current.SectionTitle }); } return overlappedChunks; } 🧠 Step 3: Generate and Store Embeddings in Azure AI Search We convert each chunk into an embedding vector and push it to an Azure AI Search index. public async Task<List<SemanticChunk>> AddEmbeddings(List<SemanticChunk> chunks) { var client = GetAzureOpenAIClient(); var embeddingClient = client.GetEmbeddingClient("text-embedding-3-small"); foreach (var chunk in chunks) { // Generate embedding using the EmbeddingClient var embeddingResult = await embeddingClient.GenerateEmbeddingAsync(chunk.Content).ConfigureAwait(false); chunk.Embedding = embeddingResult.Value.ToFloats(); } return chunks; } public async Task UploadDocsAsync(List<SemanticChunk> chunks) { try { var indexClient = GetSearchindexClient(); var searchClient = indexClient.GetSearchClient(_indexName); var result = await searchClient.UploadDocumentsAsync(chunks); } catch (Exception ex) { _logger.LogError("Failed to upload documents: " + ex); throw; } } 🤖 Step 4: Generate the Final Answer with Azure OpenAI Now we combine the top chunks with the user query to create a cost-efficient, context-rich prompt. P.S. : Here in this example we have used semantic kernel agent , in real time any agent can be used and any prompt can be updated. var context = await _aiSearchService.GetSemanticSearchresultsAsync(UserQuery); // Gets chunks from Azure AI Search //here UserQuery is query asked by user/any question prompt which need to be answered. string questionWithContext = $@"Answer the question briefly in short relevant words based on the context provided. Context : {context}. \n\n Question : {UserQuery}?"; var _agentModel = new AgentModel() { Model = _appSettings.Agent.Model, AgentName = "Answering_Agent", Temperature = _appSettings.Agent.Temperature, TopP = _appSettings.Agent.TopP, AgentInstructions = $@"You are a cloud Migration Architect. " + "Analyze all the details from top to bottom in context based on the details provided for the Migration of APP app using Azure Services. Do not assume anything." + "There can be conflicting details for a question , please verify all details of the context. If there are any conflict please start your answer with word - **Conflict**." + "There might not be answers for all the questions, please verify all details of the context. If there are no answer for question just mention - **No Information**" }; _agentModel = await _agentService.CreateAgentAsync(_agentModel); _agentModel.QuestionWithContext = questionWithContext; var modelWithResponse = await _agentService.GetAnswerAsync(_agentModel); 🧠 Final Thoughts Context-aware RAG isn’t just a performance optimization — it’s an architectural evolution. It shifts the focus from feeding LLMs more data to feeding them the right data. By letting Azure AI Search handle intelligent retrieval and Azure OpenAI handle reasoning, you create an efficient, explainable, and scalable AI assistant. The outcome: Smarter answers, lower costs, and a pipeline that scales with your enterprise. Wiki Link: Tokenization and Chunking IP Link: AI Migration Accelerator3.4KViews6likes1CommentThe Future of AI: Computer Use Agents Have Arrived
Discover the groundbreaking advancements in AI with Computer Use Agents (CUAs). In this blog, Marco Casalaina shares how to use the Responses API from Azure OpenAI Service, showcasing how CUAs can launch apps, navigate websites, and reason through tasks. Learn how CUAs utilize multimodal models for computer vision and AI frameworks to enhance automation. Explore the differences between CUAs and traditional Robotic Process Automation (RPA), and understand how CUAs can complement RPA systems. Dive into the future of automation and see how CUAs are set to revolutionize the way we interact with technology.15KViews6likes0CommentsAzure Open AI (GPT) with Power Apps - Build a Power App to create Demo or Personal Knowledge Bot
Let's build a power app with open ai to create a personal knowledge assistant and or also to show demo. App allows users to increase productivity by gaining knowledge by asking questions and other features like Summarization, Code generation, Email Content, Blob post content, twitter content.28KViews6likes4CommentsPredict steel quality with Azure AutoML in manufacturing
This post will guide you through how we, Lotta Åhag and Gustav Kruse, used Azure AutoML and the 'Enterprise Scale ML (ESML) solution accelerator for Azure', to build an end-2-end machine learning solution in 6 weeks. The value of the solution is estimated to reduce 3.35 tons of Co2 emissions of propane and decrease electricity usage of 90MWh per year after putting the solution into production. The ecological impact is much higher less quality rejections will save a lot of resources including coal (and gas) needed to produce the steel. We collaborated with the Epiroc Data Scientist, Erik Rosendahl, who worked with the ESML templates for operation and governance. This is the story we want to share, about an end-2-end, machine learning solution on Azure. We wanted to leverage AI for steel manufacturing, in the area of heat treatment quality, with the goal to enhance the process to be able to reduce CO2. We got help from 2 student data scientists who wanted to execute this as their master thesis. In 6 weeks, they managed to leverage Azure Machine Learning and the ESML AI factory at Epiroc, using AutoML to build a machine learning model w an end-2-end pipeline from datalake to Power BI report. The team quickly got its own set of Azure resources as an ESML Project which ensured both enterprise grade scale and security – and out came a new AI innovation, with ecological wins - 3.35 ton C02 reduction and 30% less quality rejections. //Jonas Jern, Head of Digital Innovation, Epiroc Drilling Tools AB8.1KViews4likes0Comments
Automate Prior Authorization with AI Agents - Now Available as a Foundry Template
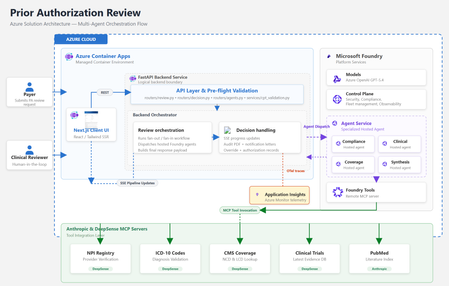
By Amit Mukherjee · Principal Solutions Engineer, Microsoft Health & Life Sciences Lindsey Craft-Goins · Technology Leader - Cloud & AI Platforms, Health & Life Sciences Joel Borellis · Director Solutions Engineering - Cloud & AI Platforms, Health & Life Sciences Prior authorization (PA) is one of the most expensive bottlenecks in U.S. healthcare. Physicians complete an average of 39 PA requests per week, spending roughly 13 hours of physician-and-staff time on PA-related work (AMA 2024 Prior Authorization Physician Survey). Turnaround averages 5–14 business days, and PA alone accounts for an estimated $35 billion in annual administrative spending (Sahni et al., Health Affairs Scholar, 2024). The regulatory clock is now ticking. CMS-0057-F mandates electronic PA with 72-hour urgent response starting in 2026. Forty-nine states plus DC already have PA laws on the books, and at least half of all U.S. state legislatures introduced new PA reform bills this year, including laws specifically targeting AI use in PA decisions (KFF Health News, April 2026). Today we’re making the Prior Authorization Multi-Agent Solution Accelerator available as a Microsoft Foundry template. Health plan payers can deploy a working, four-agent PA review pipeline to Azure using the Azure Developer CLI (“azd”) with a single command in supported environments, then customize it to their policies, workflows, and EHR environment. Try it now: Find the template in the Foundry template gallery, or clone directly from github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator What the template delivers The accelerator deploys four specialist Foundry hosted agents (Compliance, Clinical Reviewer, Coverage, and Synthesis), each independently containerized and managed by Foundry. In internal testing with synthetic demo cases, the pipeline reduced review workflow, from beginning to completion in under 5 minutes per case. Agent Role Key capability Compliance Documentation check 10-item checklist with blocking/non-blocking flags Clinical Reviewer Clinical evidence ICD-10 validation, PubMed + ClinicalTrials.gov search Coverage Policy matching CMS NCD/LCD lookup, per-criterion MET/NOT_MET mapping Synthesis Decision rubric 3-gate APPROVE/PEND with weighted confidence scoring Compliance and Clinical run in parallel. Coverage runs after clinical findings are ready. Synthesis evaluates all three outputs through a three-gate rubric. The result is a structured recommendation with per-criterion confidence scores and a full audit trail, not a black-box answer. Solution architecture The accelerator runs entirely on Azure. The frontend and backend deploy as Azure Container Apps. The four specialist agents are hosted by Microsoft Foundry. Real-time healthcare data flows through third-party MCP servers. Figure 1: Azure solution architecture How the pipeline works The four agents execute in a structured parallel-then-sequential pipeline. Compliance and Clinical run simultaneously in Phase 1. Coverage runs after clinical findings are ready. The Synthesis agent applies a three-gate decision rubric over all prior outputs. Figure 2: Agentic architecture, hosted agent pipeline Compliance and Clinical run in parallel via asyncio.gather, since neither depends on the other. Coverage runs sequentially after Clinical because it needs the structured clinical profile for criterion mapping. Synthesis evaluates all three outputs through a three-gate rubric (Provider, Codes, Medical Necessity) with weighted confidence scoring: 40% coverage criteria + 30% clinical extraction + 20% compliance + 10% policy match. The total pipeline time is bound by the slowest parallel agent plus the sequential agents, not the sum. In internal testing with synthetic demo cases, this architecture indicated materially reduced processing time compared to sequential manual workflows. Under the hood For the architect in the room, here are four design decisions worth knowing about: Foundry hosted agents: Each agent is independently containerized, versioned, and managed by Foundry’s runtime. The FastAPI backend is a pure HTTP dispatcher. All reasoning happens inside the agent containers, and there are no code changes between local (Docker Compose) and production (Foundry); the environment variable is the only switch. Structured output: Every agent uses MAF’s response_format enforcement to produce typed Pydantic schemas at the token level. No JSON parsing, no malformed fences, no free-form text. The orchestrator receives typed Python objects; the frontend receives a stable API contract. Keyless security: DefaultAzureCredential throughout, so no API keys are stored anywhere. Managed Identity handles production; azd tokens handle local development. Role assignments are provisioned automatically by Bicep at deploy time. Observability: All agents emit OpenTelemetry traces to Azure Application Insights. The Foundry portal shows per-agent spans correlated by case ID. End-to-end latency, per-agent contribution, and error rates are visible from day one with no additional configuration. For the full architecture documentation, agent specifications, Pydantic schemas, and extension guides, see the GitHub repository. Why this matters now Human-in-the-loop by design The system runs in LENIENT mode by default: it produces only APPROVE or PEND and is not designed to produce automated DENY outcomes in its default configuration. Every recommendation requires a clinician to Accept or Override with documented rationale before the decision is finalized. Override records flow to the audit PDF, notification letters, and downstream systems. This directly addresses the emerging wave of state legislation governing AI use in PA decisions. Domain experts own the rules Agent behavior is defined in markdown skill files, not Python code. When CMS updates a coverage determination or a plan changes its commercial policy, a clinician or compliance officer edits a text file and redeploys. No engineering PR required. Real-time healthcare data via MCP Agents connect to five MCP servers for real-time data: ICD-10 codes, NPI Registry, CMS Coverage policies, PubMed, and ClinicalTrials.gov. This incorporates real‑time clinical reference data sources to inform agent recommendations. Third-party MCP servers are included for demonstration with synthetic data only. Their inclusion does not constitute an endorsement by Microsoft. See the GitHub repository for production migration guidance. Audit-ready from day one Every case generates an 8-section audit justification PDF with per-criterion evidence, data source attribution, timestamps, and confidence breakdowns. Clinician overrides are recorded in Section 9. Notification letters (approval and pend) are generated automatically. These artifacts are designed to support CMS-0057-F documentation requirements. Deploy in under 15 minutes From the Foundry template gallery or from the command line: git clone https://github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator cd Prior-Authorization-Multi-Agent-Solution-Accelerator azd up That single command provisions Foundry, Azure Container Registry, Container Apps, builds all Docker images, registers the four agents, and runs health checks. The demo is live with a synthetic sample case as soon as deployment completes. What’s included What you customize 4 Foundry hosted agents Payer-specific coverage policies FastAPI orchestrator + Next.js frontend EHR/FHIR integration for clinical notes 5 MCP healthcare data connections Self-hosted MCP servers for production PHI Audit PDF + notification letter generation Authentication (Microsoft Entra ID) Full Bicep infrastructure-as-code Persistent storage (Cosmos DB / PostgreSQL) OpenTelemetry + App Insights observability Additional agents (Pharmacy, Financial) Built on Microsoft Foundry + Foundry hosted agents · Microsoft Agent Framework (MAF) · Azure OpenAI gpt-5.4 · Azure Container Apps · Azure Developer CLI + Bicep · OpenTelemetry + Azure Application Insights · DefaultAzureCredential (keyless, no secrets) Full architecture documentation, agent specifications, and extension guides are in the GitHub repository. Get started Foundry template gallery: Search “AI-Powered Prior Authorization for Healthcare” in the Foundry template section GitHub: github.com/microsoft/Prior-Authorization-Multi-Agent-Solution-Accelerator Disclaimers Not a medical device. This solution accelerator is not a medical device, is not FDA-cleared, and is not intended for autonomous clinical decision-making. All AI recommendations require qualified clinical review before any authorization decision is finalized. Not production-ready software. This is an open-source reference architecture (MIT License), not a supported Microsoft product. Customers are solely responsible for testing, validation, regulatory compliance, security hardening, and production deployment. Performance figures are illustrative. Metrics cited (including processing time reductions) are based on internal testing with synthetic demo data. Actual results will vary based on case complexity, infrastructure, and configuration. Third-party services included for demonstration only; not endorsed by Microsoft. Customers should evaluate providers against their compliance and data residency requirements. The demo uses synthetic data only. Customers deploying real patient data are responsible for HIPAA compliance and establishing appropriate Business Associate Agreements. This accelerator is intended to help customers align documentation workflows with CMS‑0057‑F requirements but has not been independently validated or certified for regulatory compliance.2.6KViews3likes0Comments