ai
595 TopicsClosing the AI Agent Governance Gap with Microsoft Foundry
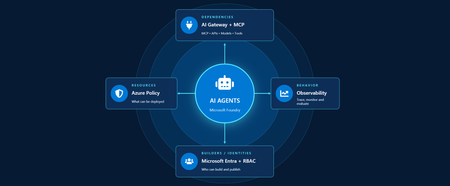
Developers are shipping agents faster than security teams can catalog them. As organizations move beyond pilots and begin operating dozens or hundreds of agents, one question keeps coming up: how do we actually get visibility into our AI agents across our environment? In this article, we'll walk through how Azure services can help establish visibility, guardrails, and cost accountability across your AI estate. Governance for AI happens across four layers: Resources – who can create new AI resources Builders – who can develop and publish agents in a certain scope Behavior – how agent outputs are evaluated, monitored, and governed Dependencies – what models, tools, APIs, and MCP servers agents can interact with Most organizations already have governance controls for identities, networking, and compliance. The challenge isn't creating new controls. It's connecting existing controls into an operating model that works for AI agents. Below we walk through each area and go a bit deeper on how to close the gap. Setting up boundaries with Azure Policy First, let's start in the Azure portal with Azure Policy. Azure Policy lets you set guardrails on what can be deployed in your environment and flags or blocks anything that doesn't comply. For AI workloads, the built-in definitions range from limiting models that people in your organization can deploy to locking down the network through enabling private endpoints. Some policies you get started with: Foundry model deployments should only use approved models: Restricts deployments to models or publishers your organization has explicitly approved Foundry model deployments should meet eligibility requirements (preview): Applies rules based on model attributes like preview vs. GA status and distribution source Azure AI Services resources should have key access disabled: Makes Microsoft Entra ID the only entry point The full list of policies related to Azure AI Services are available here: List of built-in policy definitions - Azure Policy | Microsoft Learn Why this comes first: Policy checks resources before they are created, so it proactively keeps your environment aligned with your standards. Implementing role-based access control (RBAC) Once these boundaries are in place, the next step is RBAC. Setting RBAC up early ensures that people and identities building agents have the right scope for what they actually need to do. Foundry roles only apply when you authenticate using Microsoft Entra ID. If you're using key-based authentication instead, the key grants full access with without role restrictions. API keys are convenient for quick development usage but when moving towards production, Microsoft Entra ID is the preferred method. Roles can be assigned at three scopes: the Foundry resource, a Foundry project, or an individual agent itself. Below is an example of how different personas within organization can map to a certain scope for creating and building agents with Foundry. Here's how each role in the diagram compares, from least to most privileged: Role Privilege Level What it does in Microsoft Foundry Foundry Agent Consumer Least Interact with agent endpoints in a project. This is your least-privilege role for people who only need to use agents. Foundry User Low Grants reader access to the Foundry project, the Foundry resource, and data actions for your Foundry project. Least-privilege access role for developers building and testing agents. Foundry Project Manager Medium This role lets you perform management actions on Foundry projects, build and develop with projects, and conditionally assign the Foundry User role to other user principals. Foundry Account Owner Higher Grants full access to manage Foundry projects and resources, and lets you assign the Foundry User role to other user principals. Foundry Owner Highest Grants full access to manage Foundry projects and resources to build and develop with projects. This role can also assign the Foundry User, ACR, and monitoring roles to users in the environment. Source: Role-based access control for Microsoft Foundry - Microsoft Foundry | Microsoft Learn For the agent resources themselves, assign managed identities rather than API keys since it lowers the risk of having compromised credentials. Note if you're scripting RBAC permissions: these roles were recently renamed from Azure AI User, Azure AI Owner, Azure AI Account Owner, and Azure AI Project Manager. The role IDs and permissions didn't change, so use the role definition GUID in your code to avoid issues while the rename rolls out. Observability in Microsoft Foundry Governance requires more than access control. Organizations also need evidence of how agents are being used. Observability provides the audit trail needed to investigate incidents, understand usage patterns, and track costs. The Foundry Control Plane brings these observability and governance tools together in one place, alongside services like Azure Monitor, Microsoft Entra, Microsoft Purview, and Azure Policy. In the Foundry portal, tracing is a good starting point. Once you connect an Application Insights resource to your project, Foundry turns on tracing automatically so every run, including the ones you test in the playground, is logged. After it is completed, you can search by Response ID or Trace ID to see the conversation history, token usage, run steps, tool calls, and inputs and outputs between the user and the agent. For more granular queries, you can write KQL to dive into individual agent runs or use the prebuilt Grafana dashboards in Azure Monitor. With client-side tracing, you can also export traces to observability tools you may already use, such as Datadog or Jaeger. Note: Permissions required for viewing this telemetry requires the Log Analytics Reader role on the connected Application Insights resource, and Privileged Monitoring Data Reader on top of that if the underlying Log Analytics tables are protected. Alongside all of these monitoring features, every agent comes with content safety guardrails and evaluations let you test and optimize performance before and after you publish your agents. When agents get published to Microsoft Teams and Microsoft 365 Copilot, Microsoft 365 admins can approve usage requests. These requests can be further scoped to a limited group for pilot testing/department usage or the full organization. Adding an AI gateway Observability tells you what your agents are doing, but how do you actually control them? This is where Azure API Management comes in. Once you have more than one agent, model deployment, or multiple teams consuming them, you need a single enforcement point between the agents and the resources they call. Adding Azure API Management in front of Microsoft Foundry gives you: Rate limiting and load balancing across regions and model deployments Consistent authentication and quota policies for model and tool traffic Usage tracking per team or cost center so you can accurately charge back to different departments Governed access to your custom and remote MCP servers Note: When choosing MCP servers, start with trusted, enterprise supported sources (GitHub, Microsoft, internally developed servers, etc.) that have documented security controls, enterprise authentication, clear ownership, and least-privilege permissions. Treat community MCP servers as untrusted until they have undergone a formal security review and are verified by organizations. Adding an AI gateway completes the governance picture. Azure Policy governs what can be deployed. RBAC governs who can build and manage agents. Observability provides evidence of how agents behave in production. The AI gateway extends governance into runtime, controlling how agents interact with models, tools, and external systems. Combined, these layers help organizations move beyond simply building agents to operating them responsibly at scale. Extend governance across the wider estate A few directions to take this further: MCP registry in Azure API Center – As MCP usage grows, you can create an approved inventory of MCP servers and APIs that can be used across an organization. Microsoft Agent 365 – Microsoft's enterprise control plane for AI agents. It gives every agent its own Microsoft Entra Agent ID and published Foundry agents sync to its registry automatically. This gives your IT team one place to run access reviews, lifecycle policies, and owner attestation across every agent in the tenant, including shadow agents discovered outside Foundry. Copilot Studio – when you add an MCP tool, you can point it at the API Management URL instead of the direct remote endpoint to gain additional observability through the gateway. GitHub Copilot – you can apply the same AI gateway-fronted MCP registry, applied to the developer side. Microsoft Purview – data classification, DLP, audit, and AI interaction governance across the wider estate. Where to go next Looking for a quick start? Turn on the three Azure Policy definitions above in audit mode against a non-production subscription and see what gets flagged that is out of compliance. Ready to design the end-to-end pattern? Take a look at this Cloud Adoption Framework guidance on AI governance and governing Azure platform services for AI. Want to go deeper on agent observability? Start with these articles around Application Insights integrations with Foundry: Use Insights in Microsoft Foundry and Monitor AI Agents with Application Insights Governing AI agents doesn't require starting from scratch. The identity, policy, monitoring, and cost controls you already use for the rest of your Azure estate can extend to AI workloads. Start with one layer, connect the next, and build a governance foundation that grows with your AI adoption.71Views2likes0Comments
Update network rules for the API Management service tag
To improve Azure API Management resiliency and scalability, we’re expanding our infrastructure and adding control-plane IP addresses. These addresses are included in the ApiManagement service tag. If you use VNet internal or VNET external with the classic (v1) tiers, check your network security groups (NSGs), user-defined routes (UDRs), and firewalls. Replace hard-coded API Management IP addresses with the service tag wherever supported. Make this change by November 30, 2026, to avoid disruption to management access. If network rules block connectivity to the management endpoint after that date, you may be unable to manage your API Management configuration—such as APIs, operations, and policies—from the Azure portal or CLI. This change affects management-plane traffic only. Runtime traffic, including API calls to your services, is not impacted. Find the ApiManagement tag in Microsoft’s Azure service tags overview or the latest Azure IP Ranges and Service Tags JSON download. If your firewall doesn’t support service tags, use the published list and keep your IP rules synchronized with its latest version. Don’t rely on a fixed, point-in-time IP list. During the transition, the service tag includes both existing and new addresses. For reference: Use API Management in an internal virtual network
Using Jev with Agents in Microsoft Foundry for Model Evaluation
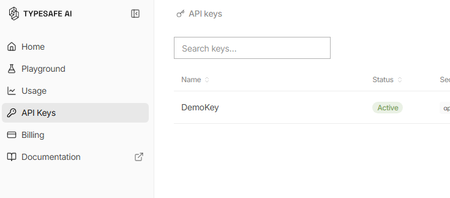
What is Jev? Jev is a new AI model from TypeSafe AI, first released in early access on 15 September 2026. TypeSafe describes Jev as its first “System One” model, designed specifically to make fast, structured decisions rather than generate free-form text. You provide Jev with some state or context and define the judgement you want it to make. It then returns a typed, probabilistic decision, such as: Choice: select from a defined set of options Score: evaluate something against an ordered scale Yes/No probability: determine the probability of a condition being true Unlike a conventional LLM, Jev gives up string generation in favour of type-safe structured values. Their description is essentially unstructured state in, typed probabilistic decisions out Why use Jev? Jev is particularly useful when an application needs to make a judgement rather than generate an answer. For example: Consistent evaluation against explicitly defined criteria Structured outputs that applications can consume directly Classification, assessment, routing and decision-support Agent workflows, where a judgement is required before taking an action Guardrails, such as assessing whether an agent should make a tool call Model routing, where a judgement determines which model or process should handle a request Every decision can also include a confidence or probability, allowing an application to use thresholds to decide when to proceed automatically or when further review is required. Jev and explainability Jev can provide a different approach to explainability for Model-as-a-Service (MaaS) and hosted LLM solutions. Traditional explainability techniques such as SHAP provide feature-attribution explanations for model predictions. Applying these techniques can be more difficult when the model is consumed solely through a hosted API and its internals are not available. Jev does not replace SHAP or provide the same type of feature-attribution explanation. Instead, it can be used as a separate judgement layer, evaluating an LLM's inputs, outputs or proposed actions against explicit criteria and returning structured decisions with confidence scores. For example: LLM generates an answer → Jev evaluates the answer → application decides what to do next This can provide a useful, measurable evaluation layer around otherwise opaque MaaS models. Could you do this with another LLM? Yes you could ask a conventional LLM to classify, score or evaluate an input and request structured JSON output. However, Jev has been purpose-built for this type of workload rather than general-purpose text generation. TypeSafe reports that Jev produces outputs in parallel rather than generating tokens sequentially, and its hosted service currently advertises typical decision latency of approximately 70–500 ms. Pricing As of September 2026, TypeSafe's documentation lists Jev 1.13 (jev-1.13.0) at $0.042 per million input tokens, with output tokens free. It lists rate limits of 250,000 tokens per second and 1,200 requests per minute, although TypeSafe states that these limits can change. As Jev produces decisions rather than generated text, you are effectively paying for the context it evaluates rather than for generated output. Pricing is subject to change and these figures are accurate only as of the date of this article Using Jev with Microsoft Foundry A useful pattern with Microsoft Foundry is to treat Jev as a specialised judgement/evaluation component alongside your generative models: User/Application → Foundry model or agent → Jev judgement → deterministic logic → action/response For example, a Foundry-hosted model could generate a proposed answer and Jev could evaluate that answer against predefined criteria before your application allows the workflow to continue. Here's how to set it up: First, you will need to apply for the preview for Jev from TypeSafe. Once you have an account you will need to create an API key Go to API keys in the menu and create a new key (copy the key for use in Foundry) You may also have received some free credit, which should be more than sufficient for experimenting with Jev given its low per-token cost. Next we go to Foundry and create a new agent for Jev In your agent, add a Tool and select OpenAPI tool as below Fill out the dialogue as follows You will have to create a new connection - The key should be in this format "Bearer apikey_<the rest of your key>" For the schema add this { "openapi": "3.0.3", "info": { "title": "TypeSafe Jev System One", "version": "1.1.0", "description": "Evaluate content using TypeSafe Jev System One." }, "servers": [ { "url": "https://api.typesafe.ai" } ], "paths": { "/v1/systemone": { "post": { "operationId": "evaluate_with_jev", "summary": "Evaluate content using Jev", "description": "Evaluate state against typed questions using TypeSafe Jev.", "security": [ { "bearerAuth": [] } ], "requestBody": { "required": true, "content": { "application/json": { "schema": { "type": "object", "additionalProperties": false, "required": [ "state", "model", "questions" ], "properties": { "state": { "type": "string", "description": "The original text or content for Jev to evaluate." }, "model": { "type": "string", "enum": [ "jev-latest" ], "default": "jev-latest", "description": "The TypeSafe Jev model. Use jev-latest." }, "questions": { "type": "object", "description": "A map of named questions for Jev to answer. Each question must be a Noul, Choice, or Score question.", "additionalProperties": { "oneOf": [ { "$ref": "#/components/schemas/NoulQuestion" }, { "$ref": "#/components/schemas/ChoiceQuestion" }, { "$ref": "#/components/schemas/ScoreQuestion" } ] } } } } } } }, "responses": { "200": { "description": "Successful Jev evaluation", "content": { "application/json": { "schema": { "type": "object", "additionalProperties": true } } } }, "400": { "description": "Invalid request" }, "401": { "description": "Authentication failed" }, "422": { "description": "Request validation failed" } } } } }, "components": { "schemas": { "NoulQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions" ], "properties": { "type": { "type": "string", "enum": [ "noul" ] }, "instructions": { "type": "string", "description": "The yes/no question for Jev to evaluate." }, "criteria": { "type": "object", "additionalProperties": false, "properties": { "true": { "type": "string", "description": "Description of what a yes or value near 1 means." }, "false": { "type": "string", "description": "Description of what a no or value near 0 means." } } } } }, "ChoiceQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions", "criteria" ], "properties": { "type": { "type": "string", "enum": [ "choice" ] }, "instructions": { "type": "string", "description": "The question for Jev to decide between the supplied choices." }, "criteria": { "type": "object", "description": "A map where each property name is a possible choice and its value describes that choice.", "minProperties": 2, "additionalProperties": { "type": "string" } } } }, "ScoreQuestion": { "type": "object", "additionalProperties": false, "required": [ "type", "instructions", "criteria" ], "properties": { "type": { "type": "string", "enum": [ "score" ] }, "instructions": { "type": "string", "description": "The attribute or question Jev should score." }, "criteria": { "type": "array", "description": "Ordered scoring levels from lowest to highest.", "minItems": 2, "items": { "type": "string" } } } } }, "securitySchemes": { "bearerAuth": { "type": "apiKey", "name": "Authorization", "in": "header" } } }, "security": [ { "bearerAuth": [] } ] } We are going to use Jev to assess complaints so our instructions for the Agent will be You are a customer-support triage agent. For every customer-support message you MUST call the evaluate_with_jev tool. IMPORTANT: When calling evaluate_with_jev, construct Jev questions using ONLY the following property names: For a Noul question: { "type": "noul", "instructions": "...", "criteria": { "true": "...", "false": "..." } } For a Choice question: { "type": "choice", "instructions": "...", "criteria": { "option1": "...", "option2": "..." } } For a Score question: { "type": "score", "instructions": "...", "criteria": [ "lowest level", "middle level", "highest level" ] } NEVER use these properties: - question - prompt - options - ordered_criteria Always use: - instructions - criteria For customer support tickets, ask Jev these three questions: billing: type = noul instructions = "Does this ticket concern billing, payments, charges, invoices or refunds?" criteria.true = "The issue concerns billing or a financial transaction." criteria.false = "The issue does not concern billing or a financial transaction." tone: type = choice instructions = "What is the customer's tone?" criteria: calm = "Neutral, polite or informational." frustrated = "Dissatisfied, impatient or inconvenienced." angry = "Strongly confrontational or extremely dissatisfied." urgency: type = score instructions = "How urgently does this ticket require attention?" criteria in this exact order: 1. "Can wait" 2. "Handle this week" 3. "Handle today" Always set model to "jev-latest". Pass the customer's original message as state. Do not classify the ticket yourself. Use the values returned by Jev. Always show the Jev output at the end of the response Now we can give a complaint and see what Jev says The room had no water in and one of the towels was dirty Response I’m sorry about the issues you experienced—no running water and a dirty towel are unacceptable. I’ll get this addressed right away. Immediate help I can arrange now: Send maintenance to restore water. Have housekeeping deliver fresh towels and re-service the bathroom. Provide bottled water immediately. If water can’t be restored quickly, arrange a room move. Please share: Your reservation name and room number Best contact number Whether there’s no water at all or only hot/cold is affected Whether you prefer immediate service or a room change If you’ve already left, let me know the date/time this happened so we can investigate and follow up. Jev output: { "model": "jev-1.13.0", "answers": { "billing": { "type": "noul", "noul": 0.02 }, "tone": { "type": "choice", "choice": "frustrated", "confidence": 0.6, "probabilities": { "frustrated": 0.74, "calm": 0.26, "angry": 0.0 } }, "urgency": { "type": "score", "score": 1.81, "confidence": 0.72, "legend": { "0": "Can wait", "1": "Handle this week", "2": "Handle today" }, "probabilities": { "0": 0.03, "1": 0.12, "2": 0.85 } } }, "usage": { "input_tokens": 466, "output_tokens": 75 } } We can now see both Jev's decision and the probabilities behind it. In this example, Jev determines that the complaint is very unlikely to be billing-related, identifies the customer's tone as frustrated, and gives a high probability that the issue should be handled today. This is where Jev becomes particularly useful in an agent workflow. Rather than relying on generated text to drive the next step, our application can use these structured probabilities to make deterministic decisions, such as routing the complaint, escalating it, or requiring human review when confidence falls below a defined threshold.From Business Brief to Production Agent: Building in Three Stages, Not One
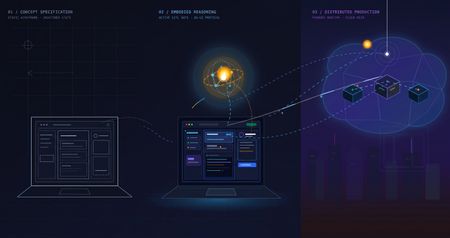
The problem with "AI can help my business" Every non-technical founder has heard some version of "you should put an AI agent on this." Far fewer have seen what it actually costs, in time and money, to find out whether that's true for their specific business — before committing to it. The honest answer is: it shouldn't cost much at all, if you build it in the right order. Most of the expensive AI project failures aren't failures of the model — they're failures of sequencing. Someone commits to real infrastructure, real hosting, and real integration work before anyone has confirmed the underlying idea even holds up. This post walks through a small, realistic project — an autonomous sales-development agent for a fictitious construction-tech company — built in three deliberate stages, each one cheap enough to abandon and each one answering a different question before the next stage spends any more money or time. The point isn't the specific agent. It's the order of operations: what to validate first, what to validate second, and what you only pay for once everything before it has already been proven. The Brief Hi, I'm looking for someone who can help me grow FieldForge, a SaaS platform specifically for general contractors, remodelers, and design-build companies. I'm not looking for generic lead lists. I need someone who can identify qualified construction companies, reach the owner/decision-maker, start conversations, and book demos that can turn into paying SaaS customers. Your experience with B2B lead generation and appointment setting looks relevant. I'd love to hear how you would approach generating qualified leads and growing a construction-focused SaaS. Translated into engineering terms, that's four capabilities: pull in new leads from a data feed (ingest_permits), decide whether each one is worth pursuing (qualify_lead), draft a personalized first-touch email for the ones that qualify (generate_pitch_email), and hand qualified leads off to an outbound sequence (dispatch_sequence). Nothing about that list requires committing to any infrastructure yet — which is exactly the point of Stage 1. Stage 1: Mock prototype — no AI, no backend, no cost The first stage has no real agent in it at all. It's a Vite + React console with the full intended UI — a strategy pane, a live-feed pane, a lead-dossier pane — wired to hand-written mock data and a fake setTimeout standing in for "the AI is thinking." No model calls, no cloud resources, no backend of any kind. It runs entirely in a browser tab: This is deliberately the cheapest possible way to answer the first real question: does this even make sense as a product, before a single token of inference is spent proving it? Is a 3-pane command console the right way to expose "an agent found and qualified these leads for you"? Is a permit-triggered pitch angle a good hook, or does it look contrived once it's actually on screen? Does a business owner look at this and understand what they're being offered? None of those questions need a real agent to answer — they need a UI a person can click through and react to. Running this stage costs essentially nothing beyond development time: no API calls, no cloud spend, nothing to tear down if the idea doesn't land. Where the AI pair programmer actually did the work. This entire stage — the layout, the state management, the mock data shapes, the interaction flow — was built by describing the product in plain language to an AI coding assistant (GitHub Copilot, Claude) and iterating on the generated code directly, rather than dragging components around in a low-code builder. That distinction matters more than it sounds like it should. A low-code prototype is fast to show, but it's still just a prototype — once a real agent needs to sit behind it, most of that first version gets rebuilt in real code anyway. A pro-code prototype, even a fake one, is a keepable asset: the exact same React components, the exact same UI shell, carry forward unchanged into Stage 2 and Stage 3. Nothing here gets rebuilt later — it gets connected to something real. What this stage proves, and what it deliberately doesn't. By the end of Stage 1, you know whether the product concept and the UX hold up — whether the thing you're describing to a non-technical stakeholder actually makes sense once it's on a screen in front of them. What it tells you nothing about: whether a real model can actually do the reasoning this UI is pretending to show. That's a completely different risk, and it's wrong to pay for cloud infrastructure to find out — it just needs a real agent, still running on a laptop: Stage 2: A real agent, still running on a laptop — the convincing part This is the stage that actually matters most, and it's also the cheapest place to find out if the whole idea works. The fakery gets ripped out and replaced with a genuine agent: a Microsoft Agent Framework Agent, backed by a real model deployment on Microsoft Foundry, given the same four tools from the brief — ingest_permits, qualify_lead, generate_pitch_email, dispatch_sequence — as real Python functions it can actually call. Its reasoning streams live into the same terminal-style pane the mock prototype already had, so nothing about the UI needs to change; only what's driving it does. Crucially, the frontend stays on a local dev server and the agent stays a local process on the same machine. There's no cloud hosting, no production auth, no deployment pipeline — the UI just talks to a locally running agent server over a simple streaming protocol. That's the deliberate design of this stage: the only thing worth testing here is whether the agent is actually good, and every question that matters — does it call tools in a sensible order, does it correctly decide which leads qualify, does its drafted email actually reflect the lead's specific trigger event rather than reading like a template — can be answered without touching a cloud resource. The qualify_lead tool is where this gets concrete: it's handed a target definition — commercial/residential remodelers in a specific revenue band, an active permit filing, still running manual/legacy tooling — and has to decide, per lead, whether it's a fit. You'll see this called an ICP (Ideal Customer Profile) constantly in sales and GTM circles right now, to the point of being a bit of a buzzword. Stripped of the jargon it's just this: a precise, written-down definition of a good-fit customer, specific enough that a model can apply it as consistently as a trained human rep would. The reason it matters isn't the term — it's that the agent's usefulness is bounded entirely by how precisely that definition is written, and this stage is exactly where you find out if yours is precise enough. This is also where model choice gets decided, cheaply. Swapping which Foundry model deployment sits behind the agent, or rewriting the system instructions, costs a restart and a few cents of inference — not a redeploy, not a new pipeline run. If gpt-4o isn't giving good enough qualification judgment, or the reasoning is inconsistent between runs, you find out here, in seconds per iteration, for the price of a handful of API calls. Compare that to discovering the same problem after cloud hosting, authentication, and a production pipeline are already built around it. That's why this stage — not Stage 1 — is the genuinely convincing one. Anyone can mock up a UI that looks like an agent found and qualified a lead. Stage 2 is where you can put a real, unscripted permit feed in front of a real model and watch it reason its way to a defensible qualify/reject decision and a genuinely personalized email, live, for the cost of a few model calls. That's the moment a skeptical stakeholder stops asking "does this actually work" and starts asking "when can we have it." What this stage proves, and what it deliberately doesn't. By the end of it, you know the agent itself is sound — right tools, right order, correct ICP logic, real personalization — for a cost barely above Stage 1's. What it hasn't touched: what happens when a real user hits this over the public internet, how auth works outside your own machine, whether the hosting model you eventually pick can actually serve this reliably. That's a different kind of work, and it starts now that there's finally something worth doing that work for. Stage 3: Quasi-production — translating a proven agent into a running service Stage 2 answers "does the agent work." Stage 3 answers a different question entirely: "can this be handed to someone who isn't on my laptop." That's not a continuation of Stage 2's work — it's a translation of it. The agent's logic, tools, and instructions don't change at all going into this stage; what changes is everything around them, as the same proven Agent gets repackaged into something that can actually run as a service instead of a local process. The agent itself deploys as a Foundry Hosted Agent via azd — no hand-written Dockerfile, no Container App config, no Bicep authored from scratch; Foundry's managed hosting owns the runtime, scaling, and session continuity (via previous_response_id chaining on the Responses protocol), and assigns the agent its own managed identity. The frontend and its API layer become an Azure Static Web App: the React build as static assets, plus a small same-origin Azure Function that reverse-proxies requests to the hosted agent. That proxy exists for a concrete reason — Foundry's hosted-agent endpoint has no CORS support, so a browser calling it directly would simply be refused; routing through a same-origin Function sidesteps that entirely, and keeps the real agent URL and credentials server-side instead of sitting in a public JS bundle. None of that is agent work. It's the operational work of turning a validated prototype into a real, addressable, network-reachable thing — the productionization step every agent eventually needs regardless of how it was built, and the part that's easy to underestimate if you haven't budgeted for it as its own phase. Framed plainly, this stage is where the project stops being "a demo that runs on my machine" and starts being "a small SaaS": something with a real URL, a real hosting bill, real auth, and a real deploy pipeline — everything that separates a working prototype from a thing you could actually put a customer in front of. To be clear about the boundary of "quasi": this is not a fully hardened production system. There's no custom domain, no persistent session store beyond what Foundry provides out of the box, and no load testing. What it is: proof that the exact agent validated in Stage 2 can be deployed, reached over a real network, and driven from a real hosted frontend without silently breaking — the last class of risk that only shows up once something leaves your own machine. What this stage proves, and what it deliberately doesn't. By the end of it, you know the whole pipeline holds together end to end, from a hosted UI through a same-origin proxy to a Foundry-managed agent and back, streaming, over a real deployment. What it doesn't prove: that it holds up under real production load, real customer data governance, or a real incident on-call rotation. Those are legitimate next questions — just not the ones this stage was built to answer, and not ones worth paying for before the first two questions were settled. The pattern, not just the project Line the three stages up and the shape becomes obvious: each one is deliberately the cheapest possible way to eliminate one specific class of risk before the next stage spends real money finding out the hard way. Stage 1 kills product/UX risk for the cost of dev time and zero infrastructure. Stage 2 kills agent-quality risk — the right tools, the right model, correct decisions — for the cost of a few model calls, and it's the stage that actually earns anyone's confidence that this is real. Stage 3 kills operational risk — real hosting, real network, real auth — by translating an already-proven agent into a running service, rather than building all of that around an agent nobody has validated yet. Collapse those stages — build the hosting and the agent and the UI all at once, betting everything up front — and you don't save time. You just move all three classes of failure into the same debugging session, at the point where they're most expensive to disentangle and hardest to tell apart. Staged this way, each phase is cheap enough to walk away from if it fails, and each one only gets built on top of a phase that already earned its place. There's a second half to this story that's deliberately not in this post: the data. Everything here ran on synthetic permit feeds and mock company data — a real deployment lives or dies on where its actual leads come from and how well they're structured for a model to reason over. That's its own story, and it gets a dedicated write-up of its own. Project reference Source code: https://github.com/olivierb123/lead-agent-demo Live demo: https://victorious-glacier-03340ff0f.3.azurestaticapps.net81Views0likes0Comments
Your Agent Shouldn't Wait for a Prompt: Build an Event-Driven Microsoft Foundry Routine
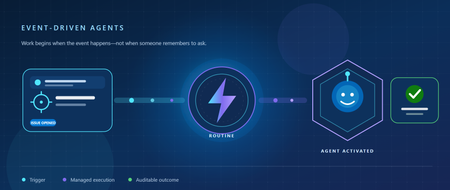
Most agents are still waiting in a chat window. They may be capable of classifying an incident, finding the right documentation, or recommending an owner - but nothing happens until someone remembers to ask. The hard part is no longer always the reasoning. It is noticing that work has arrived, invoking the agent securely, and keeping enough history to understand what happened. Routines in Microsoft Foundry close that gap. A routine connects a trigger - such as a schedule, timer, GitHub issue, or Microsoft Teams message - to an agent action. Microsoft Foundry queues the invocation, runs the agent, and stores a run record for later inspection. In this post, we will build an event-driven routine for a familiar developer workflow: When someone opens a GitHub issue, invoke a triage agent immediately - without waiting for a person to copy the issue into a chat. Along the way, we will look at the architecture, create the routine with the Azure Developer CLI (azd), test it, inspect its run history, and make an explicit identity decision before putting it into production. From conversational agents to event-driven agents A chat-first agent follows a request-response pattern: A user opens an interface. The user provides a prompt. The agent performs work. The interaction ends or waits for another prompt. An event-driven agent starts differently. Work in an external system becomes the prompt. A newly opened issue, for example, already contains useful context: its title, description, author, repository, labels, and timestamps. A routine can receive that event through an authorized connection and invoke an agent while the context is still fresh. That changes the agent's role. It is no longer only a place people go for answers. It becomes a participant in an operational workflow. The routine does not replace the agent. It supplies the managed automation around it: Trigger: Defines when work starts. Connection: Authenticates the event source. Action: Identifies the agent and invocation protocol. Dispatch identity: Determines whose permissions are used when the agent and its tools run. Run history: Records executions so operators can inspect outcomes. This separation is useful. The agent owns the reasoning; the routine owns when and how that reasoning begins. The scenario: triage every new GitHub issue Our example assumes that a triage agent is already deployed in a Microsoft Foundry project. When an issue opens, the agent should: Summarize the issue in two or three sentences. Classify it as a bug, feature request, documentation issue, or support question. Estimate severity and explain the evidence. Recommend an owner or team. Identify missing reproduction details. Produce a proposed response for a maintainer to review. Keeping a human review step is intentional. Event-driven does not have to mean unrestricted autonomy. A routine can automate the expensive first pass while a maintainer remains responsible for labels, assignments, and public responses. Prerequisites You need: An active Microsoft Foundry project. The Foundry User role or higher on the project. A deployed prompt agent or hosted agent. Workflow agents are not currently supported by routines. The Azure Developer CLI. A GitHub connection authorized in the Foundry project. The routines extension for azd. Install the extension and confirm that the routine commands are available: azd extension install azure.ai.routines azd ai routine --help Set the project endpoint through your active azd environment or pass it explicitly to each command: azd env set AZURE_AI_PROJECT_ENDPOINT \ "https://<account>.services.ai.azure.com/api/projects/<project>" The agent must exist before you attach a routine to it. A routine references an agent; it does not deploy one. Create the GitHub issue routine The following command creates an enabled routine named triage-on-open. Replace the placeholders with the connection and repository details from your environment: azd ai routine create triage-on-open \ --trigger github-issue \ --connection-id "<workspace-connection-id>" \ --owner "<github-owner>" \ --repository "<github-repository>" \ --issue-event opened \ --action agent-invoke \ --agent-name "triage-agent" \ --description "Triage every newly opened GitHub issue" There are two important type translations in this command: The CLI alias github-issue represents the routine trigger type github_issue. The CLI alias agent-invoke invokes the agent through the Invocations API. If your agent uses the Responses API instead, use --action agent-response. Choose the protocol that matches the deployed agent rather than treating the two actions as interchangeable. For automation that belongs in source control, define the routine as an azure.ai.routine service in azure.yaml. This makes the relationship between the agent and its trigger reproducible across environments: services: triage-agent: host: azure.ai.agent project: ./agent triage-on-open: host: azure.ai.routine uses: - triage-agent description: Triage every newly opened GitHub issue enabled: true triggers: issue-opened: type: github_issue connection_id: ${GITHUB_CONNECTION_ID} owner: ${GITHUB_OWNER} repository: ${GITHUB_REPOSITORY} issue_event: opened action: type: invoke_agent_invocations_api agent_name: triage-agent Deploy the routine after the target agent: azd deploy triage-on-open --no-prompt The uses relationship tells azd to order the agent before the routine. Deployment is idempotent: redeploying updates the named routine instead of creating duplicates. Give the agent a clear triage contract Automation magnifies ambiguity. A vague instruction that is merely inconvenient in a chat can produce inconsistent work every time an event fires. Give the triage agent a bounded contract such as: You are the first-pass triage agent for this repository. For each newly opened issue: 1. Summarize the reported behavior without adding facts. 2. Classify it as bug, feature, documentation, or support. 3. Assign severity only when the issue contains supporting evidence. 4. List missing information needed to reproduce or route the issue. 5. Recommend an owner from the approved ownership map. 6. Draft a response, but do not publish, close, label, or assign the issue. Return structured JSON that matches the triage schema. A useful output contract might look like this: { "summary": "The CLI exits when a project endpoint contains an explicit port.", "category": "bug", "severity": { "level": "medium", "reason": "The issue blocks routine creation but has a documented workaround." }, "missing_information": [ "Azure Developer CLI version", "Redacted project endpoint shape", "Full error output" ], "recommended_owner": "developer-experience", "proposed_response": "Thanks for the report. Could you share..." } Structured output gives downstream systems something predictable to validate. It also makes evaluation easier: you can test category accuracy, required-field completeness, unsupported severity claims, and whether the agent attempted a prohibited action. Test before waiting for a real event Start by checking that Foundry stored the routine you intended: azd ai routine show triage-on-open --output json Confirm: The routine is enabled. The trigger watches the correct owner and repository. issue_event is opened. The action references the intended agent. The connection ID belongs to the expected Foundry project. You can manually dispatch a routine while testing: azd ai routine dispatch triage-on-open \ --input '{"test":true,"issue":{"number":123,"title":"Test triage event"}}' The manual input is a one-time override for that dispatch. It does not replace the event payload or modify the routine's stored configuration. Inspect recent executions: azd ai routine run list triage-on-open --top 20 Then open a test issue in the watched repository and inspect the run list again. A production test should verify more than "the agent ran." Check that the correct event started the run, the agent received enough context, tool calls used the intended identity, the output matched the schema, and prohibited actions did not occur. Choose the dispatch identity deliberately Every routine uses the agent identity by default. This is usually the better fit for unattended automation because access belongs to the agent rather than to an employee's account. Use agent identity when the agent's tools authenticate with managed identity, workload identity, or keys and the agent has been granted only the permissions required for the task. Some tools require delegated user access. In that case, you can create the routine with creator identity. Creator identity means the Microsoft Entra identity of the person or service principal that creates the routine—not the agent publisher, connection creator, latest editor, or user who caused an event. This distinction has operational consequences: If the creator loses access or consent, delegated tool calls can fail. Recreating the routine as another principal changes the delegated creator identity. The event connection identity is separate from the identity used to dispatch the agent. Dispatch identity is a creation-time decision. To switch an existing routine between agent and creator identity, delete and recreate it. For a GitHub triage flow, a strong starting design is: Use a narrowly scoped project connection to receive issue events. Use agent identity for Foundry and Azure resources. Keep repository-changing actions disabled until evaluation demonstrates reliable behavior. Require human approval before posting, assigning, labeling, or closing. Identity is not a deployment detail. It is part of the automation's behavior and should be reviewed with the same care as the prompt and tool list. Make failure visible An event-driven agent can fail even when its reasoning is sound. The connection might expire. The agent might receive an unexpected payload. A tool might lose permission. The output might violate its schema. Monitor the workflow at four boundaries: Trigger: Did the expected event fire the routine exactly once? Invocation: Did Foundry invoke the intended agent and protocol? Tools: Did tool calls succeed with the intended identity and scope? Outcome: Did the output satisfy the triage contract? Use azd ai routine run list for routine execution history and your agent's Foundry observability data for traces, tool calls, latency, and failures. Preserve representative failures as evaluation cases instead of fixing each incident only in the prompt. Also design for duplicate delivery. Before taking a repository-changing action, check whether the issue and event have already been processed. Idempotency matters more once an agent can act without a person initiating each run. Know the current boundaries Before adopting routines for a regulated or business-critical workload, review the current service constraints: Routines support prompt agents and hosted agents, but not workflow agents. A recurring schedule has a minimum interval of five minutes. GitHub issue triggers support opened and closed issue events. Routines inherit the project's networking configuration and can work with virtual-network-secured projects. Routines do not currently support customer-managed key encryption. Regional availability has exceptions; verify your project's region in the current documentation. These boundaries can change. Treat the routines documentation as the source of truth when moving from a tutorial to production. What changes when agents stop waiting? The most interesting part of this design is not the GitHub trigger. It is the change in operating model. The agent begins work because the world changed, not because someone opened a chat. That makes trigger scope, identity, output contracts, run history, evaluation, and human approval part of the agent design—not infrastructure to consider later. Once the triage routine is working, the same pattern can support: A Teams message that starts support classification. A nightly backlog review. A one-time release-readiness check. A scheduled compliance summary. A hosted agent that uses the reminder tool to resume the same conversation after a long-running task. Start with one bounded event and one reversible outcome. Measure what the agent does, not merely whether it ran. Then expand its permissions only as evidence earns that autonomy. Try it next Choose the path that matches where you are: Build: Follow the Microsoft Foundry routines documentation and connect one existing agent to a schedule or event. Harden: Review dispatch identity, connection scope, idempotency, output validation, and human approval before enabling repository-changing tools. Extend: Add the reminder tool to a hosted agent that needs to continue work later. Explore: Open the Microsoft Foundry portal to inspect your project, agents, and routine runs. Your agent already knows how to do useful work. The next step is teaching it when that work should begin.385Views2likes2CommentsYour Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.384Views1like0CommentsVoice agents in Foundry Agent Service: architecture, trust boundaries, and real-audio latency
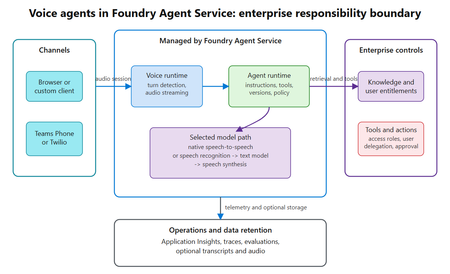
Assess where voice agents in Foundry Agent Service simplify the runtime, where enterprise trust boundaries remain, and what a 300-turn real-audio benchmark reveals about latency across six configurations.242Views0likes0CommentsCopilot, Microsoft 365 & Power Platform Community call
💡 Copilot, Microsoft 365 & Power Platform weekly community call focuses on different use cases and features within the Microsoft 365 and Power Platform - across Microsoft 365 Copilot, Copilot Studio, SharePoint, Power Apps and more. Demos in this call are presented by the community members. 👏 Looking to catch up on the latest news and updates, including cool community demos, this call is for you! 📅 On 8th of October we'll have following agenda: Latest news and events from Microsoft Topics Copilot prompt of the week CommunityDays.org update Microsoft 365 Maturity model PnP Framework and Core SDK extension PnP PowerShell Script samples Copilot pro dev samples Power Platform samples Demos this time Ritu Hooda – Building an Enterprise Prompt Library with Copilot CLI Iberedem Bassey – How to configure Administrative units in M365 (Standard and Restricted Management Admin unit creation) Fabian Hutzli – How to govern Sites.Selected Access 📅 Download recurrent invite from https://aka.ms/community/m365-powerplat-dev-call-invite 📞 & 📺 Join the Microsoft Teams meeting live at https://aka.ms/community/m365-powerplat-dev-call-join 💡 Building something cool for Microsoft 365 or Power Platform (Copilot, SharePoint, Power Apps, etc)? We are always looking for presenters - Volunteer for a community call demo at https://aka.ms/community/request/demo 👋 See you in the call! 📖 Resources: Previous community call recordings and demos from the Microsoft Community Learning YouTube channel at https://aka.ms/community/youtube Microsoft 365 & Power Platform samples from Microsoft and community - https://aka.ms/community/samples Microsoft 365 & Power Platform community details - https://aka.ms/community/home 🧡 Sharing is caring!93Views0likes0CommentsCopilot, Microsoft 365 & Power Platform product updates call
💡Copilot, Microsoft 365 & Power Platform product updates call concentrates on the different use cases and features within the Microsoft 365 and in Power Platform. Call includes topics like Microsoft 365 Copilot, Copilot Studio, Microsoft Teams, Power Platform, Microsoft Graph, Microsoft Viva, Microsoft Search, Microsoft Lists, SharePoint, Power Automate, Power Apps and more. 👏 Weekly Tuesday call is for all community members to see Microsoft PMs, engineering and Cloud Advocates showcasing the art of possible with Microsoft 365 and Power Platform. 📅 On the 6th of October we'll have following agenda: News and updates from Microsoft Together mode group photo Sara Cummings – Latest AI authoring features in SharePoint Ricky Castaneda – Building multi-channel Agents with Teams SDK and the new Agents SDK extension 📞 & 📺 Join the Microsoft Teams meeting live at https://aka.ms/community/ms-speakers-call-join 🗓️ Download recurrent invite for this weekly call from https://aka.ms/community/ms-speakers-call-invite 👋 See you in the call! 💡 Building something cool for Microsoft 365 or Power Platform (Copilot, SharePoint, Power Apps, etc)? We are always looking for presenters - Volunteer for a community call demo at https://aka.ms/community/request/demo 📖 Resources: Previous community call recordings and demos from the Microsoft Community Learning YouTube channel at https://aka.ms/community/youtube Microsoft 365 & Power Platform samples from Microsoft and community - https://aka.ms/community/samples Microsoft 365 & Power Platform community details - https://aka.ms/community/home 🧡 Sharing is caring!116Views0likes0CommentsHow to make AI responses faster on Microsoft Foundry: lessons from 2,040 measurements
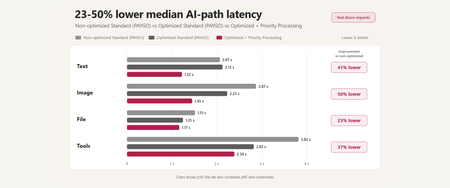
A reproducible Microsoft Foundry performance study covering prompt caching, multimodal input, tool orchestration, MCP lifecycle, Toolbox tool search, and Priority Processing - with correctness and reliability measured alongside latency.343Views0likes0Comments