ai
592 Topics
SharePoint at 25: The knowledge platform for Copilot and agents
Celebrate the 25th birthday of SharePoint with this global digital broadcast—now available on‑demand! Gear up for an exciting look at SharePoint’s historic moments along with an exclusive look ahead to the next chapter of SharePoint’s AI future! You will discover how SharePoint’s new content AI capabilities and intelligent experiences will transform the way people create, manage, and collaborate. 💡 Don’t miss the SharePoint Hackathon in March 2026 Design, create, share! We are excited to invite you to a hackathon dedicated to crafting exceptional employee experiences using AI and the latest SharePoint features. You don't need to be a developer - end users, designers, architects and everyone can join. Learn more at https://aka.ms/SPat25/hackathon. 🛠️ Don’t miss the SharePoint Hackathon in March 2026 Design, create, share! We are excited to invite you to a hackathon dedicated to crafting exceptional employee experiences using AI and the latest SharePoint features. More details coming soon. ADDITIONAL LINKS Watch the broadcast and AMA on-demand: https://aka.ms/SPat25 Watch our first release of SharePoint demo videos: https://aka.ms/SPat25/Playlist Stay connected with monthly product updates: https://aka.ms/SharePointShowcase Explore the global SharePoint community: https://aka.ms/SPCommunity Join our weekly community calls for latest on Copilot, SharePoint, Power Platform and more: https://aka.ms/community/calls15KViews36likes148CommentsAzure API Management Your Auth Gateway For MCP Servers
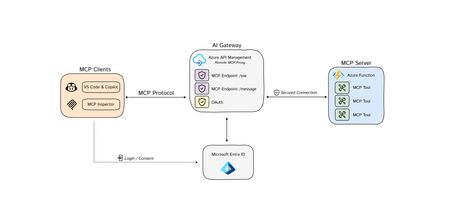
The Model Context Protocol (MCP) is quickly becoming the standard for integrating Tools 🛠️ with Agents 🤖 and Azure API Management is at the fore-front, ready to support this open-source protocol 🚀. You may have already encountered discussions about MCP, so let's clarify some key concepts: Model Context Protocol (MCP) is a standardized way, (a protocol), for AI models to interact with external tools, (and either read data or perform actions) and to enrich context for ANY language models. AI Agents/Assistants are autonomous LLM-powered applications with the ability to use tools to connect to external services required to accomplish tasks on behalf of users. Tools are components made available to Agents allowing them to interact with external systems, perform computation, and take actions to achieve specific goals. Azure API Management: As a platform-as-a-service, API Management supports the complete API lifecycle, enabling organizations to create, publish, secure, and analyze APIs with built-in governance, security, analytics, and scalability. New Cool Kid in Town - MCP AI Agents are becoming widely adopted due to enhanced Large Language Model (LLM) capabilities. However, even the most advanced models face limitations due to their isolation from external data. Each new data source requires custom implementations to extract, prepare, and make data accessible for any model(s). - A lot of heavy lifting. Anthropic developed an open-source standard - the Model Context Protocol (MCP), to connect your agents to external data sources such as local data sources (databases or computer files) or remote services (systems available over the internet through e.g. APIs). MCP Hosts: LLM applications such as chat apps or AI assistant in your IDEs (like GitHub Copilot in VS Code) that need to access external capabilities MCP Clients: Protocol clients that maintain 1:1 connections with servers, inside the host application MCP Servers: Lightweight programs that each expose specific capabilities and provide context, tools, and prompts to clients MCP Protocol: Transport layer in the middle At its core, MCP follows a client-server architecture where a host application can connect to multiple servers. Whenever your MCP host or client needs a tool, it is going to connect to the MCP server. The MCP server will then connect to for example a database or an API. MCP hosts and servers will connect with each other through the MCP protocol. You can create your own custom MCP Servers that connect to your or organizational data sources. For a quick start, please visit our GitHub repository to learn how to build a remote MCP server using Azure Functions without authentication: https://aka.ms/mcp-remote Remote vs. Local MCP Servers The MCP standard supports two modes of operation: Remote MCP servers: MCP clients connect to MCP servers over the Internet, establishing a connection using HTTP and Server-Sent Events (SSE), and authorizing the MCP client access to resources on the user's account using OAuth. Local MCP servers: MCP clients connect to MCP servers on the same machine, using stdio as a local transport method. Azure API Management as the AI Auth Gateway Now that we have learned that MCP servers can connect to remote services through an API. The question now rises, how can we expose our remote MCP servers in a secure and scalable way? This is where Azure API Management comes in. A way that we can securely and safely expose tools as MCP servers. Azure API Management provides: Security: AI agents often need to access sensitive data. API Management as a remote MCP proxy safeguards organizational data through authentication and authorization. Scalability: As the number of LLM interactions and external tool integrations grows, API Management ensures the system can handle the load. Security remains to be a critical piece of building MCP servers, as agents will need to securely connect to protected endpoints (tools) to perform certain actions or read protected data. When building remote MCP servers, you need a way to allow users to login (Authenticate) and allow them to grant the MCP client access to resources on their account (Authorization). MCP - Current Authorization Challenges State: 4/10/2025 Recent changes in MCP authorization have sparked significant debate within the community. 🔍 𝗞𝗲𝘆 𝗖𝗵𝗮𝗹𝗹𝗲𝗻𝗴𝗲𝘀 with the Authorization Changes: The MCP server is now treated as both a resource server AND an authorization server. This dual role has fundamental implications for MCP server developers and runtime operations. 💡 𝗢𝘂𝗿 𝗦𝗼𝗹𝘂𝘁𝗶𝗼𝗻: To address these challenges, we recommend using 𝗔𝘇𝘂𝗿𝗲 𝗔𝗣𝗜 𝗠𝗮𝗻𝗮𝗴𝗲𝗺𝗲𝗻𝘁 as your authorization gateway for remote MCP servers. 🔗For an enterprise-ready solution, please check out our azd up sample repo to learn how to build a remote MCP server using Azure API Management as your authentication gateway: https://aka.ms/mcp-remote-apim-auth The Authorization Flow The workflow involves three core components: the MCP client, the APIM Gateway, and the MCP server, with Microsoft Entra managing authentication (AuthN) and authorization (AuthZ). Using the OAuth protocol, the client starts by calling the APIM Gateway, which redirects the user to Entra for login and consent. Once authenticated, Entra provides an access token to the Gateway, which then exchanges a code with the client to generate an MCP server token. This token allows the client to communicate securely with the server via the Gateway, ensuring user validation and scope verification. Finally, the MCP server establishes a session key for ongoing communication through a dedicated message endpoint. Diagram source: https://aka.ms/mcp-remote-apim-auth-diagram Conclusion Azure API Management (APIM) is an essential tool for enterprise customers looking to integrate AI models with external tools using the Model Context Protocol (MCP). In this blog, we've emphasized the simplicity of connecting AI agents to various data sources through MCP, streamlining previously complex implementations. Given the critical role of secure access to platforms and services for AI agents, APIM offers robust solutions for managing OAuth tokens and ensuring secure access to protected endpoints, making it an invaluable asset for enterprises, despite the challenges of authentication. API Management: An Enterprise Solution for Securing MCP Servers Azure API Management is an essential tool for enterprise customers looking to integrate AI models with external tools using the Model Context Protocol (MCP). It is designed to help you to securely expose your remote MCP servers. MCP servers are still very new, and as the technology evolves, API Management provides an enterprise-ready solution that will evolve with the latest technology. Stay tuned for further feature announcements soon! Acknowledgments This post and work was made possible thanks to the hard work and dedication of our incredible team. Special thanks to Pranami Jhawar, Julia Kasper, Julia Muiruri, Annaji Sharma Ganti Jack Pa, Chaoyi Yuan and Alex Vieira for their invaluable contributions. Additional Resources MCP Client Server integration with APIM as AI gateway Blog Post: https://aka.ms/remote-mcp-apim-auth-blog Sequence Diagram: https://aka.ms/mcp-remote-apim-auth-diagram APIM lab: https://aka.ms/ai-gateway-lab-mcp-client-auth Python: https://aka.ms/mcp-remote-apim-auth .NET: https://aka.ms/mcp-remote-apim-auth-dotnet On-Behalf-Of Authorization: https://aka.ms/mcp-obo-sample 3rd Party APIs – Backend Auth via Credential Manager: Blog Post: https://aka.ms/remote-mcp-apim-lab-blog APIM lab: https://aka.ms/ai-gateway-lab-mcp YouTube Video: https://aka.ms/ai-gateway-lab-demo25KViews12likes4CommentsLoop governance, lifecycle, manageability for IT Admins – Nov 2024
Dive into our latest update on Loop governance, lifecycle, and manageability tailored just IT admins! Discover how Loop's seamless integration with Microsoft 365 can transform your team's productivity with real-time co-authoring, versatile components, and enhanced security features. From Copilot Pages to comprehensive manageability roadmap items, this blog has everything you need to confidently pilot and fully enable Loop in your organization. 20KViews12likes21Comments
Supporting ChatGPT on PostgreSQL in Azure
Affan Dar, Vice President of Engineering, PostgreSQL at Microsoft Adam Prout, Partner Architect, PostgreSQL at Microsoft Panagiotis Antonopoulos, Distinguished Engineer, PostgreSQL at Microsoft The OpenAI engineering team recently published a blog post describing how they scaled their databases by 10x over the past year, to support 800 million monthly users. To do so, OpenAI relied on Azure Database for PostgreSQL to support important services like ChatGPT and the Developer API. Collaborating with a customer experiencing rapid user growth has been a remarkable journey. One key observation is that PostgreSQL works out of box for very large-scale points. As many in the public domain have noted, ChatGPT grew to 800M+ users before OpenAI started moving new and shardable workloads to Azure Cosmos DB. Nevertheless, supporting the growth of one of the largest Postgres deployments was a great learning experience for both of our teams. Our OpenAI friends did an incredible job at reacting fast and adjusting their systems to handle the growth. Similarly, the Postgres team at Azure worked to further tune the service to support the increasing OpenAI workload. The changes we made were not limited to OpenAI, hence all our Azure Database for PostgreSQL customers with demanding workloads have benefited. A few of the enhancements and the work that led to these are listed below. Changing the network congestion protocol to reduce replication lag Azure Database for PostgreSQL used the default CUBIC congestion control algorithm for replication traffic to replicas both within and outside the region. Leading up to one of the OpenAI launch events, we observed that several geo-distributed read replicas occasionally experienced replication lag. Replication from the primary server to the read replicas would typically operate without issues; however, at times, the replicas would unexpectedly begin falling behind the primary for reasons that were not immediately clear. This lag would not recover on its own and would grow to a point when, eventually, automation would restart the read replica. Once restarted, the read replica would once again catch up, only to repeat this cycle again within a day or less. After an extensive debugging effort, we traced the root cause to how the TCP congestion control algorithm handled a higher rate of packet drops. These drops were largely a result of high point-to-point traffic between the primary server and its replicas, compounded by the existing TCP window settings. Packet drops across regions are not unexpected; however, the default congestion control algorithm (CUBIC) treats packet loss as a sign of congestion and does an aggressive backoff. In comparison, the Bottleneck Bandwidth and Round-trip propagation time (BBR) congestion control algorithm is less sensitive to packet drops. Switching to BBR, adding SKU specific TCP window settings, and switching to fair queuing network discipline (which can control pacing of outgoing packets at hardware level) resolved this issue. We’ll also note that one of our seasoned PostgreSQL committers provided invaluable insights during this process, helping us pinpoint the issue more effectively. Scaling out with Read replicas PostgreSQL primaries, if configured properly, work amazingly well in supporting a large number of read replicas. In fact, as noted in the OpenAI engineering blog, a single primary has been able to power around 50+ replicas across multiple regions. However, going beyond this increases the chance of impacting the primary. For this reason, we added the cascading replica support to scale out reads even further. But this brings in a number of additional failure modes that need to be handled. The system must carefully orchestrate repairs around lagging and failing intermediary nodes, safely repointing replicas to new intermediary nodes while performing catch up or rewind in a mission critical setup. Furthermore, disaster recovery (DR) scenarios can require a fast rebuild of a replica and as data movement across regions is a costly and time-consuming operation, we developed the ability to create a geo replica from a snapshot of another replica in the same region. This feature avoids the traditional full data copy process, which may take hours or even days depending on the size of the data, by leveraging data for that cluster that already exists in that region. This feature will soon be available for all our customers as well. Scaling out Writes These improvements solved the read replica lag problems and read scale but did not help address the growing write scale for OpenAI. At some point, the balance tipped and it was obvious that the IOPs limits of a single PostgreSQL primary instance will not cut it anymore. As a result OpenAI decided to move new and shardable workloads to Azure Azure Cosmos DB, which is our default recommended NoSQL store for fully elastic workloads. However, some workloads, as noted in the OpenAI blog are much harder to shard. While OpenAI is using Azure Database for PostgreSQL flexible server, several of the write scaling requirements that came up have been baked into our new Azure HorizonDB offering, which entered private preview in November 2025. Some of the architectural innovations are described in the following sections. Azure HorizonDB scalability design To better support more demanding workloads, Azure HorizonDB introduces a new storage layer for Postgres that delivers significant performance and reliability enhancements: More efficient read scale out. Postgres read replicas no longer need to maintain their own copy of the data. They can read pages from the single copy maintained by the storage layer. Lower latency Write-Ahead Logging (WAL) writes and higher throughput page reads via two purpose-built storage services designed for WAL storage and Page storage. Durability and high availability responsibilities are shifted from the Postgres primary to the storage layer, allowing Postgres to dedicate more resources to executing transactions and queries. Postgres failovers are faster and more reliable. To understand how Azure HorizonDB delivers these capabilities, let’s look at its high‑level architecture as shown in Figure 1. It follows a log-centric storage model, where the PostgreSQL writeahead log (WAL) is the sole mechanism used to durably persist changes to storage. PostgreSQL compute nodes never write data pages to storage directly in Azure HorizonDB. Instead, pages and other on-disk structures are treated as derived state and are reconstructed and updated from WAL records by the data storage fleet. Azure HorizonDB storage uses two separate storage services for WAL and data pages. This separation allows each to be designed and optimized for the very different patterns of reads and writes PostgreSQL does against WAL files in contrast to data pages. The WAL server is optimized for very low latency writes to the tail of a sequential WAL stream and the Page server is designed for random reads and writes across potentially many terabytes of pages. These two separate services work together to enable Postgres to handle IO intensive OLTP workloads like OpenAI’s. The WAL server can durably write a transaction across 3 availability zones using a single network hop. The typical PostgreSQL replication setup with a hot standby (Figure 2) requires 4 hops to do the same work. Each hop is a component that can potentially fail or slow down and delay a commit. Azure HorizonDB page service can scale out page reads to many hundreds of thousands of IOPs for each Postgres instance. It does this by sharding the data in Postgres data files across a fleet of page servers. This spreads the reads across many high performance NVMe disks on each page server. 2 - WAL Writes in HorizonDB Another key design principle for Azure HorizonDB was to move durability and high availability related work off PostgreSQL compute allowing it to operate as a stateless compute engine for queries and transactions. This approach gives Postgres more CPU, disk and network to run your application’s business logic. Table 1 summarizes the different tasks that community PostgreSQL has to do, which Azure HorizonDB moves to its storage layer. Work like dirty page writing and checkpointing are no longer done by a Postgres primary. The work for sending WAL files to read replicas is also moved off the primary and into the storage layer – having many read replicas puts no load on the Postgres primary in Azure HorizonDB. Backups are handled by Azure Storage via snapshots, Postgres isn’t involved. Task Resource Savings Postgres Process Moved WAL sending to Postgres replicas Disk IO, Network IO Walsender WAL archiving to blob storage Disk IO, Network IO Archiver WAL filtering CPU, Network IO Shared Storage Specific (*) Dirty Page Writing Disk IO background writer Checkpointing Disk IO checkpointer PostgreSQL WAL recovery Disk IO, CPU startup recovering PostgreSQL read replica redo Disk IO, CPU startup recovering PostgreSQL read replica shared storage Disk IO background, checkpointer Backups Disk IO pg_dump, pg_basebackup, pg_backup_start, pg_backup_stop Full page writes Disk IO Backends doing WAL writing Hot standby feedback Vacuum accuracy walreceiver Table 1 - Summary of work that the Azure HorizonDB storage layer takes over from PostgreSQL The shared storage architecture of Azure HorizonDB is the fundamental building block for delivering exceptional read scalability and elasticity which are critical for many workloads. Users can spin up read replicas instantly without requiring any data copies. Page Servers are able to scale and serve requests from all replicas without any additional storage costs. Since WAL replication is entirely handled by the storage service, the primary’s performance is not impacted as the number of replicas changes. Each read replica can scale independently to serve different workloads, allowing for workload isolation. Finally, this architecture allows Azure HorizonDB to substantially improve the overall experience around high availability (HA). HA replicas can now be added without any data copying or storage costs. Since the data is shared between the replicas and continuously updated by Page Servers, secondary replicas only replay a portion of the WAL and can easily keep up with the primary, reducing failover times. The shared storage also guarantees that there is a single source of truth and the old primary never diverges after a failover. This prevents the need for expensive reconciliation, using pg_rewind, or other techniques and further improves availability. Azure HorizonDB was designed from the ground up with learnings from large scale customers, to meet the requirements of the most demanding workloads. The improved performance, scalability and availability of the Azure HorizonDB architecture make Azure a great destination for Postgres workloads.5.1KViews11likes0CommentsAsk Microsoft Anything: Why Cybersecurity Needs a New Security Stack for the AI Era with David Weston
David Weston leads Agentic Security at Microsoft, where he and his team build the AI models, autonomous agents, and evaluation systems redefining how defenders operate. At Microsoft since the Windows 7 era, he has worked across exploit mitigation design, malware analysis, APT research, and led security engineering for Windows, Xbox, Azure OS, and Microsoft's Offensive Security Research & Engineering group. His current work is leading teams training frontier security models, agentic security systems for defenders, and pushing AI-driven vulnerability discovery through Microsoft's Multi-Model Agentic Scanning Harness (MDASH). A longtime member of the research community and former CISA technical advisor, David is a regular presenter at BlueHat, Black Hat, and DEF CON. Key areas Dave and his team can discuss: The vision behind Project Perception How AI is changing the economics of cyber offense and defense Lessons learned from building MDASH and Microsoft's AI security initiatives Security-first AI development and deployment What's next for defenders as agentic systems become mainstream This will be a TEXT-BASED AMA, so ask your questions in the comment section down below and David and team will be answering via comment replies during the live hour!4.7KViews9likes16Comments
Making Sense of Azure AI Foundry IQ
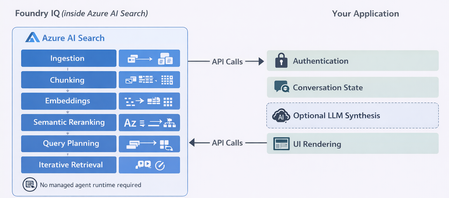
As enterprise teams build AI agents, the hardest design decisions often have nothing to do with models. Instead, they revolve around a more fundamental question: How should an agent access organizational knowledge in a way that is accurate, secure, and sustainable over time? Azure AI Foundry IQ is designed to address a specific version of that problem. It is not a general‑purpose data access layer, and it is not a replacement for every retrieval pattern. Understanding where it fits and where it does not is key to using it effectively. This post explores those boundaries and grounds them in concrete, enterprise‑relevant scenarios, before showing how Foundry IQ can be implemented directly via Azure AI Search APIs and SDKs. What Azure AI Foundry IQ Is (and Is Not): Azure AI Foundry IQ is a managed knowledge layer built on Azure AI Search. It allows you to define a knowledge base that spans multiple content sources such as SharePoint, Azure Blob Storage, OneLake, existing Azure AI Search indexes, and selected external sources and expose them through a single, permission‑aware endpoint. When an agent queries a knowledge base, Foundry IQ: Plans how the query should be executed Selects relevant knowledge sources Runs retrieval (optionally in multiple steps) Enforces user permissions Returns grounded results with citations A single knowledge base can be reused across multiple agents or applications, avoiding duplicated indexing and inconsistent retrieval logic. What Foundry IQ is not: It does not execute SQL queries, perform aggregations, or provide real‑time numeric accuracy. Foundry IQ retrieves unstructured text, not transactional or analytical data. Where Foundry IQ Is a Good Fit 1. Multi‑Source, Distributed Knowledge Foundry IQ is most valuable when relevant knowledge is spread across multiple systems. It removes the need for each agent to manage source‑specific routing and retrieval logic. This benefit increases as the number of sources grows; with a single source, the overhead is rarely justified. 2. Complex or Multi‑Part Questions Foundry IQ’s agentic retrieval model is designed for questions that require: Decomposition into sub‑questions Retrieval from multiple documents Synthesis across sources Its multi‑step retrieval approach is especially effective when a single document cannot answer the question on its own. 3. Reduced Custom Retrieval Engineering Foundry IQ automates indexing, chunking, vectorization, and orchestration across sources. This makes it a strong choice for teams that want to focus on agent behavior rather than building and maintaining custom RAG pipelines. 4. Enterprise Security and Governance Foundry IQ integrates with Microsoft Entra ID and supports document‑level permissions and Purview sensitivity labels where the underlying source allows it. This makes it suitable for internal or regulated scenarios where permission trimming is a hard requirement. 5. Shared Knowledge Across Multiple Agents A single knowledge base can serve multiple agents or applications, reducing operational overhead and ensuring consistent retrieval behavior across experiences. 6. High Emphasis on Answer Quality and Trust For scenarios where correctness, grounding, and citations matter more than latency or cost, Foundry IQ’s multi‑step retrieval consistently outperforms basic RAG approaches. Example Scenarios Where Foundry IQ Works Well Scenario A: Internal Policy and Operations Assistant An enterprise builds an internal assistant for store managers. Relevant information lives in: • HR policies in SharePoint • Safety procedures in Blob Storage • Operations manuals in OneLake Questions often span multiple documents. A single Foundry IQ knowledge base unifies these sources and enforces permissions automatically. Scenario B: Compliance or Regulatory Knowledge Assistant A compliance team needs answers strictly grounded in approved documents, with citations and access control. Foundry IQ ensures only authorized content is retrieved, reducing the risk of accidental data exposure. Scenario C: Shared Knowledge Layer for Multiple Internal Agents Multiple internal agents like chat assistants, workflow helpers, embedded copilots rely on the same procedural content. A shared knowledge base avoids duplicate indexing and centralizes governance. Where Foundry IQ Is Not a Good Fit 1. Simple or Single‑Source Q&A For a single, well‑defined source, Foundry IQ’s orchestration adds complexity without proportional benefit. 2. Structured or Analytical Data Queries Foundry IQ does not execute live queries or calculations. It retrieves text, not metrics. 3. Ultra‑Low Latency or High‑Throughput Requirements Agentic retrieval introduces LLM‑in‑the‑loop latency and token costs. For sub‑second responses at scale, simpler retrieval pipelines are more appropriate. 4. Highly Customized Retrieval Logic Foundry IQ abstracts the retrieval pipeline. If you require fine‑grained control over scoring or transformations, a fully custom search pipeline may be preferable. Example Scenarios Where Foundry IQ Is the Wrong Tool Scenario D: Sales and Inventory Analytics Agent Questions like “What were Q4 sales by region?” require live data queries. Indexing reports leads to stale answers. A direct SQL or analytics tool is the correct solution. Scenario E: High‑Volume, Low‑Latency Assistant Voice‑based assistants requiring sub‑second responses cannot tolerate the latency of agentic retrieval. A Common Architecture Pattern Most successful implementations combine: Foundry IQ for unstructured documents and policies Structured data tools for analytics and live queries An application or agent layer that routes questions based on intent This avoids forcing a single tool to solve every problem. Querying Foundry IQ Knowledge Bases Directly via Azure AI Search SDK You can query Azure AI Foundry IQ knowledge bases directly using the azure-search-documents Python SDK without using Foundry Agent Service. Your App → Azure AI Search SDK → Foundry IQ Knowledge Base → Grounded Results Ideal when you want full orchestration control while still benefiting from managed, agentic retrieval. How this works Note:It is a reference implementation Install pip install --pre azure-search-documents azure-identity Setup (High Level) Provision Azure AI Search (Basic or higher) Enable Azure AD and API key authentication Enable a system‑assigned managed identity Ingest Content via Knowledge Sources Blob Storage, SharePoint, or OneLake Index, indexer, data source, and skillset are created automatically Knowledge sources and KBs are created via REST API (2025‑11‑01‑preview) Create a Knowledge Base minimal reasoning → semantic retrieval only (no LLM) low / medium reasoning → requires Azure OpenAI model Search service MI needs Cognitive Services User Querying the Knowledge Base (Python) Initialize the Client from azure.identity import DefaultAzureCredential from azure.search.documents.knowledgebases import KnowledgeBaseRetrievalClient client = KnowledgeBaseRetrievalClient( endpoint="https://<search-service>.search.windows.net", knowledge_base_name="<kb-name>", credential=DefaultAzureCredential(), ) Minimal Reasoning (Fast, No LLM) from azure.search.documents.knowledgebases.models import ( KnowledgeBaseRetrievalRequest, KnowledgeRetrievalSemanticIntent, KnowledgeRetrievalMinimalReasoningEffort, KnowledgeRetrievalOutputMode, ) request = KnowledgeBaseRetrievalRequest( intents=[KnowledgeRetrievalSemanticIntent(search="your question here")], retrieval_reasoning_effort=KnowledgeRetrievalMinimalReasoningEffort(), output_mode=KnowledgeRetrievalOutputMode.EXTRACTIVE_DATA, ) response = client.retrieve(retrieval_request=request) Conversational Reasoning (LLM‑Backed) from azure.search.documents.knowledgebases.models import ( KnowledgeBaseRetrievalRequest, KnowledgeBaseMessage, KnowledgeBaseMessageTextContent, KnowledgeRetrievalLowReasoningEffort, KnowledgeRetrievalOutputMode, ) request = KnowledgeBaseRetrievalRequest( messages=[ KnowledgeBaseMessage( role="user", content=[KnowledgeBaseMessageTextContent(text="<first user question>")] ), KnowledgeBaseMessage( role="assistant", content=[KnowledgeBaseMessageTextContent(text="<assistant response>")] ), KnowledgeBaseMessage( role="user", content=[KnowledgeBaseMessageTextContent(text="<follow-up question>")] ), ], retrieval_reasoning_effort=KnowledgeRetrievalLowReasoningEffort(), output_mode=KnowledgeRetrievalOutputMode.EXTRACTIVE_DATA, ) response = client.retrieve(retrieval_request=request) Keep in mind: intents → minimal reasoning only messages → low / medium reasoning only They are not interchangeable. Processing the Response # Extracted content for msg in (response.response or []): for item in (msg.content or []): print(item.text) # Citations (handles blob, SharePoint, OneLake, and search index references) for ref in (response.references or []): ref_id = getattr(ref, "id", None) url = getattr(ref, "blob_url", None) or getattr(ref, "url", None) print(f"[{ref_id}] {url}") # Retrieval diagnostics for record in (response.activity or []): elapsed = getattr(record, "elapsed_ms", None) or "" print(f"{record.type}: {elapsed}ms") Output Modes Mode When to Use extractiveData Feed grounded chunks into your own LLM answerSynthesis Return a ready‑made answer with citations (LLM required) Security & Permissions RBAC: Search Index Data Reader with DefaultAzureCredential Permission trimming Must be enabled at ingestion (ingestionPermissionOptions) Enforced at query time by passing the user’s bearer token response = client.retrieve( retrieval_request=request, x_ms_query_source_authorization="Bearer <user-token>" ) Foundry IQ won't solve every retrieval problem. But when your agents need grounded, permission-aware answers from content scattered across SharePoint, Blob Storage, and OneLake, it handles the hard parts — so you can focus on what your agent actually does.Announcing Azure HorizonDB
Affan Dar, Vice President of Engineering, PostgreSQL at Microsoft Charles Feddersen, Partner Director of Program Management, PostgreSQL at Microsoft Today at Microsoft Ignite, we’re excited to unveil the preview of Azure HorizonDB, a fully managed Postgres-compatible database service designed to meet the needs of modern enterprise workloads. The cloud native architecture of Azure HorizonDB delivers highly scalable shared storage, elastic scale-out compute, and a tiered cache optimized for running cloud applications of any scale. Postgres is transforming industries worldwide and is emerging as the foundation of modern data solutions across all sectors at an unprecedented pace. For developers, it is the database of choice for building new applications with its rich set of extensions, open-source API, and expansive ecosystems of tools and libraries. At the same time, but at the opposite end of the workload spectrum, enterprises around the world are also increasingly turning to Postgres to modernize their existing applications. Azure HorizonDB is designed to support applications across the entire workload spectrum from the first line of code in a new app to the migration of large-scale, mission-critical solutions. Developers benefit from the robust Postgres ecosystem and seamless integration with Azure’s advanced AI capabilities, while enterprises can gain a secure, highly available, and performant cloud database to host their business applications. Whether you’re building from scratch or transforming legacy infrastructure, Azure HorizonDB empowers you to innovate and scale with confidence, today and into the future. Azure HorizonDB introduces new levels of performance and scalability to PostgreSQL. The scale-out compute architecture supports up to 3,072 vCores across primary and replica nodes, and the auto-scaling shared storage supports up to 128TB databases while providing sub-millisecond multi-zone commit latencies. This storage innovation enables Azure HorizonDB to deliver up to 3x more throughput when compared with open-source Postgres for transactional workloads. Azure HorizonDB is enterprise ready on day one. With native support for Entra ID, Private Endpoints, and data encryption, it provides compliance and security for sensitive data stored in the cloud. All data is replicated across availability zones by default and maintenance operations are transparent with near-zero downtime. Backups are fully automated, and integration with Azure Defender for Cloud provides additional protection for highly sensitive data. All up, Azure HorizonDB offers enterprise-grade security, compliance, and reliability, making it ready for business use today. Since the launch of ChatGPT, there has been an explosion of new AI apps being built, and Postgres has become the database of choice due in large part to its vector index support. Azure HorizonDB extends the AI capabilities of Postgres further with two key features. We are introducing advanced filtering capabilities to the DiskANN vector index which enable query predicate pushdowns directly into the vector similarity search. This provides significant performance and scalability improvements over pgvector HNSW while maintaining accuracy and is ideal for similarity search over transactional data in Postgres. The second feature is built-in AI model management that seamlessly integrates generative, embedding, and reranking models from Microsoft Foundry for developers to use in the database with zero configuration. In addition to enhanced vector indexing and simplified model management to build powerful new AI apps, we’re also pleased to announce the general availability of Microsoft’s PostgreSQL Extension for VS Code that provides the tooling for Postgres developers to maximize their productivity. Using this extension, GitHub Copilot is context aware of the Postgres database which means less prompting and higher quality answers, and in the Ignite release, we’ve added live monitoring with one-click GitHub Copilot debugging where Agent mode can launch directly from the performance monitoring dashboard to diagnose Postgres performance issues and guide users to a fix. Alpha Life Sciences are an existing Azure customers “I’m truly excited about how Azure HorizonDB empowers our AI development. Its seamless support for Vector DB, RAG, and Agentic AI allows us to build intelligent features directly on a reliable Postgres foundation. With Azure HorizonDB, I can focus on advancing AI capabilities instead of managing infrastructure complexities. It’s a smart, forward-looking solution that perfectly aligns with how we design and deliver AI-powered applications.” Pengcheng Xu, CTO Alpha Life Sciences For enterprises that are modernizing their applications to Postgres in the cloud, the security and availability of Azure HorizonDB make it an ideal platform. However, these migrations are often complex and time consuming for large legacy codebase conversions. To simplify this and reduce the risk, we’re pleased to announce the preview of GitHub Copilot powered Oracle migration built into the PostgreSQL Extension for VS Code. Built into VS Code, teams of engineers can work with GitHub Copilot to automate the end-to-end conversion of complex database code using rich code editing, version control, text authoring, and deployment in an integrated development environment. Azure HorizonDB is the next generation of fully managed, cloud native PostgreSQL database service. Built on the latest Azure infrastructure with state-of-the-art cloud architecture, Azure HorizonDB is ready to for the most demanding application workloads. In addition to our portfolio of managed Postgres services in Azure, Microsoft is deeply invested into the open source Postgres project and is one of the top corporate upstream contributors and sponsors for the PostgreSQL project, with 19 Postgres project contributors employed by Microsoft. As a hyperscale Postgres vendor, it’s critical to actively participate in the open-source project. It enables us to better support our customers down to the metal in Azure, and to contribute our learnings from running Postgres at scale back to the community. We’re committed to continuing our investment to push the Postgres project forward, and the team is already active in making contributions to Postgres 19 to be released in 2026. Ready to explore Azure HorizonDB? Azure HorizonDB is initially available in Central US, West US3, UK South and Australia East regions. Customers are invited to apply for early preview access to Azure HorizonDB and get hands-on experience with this new service. Participation is limited, apply now at aka.ms/PreviewHorizonDB