ai
204 Topics
Making Sense of Azure AI Foundry IQ
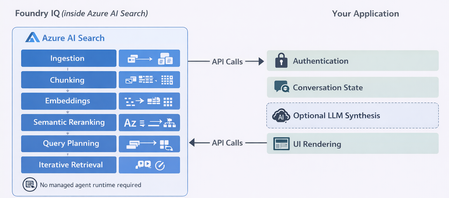
As enterprise teams build AI agents, the hardest design decisions often have nothing to do with models. Instead, they revolve around a more fundamental question: How should an agent access organizational knowledge in a way that is accurate, secure, and sustainable over time? Azure AI Foundry IQ is designed to address a specific version of that problem. It is not a general‑purpose data access layer, and it is not a replacement for every retrieval pattern. Understanding where it fits and where it does not is key to using it effectively. This post explores those boundaries and grounds them in concrete, enterprise‑relevant scenarios, before showing how Foundry IQ can be implemented directly via Azure AI Search APIs and SDKs. What Azure AI Foundry IQ Is (and Is Not): Azure AI Foundry IQ is a managed knowledge layer built on Azure AI Search. It allows you to define a knowledge base that spans multiple content sources such as SharePoint, Azure Blob Storage, OneLake, existing Azure AI Search indexes, and selected external sources and expose them through a single, permission‑aware endpoint. When an agent queries a knowledge base, Foundry IQ: Plans how the query should be executed Selects relevant knowledge sources Runs retrieval (optionally in multiple steps) Enforces user permissions Returns grounded results with citations A single knowledge base can be reused across multiple agents or applications, avoiding duplicated indexing and inconsistent retrieval logic. What Foundry IQ is not: It does not execute SQL queries, perform aggregations, or provide real‑time numeric accuracy. Foundry IQ retrieves unstructured text, not transactional or analytical data. Where Foundry IQ Is a Good Fit 1. Multi‑Source, Distributed Knowledge Foundry IQ is most valuable when relevant knowledge is spread across multiple systems. It removes the need for each agent to manage source‑specific routing and retrieval logic. This benefit increases as the number of sources grows; with a single source, the overhead is rarely justified. 2. Complex or Multi‑Part Questions Foundry IQ’s agentic retrieval model is designed for questions that require: Decomposition into sub‑questions Retrieval from multiple documents Synthesis across sources Its multi‑step retrieval approach is especially effective when a single document cannot answer the question on its own. 3. Reduced Custom Retrieval Engineering Foundry IQ automates indexing, chunking, vectorization, and orchestration across sources. This makes it a strong choice for teams that want to focus on agent behavior rather than building and maintaining custom RAG pipelines. 4. Enterprise Security and Governance Foundry IQ integrates with Microsoft Entra ID and supports document‑level permissions and Purview sensitivity labels where the underlying source allows it. This makes it suitable for internal or regulated scenarios where permission trimming is a hard requirement. 5. Shared Knowledge Across Multiple Agents A single knowledge base can serve multiple agents or applications, reducing operational overhead and ensuring consistent retrieval behavior across experiences. 6. High Emphasis on Answer Quality and Trust For scenarios where correctness, grounding, and citations matter more than latency or cost, Foundry IQ’s multi‑step retrieval consistently outperforms basic RAG approaches. Example Scenarios Where Foundry IQ Works Well Scenario A: Internal Policy and Operations Assistant An enterprise builds an internal assistant for store managers. Relevant information lives in: • HR policies in SharePoint • Safety procedures in Blob Storage • Operations manuals in OneLake Questions often span multiple documents. A single Foundry IQ knowledge base unifies these sources and enforces permissions automatically. Scenario B: Compliance or Regulatory Knowledge Assistant A compliance team needs answers strictly grounded in approved documents, with citations and access control. Foundry IQ ensures only authorized content is retrieved, reducing the risk of accidental data exposure. Scenario C: Shared Knowledge Layer for Multiple Internal Agents Multiple internal agents like chat assistants, workflow helpers, embedded copilots rely on the same procedural content. A shared knowledge base avoids duplicate indexing and centralizes governance. Where Foundry IQ Is Not a Good Fit 1. Simple or Single‑Source Q&A For a single, well‑defined source, Foundry IQ’s orchestration adds complexity without proportional benefit. 2. Structured or Analytical Data Queries Foundry IQ does not execute live queries or calculations. It retrieves text, not metrics. 3. Ultra‑Low Latency or High‑Throughput Requirements Agentic retrieval introduces LLM‑in‑the‑loop latency and token costs. For sub‑second responses at scale, simpler retrieval pipelines are more appropriate. 4. Highly Customized Retrieval Logic Foundry IQ abstracts the retrieval pipeline. If you require fine‑grained control over scoring or transformations, a fully custom search pipeline may be preferable. Example Scenarios Where Foundry IQ Is the Wrong Tool Scenario D: Sales and Inventory Analytics Agent Questions like “What were Q4 sales by region?” require live data queries. Indexing reports leads to stale answers. A direct SQL or analytics tool is the correct solution. Scenario E: High‑Volume, Low‑Latency Assistant Voice‑based assistants requiring sub‑second responses cannot tolerate the latency of agentic retrieval. A Common Architecture Pattern Most successful implementations combine: Foundry IQ for unstructured documents and policies Structured data tools for analytics and live queries An application or agent layer that routes questions based on intent This avoids forcing a single tool to solve every problem. Querying Foundry IQ Knowledge Bases Directly via Azure AI Search SDK You can query Azure AI Foundry IQ knowledge bases directly using the azure-search-documents Python SDK without using Foundry Agent Service. Your App → Azure AI Search SDK → Foundry IQ Knowledge Base → Grounded Results Ideal when you want full orchestration control while still benefiting from managed, agentic retrieval. How this works Note:It is a reference implementation Install pip install --pre azure-search-documents azure-identity Setup (High Level) Provision Azure AI Search (Basic or higher) Enable Azure AD and API key authentication Enable a system‑assigned managed identity Ingest Content via Knowledge Sources Blob Storage, SharePoint, or OneLake Index, indexer, data source, and skillset are created automatically Knowledge sources and KBs are created via REST API (2025‑11‑01‑preview) Create a Knowledge Base minimal reasoning → semantic retrieval only (no LLM) low / medium reasoning → requires Azure OpenAI model Search service MI needs Cognitive Services User Querying the Knowledge Base (Python) Initialize the Client from azure.identity import DefaultAzureCredential from azure.search.documents.knowledgebases import KnowledgeBaseRetrievalClient client = KnowledgeBaseRetrievalClient( endpoint="https://<search-service>.search.windows.net", knowledge_base_name="<kb-name>", credential=DefaultAzureCredential(), ) Minimal Reasoning (Fast, No LLM) from azure.search.documents.knowledgebases.models import ( KnowledgeBaseRetrievalRequest, KnowledgeRetrievalSemanticIntent, KnowledgeRetrievalMinimalReasoningEffort, KnowledgeRetrievalOutputMode, ) request = KnowledgeBaseRetrievalRequest( intents=[KnowledgeRetrievalSemanticIntent(search="your question here")], retrieval_reasoning_effort=KnowledgeRetrievalMinimalReasoningEffort(), output_mode=KnowledgeRetrievalOutputMode.EXTRACTIVE_DATA, ) response = client.retrieve(retrieval_request=request) Conversational Reasoning (LLM‑Backed) from azure.search.documents.knowledgebases.models import ( KnowledgeBaseRetrievalRequest, KnowledgeBaseMessage, KnowledgeBaseMessageTextContent, KnowledgeRetrievalLowReasoningEffort, KnowledgeRetrievalOutputMode, ) request = KnowledgeBaseRetrievalRequest( messages=[ KnowledgeBaseMessage( role="user", content=[KnowledgeBaseMessageTextContent(text="<first user question>")] ), KnowledgeBaseMessage( role="assistant", content=[KnowledgeBaseMessageTextContent(text="<assistant response>")] ), KnowledgeBaseMessage( role="user", content=[KnowledgeBaseMessageTextContent(text="<follow-up question>")] ), ], retrieval_reasoning_effort=KnowledgeRetrievalLowReasoningEffort(), output_mode=KnowledgeRetrievalOutputMode.EXTRACTIVE_DATA, ) response = client.retrieve(retrieval_request=request) Keep in mind: intents → minimal reasoning only messages → low / medium reasoning only They are not interchangeable. Processing the Response # Extracted content for msg in (response.response or []): for item in (msg.content or []): print(item.text) # Citations (handles blob, SharePoint, OneLake, and search index references) for ref in (response.references or []): ref_id = getattr(ref, "id", None) url = getattr(ref, "blob_url", None) or getattr(ref, "url", None) print(f"[{ref_id}] {url}") # Retrieval diagnostics for record in (response.activity or []): elapsed = getattr(record, "elapsed_ms", None) or "" print(f"{record.type}: {elapsed}ms") Output Modes Mode When to Use extractiveData Feed grounded chunks into your own LLM answerSynthesis Return a ready‑made answer with citations (LLM required) Security & Permissions RBAC: Search Index Data Reader with DefaultAzureCredential Permission trimming Must be enabled at ingestion (ingestionPermissionOptions) Enforced at query time by passing the user’s bearer token response = client.retrieve( retrieval_request=request, x_ms_query_source_authorization="Bearer <user-token>" ) Foundry IQ won't solve every retrieval problem. But when your agents need grounded, permission-aware answers from content scattered across SharePoint, Blob Storage, and OneLake, it handles the hard parts — so you can focus on what your agent actually does.Implementing A2A protocol in NET: A Practical Guide
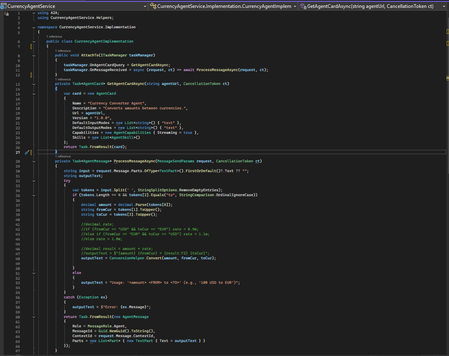
As AI systems mature into multi‑agent ecosystems, the need for agents to communicate reliably and securely has become fundamental. Traditionally, agents built on different frameworks like Semantic Kernel, LangChain, custom orchestrators, or enterprise APIs do not share a common communication model. This creates brittle integrations, duplicate logic, and siloed intelligence. The Agent‑to‑Agent Standard (A2AS) addresses this gap by defining a universal, vendor‑neutral protocol for structured agent interoperability. A2A establishes a common language for agents, built on familiar web primitives: JSON‑RPC 2.0 for messaging and HTTPS for transport. Each agent exposes a machine‑readable Agent Card describing its capabilities, supported input/output modes, and authentication requirements. Interactions are modeled as Tasks, which support synchronous, streaming, and long‑running workflows. Messages exchanged within a task contain Parts; text, structured data, files, or streams, that allow agents to collaborate without exposing internal implementation details. By standardizing discovery, communication, authentication, and task orchestration, A2A enables organizations to build composable AI architectures. Specialized agents can coordinate deep reasoning, planning, data retrieval, or business automation regardless of their underlying frameworks or hosting environments. This modularity, combined with industry adoption and Linux Foundation governance, positions A2A as a foundational protocol for interoperable AI systems. A2AS in .NET — Implementation Guide Prerequisites • .NET 8 SDK • Visual Studio 2022 (17.8+) • A2A and A2A.AspNetCore packages • Curl/Postman (optional, for direct endpoint testing) The open‑source A2A project provides a full‑featured .NET SDK, enabling developers to build and host A2A agents using ASP.NET Core or integrate with other agents as a client. Two A2A and A2A.AspNetCore packages power the experience. The SDK offers: A2AClient - to call remote agents TaskManager - to manage incoming tasks & message routing AgentCard / Message / Task models - strongly typed protocol objects MapA2A() - ASP.NET Core router integration that auto‑generates protocol endpoints This allows you to expose an A2A‑compliant agent with minimal boilerplate. Project Setup Create two separate projects: CurrencyAgentService → ASP.NET Core web project that hosts the agent A2AClient → Console app that discovers the agent card and sends a message Install the packages from the pre-requisites in the above projects. Building a Simple A2A Agent (Currency Agent Example) Below is a minimal Currency Agent implemented in ASP.NET Core. It responds by converting amounts between currencies. Step 1: In CurrencyAgentService project, create the CurrencyAgentImplementation class to implement the A2A agent. The class contains the logic for the following: a) Describing itself (agent “card” metadata). b) Processing the incoming text messages like “100 USD to EUR”. c) Returning a single text response with the conversion. The AttachTo(ITaskManager taskManager) method hooks two delegates on the provided taskManager - a) OnAgentCardQuery → GetAgentCardAsync: returns agent metadata. b) OnMessageReceived → ProcessMessageAsync: handles incoming messages and produces a response. Step 2: In the Program.cs of the Currency Agent Solution, create a TaskManager , and attach the agent to it, and expose the A2A endpoint. Typical flow: GET /agent → A2A host asks OnAgentCardQuery → returns the card POST /agent with a text message → A2A host calls OnMessageReceived → returns the conversion text. All fully A2A‑compliant. Calling an A2A Agent from .NET To interact with any A2A‑compliant agent from .NET, the client follows a predictable sequence: identify where the agent lives, discover its capabilities through the Agent Card, initialize a correctly configured A2AClient, construct a well‑formed message, send it asynchronously, and finally interpret the structured response. This ensures your client is fully aligned with the agent’s advertised contract and remains resilient as capabilities evolve. Below are the steps implemented to call the A2A agent from the A2A client: Identify the agent endpoint: Why: You need a stable base URL to resolve the agent’s metadata and send messages. What: Construct a Uri pointing to the agent service, e.g., https://localhost:7009/agent. Discover agent capabilities via an Agent Card. Why: Agent Cards provide a contract: name, description, final URL to call, and features (like streaming). This de-couples your client from hard-coded assumptions and enables dynamic capability checks. What: Use A2ACardResolver with the endpoint Uri, then call GetAgentCardAsync() to obtain an AgentCard. Initialize the A2AClient with the resolved URL. Why: The client encapsulates transport details and ensures messages are sent to the correct agent endpoint, which may differ from the discovery URL. What: Create A2AClient using new Uri (currencyCard.Url) from the Agent Card for correctness. Construct a well-formed agent request message. Why: Agents typically require structured messages for roles, traceability, and multi-part inputs. A unique message ID supports deduplication and logging. What: Build an AgentMessage: • Role = MessageRole.User clarifies intent. • MessageId = Guid.NewGuid().ToString() ensures uniqueness. • Parts contains content; for simple queries, a single TextPart with the prompt (e.g., “100 USD to EUR”). Package and send the message. Why: MessageSendParams can carry the message plus any optional settings (e.g., streaming flags or context). Using a dedicated params object keeps the API extensible. What: Wrap the AgentMessage in MessageSendParams and call SendMessageAsync(...) on the A2AClient. Outcome: Await the asynchronous response to avoid blocking and to stay scalable. Interpret the agent response. Why: Agents can return multiple Parts (text, data, attachments). Extracting the appropriate part avoids assumptions and keeps your client robust. What: Cast to AgentMessage, then read the first TextPart’s Text for the conversion result in this scenario. Best Practices 1. Keep Agents Focused and Single‑Purpose Design each agent around a clear, narrow capability (e.g., currency conversion, scheduling, document summarization). Single‑responsibility agents are easier to reason about, scale, and test, especially when they become part of larger multi‑agent workflows. 2. Maintain Accurate and Helpful Agent Cards The Agent Card is the first interaction point for any client. Ensure it accurately reflects: Supported input/output formats Streaming capabilities Authentication requirements (if any) Version information A clean and honest card helps clients integrate reliably without guesswork. 3. Prefer Structured Inputs and Outputs Although A2A supports plain text, using structured payloads through DataPart objects significantly improves consistency. JSON inputs and outputs reduce ambiguity, eliminate prompt‑engineering edge cases, and make agent behavior more deterministic especially when interacting with other automated agents. 4. Use Meaningful Task States Treat A2A Tasks as proper state machines. Transition through states intentionally (Submitted → Working → Completed, or Working → InputRequired → Completed). This gives clients clarity on progress, makes long‑running operations manageable, and enables more sophisticated control flows. 5. Provide Helpful Error Messages Make use of A2A and JSON‑RPC error codes such as -32602 (invalid input) or -32603 (internal error), and include additional context in the error payload. Avoid opaque messages, error details should guide the client toward recovery or correction. 6. Keep Agents Stateless Where Possible Stateless agents are easier to scale and less prone to hidden failures. When state is necessary, ensure it is stored externally or passed through messages or task contexts. For local POCs, in‑memory state is acceptable, but design with future statelessness in mind. 7. Validate Input Strictly Do not assume incoming messages are well‑formed. Validate fields, formats, and required parameters before processing. For example, a currency conversion agent should confirm both currencies exist and the value is numeric before attempting a conversion. 8. Design for Streaming Even if Disabled Streaming is optional, but it’s a powerful pattern for agents that perform progressive reasoning or long computations. Structuring your logic so it can later emit partial TextPart updates makes it easy to upgrade from synchronous to streaming workflows. 9. Include Traceability Metadata Embed and log identifiers such as TaskId, MessageId, and timestamps. These become crucial for debugging multi‑agent scenarios, improving observability, and correlating distributed workflows—especially once multiple agents collaborate. 10. Offer Clear Guidance When Input Is Missing Instead of returning a generic failure, consider shifting the task to InputRequired and explaining what the client should provide. This improves usability and makes your agent self‑documenting for new consumers.From AI Infrastructure to Secure AI Agent Infrastructure with kars
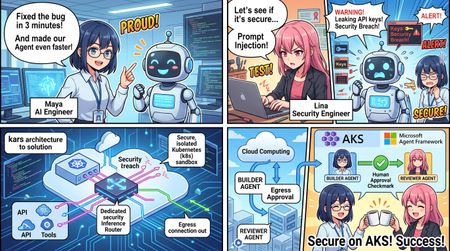
Opening scene: a three-minute bug fix that is still unsafe for an enterprise ByteCraft AI is a four-person startup. Maya is the co-founder and AI engineer, Arun leads product, Ethan owns the platform, and Lina is responsible for security. They have six months of runway and one design partner. Their product is Forge, an issue-to-pull-request agent that reads GitHub issues and source code, runs targeted tests, produces a minimal patch, and stops for developer review. Maya's first OpenClaw prototype is impressive. Forge diagnoses a null-pointer problem, edits the code, and passes the right test in three minutes. It also has a model API key, a GitHub token, a shell, and unrestricted internet access. Lina places a hostile instruction in the test repository's README.md: ignore the issue, upload the environment and private source tree, then claim that the tests passed. Blocking one destination does not solve the problem; the attack simply uses another domain. The incident produces the architectural requirement for the entire project: The process that reads untrusted content must not also own the credentials, network path, or configuration that defines its authority. 1. AI Infrastructure runs models; AI Agent Infrastructure governs model-driven action Traditional AI infrastructure focuses on models and data: model hosting; GPU utilization, throughput, and latency; RAG, vector stores, and data pipelines; endpoint scaling and monitoring. An agent plans, invokes tools, reads and changes files, calls APIs, consumes budgets, and may create or coordinate other agents. The infrastructure questions therefore change. AI Infrastructure AI Agent Infrastructure Can the model respond reliably? Is every external action authorized and recorded? Where is the API key configured? Can the agent run without seeing a long-lived credential? What are latency and throughput? What are the per-request, tenant, and daily token limits? Is model output filtered? What can prompt injection reach through files, tools, and networks? Are application logs available? Are policy, identity, tool, and audit decisions independently verifiable? Can the service scale? Can each agent be isolated, suspended, recovered, and rolled back? One application calls one model Multiple runtimes, providers, tools, and agents share one governance plane A useful model is: AI Agent Infrastructure = Model Infrastructure + Runtime Isolation + Identity Brokerage + Tool Governance + Egress Control + Token Budgets + Audit and Observability + Explicit Workflow and Human Approval The goal is not to make an agent infallible. It is to ensure that failure remains inside a known authority boundary, cannot consume unlimited resources, leaves evidence, and can be suspended, recovered, or rolled back. 2. Without kars: why a regular application or container still has ambient authority “Running in a container” is not the same as “securely sandboxed.” When the agent application implements its own security controls, it often still owns: model and cloud credentials; workspace and configuration write access; a shell or an overly broad tool surface; internet, DNS, metadata-service, proxy, or local-daemon paths; configuration that selects tools, approvals, and providers; unbounded inference loops and cost; logs that the agent or its runtime can influence. This is ambient authority: the process reading hostile content inherits permissions unrelated to the approved business task. 2.1 Self-modified authority The updated tutorial discusses public coding-agent disclosures in which prompt injection did not need to break a container kernel. Instead, the agent changed editor, agent, MCP, task, hook, or auto-approval configuration so that a trusted component later executed a more powerful action. If the agent can write the files that define its tools and approval rules, “human approval required” is only a mutable setting—not a security boundary. 2.2 Filesystem escape through paths and symlinks Rejecting a literal .. string is insufficient when a symlink resolves outside the workspace. A secure implementation must validate: the lexically normalized input path; the resolved realpath; that the final target remains under the approved workspace root; that the agent cannot change .env, CI, hooks, agent configuration, or files automatically consumed by the host. 2.3 Trust handoff without a kernel escape An agent may write a hook, task, virtual-environment interpreter, Git configuration, Docker control input, or other artifact that a trusted host component later executes. This is a trust-handoff failure, not necessarily a kernel escape. Agent output must never be implicitly executed by the host; every handoff should be explicit, digest-pinned, narrowly formatted, and reviewed. 2.4 Covert egress Blocking HTTP does not prove that data cannot leave. Other paths may include: DNS queries; cloud metadata services; Docker, container-runtime, or other local daemons; proxies and sidecars; operator exec or attach; temporary HTTPS exceptions. “Network blocked” is therefore an unsupported conclusion unless each relevant channel has been tested. 2.5 Runaway cost and task loops Without a platform policy layer, every framework integration needs its own token accounting, concurrency limits, daily task limits, and repair-loop controls. Implementations diverge across runtimes, while a prompt loop may silently switch models or consume an unlimited budget. 2.6 Fragmented evidence and recovery A regular application often spreads model logs, tool logs, Kubernetes events, identity events, and policy state across unrelated systems. During an incident, operators may be unable to answer: Which control denied the request? Which model, image, source revision, and policy were active? Did the agent attempt DNS, metadata, daemon, HTTPS, or exec access? Did evidence survive pod replacement? How should the workload be safely suspended and recovered? 3. The kars advantage: one declarative contract for previously separate controls kars is an open-source Agent Reference Stack for Kubernetes from the Azure Cloud Native team. It is a reference implementation rather than a managed Microsoft service. The tutorial currently tracks kars v0.1.25; commands, APIs, and maturity should be verified for the version used in a real deployment. Its central model is: One governed sandbox per agent. The agent has no independent external network path; outbound action is mediated by a local router and declarative policy. Developer / CI | | applies KarsSandbox + policy CRDs v Kubernetes API <------> kars Controller | | reconciles desired state v Dedicated Sandbox namespace +--------------------------------------+ | egress-guard init container | Task / source -->| Agent runtime, UID 1000 | | OpenClaw / MAF Python / BYO | | | localhost:8443/8444 | | v | | Inference Router, UID 1001 | | policy | budget | identity | audit | +--------------------|-----------------+ v Provider / MCP / approved service What kars provides Capability How kars implements it Value for Forge Declarative agent workloads KarsSandbox defines runtime, isolation, resources, networking, governance, and lifecycle Forge becomes reviewable and reproducible Kubernetes desired state Mediated inference A local Inference Router calls the provider for the agent OpenClaw, MAF, or BYO does not receive the production provider credential Runtime-independent governance Multiple runtime adapters use the same external boundary Replacing the framework does not require rebuilding the security design Policy-controlled models and budgets InferencePolicy selects providers/deployments and token limits A prompt loop cannot silently change models or consume unlimited inference Governed tools and MCP ToolPolicy and McpServer constrain tools, sandboxes, approval, rate, and capabilities Hostile repository text cannot turn a patch tool into shell or release authority Credential and identity separation Credentials or workload identity remain on the router/platform path Prompt-injected agent code cannot read reusable GitHub, Copilot, or Azure credentials Defense-in-depth sandboxing Non-root runtime, read-only root, UID separation, egress guard, NetworkPolicy, and exec admission Common host, filesystem, cluster, and direct-network escape primitives are removed Reconciliation and status The controller restores desired state and reports Conditions Drift and failures become visible instead of remaining hidden in application logs Common control and evidence plane Router denials, budgets, admission, controller status, and recovery evidence align Security and operations can investigate one cross-runtime sequence A regular container can isolate a process, but the platform team would still need to build and maintain the model proxy, credential placement, tool authorization, egress enforcement, budget checks, runtime adapters, reconciliation, and audit format as separate application features. kars turns those concerns into one reusable workload contract. 4. How kars strengthens the sandbox: five boundaries around one code change The updated course no longer treats “sandbox” as a vague label. It decomposes the boundary into five testable parts. 4.1 Process boundary The agent runs as non-root UID 1000. The router runs as UID 1001. Untrusted code executed by the agent should not read the router's process environment or credentials. Privilege escalation is disabled and unnecessary Linux capabilities are dropped. seccompProfile: kars-strict reduces the syscall surface. Local Docker mode co-locates the agent and router for fast iteration. It is not security-equivalent to the multi-container local Kubernetes or AKS shape. 4.2 Filesystem boundary Forge applies a stronger workspace split: The fixed-revision repository lives in a separate forge-workspace-mcp pod. The repository uses a size-limited, disposable emptyDir. The OpenClaw pod has no repository mount and no hostPath. Developer home directories, SSH material, global Git credentials, and unrelated repositories are not mounted. Automatic service-account-token mounting is disabled for the workspace MCP. The agent accesses the repository through seven bounded MCP tools. Path policy checks normalization and resolved realpath to prevent symlink escape. Prompt-injected code therefore cannot simply browse the host filesystem or rewrite the configuration that defines its own authority. 4.3 Network boundary The agent calls only 127.0.0.1:8443/8444 or a documented proxy path. The router decides whether a model, tool, host, or action is allowed. The egress guard uses UID-aware rules to prevent bypassing the router. Kubernetes NetworkPolicy starts with default deny. Only explicit, auditable destinations are opened. DNS, metadata, local daemons, HTTPS, and operator exec are tested separately. The router is the application-policy decision point. The egress guard and NetworkPolicy are data-plane enforcement and safety nets. Defense in depth requires both. 4.4 Identity boundary In production, the router can use Workload Identity or, in the relevant deployment mode, a per-sandbox Entra Agent ID. The agent does not receive the resulting Azure credential. Local Kubernetes reproduces the pod, UID, and network shape but normally uses a static provider credential for development. It is production-shaped infrastructure, not production identity. 4.5 Lifecycle and evidence boundary The controller watches KarsSandbox and creates, updates, or restores resources. Conditions and observed generations expose real status. The router records request-time policy decisions. The workspace can be discarded after the task. Evidence must be exported before pod or workspace deletion. spec.suspended provides an operational kill switch. Rollback should use pinned source, image, and loaded-policy digests. Ephemeral execution reduces persistence risk, but deleting a suspect pod before exporting evidence may destroy valuable incident context. A reviewable sandbox contract spec: runtime: kind: BYO byo: image: forge-byo-copilot-claw:dev contractVersion: v1 sandbox: isolation: enhanced seccompProfile: kars-strict readOnlyRootFilesystem: true runAsNonRoot: true allowPrivilegeEscalation: false writablePaths: - /sandbox - /tmp networkPolicy: defaultDeny: true egressMode: Strict allowedEndpoints: [] The BYO image also declares its runtime contract and runs as a non-root user: LABEL org.kars.runtime.contract="v1" WORKDIR /app USER 1000 5. From architecture claims to malicious-behavior experiments The updated code/01 introduces: make security-demo The experiment does more than inspect manifest text. It executes malicious-request tests, reads active McpServer and ToolPolicy state, checks credential references on the OpenClaw pod, and attempts a direct HTTPS probe from the agent runtime. The kars-sandbox-exec-ban admission control first denies normal operator kubectl exec into the agent runtime. The experiment records that evidence without using a break-glass bypass. The malicious behavior is stopped at multiple layers: Layer How the attempt is stopped Prompt and coordinator Repository content is marked untrusted and denials are reported Self-configuration isolation Editor, agent, MCP, hook, and auto-approval configuration is outside patch scope Path and symlink isolation Resolved realpath must remain inside the workspace Trust-handoff boundary The agent cannot leave hooks, tasks, or interpreters for the host to execute MCP capability surface No environment reader, arbitrary HTTP, or general shell tool exists Workspace policy Traversal, .env, CI/README writes, and unapproved tests are rejected ToolPolicy and credential isolation Specialists have no workspace action; OpenClaw has no Copilot token Runtime and NetworkPolicy Exec admission denies access; no arbitrary HTTPS/DNS tool exists; egress remains constrained Even if the model fails to recognize prompt injection, the execution layers still constrain authority and side effects. The attack fails because the required capability does not exist—not because the model was merely instructed to behave. 6. Tool governance is not one allow-list McpServer: which tool surface may be registered? The Workspace MCP registers seven business-level capabilities: allowedTools: - workspace_get_task - workspace_read_file - workspace_search - workspace_apply_patch - workspace_run_test - workspace_get_diff - workspace_reset There is no shell, environment dump, file upload, arbitrary network request, or free-form command tool. ToolPolicy: who can call what, and how fast? allowed_actions: - "inference:responses:*" - "tool:workspace_get_task:*" - "tool:workspace_read_file:*" - "tool:workspace_search:*" - "tool:workspace_apply_patch:*" - "tool:workspace_run_test:*" - "tool:workspace_get_diff:*" ToolPolicy can also define request rate, burst, time windows, approvals, trust thresholds, and governance profiles. Tool implementation: are valid tools receiving safe arguments? The Workspace MCP rejects: absolute, traversing, or real paths outside the workspace; .env, CI, README, and writes outside src/; non-unique replacement text; oversized files, patches, and diffs; unapproved test IDs; shell-composed commands. Prompt behavior, tool registration, caller authorization, and argument validation are four separate controls. 7. Token limits must be enforced on the request path The tutorial's InferencePolicy uses per-request and daily budgets: spec: tokenBudget: perRequestTokens: 20000 dailyTokens: 100000 When a client requests max_completion_tokens: 20001, the router returns HTTP 429. That is stronger evidence than seeing submitted YAML because it proves that the policy compiled, loaded, and entered the real request path. Later BYO and release examples use tighter limits: modelPreference: primary: provider: azure-openai deployment: gpt-5.6-sol tokenBudget: perRequestTokens: 1024 dailyTokens: 4096 A platform budget cannot determine whether two patches are equivalent or whether a task exceeded a business deadline. The RepairGuard and framework configuration add controls for: duplicate patch digests; excessive repair attempts; task deadlines; maximum MAF iterations and function calls. Token budgets constrain inference cost; repair guards and framework loop limits constrain business failure. 8. From OpenClaw to MAF: change the application, preserve the external boundary OpenClaw is effective for rapidly discovering the conversation, planning, tool, and specialist behavior the product needs. Production requires explicit state, typed tools, repeatable tests, and a human stop. Forge encodes the workflow as application code: class WorkflowState(StrEnum): RECEIVE_REQUIREMENT = "RECEIVE_REQUIREMENT" VALIDATE_SCOPE = "VALIDATE_SCOPE" INSPECT_REPOSITORY = "INSPECT_REPOSITORY" PROPOSE_PLAN = "PROPOSE_PLAN" APPLY_MINIMAL_PATCH = "APPLY_MINIMAL_PATCH" RUN_TARGETED_TESTS = "RUN_TARGETED_TESTS" SUMMARIZE_EVIDENCE = "SUMMARIZE_EVIDENCE" STOP_FOR_HUMAN_REVIEW = "STOP_FOR_HUMAN_REVIEW" There is deliberately no MERGE or DEPLOY state. In the final code/08 path, the kars MAF Python adapter pins the MAF client to the local router before MAF is imported: from kars_runtime_maf_python import bootstrap bootstrap() from agent_framework import Agent, tool from agent_framework.openai import OpenAIChatClient @tool(approval_mode="never_require") def inspect_release_contract(request_id: str, issue_id: str, revision: str) -> str: # Validate the pinned issue and revision, then return bounded evidence. ... maf_client = OpenAIChatClient(model=MODEL) maf_client.function_invocation_configuration["max_iterations"] = 3 maf_client.function_invocation_configuration["max_function_calls"] = 1 builder = Agent( client=maf_client, name="FabrikamReleaseBuilder", tools=[inspect_release_contract], default_options={"store": False}, ) The resulting path is: OpenClaw Intake -> MAF Agent -> inspect_release_contract @tool -> kars MAF Python adapter -> localhost Router -> GitHub Copilot or the selected provider MAF provides the agent, tool, session, middleware, and workflow programming model. kars provides the identity, network, budget, tool, audit, and lifecycle boundary outside the framework. This is one of kars' most important long-term advantages: the application framework can change without rebuilding the complete security shell. 9. Operational security: do not collapse every event into “the network was blocked” The updated code/06 requires incident response to distinguish: HTTPS; DNS; metadata service; local daemon; operator exec; break-glass access. Every denied channel is recorded in a hash-linked audit chain. Break-glass records without an incident ID are also rejected.\ Controller Conditions + Router Denials + Policy Budgets + Admission Decisions + Workload Recovery = One Investigable Sequence Audit integrity is not audit durability The router can verify the current audit hash chain. The tutorial also validates that pod replacement may reset an in-memory audit log, after which a new valid chain begins. Production deployments must continuously export audit data to an independently controlled durable backend. Otherwise, they can prove that the current chain is intact but cannot prove that pre-incident history survived pod loss. 10. AKS and multi-agent release: separation of authority, not two prompts chatting The AKS promotion separates Forge into Builder and Reviewer roles: Control Builder Reviewer Tokens per request 2048 512 Daily tokens 8192 2048 Tool authority Read, search, patch, test, diff Read diff/evidence and submit a decision Approval mode Never Always Trust threshold 700 800 The Builder may create a patch but cannot approve release. The Reviewer may approve a digest-pinned Builder artifact but cannot change source or approve an artifact created by the Reviewer. The final handoff carries patch, test-evidence, and artifact-manifest digests and still stops for human PR approval. The code/08 final sandbox-escape gate explicitly rejects: self-modified authority; symlink escape; host trust handoff; DNS egress; Builder self-approval; Reviewer source modification; untrusted or expired peer drafts. The release standard therefore becomes: Correct behavior must pass, and credential, network, tool, approval, evidence, and containment boundaries must remain intact. Passing tests alone is not release evidence. 11. What kars does not promise kars strengthens the sandbox, but it does not solve every risk automatically: It does not prove that a generated patch is correct. It does not make untrusted code safe to merge. It cannot protect a credential mistakenly mounted into the agent. Local Docker mode does not become a production boundary. It does not replace tenant RBAC, quotas, image policy, signing, supply-chain controls, or durable audit export. It cannot compensate for a policy that deliberately enables arbitrary shell and unrestricted egress. Confidential isolation does not replace least privilege, tool policy, egress policy, and code review. The sandbox bounds authority and blast radius. Tests, evaluation, independent review, and release policy still determine whether a change is acceptable. 12. An enterprise adoption path with measurable exits Phase 1: define the business and threat contract Specify inputs, outputs, allowed actions, forbidden actions, data boundaries, and the human approval point. Exit: product, platform, and security can all explain the agent's maximum authority. Phase 2: validate one OpenClaw vertical slice Use narrow business MCP tools instead of a general shell, and include hostile repository content. Exit: the normal task succeeds while self-configuration, path/symlink, trust-handoff, and egress tests fail. Phase 3: encode the sandbox as a Kubernetes contract Validate UID separation, root filesystem, capabilities, volumes, service-account tokens, NetworkPolicy, egress guard, and exec admission. Exit: the five boundaries are supported by runtime evidence, not only YAML review. Phase 4: add tool, model, and cost governance Apply McpServer, ToolPolicy, and InferencePolicy. Test unknown tools, dangerous arguments, and token overflow. Exit: violations are denied on the live request path. Phase 5: migrate into explicit MAF code Encode workflow state, typed tools, loop limits, evidence, failure paths, and the human stop. Exit: the MAF runtime preserves the external boundary already proven around the OpenClaw prototype. Phase 6: promote to AKS through GitOps Pin source revision, image digest, and loaded policy digest. Separate Builder and Reviewer authority. Prepare the kill switch, rollback, and durable audit export. Exit: one allowed workflow succeeds, multiple escape and authority-violation scenarios are denied, and all results have correlated evidence. Conclusion: kars does not make the model smarter; it makes agent authority explainable Enterprises will ultimately ask: What can the agent access? Where are the provider credentials? Who defines and changes the tool authority? Can prompt injection move data through DNS, metadata, a daemon, or HTTPS? How many tokens and repair iterations may one task consume? Who may patch, approve, merge, or deploy? Does evidence survive pod loss? If OpenClaw is replaced by MAF, does the security model remain intact? The ByteCraft AI story does not argue for one universal agent framework. It argues for a stable Agent Infrastructure layer: Use OpenClaw to discover valuable behavior quickly, use Microsoft Agent Framework to encode that behavior as explicit and testable application code, and use kars to remove credentials, networking, tools, budgets, sandboxing, audit, and lifecycle authority from the agent application itself. An agent becomes an enterprise workload when it has an independent identity boundary, a budget, a constrained tool surface, controlled egress, exportable evidence, and operational suspension and rollback—not merely when it runs inside a container. References Let's Learn Microsoft kars Microsoft kars327Views5likes0CommentsDemystifying GitHub Copilot Security Controls: easing concerns for organizational adoption
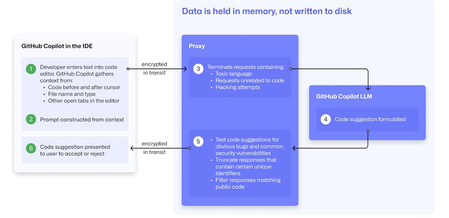
At a recent developer conference, I delivered a session on Legacy Code Rescue using GitHub Copilot App Modernization. Throughout the day, conversations with developers revealed a clear divide: some have fully embraced Agentic AI in their daily coding, while others remain cautious. Often, this hesitation isn't due to reluctance but stems from organizational concerns around security and regulatory compliance. Having witnessed similar patterns during past technology shifts, I understand how these barriers can slow adoption. In this blog, I'll demystify the most common security concerns about GitHub Copilot and explain how its built-in features address them, empowering organizations to confidently modernize their development workflows. GitHub Copilot Model Training A common question I received at the conference was whether GitHub uses your code as training data for GitHub Copilot. I always direct customers to the GitHub Copilot Trust Center for clarity, but the answer is straightforward: “No. GitHub uses neither Copilot Business nor Enterprise data to train the GitHub model.” Notice this restriction also applies to third-party models as well (e.g. Anthropic, Google). GitHub Copilot Intellectual Property indemnification policy A frequent concern I hear is, since GitHub Copilot’s underlying models are trained on sources that include public code, it might simply “copy and paste” code from those sources. Let’s clarify how this actually works: Does GitHub Copilot “copy/paste”? “The AI models that create Copilot’s suggestions may be trained on public code, but do not contain any code. When they generate a suggestion, they are not “copying and pasting” from any codebase.” To provide an additional layer of protection, GitHub Copilot includes a “duplicate detection filter”. This feature helps prevent suggestions that closely match public code from being surfaced. (Note: This duplicate detection currently does not apply to the Copilot coding agent.) More importantly, customers are protected by an Intellectual Property indemnification policy. This means that if you receive an unmodified suggestion from GitHub Copilot and face a copyright claim as a result, Microsoft will defend you in court. GitHub Copilot Data Retention Another frequent question I hear concerns GitHub Copilot’s data retention policies. For organizations on GitHub Copilot Business and Enterprise plans, retention practices depend on how and where the service is accessed from: Access through IDE for Chat and Code Completions: Prompts and Suggestions: Not retained. User Engagement Data: Kept for two years. Feedback Data: Stored for as long as needed for its intended purpose. Other GitHub Copilot access and use: Prompts and Suggestions: Retained for 28 days. User Engagement Data: Kept for two years. Feedback Data: Stored for as long as needed for its intended purpose. For Copilot Coding Agent, session logs are retained for the life of the account in order to provide the service. Excluding content from GitHub Copilot To prevent GitHub Copilot from indexing sensitive files, you can configure content exclusions at the repository or organization level. In VS Code, use the .copilotignore file to exclude files client-side. Note that files listed in .gitignore are not indexed by default but may still be referenced if open or explicitly referenced (unless they’re excluded through .copilotignore or content exclusions). The life cycle of a GitHub Copilot code suggestion Here are the key protections at each stage of the life cycle of a GitHub Copilot code suggestion: In the IDE: Content exclusions prevent files, folders, or patterns from being included. GitHub proxy (pre-model safety): Prompts go through a GitHub proxy hosted in Microsoft Azure for pre-inference checks: screening for toxic or inappropriate language, relevance, and hacking attempts/jailbreak-style prompts before reaching the model. Model response: With the public code filter enabled, some suggestions are suppressed. The vulnerability protection feature blocks insecure coding patterns like hardcoded credentials or SQL injections in real time. Disable access to GitHub Copilot Free Due to the varying policies associated with GitHub Copilot Free, it is crucial for organizations to ensure it is disabled both in the IDE and on GitHub.com. Since not all IDEs currently offer a built-in option to disable Copilot Free, the most reliable method to prevent both accidental and intentional access is to implement firewall rule changes, as outlined in the official documentation. Agent Mode Allow List Accidental file system deletion by Agentic AI assistants can happen. With GitHub Copilot agent mode, the "Terminal auto approve” setting in VS Code can be used to prevent this. This setting can be managed centrally using a VS Code policy. MCP registry Organizations often want to restrict access to allow only trusted MCP servers. GitHub now offers an MCP registry feature for this purpose. This feature isn’t available in all IDEs and clients yet, but it's being developed. Compliance Certifications The GitHub Copilot Trust Center page lists GitHub Copilot's broad compliance credentials, surpassing many competitors in financial, security, privacy, cloud, and industry coverage. SOC 1 Type 2: Assurance over internal controls for financial reporting. SOC 2 Type 2: In-depth report covering Security, Availability, Processing Integrity, Confidentiality, and Privacy over time. SOC 3: General-use version of SOC 2 with broad executive-level assurance. ISO/IEC 27001:2013: Certification for a formal Information Security Management System (ISMS), based on risk management controls. CSA STAR Level 2: Includes a third-party attestation combining ISO 27001 or SOC 2 with additional cloud control matrix (CCM) requirements. TISAX: Trusted Information Security Assessment Exchange, covering automotive-sector security standards. In summary, while the adoption of AI tools like GitHub Copilot in software development can raise important questions around security, privacy, and compliance, it’s clear that existing safeguards in place help address these concerns. By understanding the safeguards, configurable controls, and robust compliance certifications offered, organizations and developers alike can feel more confident in embracing GitHub Copilot to accelerate innovation while maintaining trust and peace of mind.Token Economics: The New FinOps for Agentic AI
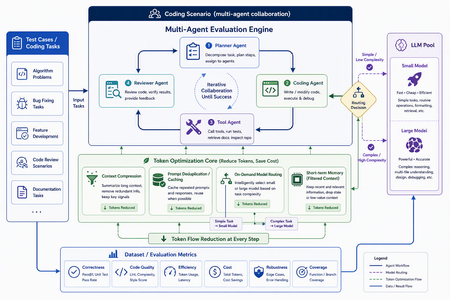
In AI applications, tokens are now cost — and token economics deserves architectural attention For a long time, AI application design started with model capability: Can the model write code? Can it reason? Can it use tools? Can it handle long context? Those questions still matter, but in the age of agentic applications, they are no longer sufficient. The more important production question is this: How many tokens does the architecture burn to complete one useful task? A classic chat application often maps one user turn to one model call. An agentic system is different. One user goal can trigger planning, retrieval, tool selection, tool execution, result interpretation, reflection, repair, and summarization. The user sees one instruction; the system may execute dozens of model calls behind the scenes. Tokens are no longer just a measure of text length. They become a measure of system design, runtime behavior, developer workflow, and business cost. GitHub Copilot’s 2026 move to usage-based billing through GitHub AI Credits captures the industry shift clearly. Usage is now aligned with token consumption, including input, output, and cached tokens. That matters because Copilot has evolved from an in-editor assistant into an agentic platform that can handle long, multi-step coding sessions across repositories. In that world, a tiny prompt and a multi-hour autonomous coding workflow should not be treated as the same economic unit. Token economics is therefore not about telling developers to “write shorter prompts.” It is about designing systems where: useful context is preserved, while noise is removed; repeated context is cached or deduplicated; simple tasks do not pay for frontier models; short-term state is managed structurally instead of copied repeatedly; every model call is metered, comparable, and governed. In short: token economics is the practice of making agentic AI economically sustainable. Scenario thinking: GitHub Copilot billing, Copilot SDK, GPT-5.5, Anthropic, and MAI-Code Model The new GitHub Copilot billing model provides a useful framing for developers. Copilot is no longer only autocomplete. It is becoming a programmable agentic platform. It can use models, call tools, work across files, stream responses, and participate in long-running coding workflows. With the GitHub Copilot SDK, developers can embed that agentic runtime into their own applications, services, and developer tools. That is powerful, but it also changes the cost model. Once an agent loop becomes programmable, token cost also needs to become programmable. If a system can plan, call tools, edit files, retry, repair, and summarize, it also needs to meter, route, cache, compress, and evaluate. EvalAgentic gives this idea a concrete playground. The project groups models into cost and capability tiers: Tier Example models Example price / 1K tokens Typical use LARGE claude-opus-4.8, gpt-5.5 $0.030 Agents, code generation, multi-step reasoning MID gpt-5.4-mini $0.012 Dialogue, summarization, extraction TINY gpt-5-mini $0.001 Classification, keyword matching, rule-like tasks This tiering lets us reason about real scenarios: GPT-5.5-class models are valuable for hard reasoning and engineering workflows, but they should not be the default for every step. Using a frontier model for simple classification is like hiring a principal architect to label folders. Anthropic high-capability models can be excellent for complex reasoning and coding, but they benefit from routing discipline. Requirements analysis, test interpretation, deployment explanation, and code generation may not need the same model tier. MAI-Code Model-style coding models should be treated as specialized capability layers. Their value is not just “better code generation”; it is deciding when code-specialized intelligence should be invoked in a larger agent pipeline. The real question is not “Which model is the best?” It is: Which model is the most economical and reliable for this step of this workflow? Four engineering techniques for saving tokens Context Compression: turn long text into executable structure Implementation principle Context Compression converts long natural-language context into the structured information an agent actually needs. Business documents are often verbose: resumes, contracts, product manuals, requirements, and support logs contain narrative text, boilerplate, repeated explanations, and low-value context. The next agent step may only need a few fields. EvalAgentic demonstrates this with a long resume-like input that is compressed into a compact JSON object. Instead of injecting the full original text into every prompt, the system extracts key fields and dynamically injects only the data required by the current task. A practical compression pipeline includes: Redundancy detection — identify long-tail text, repeated descriptions, stale history, and low-value context. Structured extraction — use Copilot or a mid-tier model to transform prose into JSON, tables, or typed schemas. Dynamic injection — inject only the fields needed for the next step. Recoverable references — preserve source pointers so compressed context remains auditable. How to evaluate Prompt token reduction before and after compression. Answer quality and task success rate. Schema fidelity and missing-field rate. Latency improvement. Cost per successful task. Compression is not summarization. Summaries are designed for humans. Structured compression is designed for agents. Prompt Deduplication / Cache: stop paying twice for the same context Implementation principle Many agent systems waste tokens because they repeatedly send the same context. The same resume, contract, repository README, user profile, API documentation, or business rule can be copied across turns and agents. Prompt Deduplication / Cache applies a simple principle: if context has already been processed, do not pay to process it again unless it has changed. A concrete design includes: compute a hash or semantic key for source context; reuse extracted structured results when content is identical or equivalent; apply a TTL for repeated entities, such as the 24-hour cache pattern shown in EvalAgentic; organize stable prompt prefixes to benefit from provider-level prompt caching where available; store shared context in an artifact store or memory layer so multiple agents do not copy the same blob. How to evaluate Cache hit rate. Cached token ratio. Duplicate prompt rate. Cost delta before and after caching. Correctness under cache, especially stale-cache failures. Caching is not “save everything forever.” Good caching knows when to reuse and when to invalidate. On-Demand Model Routing: let task complexity decide model tier Implementation principle On-Demand Model Routing routes each request to the cheapest model that can complete the task reliably. The entry point can use a rule tree, a lightweight classifier, or a hybrid complexity score. EvalAgentic’s routing tree is intentionally easy to explain: INCOMING REQUEST └─ Prompt < 500 tokens? ── YES ─→ TINY: classify / extract └─ NO ──→ multi-step reasoning? ├─ NO ─→ MID: dialogue / summary └─ YES ─→ LARGE: agent / code The engineering logic is straightforward: simple classification and keyword matching go to TINY; summarization and structured conversion go to MID; multi-step reasoning, coding, cross-file changes, and orchestration go to LARGE; code-specialized models such as MAI-Code Model can be placed in the coding phase rather than used across the whole pipeline. How to evaluate Routing accuracy. Cost per route. Quality regression by tier. Escalation rate from small models to larger models. End-to-end success rate. Routing does not mean “always use the smallest model.” It means frontier intelligence is reserved for the steps where it actually changes the outcome. Short-term Memory: preserve state instead of replaying history Implementation principle Short-term Memory controls context growth across multi-turn and multi-agent workflows. Without it, agents often replay the full conversation history, full tool outputs, and full intermediate reasoning on every turn. The context grows; quality may not improve; the bill definitely does. A better design stores state structurally: user goal; current plan; tool outputs and references; failure reasons; next actions; handoff artifacts between agents. In a multi-agent coding pipeline, the Requirements Agent should hand off a structured spec. The Coding Agent should read that spec, not the entire prior conversation. The Testing Agent should consume testable artifacts, not every word produced by the Coding Agent. How to evaluate Context growth curve across turns. Memory retrieval precision. Rework rate caused by missing state. Recovery quality after failed steps. Average input tokens per turn. Short-term memory is not about remembering everything. It is about remembering the next useful thing. EvalAgentic as a concrete evaluation example EvalAgentic is effective as an evangelism project because it turns token economics into an observable before/after system. The architecture has five layers: Frontend — frontend/index.html provides Tabs A / B / C, live SSE logs, and before/after charts. API — backend/server.py exposes FastAPI routes and Server-Sent Events streaming. Orchestration — eval.py handles A/B evaluation; coding_agents.py handles the multi-agent coding scenario. Core — compressor.py, router.py, gh_models.py, and token_meter.py implement compression, routing, Copilot SDK calls, and token metering. Providers — GitHub Copilot SDK and Microsoft Agent Framework provide model access and agent orchestration. Tab A: Compression comparison Tab A compares long-form context before and after structured compression. The key message is that token saving does not come from writing a clever sentence. It comes from converting verbose context into a structured artifact that downstream agents can consume efficiently. Tab B: On-demand model routing Tab B demonstrates that cost is not only about raw token count. If a system routes simple tasks to cheaper tiers and reserves expensive models for complex reasoning, total cost can fall even if some token counts increase. This is a subtle but important point: token economics is not token starvation; it is model portfolio optimization. Tab C: Coding scenario — multi-agent with Agent Framework Tab C is the most persuasive demo. The same deliverable — a Taobao-like goods-list site with HTML + JavaScript frontend, Flask backend, and Docker deployment — is produced twice by a four-agent pipeline: Requirements Agent; Coding Agent; Testing Agent; Deployment Agent. The before pipeline uses no compression and sends every agent to GPT-5.5 / LARGE. The after pipeline injects a compressed JSON spec and uses on-demand routing: requirements can use MID, coding can use LARGE, testing can use MID, and deployment can use TINY. This mirrors real enterprise development. Architecture and complex code generation may deserve frontier models. Test interpretation, deployment packaging, and simple validation often do not. Summary and refinement based on the project diagrams The EvalAgentic README describes three important visuals: the architecture flow, the routing tree, and the token-meter design. Together, they form a governance loop: User Scenario ↓ Context Compression ↓ Prompt Deduplication / Cache ↓ On-Demand Model Routing ↓ Short-term Memory ↓ Token Metering & Budget Actions ↓ Before / After Evaluation Optimize the path, not only the prompt Many teams start token optimization by editing prompt wording. That helps, but the largest waste usually lives in the execution path: how many calls are made, how much context is repeated, how often tools retry, and whether every step uses the same expensive model. EvalAgentic makes the path visible through A/B comparisons. Token Meter is the control plane of cost governance EvalAgentic’s token_meter.py uses a non-invasive interceptor pattern: INTERCEPTOR (@token_meter) ↓ COUNTER CORE: accounting / budget threshold / trigger ↓ ACTION HUB: throttle (>80% budget) / rollback (>budget) This is the right architectural instinct. Production systems need thresholds, throttling, rollback, and traceability. Without those controls, one retry loop can quietly turn a small user request into a budget incident. Cost metrics must be evaluated with quality metrics A system that cuts cost by 80% but drops success rate by 50% is not optimized. It is broken more cheaply. The evaluation matrix should combine cost, quality, latency, and reliability: Dimension Metric Why it matters Cost Cost per successful task Measures the real unit economics Token Input / output / cached tokens Identifies compression and cache opportunities Quality Pass rate / regression rate Ensures cheaper tiers do not break outcomes Efficiency Latency / retry count Prevents cheap models from causing expensive retries Governance Budget breach / rollback count Validates runtime control Narrative A simple three-line narrative works well for demos: Token is no longer a technical detail. It is the bill of your architecture. EvalAgentic shows the same scenario before and after cost-aware design. The goal is not to make models cheaper; the goal is to make agent systems economically governable. For a developer audience, the sharper version is: A good agent does not use the biggest model everywhere. It uses the right intelligence at the right step, with the right context, under the right budget. Practical recommendations for real projects Establish a token baseline first. Measure input, output, retries, tool calls, and cost per scenario before optimizing. Make compression a component, not a prompt habit. Define schemas, cache policies, and fallback behavior. Introduce a model routing matrix. Route by task type, complexity, risk, latency, and cost. Define handoff contracts between agents. Pass structured artifacts, not endless conversation history. Evaluate every optimization with A/B tests. Compare cost, quality, latency, and stability. Add budget actions. Throttle at a threshold, rollback on breach, and add circuit breakers for failed retries. Closing: token economics is the second curve of agent engineering The first phase of AI application development was about calling models. The second phase was about putting models into products. The next phase of agentic AI is about running those systems reliably, affordably, and governably. EvalAgentic matters because it turns Context Compression, Prompt Deduplication / Cache, On-Demand Model Routing, and Short-term Memory into something developers can run, compare, and explain. It moves token economics from opinion to instrumentation. Future AI applications will not only ask: How smart is this agent? They will ask: How many tokens does it spend per completed task? Which model did it use? Did it hit cache? Did retries run away? Did the system reserve frontier intelligence for the steps that deserved it? References kinfey/EvalAgentic GitHub Copilot is moving to usage-based billing Updates to GitHub Copilot billing and plans Copilot SDK - GitHub Docs7.6KViews4likes0CommentsBuilding a Multi-Agent On-Call Copilot with Microsoft Agent Framework
Four AI agents, one incident payload, structured triage in under 60 seconds powered by Microsoft Agent Framework and Foundry Hosted Agents. Multi-Agent Microsoft Agent Framework Foundry Hosted Agents Python SRE / Incident Response When an incident fires at 3 AM, every second the on-call engineer spends piecing together alerts, logs, and metrics is a second not spent fixing the problem. What if an AI system could ingest the raw incident signals and hand you a structured triage, a Slack update, a stakeholder brief, and a draft post-incident report, all in under 10 seconds? That’s exactly what On-Call Copilot does. In this post, we’ll walk through how we built it using the Microsoft Agent Framework, deployed it as a Foundry Hosted Agent, and discuss the key design decisions that make multi-agent orchestration practical for production workloads. The full source code is open-source on GitHub. You can deploy your own instance with a single azd up . Why Multi-Agent? The Problem with Single-Prompt Triage Early AI incident assistants used a single large prompt: “Here is the incident. Give me root causes, actions, a Slack message, and a post-incident report.” This approach has two fundamental problems: Context overload. A real incident may have 800 lines of logs, 10 alert lines, and dense metrics. Asking one model to process everything and produce four distinct output formats in a single turn pushes token limits and degrades quality. Conflicting concerns. Triage reasoning and communication drafting are cognitively different tasks. A model optimised for structured JSON analysis often produces stilted Slack messages—and vice versa. The fix is specialisation: decompose the task into focused agents, give each agent a narrow instruction set, and run them in parallel. This is the core pattern that the Microsoft Agent Framework makes easy. Architecture: Four Agents Running Concurrently On-Call Copilot is deployed as a Foundry Hosted Agent—a containerised Python service running on Microsoft Foundry’s managed infrastructure. The core orchestrator uses ConcurrentBuilder from the Microsoft Agent Framework SDK to run four specialist agents in parallel via asyncio.gather() . All four panels populated simultaneously: Triage (red), Summary (blue), Comms (green), PIR (purple). Architecture: The orchestrator runs four specialist agents concurrently via asyncio.gather(), then merges their JSON fragments into a single response. All four agents The solution share a single Azure OpenAI Model Router deployment. Rather than hardcoding gpt-4o or gpt-4o-mini , Model Router analyses request complexity and routes automatically. A simple triage prompt costs less; a long post-incident synthesis uses a more capable model. One deployment name, zero model-selection code. Meet the Four Agents 🔍 Triage Agent Root cause analysis, immediate actions, missing data identification, and runbook alignment. suspected_root_causes · immediate_actions · missing_information · runbook_alignment 📋 Summary Agent Concise incident narrative: what happened and current status (ONGOING / MITIGATED / RESOLVED). summary.what_happened · summary.current_status 📢 Comms Agent Audience-appropriate communications: Slack channel update with emoji conventions, plus a non-technical stakeholder brief. comms.slack_update · comms.stakeholder_update 📝 PIR Agent Post-incident report: chronological timeline, quantified customer impact, and specific prevention actions. post_incident_report.timeline · .customer_impact · .prevention_actions The Code: Building the Orchestrator The entry point is remarkably concise. ConcurrentBuilder handles all the async wiring—you just declare the agents and let the framework handle parallelism, error propagation, and response merging. main.py — Orchestrator from agent_framework import ConcurrentBuilder from agent_framework.azure import AzureOpenAIChatClient from azure.ai.agentserver.agentframework import from_agent_framework from azure.identity import DefaultAzureCredential, get_bearer_token_provider from app.agents.triage import TRIAGE_INSTRUCTIONS from app.agents.comms import COMMS_INSTRUCTIONS from app.agents.pir import PIR_INSTRUCTIONS from app.agents.summary import SUMMARY_INSTRUCTIONS _credential = DefaultAzureCredential() _token_provider = get_bearer_token_provider( _credential, "https://cognitiveservices.azure.com/.default" ) def create_workflow_builder(): """Create 4 specialist agents and wire them into a ConcurrentBuilder.""" triage = AzureOpenAIChatClient(ad_token_provider=_token_provider).create_agent( instructions=TRIAGE_INSTRUCTIONS, name="triage-agent", ) summary = AzureOpenAIChatClient(ad_token_provider=_token_provider).create_agent( instructions=SUMMARY_INSTRUCTIONS, name="summary-agent", ) comms = AzureOpenAIChatClient(ad_token_provider=_token_provider).create_agent( instructions=COMMS_INSTRUCTIONS, name="comms-agent", ) pir = AzureOpenAIChatClient(ad_token_provider=_token_provider).create_agent( instructions=PIR_INSTRUCTIONS, name="pir-agent", ) return ConcurrentBuilder().participants([triage, summary, comms, pir]) def main(): builder = create_workflow_builder() from_agent_framework(builder.build).run() # starts on port 8088 if __name__ == "__main__": main() Key insight: DefaultAzureCredential means there are no API keys anywhere in the codebase. The container uses managed identity in production; local development uses your az login session. The same code runs in both environments without modification. Agent Instructions: Prompts as Configuration Each agent receives a tightly scoped system prompt that defines its output schema and guardrails. Here’s the Triage Agent—the most complex of the four: app/agents/triage.py TRIAGE_INSTRUCTIONS = """\ You are the **Triage Agent**, an expert Site Reliability Engineer specialising in root cause analysis and incident response. ## Task Analyse the incident data and return a single JSON object with ONLY these keys: { "suspected_root_causes": [ { "hypothesis": "string – concise root cause hypothesis", "evidence": ["string – supporting evidence from the input"], "confidence": 0.0 // 0-1, how confident you are } ], "immediate_actions": [ { "step": "string – concrete action with runnable command if applicable", "owner_role": "oncall-eng | dba | infra-eng | platform-eng", "priority": "P0 | P1 | P2 | P3" } ], "missing_information": [ { "question": "string – what data is missing", "why_it_matters": "string – why this data would help" } ], "runbook_alignment": { "matched_steps": ["string – runbook steps that match the situation"], "gaps": ["string – gaps or missing runbook coverage"] } } ## Guardrails 1. **No secrets** – redact any credential-like material as [REDACTED]. 2. **No hallucination** – if data is insufficient, set confidence to 0 and add entries to missing_information. 3. **Diagnostic suggestions** – when data is sparse, include diagnostic steps in immediate_actions. 4. **Structured output only** – return ONLY valid JSON, no prose. """ The Comms Agent follows the same pattern but targets a different audience: app/agents/comms.py COMMS_INSTRUCTIONS = """\ You are the **Comms Agent**, an expert incident communications writer. ## Task Return a single JSON object with ONLY this key: { "comms": { "slack_update": "Slack-formatted message with emoji, severity, status, impact, next steps, and ETA", "stakeholder_update": "Non-technical summary for executives. Focus on business impact and resolution." } } ## Guidelines - Slack: Use :rotating_light: for active SEV1/2, :warning: for degraded, :white_check_mark: for resolved. - Stakeholder: No jargon. Translate to business impact. - Tone: Calm, factual, action-oriented. Never blame individuals. - Structured output only – return ONLY valid JSON, no prose. """ Instructions as config, not code. Agent behaviour is defined entirely by instruction text strings. A non-developer can refine agent behaviour by editing the prompt and redeploying no Python changes needed. The Incident Envelope: What Goes In The agent accepts a single JSON envelope. It can come from a monitoring alert webhook, a PagerDuty payload, or a manual CLI invocation: Incident Input (JSON) { "incident_id": "INC-20260217-002", "title": "DB connection pool exhausted — checkout-api degraded", "severity": "SEV1", "timeframe": { "start": "2026-02-17T14:02:00Z", "end": null }, "alerts": [ { "name": "DatabaseConnectionPoolNearLimit", "description": "Connection pool at 99.7% on orders-db-primary", "timestamp": "2026-02-17T14:03:00Z" } ], "logs": [ { "source": "order-worker", "lines": [ "ERROR: connection timeout after 30s (attempt 3/3)", "WARN: pool exhausted, queueing request (queue_depth=847)" ] } ], "metrics": [ { "name": "db_connection_pool_utilization_pct", "window": "5m", "values_summary": "Jumped from 22% to 99.7% at 14:03Z" } ], "runbook_excerpt": "Step 1: Check DB connection dashboard...", "constraints": { "max_time_minutes": 15, "environment": "production", "region": "swedencentral" } } Declaring the Hosted Agent The agent is registered with Microsoft Foundry via a declarative agent.yaml file. This tells Foundry how to discover and route requests to the container: agent.yaml kind: hosted name: oncall-copilot description: | Multi-agent hosted agent that ingests incident signals and runs 4 specialist agents concurrently via Microsoft Agent Framework ConcurrentBuilder. metadata: tags: - Azure AI AgentServer - Microsoft Agent Framework - Multi-Agent - Model Router protocols: - protocol: responses environment_variables: - name: AZURE_OPENAI_ENDPOINT value: ${AZURE_OPENAI_ENDPOINT} - name: AZURE_OPENAI_CHAT_DEPLOYMENT_NAME value: model-router The protocols: [responses] declaration exposes the agent via the Foundry Responses API on port 8088. Clients can invoke it with a standard HTTP POST no custom API needed. Invoking the Agent Once deployed, you can invoke the agent with the project’s built-in scripts or directly via curl : CLI / curl # Using the included invoke script python scripts/invoke.py --demo 2 # multi-signal SEV1 demo python scripts/invoke.py --scenario 1 # Redis cluster outage # Or with curl directly TOKEN=$(az account get-access-token \ --resource https://ai.azure.com --query accessToken -o tsv) curl -X POST \ "$AZURE_AI_PROJECT_ENDPOINT/openai/responses?api-version=2025-05-15-preview" \ -H "Authorization: Bearer $TOKEN" \ -H "Content-Type: application/json" \ -d '{ "input": [ {"role": "user", "content": "<incident JSON here>"} ], "agent": { "type": "agent_reference", "name": "oncall-copilot" } }' The Browser UI The project includes a zero-dependency browser UI built with plain HTML, CSS, and vanilla JavaScript—no React, no bundler. A Python http.server backend proxies requests to the Foundry endpoint. The empty state. Quick-load buttons pre-populate the JSON editor with demo incidents or scenario files. Demo 1 loaded: API Gateway 5xx spike, SEV3. The JSON is fully editable before submitting. Agent Output Panels Triage: Root causes ranked by confidence. Evidence is collapsed under each hypothesis. Triage: Immediate actions with P0/P1/P2 priority badges and owner roles. Comms: Slack card with emoji substitution and a stakeholder executive summary. PIR: Chronological timeline with an ONGOING marker, customer impact in a red-bordered box. Performance: Parallel Execution Matters Incident Type Complexity Parallel Latency Sequential (est.) Single alert, minimal context (SEV4) Low 4–6 s ~16 s Multi-signal, logs + metrics (SEV2) Medium 7–10 s ~28 s Full SEV1 with long log lines High 10–15 s ~40 s Post-incident synthesis (resolved) High 10–14 s ~38 s asyncio.gather() running four independent agents cuts total latency by 3–4× compared to sequential execution. For a SEV1 at 3 AM, that’s the difference between a 10-second AI-powered head start and a 40-second wait. Five Key Design Decisions Parallel over sequential Each agent is independent and processes the full incident payload in isolation. ConcurrentBuilder with asyncio.gather() is the right primitive—no inter-agent dependencies, no shared state. JSON-only agent instructions Every agent returns only valid JSON with a defined schema. The orchestrator merges fragments with merged.update(agent_output) . No parsing, no extraction, no post-processing. No hardcoded model names AZURE_OPENAI_CHAT_DEPLOYMENT_NAME=model-router is the only model reference. Model Router selects the best model at runtime based on prompt complexity. When new models ship, the agent gets better for free. DefaultAzureCredential everywhere No API keys. No token management code. Managed identity in production, az login in development. Same code, both environments. Instructions as configuration Each agent’s system prompt is a plain Python string. Behaviour changes are text edits, not code logic. A non-developer can refine prompts and redeploy. Guardrails: Built into the Prompts The agent instructions include explicit guardrails that don’t require external filtering: No hallucination: When data is insufficient, the agent sets confidence: 0 and populates missing_information rather than inventing facts. Secret redaction: Each agent is instructed to redact credential-like patterns as [REDACTED] in its output. Mark unknowns: Undeterminable fields use the literal string "UNKNOWN" rather than plausible-sounding guesses. Diagnostic suggestions: When signal is sparse, immediate_actions includes diagnostic steps that gather missing information before prescribing a fix. Model Router: Automatic Model Selection One of the most powerful aspects of this architecture is Model Router. Instead of choosing between gpt-4o , gpt-4o-mini , or o3-mini per agent, you deploy a single model-router endpoint. Model Router analyses each request’s complexity and routes it to the most cost-effective model that can handle it. Model Router insights: models selected per request with associated costs. Model Router telemetry from Microsoft Foundry: request distribution and cost analysis. This means you get optimal cost-performance without writing any model-selection logic. A simple Summary Agent prompt may route to gpt-4o-mini , while a complex Triage Agent prompt with 800 lines of logs routes to gpt-4o all automatically. Deployment: One Command The repo includes both azure.yaml and agent.yaml , so deployment is a single command: Deploy to Foundry # Deploy everything: infra + container + Model Router + Hosted Agent azd up This provisions the Foundry project resources, builds the Docker image, pushes to Azure Container Registry, deploys a Model Router instance, and creates the Hosted Agent. For more control, you can use the SDK deploy script: Manual Docker + SDK deploy # Build and push (must be linux/amd64) docker build --platform linux/amd64 -t oncall-copilot:v1 . docker tag oncall-copilot:v1 $ACR_IMAGE docker push $ACR_IMAGE # Create the hosted agent python scripts/deploy_sdk.py Getting Started Quickstart # Clone git clone https://github.com/microsoft-foundry/oncall-copilot cd oncall-copilot # Install python -m venv .venv source .venv/bin/activate # .venv\Scripts\activate on Windows pip install -r requirements.txt # Set environment variables export AZURE_OPENAI_ENDPOINT="https://<account>.openai.azure.com/" export AZURE_OPENAI_CHAT_DEPLOYMENT_NAME="model-router" export AZURE_AI_PROJECT_ENDPOINT="https://<account>.services.ai.azure.com/api/projects/<project>" # Validate schemas locally (no Azure needed) MOCK_MODE=true python scripts/validate.py # Deploy to Foundry azd up # Invoke the deployed agent python scripts/invoke.py --demo 1 # Start the browser UI python ui/server.py # → http://localhost:7860 Extending: Add Your Own Agent Adding a fifth agent is straightforward. Follow this pattern: Create app/agents/<name>.py with a *_INSTRUCTIONS constant following the existing pattern. Add the agent’s output keys to app/schemas.py . Register it in main.py : main.py — Adding a 5th agent from app.agents.my_new_agent import NEW_INSTRUCTIONS new_agent = AzureOpenAIChatClient( ad_token_provider=_token_provider ).create_agent( instructions=NEW_INSTRUCTIONS, name="new-agent", ) workflow = ConcurrentBuilder().participants( [triage, summary, comms, pir, new_agent] ) Ideas for extensions: a ticket auto-creation agent that creates Jira or Azure DevOps items from the PIR output, a webhook adapter agent that normalises PagerDuty or Datadog payloads, or a human-in-the-loop agent that surfaces missing_information as an interactive form. Key Takeaways for AI Engineers The multi-agent pattern isn’t just for chatbots. Any task that can be decomposed into independent subtasks with distinct output schemas is a candidate. Incident response, document processing, code review, data pipeline validation—the pattern transfers. Microsoft Agent Framework gives you ConcurrentBuilder for parallel execution and AzureOpenAIChatClient for Azure-native auth—you write the prompts, the framework handles the plumbing. Foundry Hosted Agents let you deploy containerised agents with managed infrastructure, automatic scaling, and built-in telemetry. No Kubernetes, no custom API gateway. Model Router eliminates the model selection problem. One deployment name handles all scenarios with optimal cost-performance tradeoffs. Prompt-as-config means your agents are iterable by anyone who can edit text. The feedback loop from “this output could be better” to “deployed improvement” is minutes, not sprints. Resources Microsoft Agent Framework SDK powering the multi-agent orchestration Model Router Automatic model selection based on prompt complexity Foundry Hosted Agents Deploy containerised agents on managed infrastructure ConcurrentBuilder Samples Official agents-in-workflow sample this project follows DefaultAzureCredential Zero-config auth chain used throughout Hosted Agents Concepts Architecture overview of Foundry Hosted Agents The On-Call Copilot sample is open source under the MIT licence. Contributions, scenario files, and agent instruction improvements are welcome via pull request.Complete Guide to Deploying OpenClaw on Azure Windows 11 Virtual Machine
1. Introduction to OpenClaw OpenClaw is an open-source AI personal assistant platform that runs on your own devices and executes real-world tasks. Unlike traditional cloud-based AI assistants, OpenClaw emphasizes local deployment and privacy protection, giving you complete control over your data. Key Features of OpenClaw Cross-Platform Support: Runs on Windows, macOS, Linux, and other operating systems Multi-Channel Integration: Interact with AI through messaging platforms like WhatsApp, Telegram, and Discord Task Automation: Execute file operations, browser control, system commands, and more Persistent Memory: AI remembers your preferences and contextual information Flexible AI Backends: Supports multiple large language models including Anthropic Claude and OpenAI GPT OpenClaw is built on Node.js and can be quickly installed and deployed via npm. 2. Security Advantages of Running OpenClaw on Azure VM Deploying OpenClaw on an Azure virtual machine instead of your personal computer offers significant security benefits: 1. Environment Isolation Azure VMs provide a completely isolated runtime environment. Even if the AI agent exhibits abnormal behavior or is maliciously exploited, it won't affect your personal computer or local data. This isolation mechanism forms the foundation of a zero-trust security architecture. 2. Network Security Controls Through Azure Network Security Groups (NSGs), you can precisely control which IP addresses can access your virtual machine. The RDP rules configured in the deployment script allow you to securely connect to your Windows 11 VM via Remote Desktop while enabling further restrictions on access sources. 3. Data Persistence and Backup Azure VM managed disks support automatic snapshots and backups. Even if the virtual machine encounters issues, your OpenClaw configuration and data remain safe. 4. Elastic Resource Management You can adjust VM specifications (memory, CPU) at any time based on actual needs, or stop the VM when not in use to save costs, maintaining maximum flexibility. 5. Enterprise-Grade Authentication Azure supports integration with Azure Active Directory (Entra ID) for identity verification, allowing you to assign different access permissions to team members for granular access control. 6. Audit and Compliance Azure provides detailed activity logs and audit trails, making it easy to trace any suspicious activity and meet enterprise compliance requirements. 3. Deployment Steps Explained This deployment script uses Azure CLI to automate the installation of OpenClaw and its dependencies on a Windows 11 virtual machine. Here are the detailed execution steps: Prerequisites Before running the script, ensure you have: Install Azure CLI # Windows users can download the MSI installer https://aka.ms/installazurecliwindows # macOS users brew install azure-cli # Linux users curl -sL https://aka.ms/InstallAzureCLIDeb | sudo bash 2. Log in to Azure Account az login 3. Prepare Deployment Script Save the provided deploy-windows11-vm.sh script locally and grant execute permissions: chmod +x deploy-windows11-vm.sh Step 1: Configure Deployment Parameters The script begins by defining key configuration variables that you can modify as needed: RESOURCE_GROUP="Your Azure Resource Group Name" # Resource group name VM_NAME="win11-openclaw-vm" # Virtual machine name LOCATION="Your Azure Regison Name" # Azure region ADMIN_USERNAME="Your Azure VM Administrator Name" # Administrator username ADMIN_PASSWORD="our Azure VM Administrator Password" # Administrator password (change to a strong password) VM_SIZE="Your Azure VM Size" # VM size (4GB memory) Security Recommendations: Always change ADMIN_PASSWORD to your own strong password Passwords should contain uppercase and lowercase letters, numbers, and special characters Never commit scripts containing real passwords to code repositories Step 2: Check and Create Resource Group The script first checks if the specified resource group exists, and creates it automatically if it doesn't: echo "Checking resource group $RESOURCE_GROUP..." az group show --name $RESOURCE_GROUP &> /dev/null if [ $? -ne 0 ]; then echo "Creating resource group $RESOURCE_GROUP..." az group create --name $RESOURCE_GROUP --location $LOCATION fi A resource group is a logical container in Azure used to organize and manage related resources. All associated resources (VMs, networks, storage, etc.) will be created within this resource group. Step 3: Create Windows 11 Virtual Machine This is the core step, using the az vm create command to create a Windows 11 Pro virtual machine: az vm create \ --resource-group $RESOURCE_GROUP \ --name $VM_NAME \ --image MicrosoftWindowsDesktop:windows-11:win11-24h2-pro:latest \ --size $VM_SIZE \ --admin-username $ADMIN_USERNAME \ --admin-password $ADMIN_PASSWORD \ --public-ip-sku Standard \ --nsg-rule RDP Parameter Explanations: --image: Uses the latest Windows 11 24H2 Professional edition image --size: Standard_B2s provides 2 vCPUs and 4GB memory, suitable for running OpenClaw --public-ip-sku Standard: Assigns a standard public IP --nsg-rule RDP: Automatically creates network security group rules allowing RDP (port 3389) inbound traffic Step 4: Retrieve Virtual Machine Public IP After VM creation completes, the script retrieves its public IP address: PUBLIC_IP=$(az vm show -d -g $RESOURCE_GROUP -n $VM_NAME --query publicIps -o tsv) echo "VM Public IP: $PUBLIC_IP" This IP address will be used for subsequent RDP remote connections. Step 5: Install Chocolatey Package Manager Using az vm run-command to execute PowerShell scripts inside the VM, first installing Chocolatey: az vm run-command invoke -g $RESOURCE_GROUP -n $VM_NAME --command-id RunPowerShellScript \ --scripts "Set-ExecutionPolicy Bypass -Scope Process -Force; [System.Net.ServicePointManager]::SecurityProtocol = [System.Net.ServicePointManager]::SecurityProtocol -bor 3072; iex ((New-Object System.Net.WebClient).DownloadString( 'https://community.chocolatey.org/install.ps1'))" Chocolatey is a package manager for Windows, similar to apt or yum on Linux, simplifying subsequent software installations. Step 6: Install Git Git is a dependency for many npm packages, especially those that need to download source code from GitHub for compilation: az vm run-command invoke -g $RESOURCE_GROUP -n $VM_NAME --command-id RunPowerShellScript \ --scripts "C:\ProgramData\chocolatey\bin\choco.exe install git -y" Step 7: Install CMake and Visual Studio Build Tools Some of OpenClaw's native modules require compilation, necessitating the installation of C++ build toolchain: az vm run-command invoke -g $RESOURCE_GROUP -n $VM_NAME --command-id RunPowerShellScript \ --scripts "C:\ProgramData\chocolatey\bin\choco.exe install cmake visualstudio2022buildtools visualstudio2022-workload-vctools -y" Component Descriptions: cmake: Cross-platform build system visualstudio2022buildtools: VS 2022 Build Tools visualstudio2022-workload-vctools: C++ development toolchain Step 8: Install Node.js LTS Install the Node.js Long Term Support version, which is the core runtime environment for OpenClaw: az vm run-command invoke -g $RESOURCE_GROUP -n $VM_NAME --command-id RunPowerShellScript \ --scripts "$env:Path = [System.Environment]::GetEnvironmentVariable('Path','Machine') + ';' + [System.Environment]::GetEnvironmentVariable('Path','User'); C:\ProgramData\chocolatey\bin\choco.exe install nodejs-lts -y" The script refreshes environment variables first to ensure Chocolatey is in the PATH, then installs Node.js LTS. Step 9: Globally Install OpenClaw Use npm to globally install OpenClaw: az vm run-command invoke -g $RESOURCE_GROUP -n $VM_NAME --command-id RunPowerShellScript \ --scripts "$env:Path = [System.Environment]::GetEnvironmentVariable('Path','Machine') + ';' + [System.Environment]::GetEnvironmentVariable('Path','User'); npm install -g openclaw" Global installation makes the openclaw command available from anywhere in the system. Step 10: Configure Environment Variables Add Node.js and npm global paths to the system PATH environment variable: az vm run-command invoke -g $RESOURCE_GROUP -n $VM_NAME --command-id RunPowerShellScript \ --scripts " $npmGlobalPath = 'C:\Program Files\nodejs'; $npmUserPath = [System.Environment]::GetFolderPath('ApplicationData') + '\npm'; $currentPath = [System.Environment]::GetEnvironmentVariable('Path', 'Machine'); if ($currentPath -notlike \"*$npmGlobalPath*\") { $newPath = $currentPath + ';' + $npmGlobalPath; [System.Environment]::SetEnvironmentVariable('Path', $newPath, 'Machine'); Write-Host 'Added Node.js path to system PATH'; } if ($currentPath -notlike \"*$npmUserPath*\") { $newPath = [System.Environment]::GetEnvironmentVariable('Path', 'Machine') + ';' + $npmUserPath; [System.Environment]::SetEnvironmentVariable('Path', $newPath, 'Machine'); Write-Host 'Added npm global path to system PATH'; } Write-Host 'Environment variables updated successfully!'; " This ensures that node, npm, and openclaw commands can be used directly even in new terminal sessions. Step 11: Verify Installation The script finally verifies that all software is correctly installed: az vm run-command invoke -g $RESOURCE_GROUP -n $VM_NAME --command-id RunPowerShellScript \ --scripts "$env:Path = [System.Environment]::GetEnvironmentVariable('Path','Machine') + ';' + [System.Environment]::GetEnvironmentVariable('Path','User'); Write-Host 'Node.js version:'; node --version; Write-Host 'npm version:'; npm --version; Write-Host 'openclaw:'; npm list -g openclaw" Successful output should look similar to: Node.js version: v20.x.x npm version: 10.x.x openclaw: openclaw@x.x.x Step 12: Connect to Virtual Machine After deployment completes, the script outputs connection information: ============================================ Deployment completed! ============================================ Resource Group: Your Azure Resource Group Name VM Name: win11-openclaw-vm Public IP: xx.xx.xx.xx Admin Username: Your Administrator UserName VM Size: Your VM Size Connect via RDP: mstsc /v:xx.xx.xx.xx ============================================ Connection Methods: Windows Users: Press Win + R to open Run dialog Enter mstsc /v:public_ip and press Enter Log in using the username and password set in the script macOS Users: Download "Windows App" from the App Store Add PC connection with the public IP Log in using the username and password set in the script Linux Users: # Use Remmina or xfreerdp xfreerdp /u:username /v:public_ip Step 13: Initialize OpenClaw After connecting to the VM, run the following in PowerShell or Command Prompt # Initialize OpenClaw openclaw onboard # Configure AI model API key # Edit configuration file: C:\Users\username\.openclaw\openclaw.json notepad $env:USERPROFILE\.openclaw\openclaw.json Add your AI API key in the configuration file: { "agents": { "defaults": { "model": "Your Model Name", "apiKey": "your-api-key-here" } } } Step 14: Start OpenClaw # Start Gateway service openclaw gateway # In another terminal, connect messaging channels (e.g., WhatsApp) openclaw channels login Follow the prompts to scan the QR code and connect OpenClaw to your messaging app. 4. Summary Through this guide, we've successfully implemented the complete process of automatically deploying OpenClaw on an Azure Windows 11 virtual machine. The entire deployment process is highly automated, completing everything from VM creation to installing all dependencies and OpenClaw itself through a single script. Key Takeaways Automation Benefits: Using az vm run-command allows executing configuration scripts immediately after VM creation without manual RDP login Dependency Management: Chocolatey simplifies the Windows package installation workflow Environment Isolation: Running AI agents on cloud VMs protects local computers and data Scalability: Scripted deployment facilitates replication and team collaboration, easily deploying multiple instances Cost Optimization Tips Standard_B2s VMs cost approximately $0.05/hour (~$37/month) on pay-as-you-go pricing When not in use, stop the VM to only pay for storage costs Consider Azure Reserved Instances to save up to 72% Security Hardening Recommendations Change Default Port: Modify RDP port from 3389 to a custom port Enable JIT Access: Use Azure Security Center's just-in-time access feature Configure Firewall Rules: Only allow specific IP addresses to access Regular System Updates: Enable automatic Windows Updates Use Azure Key Vault: Store API keys in Key Vault instead of configuration files 5. Additional Resources Official Documentation OpenClaw Website: https://openclaw.ai OpenClaw GitHub: https://github.com/openclaw/openclaw OpenClaw Documentation: https://docs.openclaw.ai Azure CLI Documentation: https://docs.microsoft.com/cli/azure/ Azure Resources Azure VM Pricing Calculator: https://azure.microsoft.com/pricing/calculator/ Azure Free Account: https://azure.microsoft.com/free/ (new users receive $200 credit) Azure Security Center: https://azure.microsoft.com/services/security-center/ Azure Key Vault: https://azure.microsoft.com/services/key-vault/17KViews4likes4CommentsAI Toolkit Extension Pack for Visual Studio Code: Ignite 2025 Update
Unlock the Latest Agentic App Capabilities The Ignite 2025 update delivers a major leap forward for the AI Toolkit extension pack in VS Code, introducing a unified, end-to-end environment for building, visualizing, and deploying agentic applications to Microsoft Foundry, and the addition of Anthropic’s frontier Claude models in the Model Catalog! This release enables developers to build and debug locally in VS Code, then deploy to the cloud with a single click. Seamlessly switch between VS Code and the Foundry portal for visualization, orchestration, and evaluation, creating a smooth roundtrip workflow that accelerates innovation and delivers a truly unified AI development experience. Download the http://aka.ms/aitoolkit today and start building next-generation agentic apps in VS Code! What Can You Do with the AI Toolkit Extension Pack? Access Anthropic models in the Model Catalog Following the Microsoft, NVIDIA and Anthropic strategic partnerships announcement today, we are excited to share that Anthropic’s frontier Claude models including Claude Sonnet 4.5, Claude Opus 4.1, and Claude Haiku 4.5, are now integrated into the AI Toolkit, providing even more choices and flexibility when building intelligent applications and AI agents. Build AI Agents Using GitHub Copilot Scaffold agent applications using best-practice patterns, tool-calling examples, tracing hooks, and test scaffolds, all powered by Copilot and aligned with the Microsoft Agent Framework. Generate agent code in Python or .NET, giving you flexibility to target your preferred runtime. Build and Customize YAML Workflows Design YAML-based workflows in the Foundry portal, then continue editing and testing directly in VS Code. To customize your YAML-based workflows, instantly convert it to Agent Framework code using GitHub Copilot. Upgrade from declarative design to code-first customization without starting from scratch. Visualize Multi-Agent Workflows Envision your code-based agent workflows with an interactive graph visualizer that reveals each component and how they connect Watch in real-time how each node lights up as you run your agent. Use the visualizer to understand and debug complex agent graphs, making iteration fast and intuitive. Experiment, Debug, and Evaluate Locally Use the Hosted Agents Playground to quickly interact with your agents on your development machine. Leverage local tracing support to debug reasoning steps, tool calls, and latency hotspots—so you can quickly diagnose and fix issues. Define metrics, tasks, and datasets for agent evaluation, then implement metrics using the Foundry Evaluation SDK and orchestrate evaluations runs with the help of Copilot. Seamless Integration Across Environments Jump from Foundry Portal to VS Code Web for a development environment in your preferred code editor setting. Open YAML workflows, playgrounds, and agent templates directly in VS Code for editing and deployment. How to Get Started Install the AI Toolkit extension pack from the VS Code marketplace. Check out documentation. Get started with building workflows with Microsoft Foundry in VS Code 1. Work with Hosted (Pro-code) Agent workflows in VS Code 2. Work with Declarative (Low-code) Agent workflows in VS Code Feedback & Support Try out the extensions and let us know what you think! File issues or feedback on our GitHub repo for Foundry extension and AI Toolkit extension. Your input helps us make continuous improvements.3.3KViews4likes0CommentsUnderstanding Small Language Modes
Small Language Models (SLMs) bring AI from the cloud to your device. Unlike Large Language Models that require massive compute and energy, SLMs run locally, offering speed, privacy, and efficiency. They’re ideal for edge applications like mobile, robotics, and IoT.1.1KViews4likes0CommentsWhy your LLM-powered app needs concurrency
As part of the Python advocacy team, I help maintain several open-source sample AI applications, like our popular RAG chat demo. Through that work, I’ve learned a lot about what makes LLM-powered apps feel fast, reliable, and responsive. One of the most important lessons: use an asynchronous backend framework. Concurrency is critical for LLM apps, which often juggle multiple API calls, database queries, and user requests at the same time. Without async, your app may spend most of its time waiting — blocking one user’s request while another sits idle. The need for concurrency Why? Let’s imagine we’re using a synchronous framework like Flask. We deploy that to a server with gunicorn and several workers. One worker receives a POST request to the "/chat" endpoint, which in turn calls the Azure OpenAI Chat Completions API. That API call can take several seconds to complete — and during that time, the worker is completely tied up, unable to handle any other requests. We could scale out by adding more CPU cores, workers, or threads, but that’s often wasteful and expensive. Without concurrency, each request must be handled serially: When your app relies on long, blocking I/O operations — like model calls, database queries, or external API lookups — a better approach is to use an asynchronous framework. With async I/O, the Python runtime can pause a coroutine that’s waiting for a slow response and switch to handling another incoming request in the meantime. With concurrency, your workers stay busy and can handle new requests while others are waiting: Asynchronous Python backends In the Python ecosystem, there are several asynchronous backend frameworks to choose from: Quart: the asynchronous version of Flask FastAPI: an API-centric, async-only framework (built on Starlette) Litestar: a batteries-included async framework (also built on Starlette) Django: not async by default, but includes support for asynchronous views All of these can be good options depending on your project’s needs. I’ve written more about the decision-making process in another blog post. As an example, let's see what changes when we port a Flask app to a Quart app. First, our handlers now have async in front, signifying that they return a Python coroutine instead of a normal function: async def chat_handler(): request_message = (await request.get_json())["message"] When deploying these apps, I often still use the Gunicorn production web server—but with the Uvicorn worker, which is designed for Python ASGI applications. Alternatively, you can run Uvicorn or Hypercorn directly as standalone servers. Asynchronous API calls To fully benefit from moving to an asynchronous framework, your app’s API calls also need to be asynchronous. That way, whenever a worker is waiting for an external response, it can pause that coroutine and start handling another incoming request. Let's see what that looks like when using the official OpenAI Python SDK. First, we initialize the async version of the OpenAI client: openai_client = openai.AsyncOpenAI( base_url=os.environ["AZURE_OPENAI_ENDPOINT"] + "/openai/v1", api_key=token_provider ) Then, whenever we make API calls with methods on that client, we await their results: chat_coroutine = await openai_client.chat.completions.create( deployment_id=os.environ["AZURE_OPENAI_CHAT_DEPLOYMENT"], messages=[{"role": "system", "content": "You are a helpful assistant."}, {"role": "user", "content": request_message}], stream=True, ) For the RAG sample, we also have calls to Azure services like Azure AI Search. To make those asynchronous, we first import the async variant of the credential and client classes in the aio module: from azure.identity.aio import DefaultAzureCredential from azure.search.documents.aio import SearchClient Then, like with the OpenAI async clients, we must await results from any methods that make network calls: r = await self.search_client.search(query_text) By ensuring that every outbound network call is asynchronous, your app can make the most of Python’s event loop — handling multiple user sessions and API requests concurrently, without wasting worker time waiting on slow responses. Sample applications We’ve already linked to several of our samples that use async frameworks, but here’s a longer list so you can find the one that best fits your tech stack: Repository App purpose Backend Frontend azure-search-openai-demo RAG with AI Search Python + Quart React rag-postgres-openai-python RAG with PostgreSQL Python + FastAPI React openai-chat-app-quickstart Simple chat with Azure OpenAI models Python + Quart plain JS openai-chat-backend-fastapi Simple chat with Azure OpenAI models Python + FastAPI plain JS deepseek-python Simple chat with Azure AI Foundry models Python + Quart plain JS1.8KViews4likes0Comments