Monitoring dashboards were built for human eyes. It turns out they are also some of the best context you can hand an AI agent.
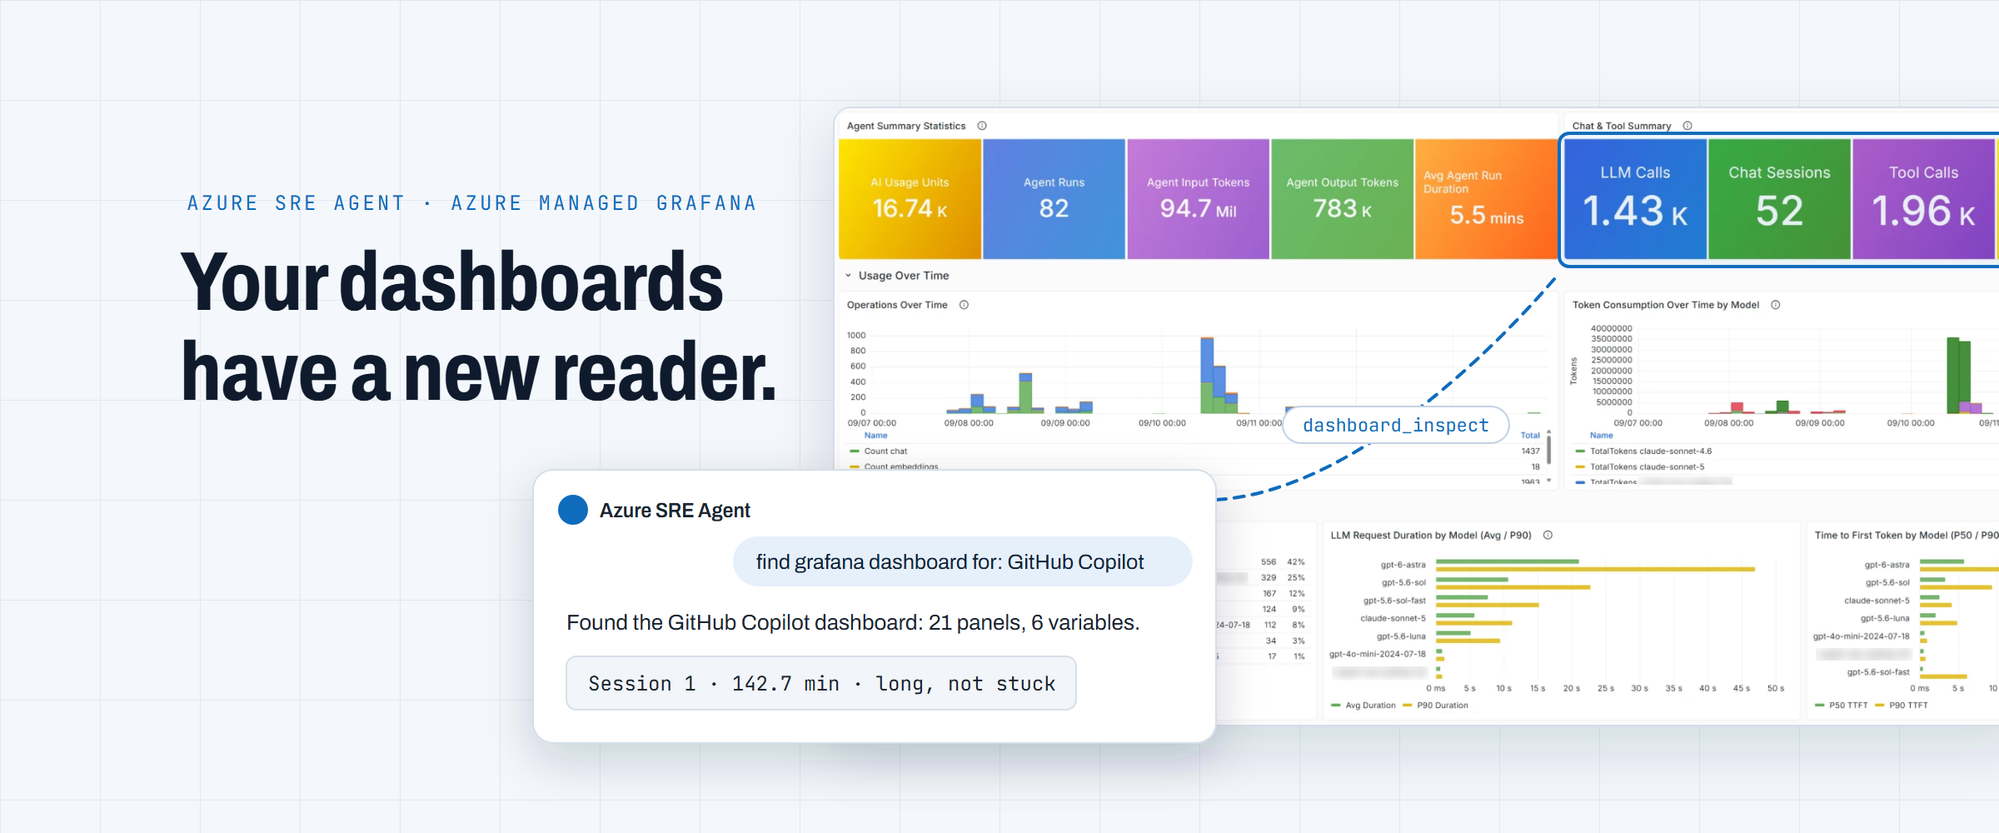
A few days ago I opened Azure SRE Agent and typed four prompts. None of them was careful:
find grafana dashboard for: GitHub Copilot
run the panels queries. list top 3 very long sessions in the past 3 days
what session 1 was doing?
what was session 2 doing?
No KQL. No table names. I didn't say what a "session" is, what "long" means, or which Application Insights resource my GitHub Copilot telemetry lands in.
Ten minutes later I had this:
| # | Session | Start (UTC) | Duration | Spans | LLM calls | Tool calls |
|---|---|---|---|---|---|---|
| 1 | 9b195ee3… | Sep 10 19:55 | 142.7 min | 663 | 291 | 365 |
| 2 | 93d53744… | Sep 08 10:17 | 47.9 min | 103 | 49 | 53 |
| 3 | 6da6be34… | Sep 10 19:24 | 28.6 min | 264 | 108 | 153 |
and two diagnoses I would not have gotten from the dashboard alone:
- Session 1 (142.7 min) was a GitHub Copilot CLI session building a Grafana dashboard: 291 model calls (233 of them on
gpt-6-astra, P50 17 s), 365 tool calls — 162 of them KQL queries through the Azure Managed Grafana MCP endpoint — 3 dashboard writes, and 2 failures. Verdict: "long, not stuck." The cost driver was a ~147:1 input-to-output token ratio: query results and dashboard JSON accumulating in context and being re-sent on every turn. - Session 2 (47.9 min) was a wait loop: 23 rounds of
cost_analysis→bash sleep(60, 120 or 180 s) → retry. The sleeps account for ~44 of the 47.9 minutes. Verdict: "latency-long, not work-long" — and a pattern worth flagging.
On the dashboard these two look the same: a long bar in Agent Run Duration. Underneath they are completely different stories.
The agent didn't know any of that when I started. The dashboard did. That is what this post is about.
First principles
Start from what a dashboard is. Every panel is a query someone wrote because the answer mattered, pointed at the right resource, titled with the question it answers, and annotated with the ways it can mislead. The variables pin it to a subscription, a resource group, an Application Insights component. The tags say what it covers. And it tends to stay correct, because people look at it every day and complain when it isn't. A dashboard is a team's understanding of a system, written down in a form that runs.
That is why a person on call can open one and get insight without asking anyone. It is also the whole argument for handing one to an agent. The insight was never in the pixels; it is in the queries, scopes, titles and descriptions underneath them, and an agent can read those directly.
A dashboard is a map for the agent. It shows where the data lives, which questions are worth asking, how each one is asked, and where the traps are. The agent didn't need a separate context file, a hand-written playbook, or a tour of the schema. Most of what a human needs to reason about the system is already there, and so is most of what the agent needs. The map is already drawn. Here is what the agent found on it.
What the agent did
SRE Agent reached my Grafana instance through the Azure Managed Grafana MCP endpoint — instances in the Azure public cloud have one at https://<grafana-endpoint>/api/azure-mcp — attached as an MCP connector. SRE Agent has a built-in connector for exactly this now; more on that below. The tool trace for the first two prompts is short:
amgmcp_dashboard_search— "GitHub Copilot" → one hit: uidGitHubCopilot, tagsgithub-copilot,opentelemetry,application-insights.amgmcp_dashboard_inspect— the panel list, the template variables with their current values, the time range, and every panel's KQL with the variables substituted.amgmcp_datasource_list— the UID of the Azure Monitor data source.amgmcp_query_resource_log— a query the agent composed, run against the Application Insights resource the dashboard points at.
Each "what was session N doing?" was two more query_resource_log calls.
Step 2 is where the interesting part happens, so I connected the same MCP endpoint to my own coding agent and ran the inspect call myself to see exactly what comes back.
Summary mode (no arguments) returns the shape of the dashboard: 21 panels with ids, titles and types; six template variables with their current values; the default time range; and a nextSteps map that tells the agent how to go deeper.
{
  "title": "GitHub Copilot",
  "panelCount": 21,
  "panels": [
    { "panelId": 5,   "title": "Time to First Token by Model (P50 / P90)", "type": "barchart" },
    { "panelId": 203, "title": "Tool Latency by Tool (P50 / P90)",         "type": "barchart" },
    { "panelId": 204, "title": "Agent Run Duration by Source and Agent",   "type": "table" },
    { "panelId": 202, "title": "Telemetry Freshness",                      "type": "table" },
    "…"
  ],
  "variables": [
    { "name": "sub",    "current": "<subscription-id>" },
    { "name": "rg",     "current": "my-resource-group" },
    { "name": "res",    "current": "my-app-insights" },
    { "name": "source", "current": "copilot-chat,github-copilot" },
    "…"
  ],
  "timeRange": { "from": "now-7d", "to": "now" },
  "nextSteps": {
    "panel_queries": "Set includeQueries=true to get each panel's underlying queries plus `resources`, the Azure resource IDs each target actually runs against …"
  }
}
Panel-queries mode returns, for every panel, the query, the data source, and the resource scope, with the template variables resolved on request. This is panel 204, the one that makes long runs visible:
dependencies
| where cloud_RoleName in (${source:singlequote})
| where tostring(customDimensions["gen_ai.operation.name"]) == "invoke_agent"
| extend agent = tostring(customDimensions["gen_ai.agent.name"])
| summarize Runs = count(),
    ['P50 Duration'] = round(percentile(duration, 50), 0),
    ['P90 Duration'] = round(percentile(duration, 90), 0),
    ['Max Duration'] = max(duration),
    ['Runs > 10 min'] = countif(duration > 600000)
    by Source = cloud_RoleName, Agent = iff(isempty(agent), "(unnamed)", agent)
| order by Runs desc
The agent still has to do the last mile. The query tool sends no time window and doesn't expand Grafana macros, so the agent swaps $__interval for a literal bin size and adds its own | where timestamp > ago(3d). But the tool description says exactly that. The agent isn't guessing.
What's on the map
Look at what the dashboard put in that response, and what the agent therefore did not have to figure out.
Where the data is. A single Azure Monitor data source can query any resource its identity is allowed to read, and the scope appears nowhere in the KQL. The dashboard's variables resolved it to one Application Insights component. Without that, the first ten minutes of an investigation often go to "which workspace?"
Which table, which attributes. dependencies, filtered by cloud_RoleName in ('copilot-chat', 'github-copilot') — GitHub Copilot in Visual Studio Code and GitHub Copilot CLI. The source variable is that mapping. Spans are classified by gen_ai.operation.name (chat, execute_tool, invoke_agent); tools by gen_ai.tool.name; tokens by gen_ai.usage.input_tokens and output_tokens. A session is copilot_chat.chat_session_id from VS Code and gen_ai.conversation.id from the CLI, coalesced, because the two clients don't agree.
The pitfalls. This is the part I care about most. Three of the panel descriptions:
Time to first token per model (P50 / P90) for measured requests. VS Code reports
copilot_chat.time_to_first_tokenin ms; Copilot CLI reportsgen_ai.response.time_to_first_chunkin seconds (converted to ms here).
Copilot CLI tool calls that cluster at exactly 60 s, 120 s or 180 s are client-side timeouts, which the CLI reports as successful calls.
Agent-run roll-up spans (
invoke_agent), which repeat their child requests, are excluded.
Each of those is a mistake I have already made once. Milliseconds versus seconds. Timeouts that look like successes. Roll-up spans that double-count tokens when you sum naively. None of it is derivable from the schema; it is tribal knowledge, and it is sitting in the dashboard JSON where an agent can read it with jsonPath: "$.panels[*].description".
The questions. The 21 panel titles are the questions an experienced on-call engineer asks about this system: Time to First Token by Model. Tool Latency by Tool. Tool Call Failures by Tool. LLM Call Outcomes Over Time. Telemetry Freshness — the last one so you can tell "no problem" from "no data". An agent reading those titles doesn't have to invent a triage plan. It has one.
Off the edge of the map
Notice what the dashboard does not have: a per-session view. There is no "longest sessions" panel; I would have to add one. The agent composed it anyway, from the dashboard's vocabulary:
dependencies
| where timestamp > ago(3d)
| where cloud_RoleName in ('copilot-chat', 'github-copilot')
| extend op = tostring(customDimensions["gen_ai.operation.name"]),
    sessId = coalesce(tostring(customDimensions["copilot_chat.chat_session_id"]),
                      tostring(customDimensions["gen_ai.conversation.id"]))
| where isnotempty(sessId)
| summarize Start = min(timestamp), End = max(timestamp), Spans = count(),
    LLMCalls = countif(op == "chat"), ToolCalls = countif(op == "execute_tool")
    by sessId
| extend DurationMin = round(datetime_diff('second', End, Start) / 60.0, 1)
| top 3 by DurationMin
Every identifier in that query came from a panel. The agent walked off the edge of the map, but it took the map's coordinate system along.
Compare that with what a human does next. The dashboard's Recent Operations table links every run to Trace Visualization, and for one slow tool call that is exactly the right tool. This is session 1's longest run in that view: a single invoke_agent span, 1 hour 18 minutes, 476 spans underneath it.
That view is hard to read end to end. You scroll, sample a few of the long red bars, and move on. The trace is the right shape for "why was this call slow?" and the wrong shape for "what was this run doing?"
The agent never looked at this picture. Its per-session stories came from aggregation instead: execute_tool spans grouped by gen_ai.tool.name, chat spans by gen_ai.response.model, P50s and first/last timestamps per group, and the phases fall out in seconds. Same rows, different reader, different question.
With content capture enabled, the spans even carry gen_ai.tool.call.arguments — which is how "bash, 120 s" became "sleep 120 — Wait before retrying throttled query", and how the agent could say backoff, not hang.
That last step matters more than it looks. The description above says calls clustering at exactly 60/120/180 s are usually client-side timeouts. In session 2 they were the other thing — deliberate sleeps — and only the captured arguments could settle it. A description tells an agent what to check; the telemetry lets it check.
Don't write dashboards for agents
The tempting takeaway is a new checklist: agents read dashboards now, so write dashboards with agents in mind. I think that is backwards. Nothing in the GitHub Copilot dashboard was written for an agent. The titles are questions because the person on call needs to know what a panel answers without reading its query. The descriptions carry the pitfalls because I hit each one and didn't want the next person to. The variables scope the queries because nobody remembers resource IDs. The freshness panel exists because a human can't tell "no problem" from "no data" either. An agent can use every one of those.
Same principle, other direction. What matters to the person on call is what matters to the agent, and the agent is smart enough to work out the rest: the time window, the bin size, a query the dashboard doesn't have yet. If a dashboard is enough for the human, it is enough for the agent. If it isn't enough for the agent, it probably wasn't enough for the next person on call either, and the fix is the same: fix the dashboard, and both readers get it.
Which brings me to the thing I find genuinely new here. A dashboard used to be a terminal artifact — the end of the pipeline, something you looked at. It is now also an input: a compact, versioned, access-controlled, human-reviewed description of how to reason about a system, in a format agents can execute. It runs the other way as well: session 1, the 142-minute one, was a coding agent building a dashboard through the same endpoint (18 inspects, 162 queries, 3 writes), and the longest-sessions query above could become a panel the same way, so the humans get it next time. The same JSON serves both readers, and you only maintain it once.
Connecting SRE Agent to Grafana
I expected the plumbing to be the boring ten minutes: find the endpoint, mint a token, paste both into a connector form. It wasn't, because SRE Agent has a native Azure Managed Grafana connector. Search for "grafana" under Connectors, pick the card, point it at your instance, test the connection, choose the tools. The agent talks to the instance's MCP endpoint with its own managed identity, so you don't have to create or rotate a token.
Try it
- Pipeline and dashboards: Monitor AI coding agents with Grafana — the OpenTelemetry Collector, the VS Code settings that turn on GitHub Copilot telemetry, and dashboards for GitHub Copilot, Claude Code, Codex, OpenClaw, OpenCode and Gemini CLI.
- The dashboard: GitHub Copilot on Grafana.com, ID 25053, ready to import into an Azure Managed Grafana instance.
- The agent: in SRE Agent, add the Azure Managed Grafana connector as above. For anything else — VS Code with GitHub Copilot, Claude Code, your own client — point it at
https://<grafana-endpoint>/api/azure-mcp; see Configure an Azure Managed Grafana Remote MCP server.
Then ask it something lazy.

 Microsoft