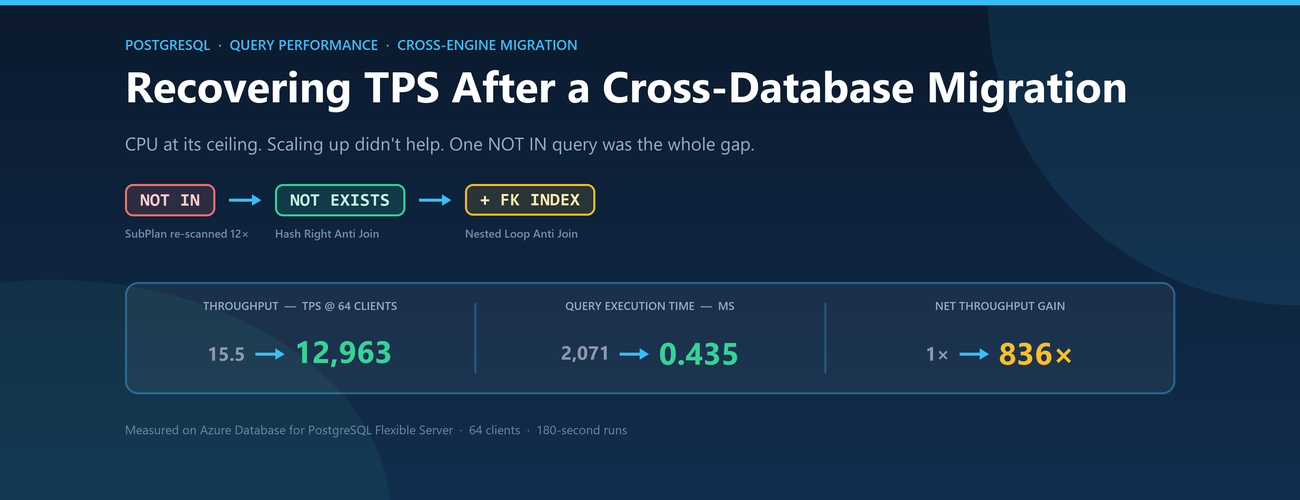
The lede: A team moved their workload from another database engine onto Azure Postgres. Functionally, everything was correct, but their benchmarks were only showing a small fraction of the expected TPS. CPU sat at the ceiling, and adding compute scale did not help. The root cause? A single `NOT IN` query was the culprit. Rewriting the query to use `NOT EXISTS` unlocked an anti-join, and an index on the foreign-key column restored throughput.
1. The Investigation
A thorough investigation led to the following observations:
- CPU remained saturated. The server ran at 100% CPU throughout the benchmark, while wait samples showed that most time was spent executing SQL - indicating queries were either using CPU or waiting for it.
- Scaling up did not help. A larger SKU delivered only a small, proportional improvement and did not close the performance gap - a clear sign of slow transactions rather than a resource ceiling.
- Ranking statements by total execution time showed that the top query ran far longer on PostgreSQL than on the source database. Throughout the tests, no changes were made to SQL statements or application logic or flow.
Under concurrent execution, the top-most query consumed all available CPU, starving every other operation of resources.
We also eliminated any potential migration-related details: table statistics were current. On a freshly migrated database, missing statistics reproduce such symptoms and running ANALYZE fixes bad SQL plans for most queries.
SELECT relname, n_live_tup, last_analyze, last_autoanalyze
FROM pg_stat_user_tables ORDER BY n_live_tup DESC;
2. The Query and the Cause
The top statement came from the order-status path, which called on each transaction to find any customer's orders that were still awaiting validation, and joined orders to order_validations expressed as "not yet validated" via a NOT IN subquery:
AND o.order_id NOT IN
(SELECT v.order_id FROM order_validations v
WHERE v.validation_state = 'PASSED')
This was the smoking gun evidence.
NOT IN carries SQL's three-valued logic (TRUE, FALSE and UNKNOWN). If a subquery result contains a NULL and the outer value matches none of the non-NULL values, the predicate evaluates to UNKNOWN rather than TRUE, and the row is dropped. Because of these semantics, the Postgres planner does not turn a NOT IN subquery into an anti-join. It evaluates the predicate as a filter over the subquery result instead of joining against it.
The previous engine performed the anti-join transformation, but Postgres does not. That difference results in the entire performance gap.
The plan shows the consequence:
-> Bitmap Heap Scan on orders o (actual time=695.848..2029.205 rows=5 loops=1)
      Filter: (... AND (NOT (ANY (order_id = (SubPlan 1).col1))))
      SubPlan 1
        -> Materialize  (actual time=0.004..99.936 rows=1031970 loops=12)
              -> Seq Scan on order_validations v  (actual rows=1530643 loops=1)
                    Filter: (validation_state = 'PASSED')
The subquery result - 1,530,643 PASSED validations - becomes materialized once and then re-scanned twelve times, once per candidate order row, equaling roughly 12.4 million row comparisons for a result which includes 12 rows.
The damage does not stop at the subquery. Because the planner cannot see through the filter, the rest of the plan continues to degrade; a bitmap scan using orders_pkey, and products joined by a sequential scan that evaluated to keep 5 rows.
A construct the planner cannot reason through does not just execute slowly; it corrupts the estimates every other node depends on.
3. The Fix
The NOT IN predicate was re-written as NOT EXISTS and LEFT JOIN...IS NULL so that the planner could properly produce an anti-join. Both rewrites are equivalent:
-- Option A: NOT EXISTS - "does a matching row exist?", a two-valued question
WHERE NOT EXISTS
(SELECT 1 FROM order_validations v WHERE
v.order_id = o.order_id AND v.validation_state = 'PASSED')
-- Option B: LEFT JOIN ... IS NULL - the same anti-join, spelled differently
LEFT JOIN order_validations v
ON v.order_id = o.order_id
AND v.validation_state = 'PASSED'
WHERE v.order_id IS NULL
The plan changes shape immediately:
-> Hash Right Anti Join (actual time=306.311..306.316 rows=5 loops=1)
      Hash Cond: (v.order_id = o.order_id)
      -> Seq Scan on order_validations v (actual time=0.008..231.238 rows=1530643 loops=1)
            Filter: (validation_state = 'PASSED')
      -> Hash (actual time=0.358..0.360 rows=12 loops=1)
            Buckets: 1024 Batches: 1 Memory Usage: 9kB
The planner hashes the small 12-row portion and streams the large table past it as the probe side. One pass over each relation is sufficient, with no materialization and no rescans.
Both rewrites compiled to identical plans - same cost, same node structure, same buffer counts, execution times within 0.14% of each other.
There is a correctness benefit too **: NOT IN** can fail quietly, when a NULL appears in the subquery: it returns an empty result that looks like a legitimate "no rows found". NOT EXISTS is not exposed to that.
4. The Final Steps
Everything above was measured with no index on foreign key order_validations.order_id which typically reflects a real post-migration state.
CREATE INDEX idx_order_validations_order_id
ON order_validations (order_id, validation_state);
ANALYZE order_validations;
With the order_id leading, the index is ordered on the anti-join key, and because validation_state is included, the inner side of the join is fully covered.
|
Variant |
FK index |
Query time |
Buffers |
|
NOT IN |
no |
2,071.51 ms |
30,386 |
|
NOT IN |
yes |
2,003.72 ms |
30,386 |
|
NOT EXISTS |
no |
306.40 ms |
22,028 |
|
NOT EXISTS |
yes |
0.435 ms |
345 |
|
LEFT JOIN ... IS NULL |
yes |
0.432 ms |
345 |
Two results stand out.
The index did nothing for `NOT IN`. 2,071 ms became 2,004 ms - run-to-run noise. The planner did not use the index, and it was right not to: the subquery result has to be materialized so it can be rescanned, so a selective index cannot contribute. It indicates the problem was never associated with the access path but with plan shape.
The same index transformed `NOT EXISTS` - 306.40 ms to 0.435 ms:
->  Nested Loop Anti Join  (actual time=0.063..0.367 rows=5 loops=1)
      ->  Bitmap Heap Scan on orders o  (actual rows=12 loops=1)
      ->  Index Only Scan using idx_order_validations_order_id on order_validations v
            (actual time=0.004..0.004 rows=1 loops=12)
            Index Cond: ((order_id = o.order_id) AND (validation_state = 'PASSED'))
            Heap Fetches: 0
Without the index, the anti-join had to hash 12 rows and streams1.53 million validation rows past the hash. With the index, the planner switched to twelve point lookups with a nested loop, and buffers needed for the whole query fell from 22,028 to 345.
This test also corrects a tempting intuition, validation_state = 'PASSED' matches 60% of the table, which makes the column look index-proof. But in the nested-loop shape the index condition is (order_id = o.order_id AND validation_state = 'PASSED') — a point lookup per outer row, and there are only twelve outer rows. Selectivity depends on the predicate as used in the plan, not on the column alone.
5. Validating Throughput is Restored
Re-running the same 64-client, 180-second benchmark with the index in place:
|
Variant |
TPS |
Avg latency |
Transactions |
vs baseline |
|
Baseline - NOT IN |
15.51 |
4,096.11 ms |
2,839 |
- |
|
LEFT JOIN ... IS NULL |
12,963.39 |
4.936 ms |
2,331,899 |
836× |
|
NOT EXISTS |
12,908.18 |
4.958 ms |
2,322,025 |
832× |
836× throughput, with latency down from four seconds to five milliseconds.
Three things are worth drawing out:
- The baseline did not move. 15.69 TPS before the index and 15.51 after. Anyone who added the index without rewriting the query would have concluded the index was useless and dropped it.
- The rewrite's value grew from 3× to 836× once the index existed to support it. SQL rewrite alone would’ve looked like a modest win rather than a transformational one.
- Latency became predictable. The baseline’s pgbench progress windows has shown avg latency oscillating across a 23% spread; while the rewrites held within 0.9% deviation across the entire run.
In the same 180 seconds, the baseline completed a total of 2,839 transactions while the rewrite completed 2,331,899. At the baseline rate, the same volume would take roughly 41.8 hours.
6. Takeaways
- A whole-database slowdown is often a bad query with concurrency. Rank statements by total execution time along with calls before scaling up hardware.
- CPU at its ceiling with backends executing rather than waiting is a query problem, not a capacity problem. Scaling up buys proportional relief at best.
- After a cross-engine migration, compare per-statement runtimes against the source platform. The queries that hurt are the ordinary-looking ones whose performance depended on an optimizer transformation the new engine does not perform.
- PostgreSQL does not transform a `NOT IN` subquery into an anti-join, because of SQL's three-valued NULL semantics. Rewriting to NOT EXISTS or LEFT JOIN ... IS NULL is what makes the anti-join available.
- Fix the plan shape first, then the access path. The same foreign-key index was worth nothing to NOT IN and 836× to NOT EXISTS on query time.
- `NOT EXISTS` and `LEFT JOIN ... IS NULL` compile to identical plans. Pick the one that reads more clearly.
- `NOT EXISTS` fixes correctness as well as speed. NOT IN silently returns nothing when the subquery contains a NULL.
Appendix - Reproducing this yourself
The six scripts below are a self-contained lab. They are synthetic stand-ins shaped to reproduce the same plan behavior, not a model of any real business. Run them in a scratch database.
Prerequisites: PostgreSQL 14+ and a pgbench client. Sizing as measured: 10,000 customers, 50,000 products, 3,000,000 orders.
|
File |
Purpose |
|
01_schema.sql |
Creates customers, products, orders, order_validations |
|
02_data.sql |
Loads the dataset and runs ANALYZE, then verifies row counts |
|
03_indexes.sql |
Baseline index; the foreign-key index is commented out until round two |
|
bench_notin.sql |
Baseline - the migrated NOT IN shape |
|
bench_notexists.sql |
Fix A - NOT EXISTS |
|
bench_leftjoin.sql |
Fix B - LEFT JOIN ... IS NULL |
Note. .sql attachments are not supported on this platform, so all six scripts are reproduced in full in the companion document AntiJoin_Repro_SQL_Scripts.docx. Copy each into a file named exactly as listed above, saved as UTF-8 without a BOM, and keep the \set lines in the bench_*.sql files at column 1 - they are pgbench meta-commands, not SQL.
Follow the run order given in that document. The foreign-key index is intentionally commented out in 03_indexes.sql so the first round measures the rewrite alone. Adding it too early removes the comparison the post depends on.
Run order
- Run 01_schema.sql, then 02_data.sql, then 03_indexes.sql.
- Benchmark all three query files. This is the "no FK index" round.
- Uncomment and run the foreign-key index block in 03_indexes.sql.
- Benchmark all three query files again.
pgbench -U postgres -h <server>.postgres.database.azure.com \
-c 64 -j 64 -T 180 -P 15 -r -n \
-f bench_notin.sql postgres
Two things are easy to get wrong on the command line:
- The database name is a positional argument, not `-d`. In pgbench, -d floods the output with protocol noise. Put the database name last.
- -r reports per-statement latency across all clients; -P 15 prints progress every 15 seconds, which is how you confirm a run was stable rather than trending.
Keep runs comparable: same client count, same duration, and a warm-up before every measured run. Capture plans separately in a single psql session - do not wrap the benchmark statements in EXPLAIN (ANALYZE), because the instrumentation overhead distorts the TPS you are trying to measure.

 Microsoft